The Data Scientist Interview Process: What It Actually Looks Like Now
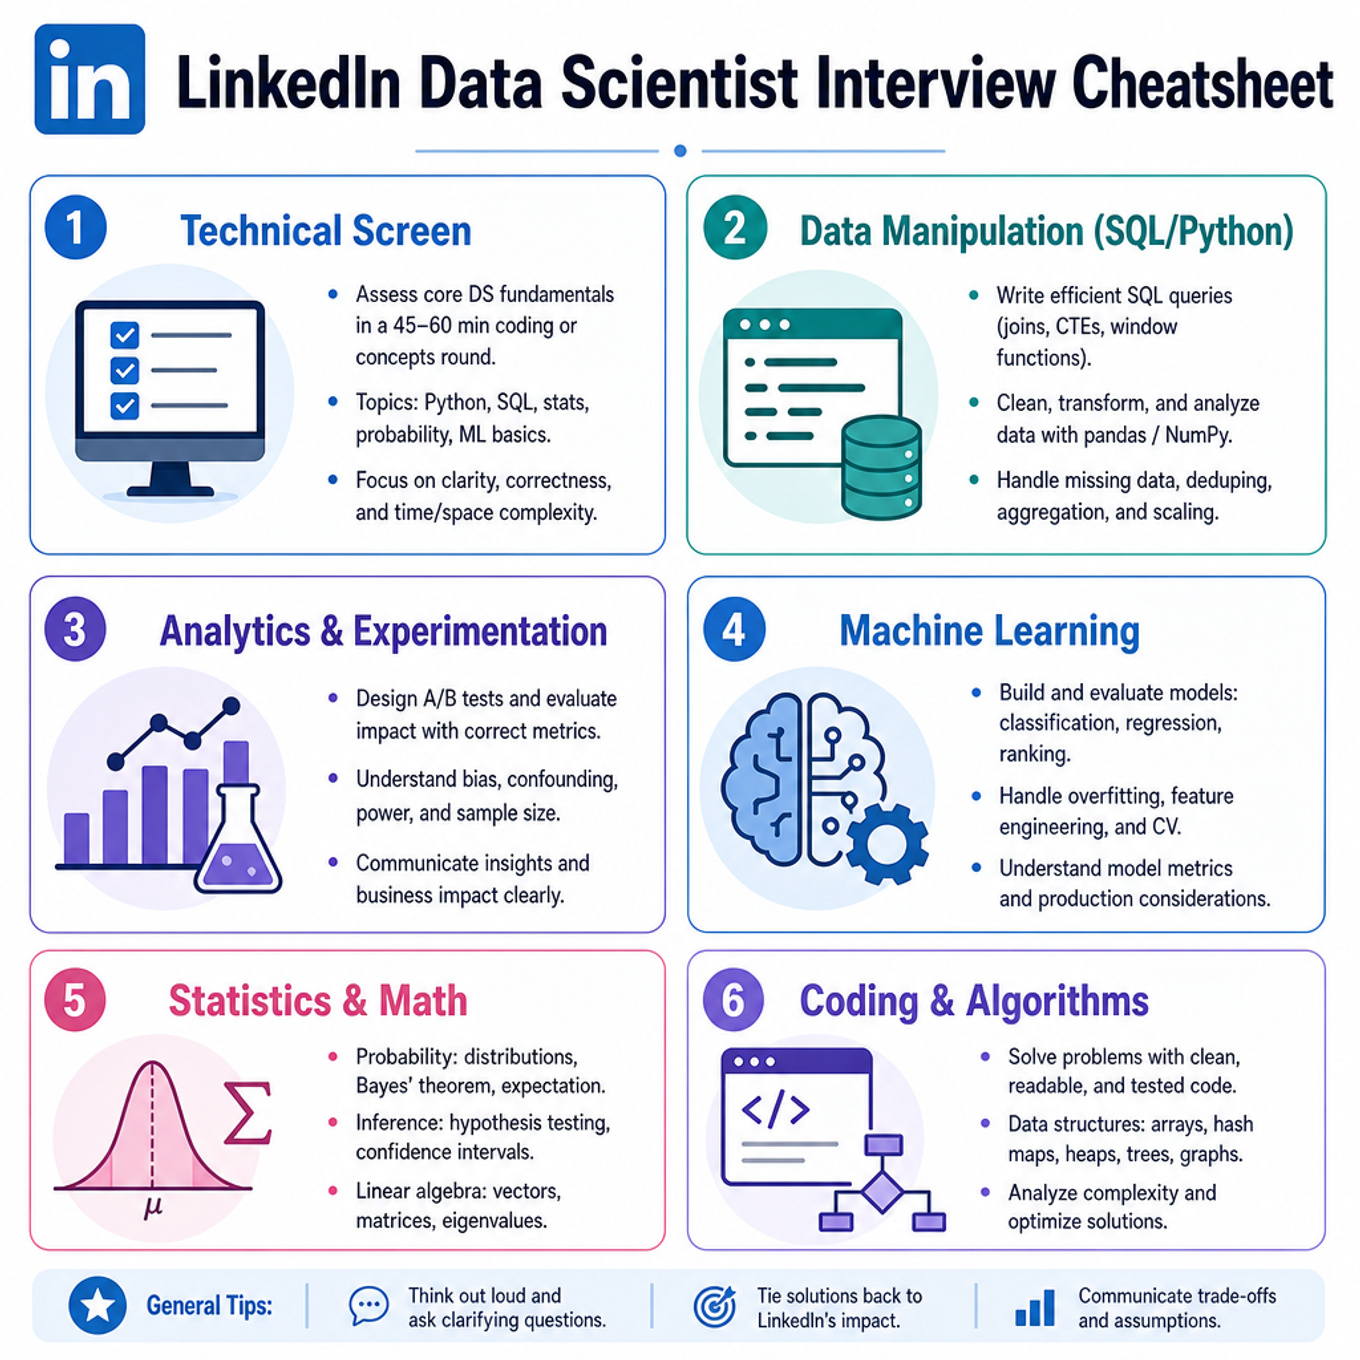
The data scientist interview has shifted over the last few years. It used to be mostly brainteasers and whiteboard derivations. Now most companies run a four-stage loop: a recruiter screen, a take-home or live coding round, a technical interview covering SQL and ML fundamentals, and a final panel that's usually a mix of product case studies and project deep-dives. The exact order changes by company, but the overall shape is consistent. If you've been through a Data Scientist Interview recently, you might notice the same patterns repeating. What most candidates get wrong isn't the technical content. They understand regression and they can write basic Python. What trips them up is the format and pacing. The technical rounds move fast. Interviewers ask follow-up questions that build on your previous answer rather than switching topics. When you pause too long or answer vaguely, they tend to move on instead of helping you along. The clock matters more than it should.
SQL Is Where Candidates Fall Apart
SQL alone filters out more applicants than any other topic. I sit on hiring panels occasionally, and the pattern is clear. People who claim strong ML skills routinely choke on window functions and recursive CTEs. The technical screening round at my current company includes two SQL questions: one involves a gaps-and-islands problem and the other tests self-joins with date ranges. Most candidates can handle simple group-bys. The ones who land offers usually spend at least a few weeks grinding LeetCode SQL problems and StrataScratch before their first interview. Don't skip the practical component. Writing SQL in a shared editor or a browser tool while being watched is different from writing it offline. Practice typing it out cleanly under time pressure. Use EXPLAIN plans when asked about performance. Mentioning indexing strategy or query plan analysis signals that you've actually worked with real data at scale rather than just running pandas queries on CSV files.
The ML Theory Round Doesn't Want Definitions
The ML portion of a typical Data Scientist Interview asks questions that sound simple but aren't. "Explain regularization" gets you nowhere. "Walk me through how L1 versus L2 changes the geometry of the solution space and what that means for feature selection" gets a conversation started. Interviewers are testing whether you can connect concepts rather than recite textbook paragraphs. One thing beginners consistently miss is the relationship between bias-variance tradeoffs and model complexity across different algorithm families. Everyone remembers the curve for linear models. Fewer people can articulate how this looks for random forests, gradient boosting, or neural networks. When I ask about dropping trees in a forest to reduce overfitting, most candidates freeze. The answer involves understanding that bagging reduces variance but doesn't reduce bias, which is why boosting exists as a separate approach. Knowing this distinction separates people who have trained models from people who understand why those models behave the way they do. I once spent 20 minutes discussing why a candidate's XGBoost model performed poorly on a specific dataset. The model had high training accuracy but terrible validation performance. We traced it back to temporal leakage. The features contained information from the future relative to the prediction target. The candidate had split the data randomly instead of chronologically. This is such a common failure mode that I recommend everyone practicing for these interviews include a timeline-aware cross-validation step in their own projects before they even start preparing. It usually takes about ten minutes to set up with scikit-learn's TimeSeriesSplit and it prevents the most embarrassing interview moment possible.
Get the Full Details
The Case Study Round Tests How You Think, Not What You Know
The product or business case round is where most people feel lost because there is no single right answer. You'll get something like "How would you measure the success of a new recommendation feature?" or "Should we ship this churn model as-is?" The interviewer wants to see you break down ambiguity, ask clarifying questions, and make explicit assumptions. They want to hear you reason out metric selection, define acceptable tradeoffs, and identify what could go wrong. A practical framework that works well: restate the problem in your own words, identify the stakeholders and their incentives, propose 2-3 measurable outcomes, pick one to optimize for and justify why, then discuss what data you'd need and what risks exist. Keep it structured but conversational. Don't ramble through five approaches and pick one at random. A mediocre plan explained clearly beats a brilliant plan stated vaguely.
The Project Walkthrough Is Non-Negotiable
Every company I've worked with includes a project discussion. You'll present something you've built and defend the decisions. Prepare to talk about what you chose to build, why, what alternatives you considered, and what you would change if you did it again. This is where you demonstrate real experience. Anyone can replicate a Kaggle notebook. Talking through production decisions, debugging iterations, and tradeoffs you made shows you've actually shipped work. One specific thing I recommend: include at least one failure in your project narrative. A model that broke in production, a data quality issue you uncovered late, a feature that looked promising but added no value. Interviewers trust candidates who can discuss failures candidly. It signals honesty and experience. Candidates who present only successes sound rehearsed.
The Take-Home Assignment Reality Check
Take-home assignments vary widely. Some companies give you a clean dataset and ask for a notebook. Others give you messy data and a vague business question. The ones that actually predict job performance provide realistic scenarios with incomplete information. A bad take-home assigns a full end-to-end project that should take 20 hours. That tells you the team doesn't understand how these exercises work. Budget yourself six to eight hours maximum. If the scope feels larger, you're either misunderstanding the ask or the assignment itself is poorly designed. Focus on clarity over completeness. A clean exploratory analysis with reasonable assumptions and a clear narrative is worth more than a perfectly tuned model built on poorly understood data. I've seen candidates lose offers because they over-engineered a solution to a problem that didn't require it. Interviewers sometimes look at your approach and conclude you'd build unnecessary complexity in production. That reputation sticks.
Statistics and Probability Still Matter More Than People Admit
Bayes theorem, confidence intervals, p-values, hypothesis testing, sampling distributions. These come up constantly. Many candidates breeze through ML and crash on stats. The question "What does a p-value of 0.03 actually mean?" sounds basic but nearly half the people I interview answer it incorrectly. It doesn't mean there's a 97% chance the alternative hypothesis is true. It means that if the null hypothesis were true, you'd see data this extreme about 3% of the time. The distinction matters more in production work than in interviews, but interviewers use it as a proxy for whether you understand what you're actually doing. Another counter-intuitive point: AUC-ROC is not always the right metric. In highly imbalanced datasets, AUC-PR (precision-recall) gives you a much clearer picture of real-world model performance. I encountered a fraud detection model during a previous role where AUC-ROC was 0.94 but the precision at realistic recall levels was under 5%. The model looked excellent on the metric everyone defaults to and terrible in practice. If an interviewer asks about imbalanced classification, mentioning this tradeoff explicitly will set you apart.
What Happens After the Technical Rounds
The final stage usually includes a culture fit conversation, sometimes with a peer or a cross-functional partner. This isn't just small talk. They're checking whether you communicate clearly, handle feedback well, and can collaborate without creating friction. I've seen technically strong candidates fail here because they argued with interviewers instead of exploring the problem together. The goal is a dialogue, not a debate. When you don't know something, say so. Propose how you'd figure it out. That response is more valuable than bluffing through an answer. Preparation tips that actually move the needle: practice explaining your past work out loud without notes. Record yourself and listen back. You'll catch filler words and vague statements immediately. Run through SQL problems on a whiteboard or shared doc, not just in your head. Review basic probability and stats until the definitions are automatic. And stop trying to memorize answers to common questions. The interviews are designed to adapt to whatever you say. Flexibility beats memorization every time.