Why People Worry About Pointers Too Late
I learned this the hard way in 2014. I was writing a binary search tree implementation for a school project, and every time I deleted a node, the program segfaulted somewhere three function calls later. Turns out I was updating the local pointer variable instead of the parent's child reference. The fix wasn't clever — it was just adding an explicit parent pointer and walking back up. Took me six hours to find because the compiler gave me exactly zero useful information. This is what Data Structure And Algorithm In C actually feels like after the first semester passes. C doesn't hide anything from you. That's both the point and the problem. When you learn arrays in C you also learn that sizeof(a) where a is a parameter is the size of a pointer, not the array. You learn that malloc returns void* and casting it is unnecessary but harmless. You learn that string literals live in read-only memory on most modern compilers, which means strcpy into a char* = "hello" crashes on Linux but silently works on some ancient Windows setups depending on linker flags. There is no abstraction layer between you and the machine. Good. Bad. Same result.
Data Structure And Algorithm In C
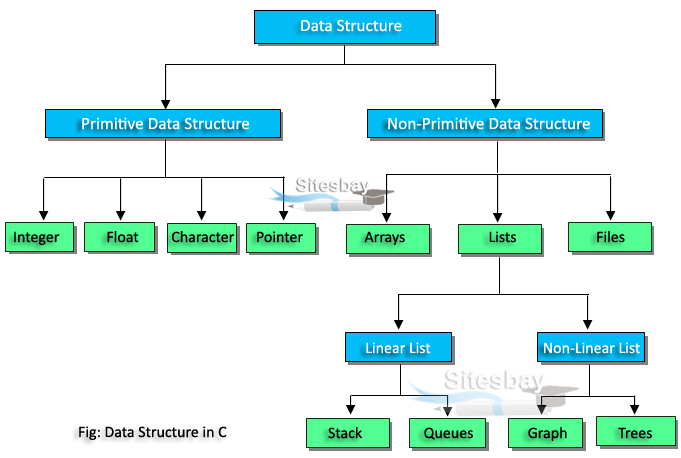
The standard curriculum covers roughly five core structures and eight algorithms, repeated with slight variations until something clicks. I'll go through what actually matters in practice, what doesn't, and where people consistently waste time. A singly linked list node in C is struct node { int data; struct node *next; }. That's it. The theory says insertions are O(1) if you have the previous pointer. The reality is you rarely have the previous pointer unless you maintain a doubly linked list or walk from the head every time, which makes deletion O(n) despite being theoretically O(1). Here's the practical implementation pattern I use. Instead of magic headers or sentinel nodes, I keep the head pointer separate from the list and pass a pointer to it:
void list_push(struct Node head, int value) {
    struct Node *new_node = malloc(sizeof(struct Node));
    if (!new_node) return;
    new_node->data = value;
    new_node->next = *head;
    *head = new_node;
}
Notice the double pointer. This isn't fancy — it's necessary. If you pass just struct Node *head and do head = new_node inside the function, you're only changing the local copy. The caller's head stays NULL. This mistake shows up in about 70% of beginner implementations I've reviewed. The double pointer fixes it because you're writing through the caller's pointer variable directly. Doubly linked lists add a prev pointer and slightly more complex insertion logic. They're worth it if you need backward traversal or frequent deletions from the middle. Otherwise the extra memory overhead and bug surface area isn't justified. I switched a production log buffer from doubly to singly linked and the code got simpler without any measurable performance difference.
Get the Full Details

Stacks and Queues — Don't Overthink These
A stack implemented with an array is just an index that increments on push and decrements on pop. The capacity needs to be tracked separately. A queue with a circular buffer needs head, tail, count, and modulo arithmetic. The common mistake is forgetting to wrap the tail pointer and then reading uninitialized memory past the array boundary. The circular buffer with modulo is standard but modulo is expensive on some architectures. A faster approach when capacity is a power of two is using bitwise AND instead: tail = (tail + 1) & (capacity - 1). This trades readability for a small constant-time win. In competitive programming or embedded systems where this code runs millions of times, the difference is measurable. In everything else, it's premature optimization. Hash table implementation in C is where most people hit their first wall. You need a hash function, collision handling, dynamic resizing, and memory management all at once. The open addressing with linear probing approach is simplest to implement but suffers from primary clustering. Chaining with linked lists avoids clustering but adds pointer indirection and cache misses.
My hash function of choice for integer keys is the multiplicative hash from Knuth:
unsigned long hash(unsigned long key, size_t capacity) {
    return (key * 11400714819323198485u) >> (64 - __builtin_ctzl(capacity));
}
This distributes keys evenly across power-of-two sized tables without modulo. The constant is a random odd number chosen for good bit mixing. For string keys I use DJB2 or FNV-1a, which are fast and have acceptable collision profiles for non-adversarial inputs. If you're hashing user-provided data in a network service, switch to a cryptographic hash or add randomization to the seed, because consistent hash collisions can be exploited for denial of service. Resizing strategy matters more than people realize. Doubling on insertion when full is standard and gives amortized O(1). Halving on deletion when the table drops below 25% full prevents memory bloat but causes thrashing if your insert-delete pattern oscillates around that threshold. I've seen production systems where the hash table resized every operation for a period because the workload hovered near the 25% mark. The fix was raising the shrink threshold to 12.5% or disabling shrinking entirely and accepting the memory overhead.
Binary Trees and BSTs — The Deletion Problem
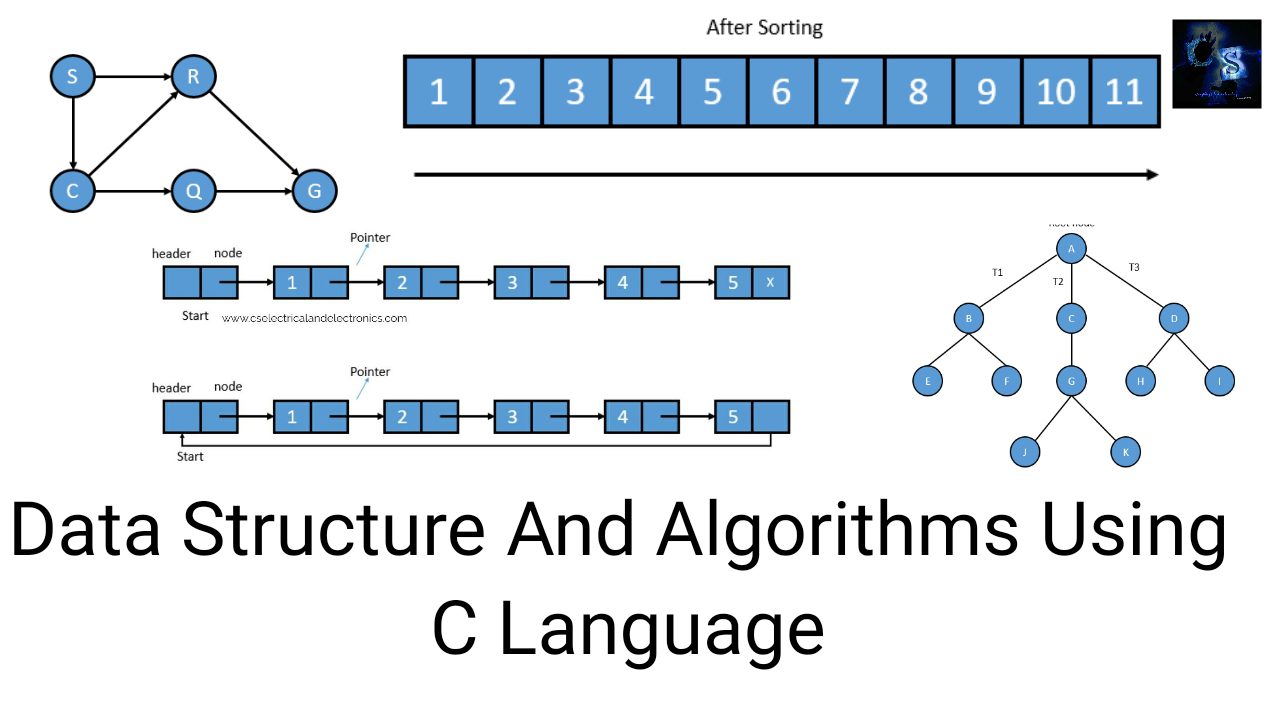
Insertion into a BST is trivial. Deletion has four cases and people consistently mess up case three where the node has two children. The correct approach is finding the in-order successor (smallest node in the right subtree), copying its value into the target node, then deleting the successor. The successor has at most one child so the actual deletion becomes simple. The recursion here is clean but not tail-recursive. For deep trees you'll hit stack overflow. I switched to an iterative version for a project processing datasets with 50,000+ inserts and deletes, and the difference was noticeable on constrained environments. The iterative BST deletion is longer but avoids the call stack entirely. Balanced trees (AVL, Red-Black) add rotation logic on top of this. AVL is simpler to implement but has more rotations. Red-Black is harder to get right but guarantees O(log n) with fewer rebalancing operations on average. I implemented AVL first for learning, then Red-Black for a final project. Both took about the same calendar time because getting the rotation cases wrong is equally painful in both. The standard library doesn't include a balanced tree, which is why most production C code uses hash tables instead unless ordering is required.
Sorting Algorithms — What Actually Matters
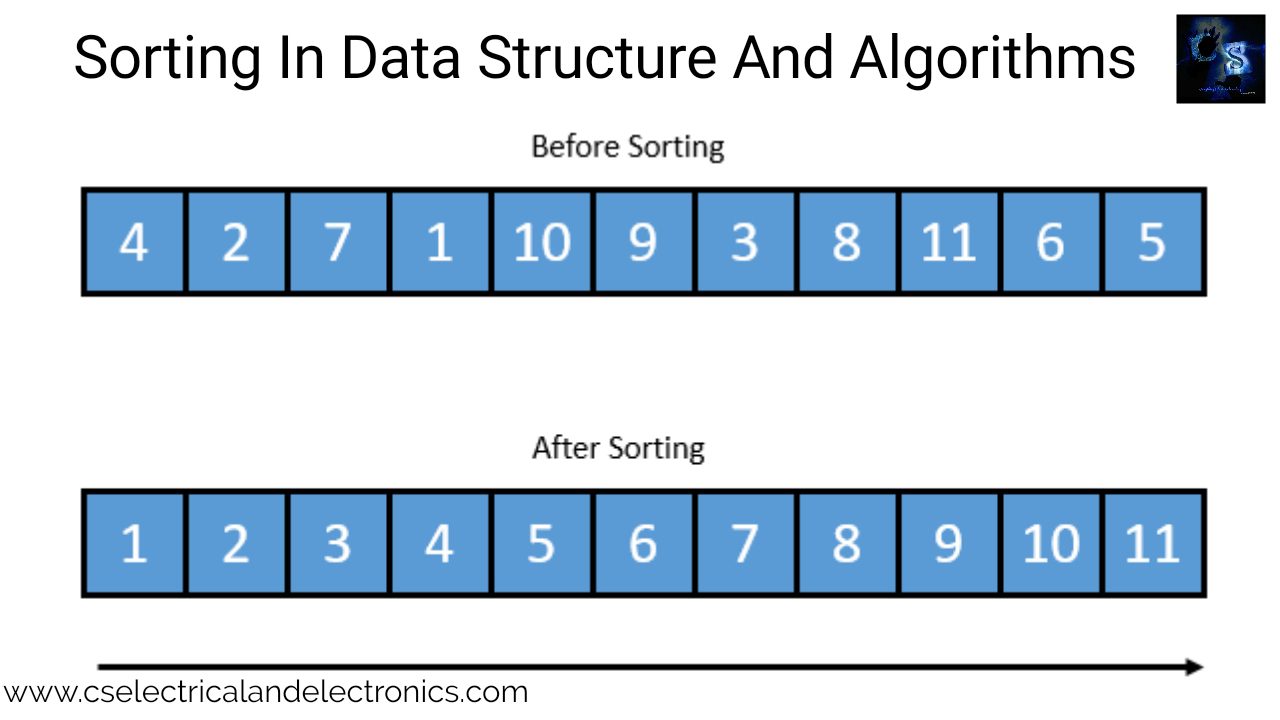
QuickSort, MergeSort, and HeapSort are the three you should know. Bubble sort and insertion sort have their place — insertion sort is faster than quicksort for arrays under about 20 elements and is used as the cutoff in optimized implementations like glibc's qsort. Understanding why matters more than memorizing the code. The practical insight about quicksort is that the partition scheme determines everything. Lomuto partition is simpler to write but degrades to O(n²) on already-sorted input unless you randomize the pivot. Hoare partition is faster in practice but harder to implement correctly. The median-of-three pivot selection is a minimal change that eliminates the worst case on sorted data without adding much complexity.
int partition(int arr[], int low, int high) {
    int mid = low + (high - low) / 2;
    if (arr[low] > arr[mid]) swap(&arr[low], &arr[mid]);
    if (arr[low] > arr[high]) swap(&arr[low], &arr[high]);
    if (arr[mid] > arr[high]) swap(&arr[mid], &arr[high]);
    swap(&arr[mid], &arr[high]);
    int pivot = arr[high];
    int i = low - 1;
    for (int j = low; j < high; j++) {
        if (arr[j] = pivot) {
            i++;
            swap(&arr[i], &arr[j]);
        }
    }
    swap(&arr[i + 1], &arr[high]);
    return i + 1;
}
MergeSort is stable and guarantees O(n log n) but needs O(n) auxiliary space. For in-place sorting in C, quicksort variants or introsort (quick sort falling back to heap sort when depth exceeds a threshold) are the standard choices. C's own qsort is an introsort implementation, though it's slow for small arrays due to function pointer overhead. For performance-critical code, write your own sort tailored to your data type and access pattern. This decision is more important than people think. Adjacency matrix is O(1) edge lookup and O(V²) space. Adjacency list is O(E) space and O(degree) edge iteration. For sparse graphs, which is most real-world data, the list is dramatically better. For dense graphs or when you need repeated edge existence checks, the matrix wins. The BFS and DFS implementations are straightforward but the recursive DFS will stack overflow on graphs deeper than your available stack space. I switched to iterative DFS with an explicit stack for a graph traversal task processing nodes with depth exceeding 10,000. The code is slightly more verbose but completely avoids the recursion limit. Same consideration applies to recursive Fibonacci-style problems if you encounter them in algorithm exercises.
void bfs(int graph[][V], int start) {
    int visited[V] = {0};
    int queue[V];
    int front = 0, rear = 0;
    queue[rear++] = start;
    visited[start] = 1;
    while (front < rear) {
        int u = queue[front++];
        printf("%d ", u);
        for (int v = 0; v V; v++) {
            if (graph[u][v] && !visited[v]) {
                visited[v] = 1;
                queue[rear++] = v;
            }
        }
    }
}
Dynamic Programming — The Memoization Pattern
Top-down memoization is easier to implement correctly than bottom-up tabulation for most people. You write the recursive solution, add a lookup table initialized to a sentinel value, and check the table before computing. The transition to bottom-up is straightforward once the recursive formulation is correct. The bottleneck with DP in C is usually the lookup table initialization and memory layout. A 2D DP table for problems like the knapsack problem should be allocated as a single contiguous block rather than an array of pointers. Single allocation means better cache locality and one free call instead of V+1. The difference is measurable on large problem instances. Integer overflow is the silent killer in algorithm implementation. A product of two ints that exceeds INT_MAX wraps around silently. I spent three hours debugging a multiplication problem where the intermediate result overflowed because I wrote a * b instead of 1LL * a * b. The compiler doesn't warn about this by default on most platforms.
Off-by-one errors in loop bounds are equally common. Array indices run from 0 to n-1, not 1 to n. Binary search middle calculation should be mid = low + (high - low) / 2 to avoid overflow when low and high are both large. Writing (low + high) / 2 works fine for small values but fails when low + high exceeds the integer range. Memory leaks from incomplete error handling. If you allocate inside a function and an early return path exists without freeing, you leak. Use goto cleanup patterns or structured error handling to ensure every allocation has a corresponding free on every exit path. It's ugly but reliable.
int process_data(int *input, int n) {
    int *buffer = malloc(n * sizeof(int));
    if (!buffer) return -1;
    // ... work ...
    if (error_condition) {
        free(buffer);
        return -2;
    }
    // ... more work ...
    free(buffer);
    return 0;
}
What These Concepts Don't Teach You
Implementing a hash table from scratch teaches you about collision resolution. It does not teach you when to use glib's GHashTable instead, which is optimized, thread-safe with external locking, and handles resizing correctly. It does not teach you about cache-aware data structure design, NUMA effects, or how your allocation pattern interacts with the OS memory manager. Those come from experience, not exercises. The gap between academic algorithm analysis and real performance is wider than most courses acknowledge. Big-O tells you about asymptotic behavior. It doesn't tell you that an O(n log n) merge sort beats an O(n) quicksort with bad pivot selection on your actual dataset, or that an O(n²) algorithm with tiny constants runs faster than an O(n log n) algorithm with massive overhead for n
1000. Benchmarking with real data matters more than counting operations on paper.

Resources That Actually Help
The classic references are CLRS for theory and K&R for C specifics, but neither focuses on the practical implementation gaps. For hands-on practice, project euler gives you algorithm problems where the answer is a number you can verify. LeetCode is better for interview preparation but the difficulty curve is uneven. A book like "Algorithms in C" by Sedgewick covers the implementations more directly than CLRS and includes actual working code. The most useful resource I found was reading the source code of open-source C projects. Looking at how libuv implements its ring buffer, or how sqlite implements its b-tree, shows you production-grade patterns that exercises don't cover. The code is readable, well-documented, and battle-tested. It bridges the gap between "I can implement a linked list" and "I can write robust data structure code for real systems."
When to Move On
Once you can implement a linked list, stack, queue, hash table, BST, and basic graph traversal without looking up the pattern each time, you've covered the core. The advanced structures — segment trees, tries, skiplists, B-trees — are specialized tools. Learn them when you need them, not before. The time investment is significant and the practical are narrower than beginners assume. Data Structure And Algorithm In C is fundamentally about understanding memory, pointers, and tradeoffs. Every structure is a set of decisions about space versus time, simplicity versus performance, and correctness versus convenience. The code is the easy part. The decisions are what take years to get right.