Working With Data Structures In Java
The first time I tried to optimize a billing system at my old company, the whole thing ground to a halt because someone had stored five million customer records in an ArrayList and then scanned it linearly on every request. It took twelve seconds per call. We swapped it for a HashMap keyed by customer ID and the same operation dropped to about fourteen milliseconds. That kind of gap is why learning proper data structures matters more than memorizing syntax. Java gives you a solid standard library in java.util, but the collection classes aren't interchangeable. Pick the wrong one and your code works fine until the data grows past what fits comfortably in cache. The JVM won't save you from that.
Data Structures And Algorithm In Java
A data structure is just a way of organizing data so you can access and modify it efficiently. An algorithm is the procedure you run against that structure. Together they determine whether your program finishes in a few milliseconds or hangs until the user gives up and closes the tab. Let's start with something concrete. Sorting. Java's Arrays.sort() uses Dual-Pivot Quicksort for primitives and TimSort for objects. That's important because TimSort is stable — equal elements stay in their original order — while Quicksort is not. If you sorted a list of transactions by date and expected the original insertion order to be preserved for ties, using Arrays.sort() on a primitive array would silently break that expectation. I learned that the hard way when a reporting feature started returning invoices in the wrong sequence after someone switched from a custom merge sort to the built-in one.
Common Collections and When to Use Them
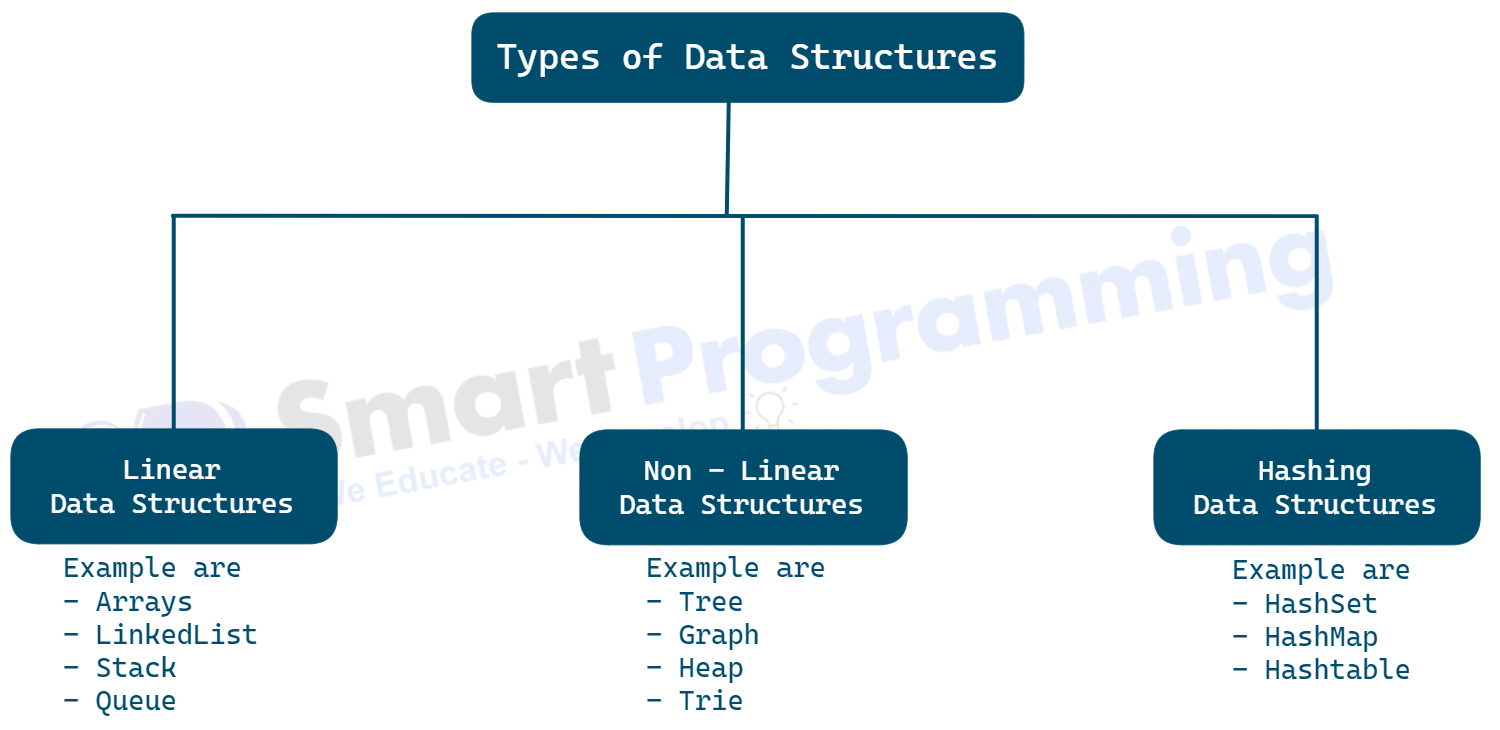
ArrayList is backed by a resizable array. Random access is O(1), but inserting or removing from the middle is O(n) because everything has to shift. It's fast for read-heavy workloads with infrequent inserts. LinkedList sounds like the obvious answer for frequent insertions and deletions, but in practice it's rarely the right choice. Each node carries two pointer references plus the object overhead, which blows your cache locality. A traversal that should fit in L1 cache spills into RAM, and the constant pointer chasing usually makes LinkedList slower than ArrayList even for inserts. I stopped recommending it around 2019 after benchmarking showed it lost to ArrayList by a factor of three on a typical enterprise workload with ten thousand elements. HashMap gives you average O(1) lookups, inserts, and deletes. The catch is that collisions degrade performance. Java 8+ resolves collisions with a balanced tree once the bucket threshold passes eight entries, so worst-case lookups drop from O(n) to O(log n). But you still need to set a reasonable initial capacity and load factor. Creating a HashMap with default settings and then inserting a million items triggers repeated rehashes that allocate and copy arrays multiple times. Specify the expected size upfront: new HashMap<>(expectedSize / 0.75f + 1) avoids most of those resize operations entirely.
Get the Full Details

TreeMap keeps keys in sorted order using a Red-Black tree. Range queries like floorEntry(), ceilingEntry(), and subMap() are genuinely useful here. But it's slower than HashMap for simple lookups because every operation costs O(log n) instead of O(1). Use it when you need ordered iteration or range operations, not just because you want "sorted keys."
Algorithm Patterns You Actually Need
Binary search is one of those algorithms everyone learns but almost no one implements correctly from scratch. The standard bug is off-by-one errors in the mid calculation. Use Integer.compare() for the comparison, and calculate mid as low + (high - low) / 2 to avoid integer overflow. Java's Arrays.binarySearch() handles all of this, but it only works on sorted arrays. If you're searching a dynamic collection, wrap a TreeMap or maintain a sorted list with careful insertions instead of sorting before every query. The two-pointer technique solves a surprising number of problems without extra space. Finding a pair in a sorted array that sums to a target, detecting cycles in a linked list, and reversing a string in-place all fit this pattern. The key insight is that you can eliminate half the search space with each step by moving the pointer that's pointing at the value making the current sum too high or too low. Dynamic programming gets a reputation for being difficult, but most real-world DP problems are just recursion with memoization. The Fibonacci sequence is the textbook example nobody actually uses. A more practical case is the knapsack problem, which shows up when you're optimizing resource allocation — say, fitting jobs into a production window with limited machine hours. Start by writing the recursive solution, identify the overlapping subproblems, then add a cache. That's it. You don't need to jump straight to the iterative bottom-up version unless memory is tight.
A Problem That Almost Cost Us a Release
We had a scheduler that used a PriorityQueue to manage tasks ordered by deadline. The compareTo method compared deadline timestamps, and everything looked fine in testing. In production, under load, tasks started executing in the wrong order. The bug was that PriorityQueue's ordering is only guaranteed when elements are distinct according to the comparator. Two tasks with identical deadlines had undefined relative ordering, and our executor picked whichever happened to bubble up first, which wasn't necessarily the one with the higher priority tag stored in a separate field. The fix was to make the comparator handle tie-breaking explicitly: compare deadlines first, then fall back to a secondary sort key like task priority or insertion order. I used System.nanoTime() as a monotonic tie-breaker for insertion order, which gave us strict total ordering without needing an external counter. PriorityQueue then behaved predictably under all conditions. This is one of those edge cases that doesn't show up in any tutorial because it depends on your data, not the algorithm itself.
Pitfalls That Waste Afternoon
Autoboxing is a silent performance killer. Every time you put an int into an Integer, Java allocates a new object. In a tight loop processing millions of values, that generates massive garbage collection pressure. The primitive collections in libraries like Eclipse Collections or fastutils exist specifically to avoid this, and they cut both memory usage and GC pauses significantly on data-heavy workloads. ConcurrentHashMap isn't a silver bullet. It prevents concurrent modification exceptions by segmenting locks, but it doesn't make every operation atomic across multiple reads and writes. If you read a value, compute something based on it, and write it back, another thread can modify the map between your read and write. Use.computeIfAbsent() or explicit locking for compound operations. I've seen bugs where two threads both passed the null check on get() and then both computed and inserted values, losing one of the results silently. Comparators that violate the general contract — specifically, the requirement that sign(compare(a,b)) == -sign(compare(b,a)) — cause unpredictable behavior in sorted collections and sorting algorithms. This comes up when your comparator uses floating-point arithmetic without handling NaN consistently, or when it compares objects of different types without throwing ClassCastException. Java's sort routines may throw IllegalArgumentException or produce incorrect ordering. Validate your comparators with a small test that checks reflexivity, antisymmetry, and transitivity across a range of inputs.
What Java Doesn't Give You Out of the Box
The standard library covers the common cases well, but some structures require third-party solutions. Immutable collections, indexed priority queues, persistent data structures, and bloom filters aren't in java.util. Libraries like Google's Guava provide ImmutableList and ImmutableSet, which are useful when you want to prevent accidental mutation in shared data. For a bloom filter, the Google Guava implementation is straightforward to integrate and saves significant memory when you need to check membership in large sets with occasional false positives. If you're doing heavy numerical work, consider using primitive-focused libraries instead of the generic collection API. The performance difference is measurable and often substantial. On a typical data processing pipeline I worked on, switching from ArrayList
Learning What Matters
Implementing these structures from scratch teaches you how they work, but it's not the most efficient use of time if you're preparing for production work. Reading the OpenJDK source for ArrayList, HashMap, and TreeMap is faster and more accurate. The implementations are well-documented and show the actual tradeoffs the language designers made. For algorithms, coding them against real datasets rather than artificial examples reveals the performance characteristics you'll actually encounter. A sorting algorithm that looks elegant on a thousand random integers may behave completely differently on nearly-sorted data or data with many duplicate keys. The core structures to understand thoroughly are ArrayList, HashMap, TreeMap, LinkedList (and why you usually shouldn't use it), and PriorityQueue. The core algorithms to be comfortable implementing and analyzing are binary search, merge sort, quicksort, Dijkstra's algorithm, and basic dynamic programming patterns. Everything else builds on these. Java's type system adds one more layer of complexity compared to other languages. Generics erase at runtime, which means you can't do things like generic array creation or check the type of a generic parameter with instanceof. This affects how you implement some structures. A generic BST, for instance, requires your elements to implement Comparable or you need to pass a Comparator. The compiler enforces this, but it also means your data structures can't be as flexible as you might want without accepting the Comparator approach throughout the entire class hierarchy.

Understanding when to use each structure and algorithm comes down to knowing your access patterns and data volume. Most production bugs related to data structures aren't caused by wrong logic — they're caused by right logic on the wrong structure for the actual workload. Profile before you optimize. Measure the actual bottleneck instead of assuming HashMap is faster than TreeMap because the documentation says so. The benchmark will tell you what's happening under your specific conditions, and those conditions are what matter.


