
Why Your Python Code Runs Slow Even Though the Logic Is Right
I spent three days tracking down a performance bug where a simple list comprehension was turning a 200-millisecond operation into a 45-second one. The culprit wasn't bad hardware or a bloated framework. It was me using a list for membership testing instead of a set, inside a nested loop processing roughly 80,000 rows. That changes the complexity from O(n) to O(n²) on what should have been a trivial lookup. This is the kind of thing that separates people who can write code from people who can write code that doesn't collapse under real data volumes. Data structures and algorithms aren't academic exercises you learn once in college and forget. They're the actual mechanics of how your program uses memory and CPU time. In Python specifically, the gap between a good choice and a bad one can be the difference between a script finishing before you grab coffee and one that runs for hours. I'm not talking about competitive programming edge cases. I'm talking about the difference between using a dictionary lookup versus scanning a list, or knowing when heapq beats sorted().
Data Structures And Algorithms In Python
The built-in types you already use are where most of this lives. Lists are dynamic arrays under the hood. Dictionaries are hash tables. Sets are hash sets. When you call len() on a list in Python, it's O(1) because Python stores the length as a property, not because it counts elements each time. That matters when someone writes code that repeatedly calls len() in a tight loop and wonders why it feels sluggish, even though the operation itself is cheap. The problem is what they're doing around it. Heapq is probably the most underutilized module in the standard library. It gives you a min-heap implementation with heappush and heappop, both O(log n). The common use case is finding the k-th largest or smallest element without sorting the entire dataset. Sorting takes O(n log n). Using a heap for the k-smallest elements takes O(n log k), which is meaningfully faster when k is small relative to n. I used this pattern to efficiently track the top 100 most frequent words in a 2-gigabyte log file without loading the entire word count dictionary into sorted order first. It cut the runtime from around six minutes to about forty seconds on the same machine.
What Most People Get Wrong About Big O
Big O notation describes worst-case asymptotic complexity. It tells you how an algorithm scales as input grows, not how fast it runs on your specific data right now. Two algorithms can have the same Big O classification but perform very differently on small inputs because of constant factors and memory layout. A bubble sort is O(n²) just like an insertion sort, but insertion sort typically runs two to three times faster in practice because it does fewer comparisons and swaps on partially sorted data, which is the kind of data you often encounter in real work. Another thing people miss: Python's sort is Timsort, which is O(n log n) worst case but degrades to O(n) on data that already contains ordered runs. If you're sorting data that arrives mostly sorted, like daily log entries or incremental updates, you're essentially getting a free linear-time sort. I've seen people replace Python's built-in sort with custom implementations thinking they were optimizing, only to watch performance drop by a factor of ten. Timsort is highly optimized in C. It's not going to be beaten by a textbook quicksort written in pure Python. Understanding when to use which data structure comes down to knowing the operation you'll perform most often. If lookups are frequent, a dictionary or set is usually the right call because average-case O(1) lookup beats O(n) list scanning every time. If you need ordered traversal with efficient insertion and deletion at both ends, collections.deque gives you O(1) popleft and append, whereas a list gives you O(n) for popleft because it has to shift every remaining element. I once had a producer-consumer pipeline that was bottlenecked on deque operations, and switching from list.pop(0) to collections.deque.popleft() reduced per-item overhead from roughly 2 microseconds to under 0.1 microseconds. On a pipeline processing millions of records, that added up to several minutes of wall time saved.
Get the Full Details
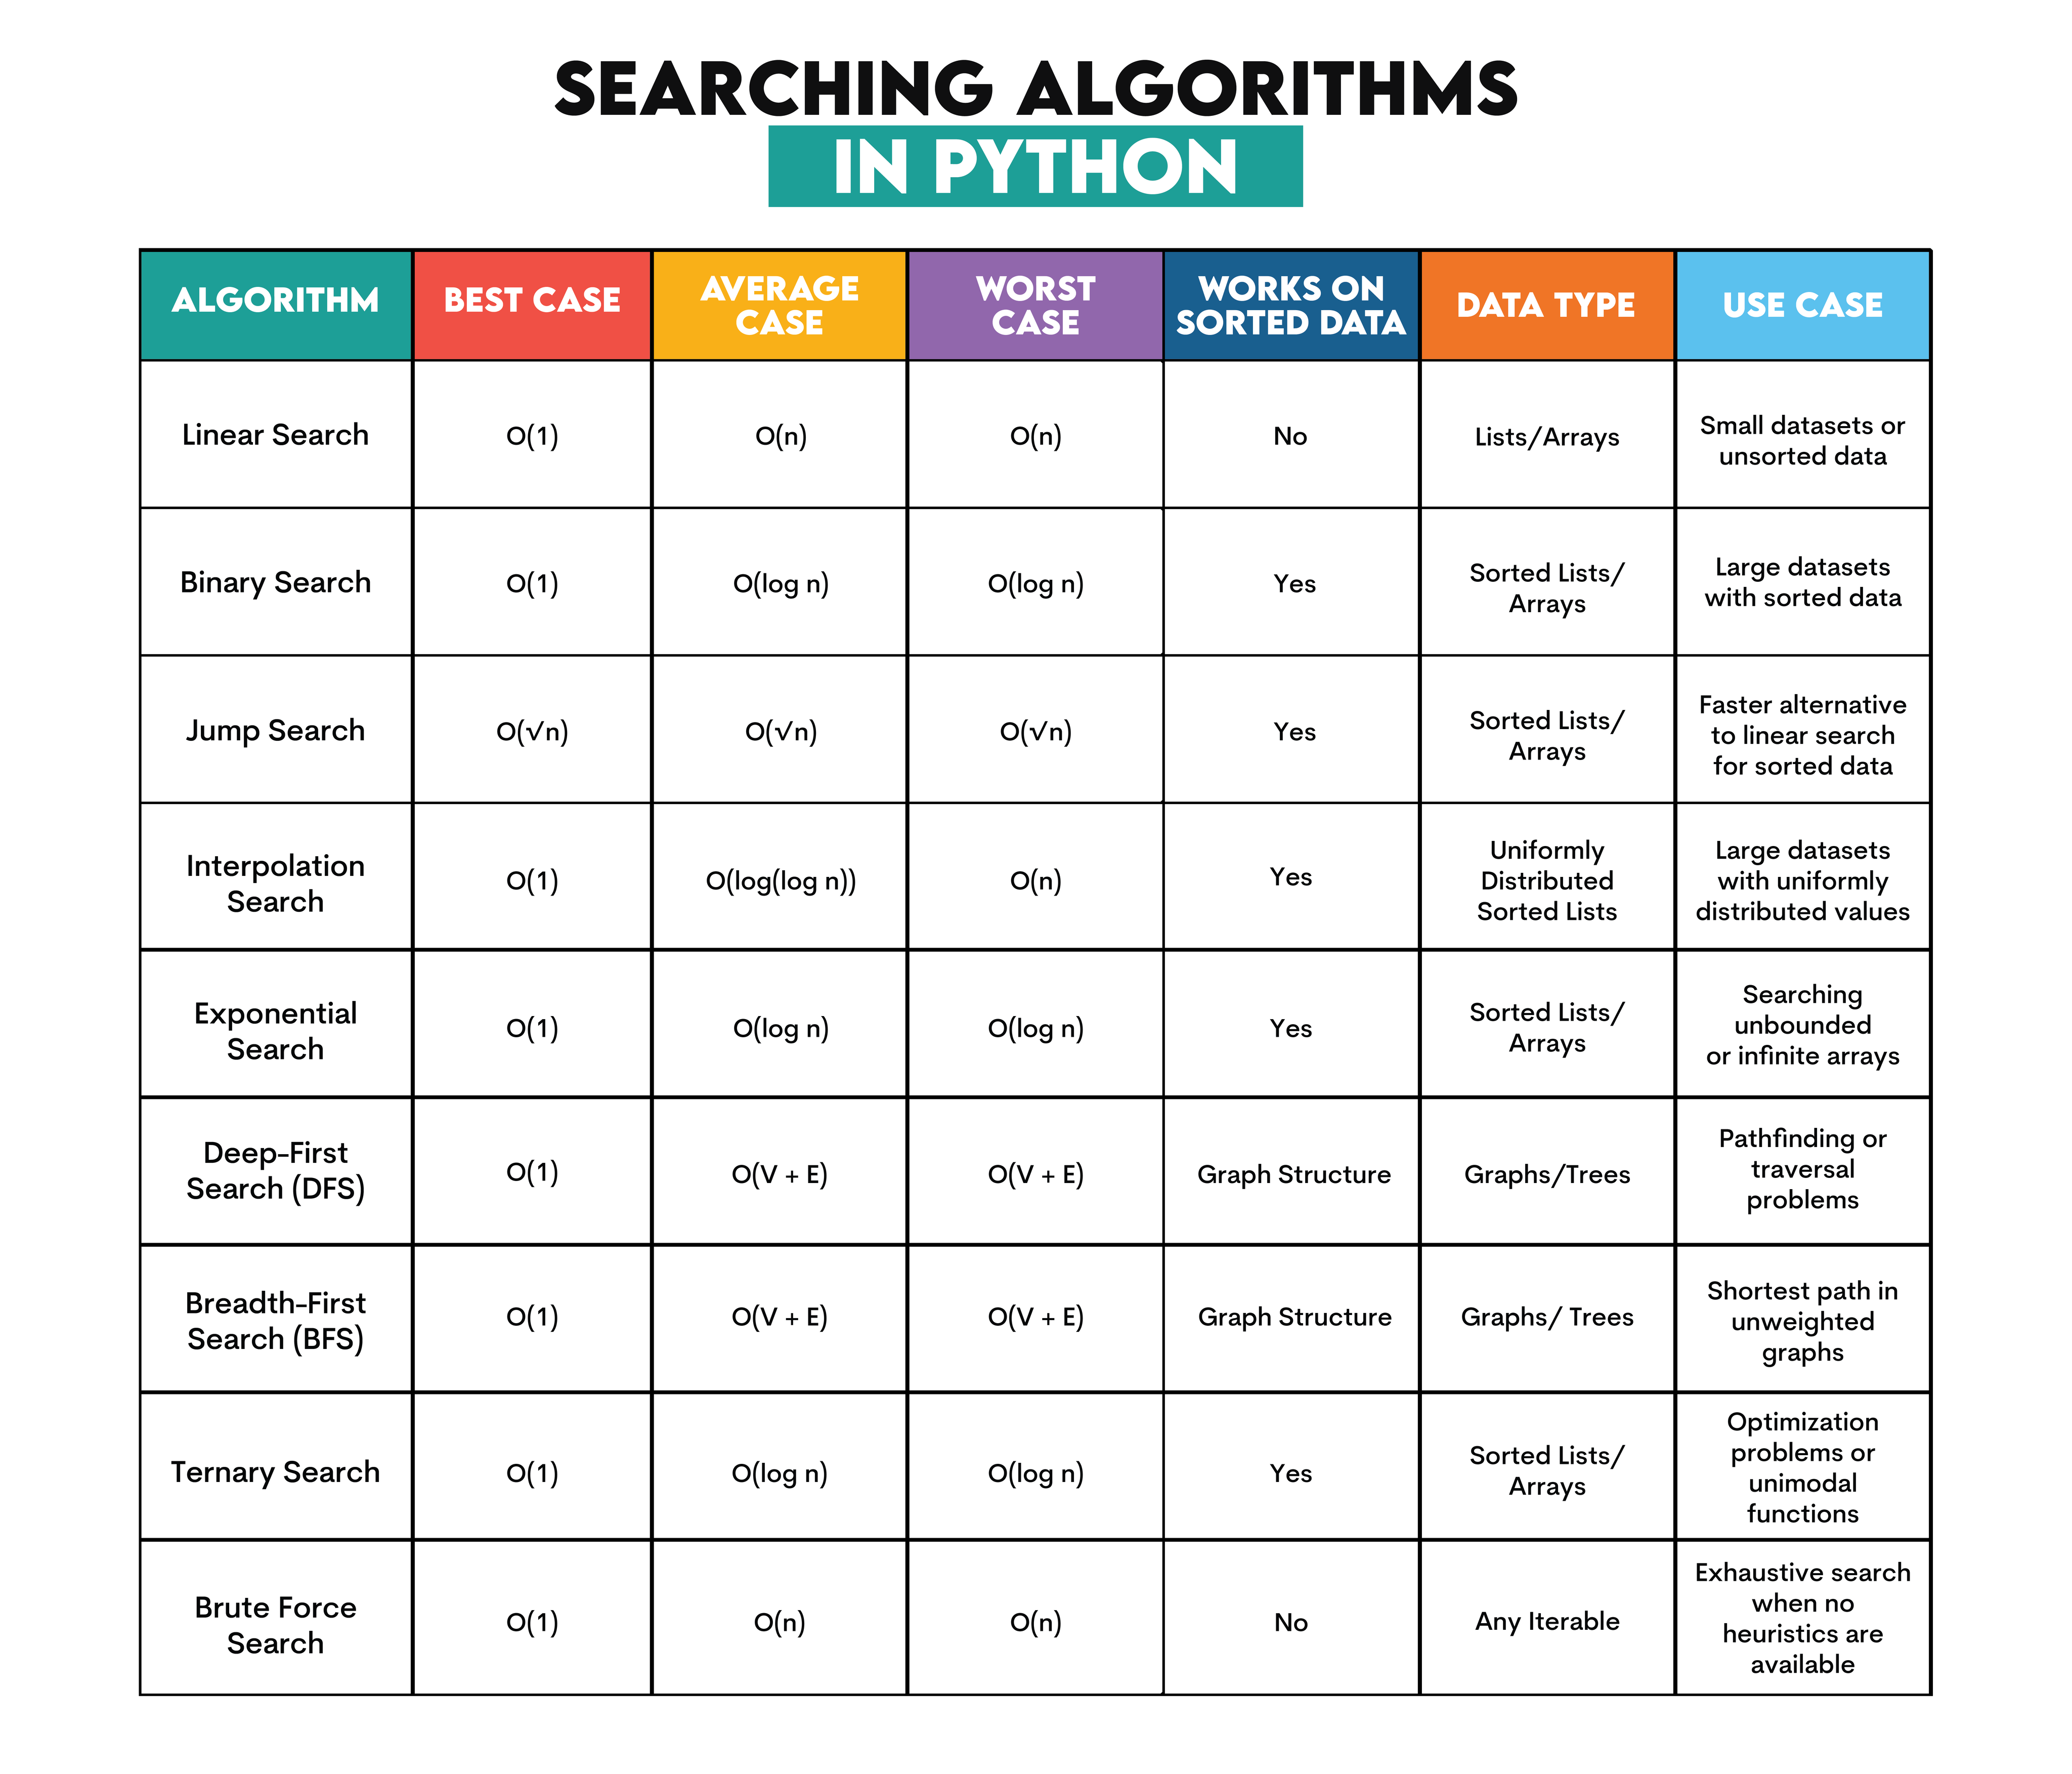
Recursion and the Stack Problem
Python doesn't optimize tail recursion. There's no tail call optimization, so recursive solutions that go deep will hit the recursion limit, which defaults to 1000 frames. You can increase it with sys.setrecursionlimit(), but that's a bandage, not a solution. Deep recursion consumes stack memory, and Python's C stack frame isn't cheap. An iterative approach or an explicit stack using a list or deque is almost always the better call for production code. I worked on a graph traversal problem where a recursive DFS was hitting the recursion limit on graphs with a few thousand nodes and deep paths. The iterative version using an explicit stack was not only more reliable, it was also about 30% faster because function call overhead in Python is significant. Each call creates a new frame, and frame creation isn't free. On a problem that ran thousands of traversals, that overhead stacked up.
Memory Efficiency Matters More Than You Think
Python objects carry overhead. A single integer in Python is not just the integer value. It's a full object with a reference count, type pointer, and the value itself, typically 28 bytes on a 64-bit build. A list of one million integers isn't just eight million bytes for the pointers. Each integer is a separate object, so you're looking at roughly 28 million bytes for the integers plus 8 million bytes for the list pointers, totaling around 36 megabytes. A numpy array of the same million integers would take about four megabytes because it stores the raw C integers contiguously without per-element object overhead. When you're working with large datasets, this difference is the gap between your script running fine and your machine swapping to disk. I once had a script that loaded a dataset of user sessions, each represented as a list of event dictionaries, and it was consuming over 4 gigabytes of RAM. Switching to using __slots__ on custom classes and converting frequently accessed fields into namedtuple instances dropped the memory footprint to about 600 megabytes without changing the external API at all. The tradeoff is that you lose some flexibility with __slots__, but for structured data that doesn't change shape, it's worth it.
When to Reach for External Libraries
The standard library covers a lot, but there are limits. For graph algorithms, networkx is convenient but not designed for performance. It's fine for small to medium graphs up to maybe fifty thousand edges, but once you go larger, the overhead becomes noticeable. If you're doing shortest path calculations on a graph with hundreds of thousands of nodes, consider using something like igraph or even a dedicated library like rustworkx, which is a high-performance graph library with a Python interface and C++ backend. For numerical algorithms, numpy and scipy are essential. Vectorized operations in numpy are orders of magnitude faster than equivalent Python loops because the inner loop runs in compiled C rather than interpreted Python bytecode. A matrix multiplication that takes fifteen seconds in pure Python can take under a hundred milliseconds with numpy on the same data. The learning curve is shallow if you already know the basics, and the performance gains are immediate. There's also the question of whether you should be solving the problem at all. Sometimes the right answer is to change the algorithm or the approach rather than optimize the implementation. I had a search feature where users were querying a database of products with free text. The initial implementation was a linear scan over a PostgreSQL table using LIKE with wildcards. That was terrible for scale. The fix wasn't a better search algorithm. It was adding a full-text search index and using tsvector queries instead. Query time dropped from about 800 milliseconds on a table of two hundred thousand rows to under five milliseconds with the right index. No data structure change was needed because the bottleneck wasn't the data structure. It was the query strategy.

A Practical Workflow for Choosing
Start by identifying what operations your data needs to support most often. Read, write, search, insert, delete, iterate, sort. Count how many of each operation you expect. The operation that dominates should drive your choice. If you're reading more than you're writing, a dictionary or set makes sense. If you're writing sequentially and reading from the front, a deque is better than a list. If you need to maintain order while doing repeated insertions and deletions, consider a balanced tree structure, though Python doesn't have a built-in one, and you'd reach for something like sortedcontainers or implement it yourself. Measure before you optimize. I've seen people restructure entire data pipelines based on theoretical complexity without measuring anything. Theoretical Big O is useful for understanding scaling behavior, but constant factors, cache locality, and Python's interpreter overhead can make a theoretically slower algorithm faster in practice for the input sizes you're actually dealing with. Profile your code with cProfile or line_profiler before committing to a refactor. You'll save yourself a lot of wasted time. The real skill isn't memorizing every data structure and its complexity. It's developing an intuition for which structure matches which problem. That intuition comes from writing enough code, hitting enough performance problems, and figuring out what worked and what didn't. The list-of-lists anti-pattern, the unoptimized greedy approach that works until the dataset grows, the recursive function that crashes on deep inputs. These are the things that teach you more than any tutorial ever will.


