The thing nobody tells you about data structures
Most people approach Data Structures Practice Problems completely backwards. They open LeetCode, pick a random medium-difficulty graph problem, stare at it for forty minutes, read the solution, and call it a day. They've solved one problem. They've learned nothing. This cycle repeats for three months and they still can't tell you when to reach for a heap versus a stack. Here's what actually works, based on the last several years of writing code for a living and coaching people who are interviewing at places like Amazon, Google, and Stripe.What Data Structures Practice Problems Actually Means
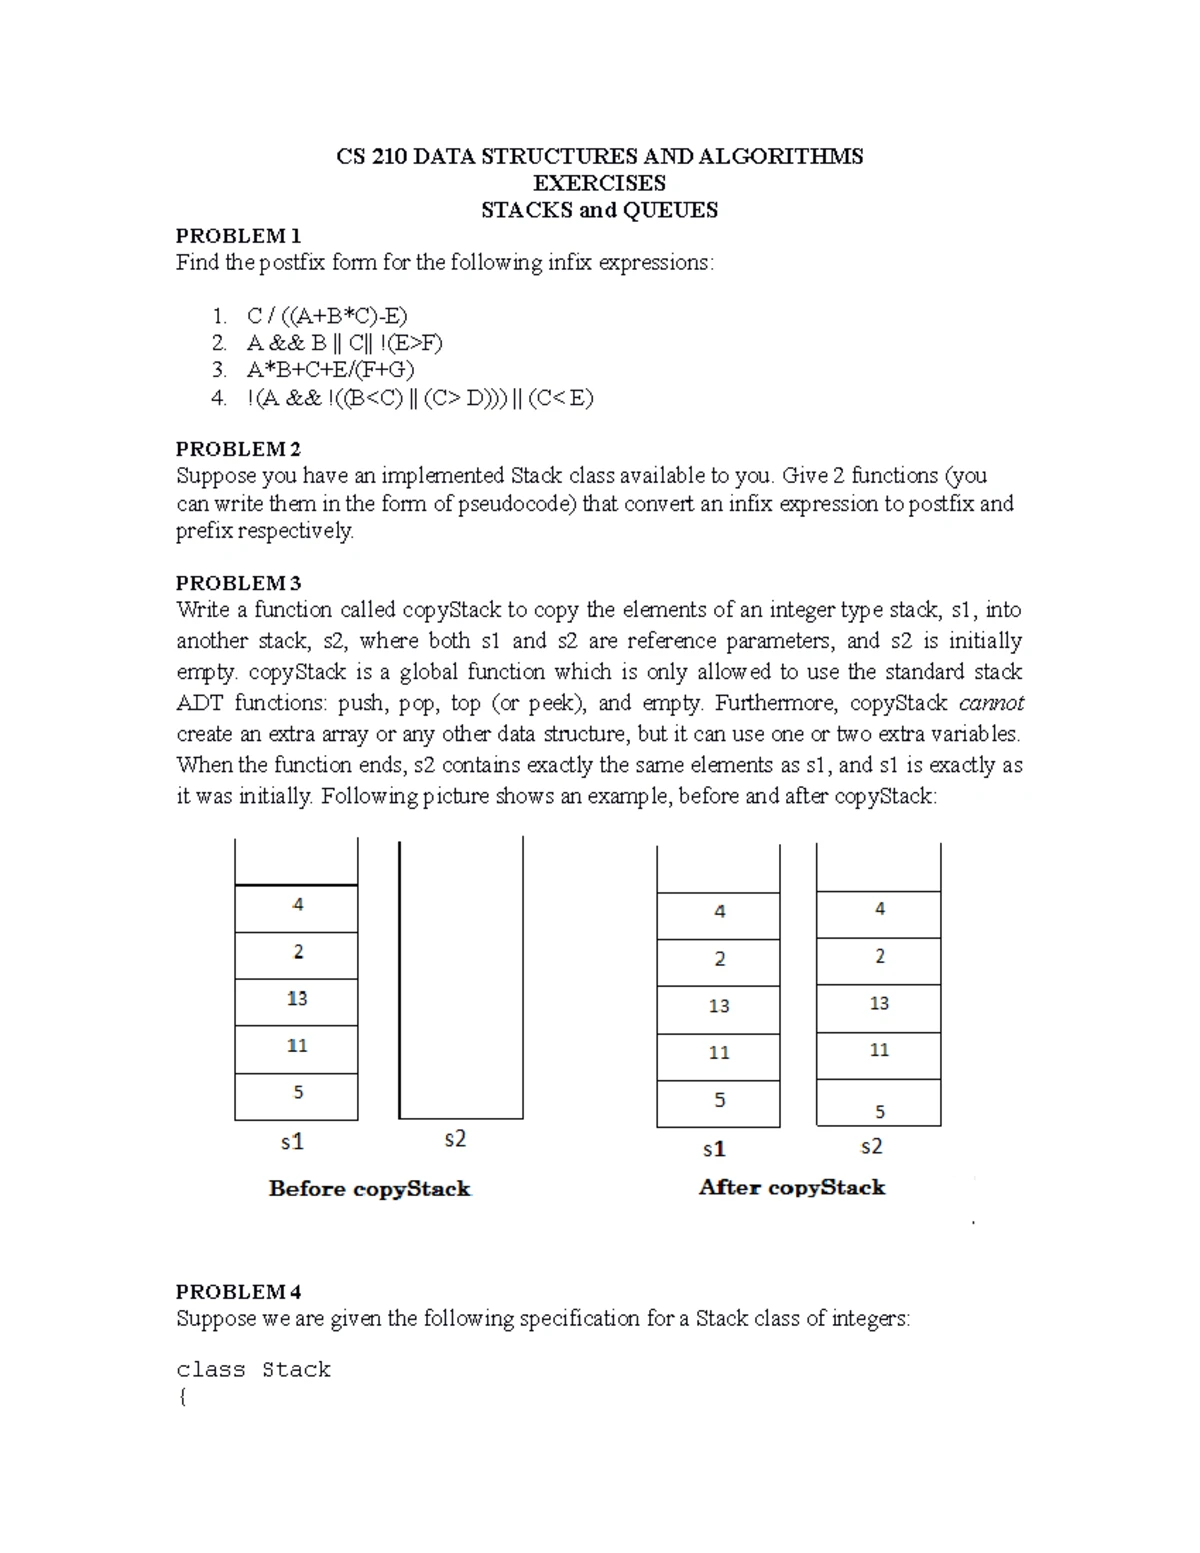
Data Structures Practice Problems isn't a single resource or a specific course. It's the deliberate, repeated exposure to algorithmic challenges structured around the underlying data structures they test. A well-designed practice set groups problems by pattern: hashmap lookups, two-pointer techniques, sliding windows, BFS and DFS traversals, priority queue applications, and so on. The goal isn't volume. It's pattern recognition under pressure. I spent two years working as a backend engineer before I realized my approach was fundamentally broken. I was solving maybe five hundred problems across platforms but getting them wrong in interviews because I'd memorized solutions, not patterns. The turning point was when I started organizing every problem I practiced into one of about twelve core patterns and tracking which ones I could solve cleanly versus which ones made me second-guess myself. The method I use now: pick one pattern. Solve three easy problems in a row. Then one medium. Then one hard. Move to the next pattern only after you can explain the solution to someone else without looking at code. This usually takes two to three weeks per pattern for a beginner, sometimes longer for the harder ones like union-find or segment trees.I keep a simple spreadsheet. Column one is the pattern name, column two is the problem link, column three is whether I solved it on the first try, column four is the time I spent, and column five is a note about what tripped me up. After six months of this, the spreadsheet becomes a much better study guide than any curated list someone published on the internet.
Why most people fail at Data Structures Practice Problems
There are two mistakes that show up again and again, and they're not what you'd expect. The first is trying to solve the hard version of a problem before you're comfortable with the easy version. I remember one specific problem involving a sliding window where the easy version asked for the longest substring without repeating characters, and the medium version asked for the longest substring with at most two distinct characters. I jumped straight to the medium version, wrote a brute force solution that timed out, and spent an hour on it. The hard version of that same problem exists too — longest substring with at least k repeating characters — and it adds a divide-and-conquer angle on top of the window logic. If you don't own the easy version first, you're building on sand. The second mistake is far more common. People treat every problem as unique. They learn "reverse a linked list" as one skill and "merge two sorted lists" as another skill, when both of them are literally the same technique with the same pointer manipulation. A singly linked list traversal with a prev-current-next pattern is one of the few moves you need. Recognize it early and stop reinventing it.Another nuance that rarely gets discussed: you should spend significantly more time on array and string problems than on tree or graph problems if you're preparing for generalist technical interviews. Roughly sixty percent of the data structure questions in typical phone screens involve arrays or strings. A hashmap almost always solves two-sum style questions. Two pointers almost always solves palindrome or pair-sum problems. If your interview prep is weighted evenly across all data structure types, you're spending too much time on obscure graph traversals and not enough on the problems that actually show up.
A specific edge case that cost me three days
During interview prep for a senior role, I hit a problem involving grouping anagrams where the input could contain empty strings and duplicate groups. My first pass used a standard hashmap mapping sorted character keys to lists of words. It passed the sample cases but failed on a hidden test. The issue was subtle: I was mutating the input list while iterating over it, which caused index shifting and skipped elements in one particular branch. I didn't catch it because my test cases were too clean. The workaround was straightforward — I made a copy of the input array before processing and iterated over the copy instead. But the real lesson was that I should have written a fuzzer to generate random edge cases instead of hand-crafting tests. A random generator that produces arrays with nulls, duplicates, empty strings, and very large inputs catches these things faster than any manual test suite. I've used this approach ever since, and it's saved me from at least a dozen similar bugs.You'll find similar pain points across every pattern. A union-find problem I did recently had a test case with a single element, which bypassed my path compression logic entirely because the base case wasn't explicit. A heap problem failed when the heap was empty and I tried to peek without checking. These aren't hard problems intellectually. They're hard because interviewers build their test suites around the corners, and most people's practice doesn't cover the corners.
Get the Full Details
Data Structures Practice Problems that build real skill
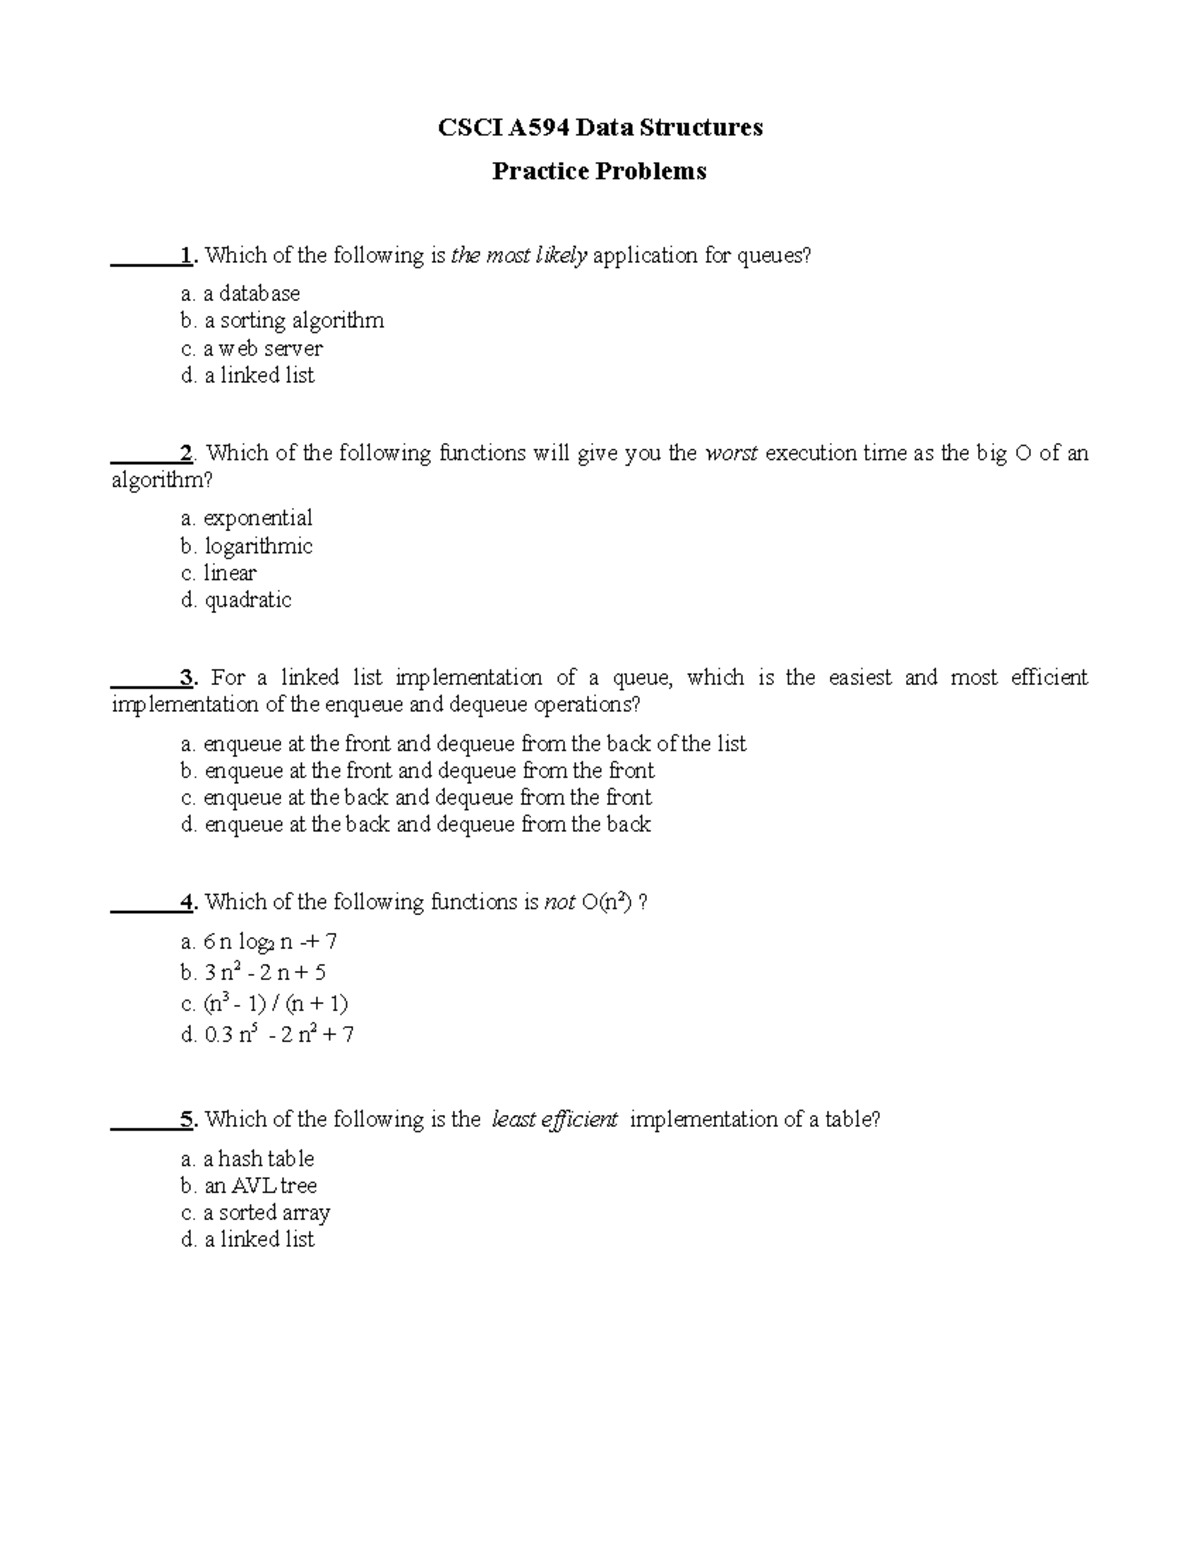
If you're looking for where to actually practice, here's what I'd recommend, ranked by usefulness rather than popularity. LeetCode remains the standard, but you need to use it strategically. Filter by topic, not by difficulty. Do all the easy hashmap problems in one sitting. Then all the medium ones. Track your progress the way I described. Don't bounce between topics. NeetCode.io offers a structured road map that follows exactly the pattern-based approach I mentioned. It groups problems by technique and orders them from simple to complex within each group. This is useful if you want someone else to make the decisions about what to practice next. CodeSignal has a good arcade mode section for data structure fundamentals, and its interview preparation section includes timed sessions that simulate real conditions. The timing aspect matters because it forces you to move past the "I can solve this if I have all day" comfort zone. Google's algorithm course on Coursera and Princeton's algorithms course on edX are both free and cover the theoretical foundation more thoroughly than most practice platforms. They won't get you hired directly, but they'll help you understand why a particular data structure has a certain time complexity, which makes remembering the implementation much easier.The free practice lists at github.com/gzc/ICPC-template and the curated lists at github.com/trekhleb/learn-algorithms are worth bookmarking. They're maintained by people who actually compete in programming contests, so the problems lean toward the harder, less polished end of the spectrum. That's good if you want a challenge, not good if you're starting out.
The part nobody talks about: time complexity intuition
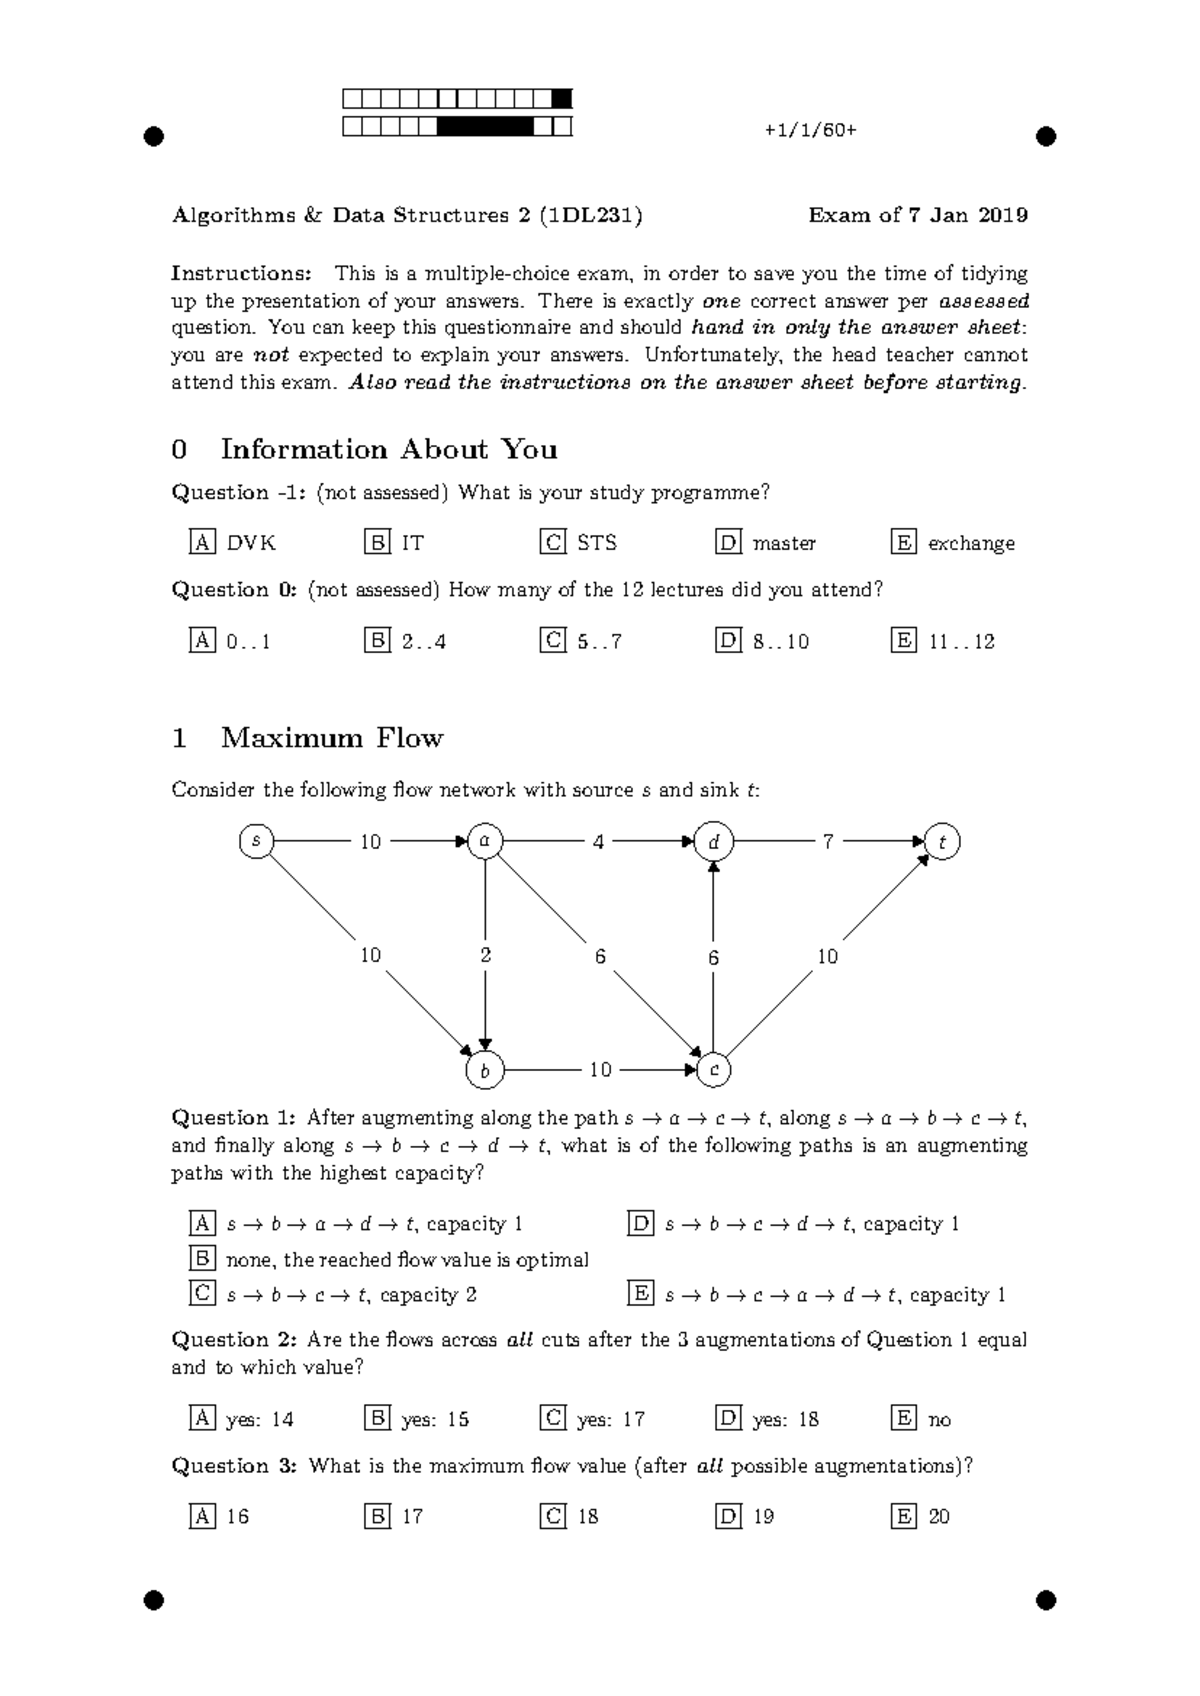
You can memorize every implementation of every data structure and still fail an interview if your time complexity analysis is weak. Interviewers will watch you write code and then ask, "What's the complexity?" If you hesitate or give an answer you're not sure about, they'll dig deeper until they find the crack. The trick isn't memorizing formulas. It's developing an intuition for what operations cost. Every array lookup is O(1). Every binary search on a sorted array is O(log n). Every tree traversal is O(n) where n is the number of nodes. A nested loop where the inner loop depends on the outer loop variable is usually O(n²), unless there's a geometric reduction happening, in which case it might be O(n log n) or even O(n).I once saw a candidate solve a problem in O(n²) when an O(n) solution was obvious, and when I pointed it out, they couldn't explain why theirs was slower. They'd written the code correctly but hadn't thought about what the code was actually doing at each step. That's the difference between practicing problems and learning them. Before you move on from any problem, write down the time and space complexity, explain why it's correct, and identify whether there's a faster approach you might have missed.
When these problems won't help you
I need to be honest about the limitations. Data Structures Practice Problems alone won't prepare you for system design interviews, which are standard at the senior level. They won't teach you about concurrency, caching strategies, or database indexing. They also don't cover the softer skills: asking clarifying questions, negotiating scope, or handling follow-up questions that push your solution in an unexpected direction. There's also a ceiling effect. Once you've solved maybe two hundred well-chosen problems across all the core patterns, additional practice yields diminishing returns. I've seen people grind five hundred problems and still freeze in interviews, and I've seen people solve one hundred fifty problems thoughtfully and perform well. The difference was that the second group reviewed every mistake, understood why each approach worked, and could explain tradeoffs out loud.If you're targeting companies known for especially deep algorithmic rounds, like Google or certain quantitative finance firms, you may need to go beyond the standard practice sets and work on competition-level problems. But for most engineering roles, the pattern-based approach I described covers the vast majority of what you'll encounter.
My recommended schedule for the next six weeks
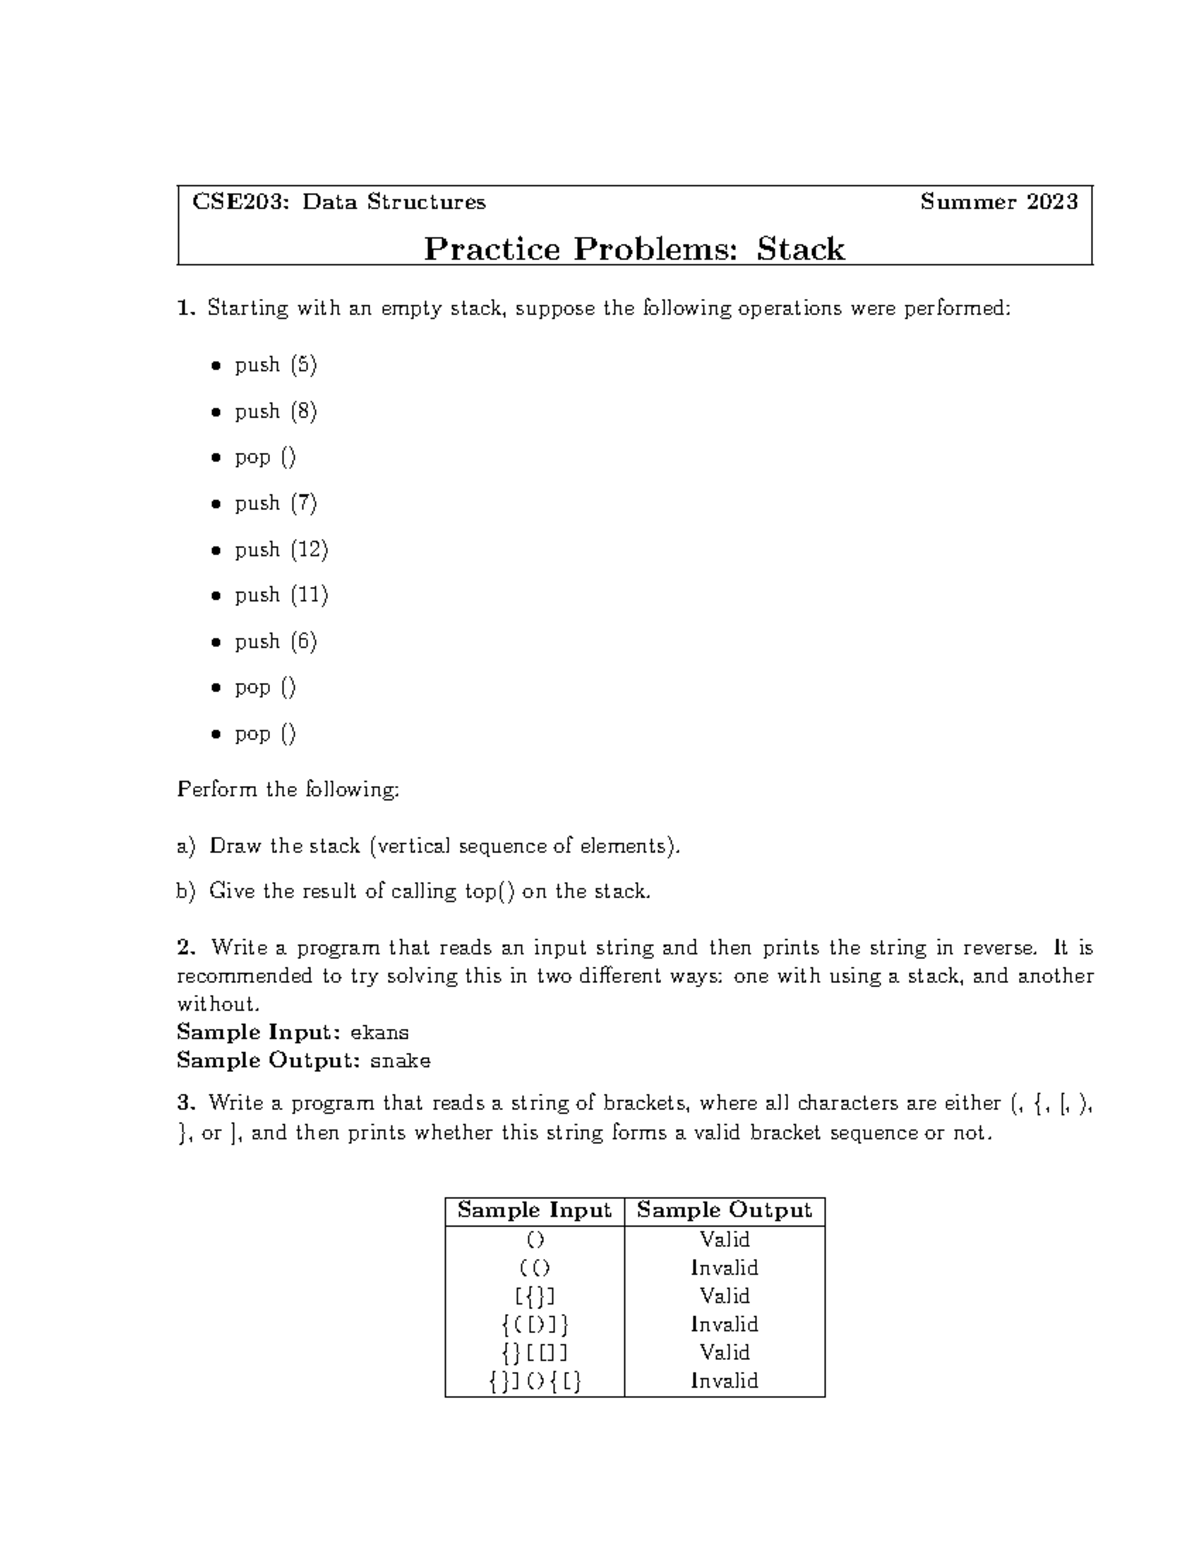
Weeks one and two: arrays and strings. Focus on two pointers, sliding window, and prefix sum techniques. Aim for about six problems per day, three easy and three medium. Weeks three and four: hashmaps, stacks, and queues. HashMaps overlap heavily with arrays, so expect repetition. Stacks appear in bracket matching, monotone stack problems, and expression evaluation. Queues appear in BFS and sliding window maximum problems. Week five: linked lists and trees. Linked lists are mostly pointer manipulation — reverse, merge, detect cycles. Trees require understanding recursion and traversal order. Do BFS and DFS on trees until you can write both from scratch without looking. Week six: heaps, graphs, and unions. Heaps are essential for top-k and median-finding problems. Graphs require comfort with adjacency lists and BFS/DFS. Union-find is the rare pattern that most people haven't seen but shows up with annoying frequency in medium-difficulty questions.That's roughly one hundred twenty to one hundred eighty problems across six weeks, assuming you practice an hour a day. Fewer hours means more weeks. More hours means you'll burn out. One hour is sustainable for most people who already have full-time jobs.
Where to download practice material
There isn't a single downloadable file that covers everything, but there are several free resources you can use as a starting point. The GitHub repositories I mentioned above contain problem lists with solutions. NeetCode's list is available as a JSON file you can import into custom flashcard apps if you want spaced repetition. The Princeton algorithms course provides problem sets with autograders. If you want something you can print and work through offline, the classic "Cracking the Coding Interview" by Gayle Laakmann McDowell still has the most organized collection of Data Structures Practice Problems in a single book, with solutions at the back. It's not free, but it's widely available used for under ten dollars, and the problems are representative of what actually shows up in interviews at mid-level companies.The single most valuable resource you can create yourself is that spreadsheet I described. It takes about fifteen minutes to set up and a few seconds to update after each problem. After six weeks, you'll have a personalized map of exactly what you know and what you don't, and that's worth more than any curated list someone else made.