Why people get data table definitions wrong
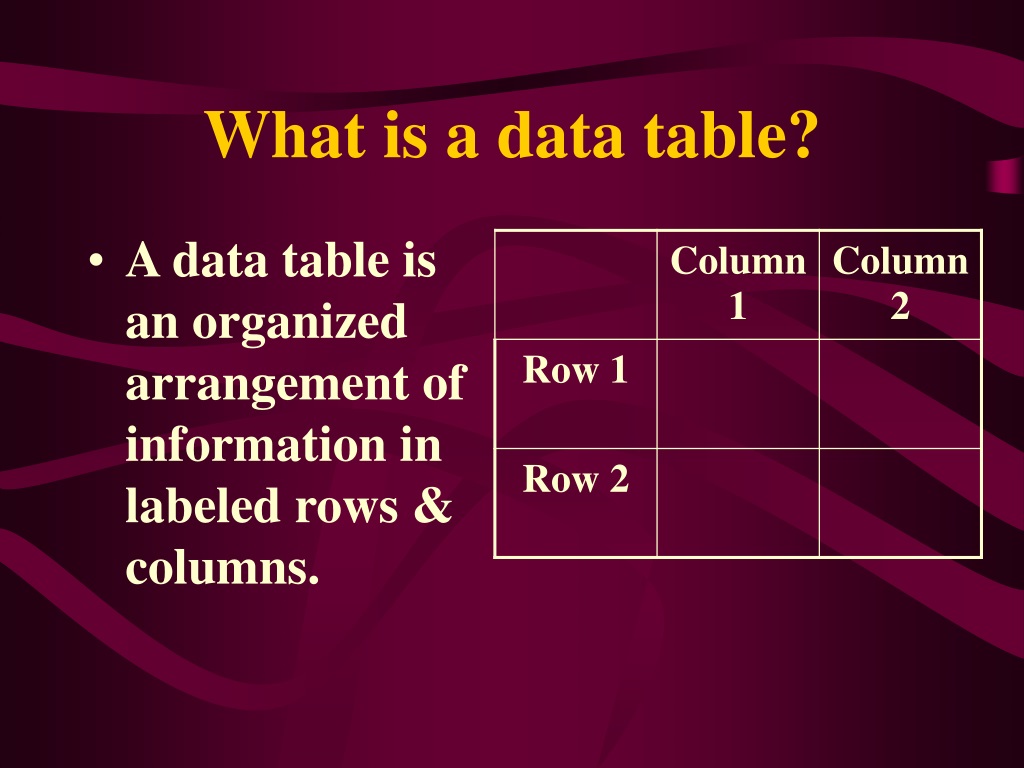
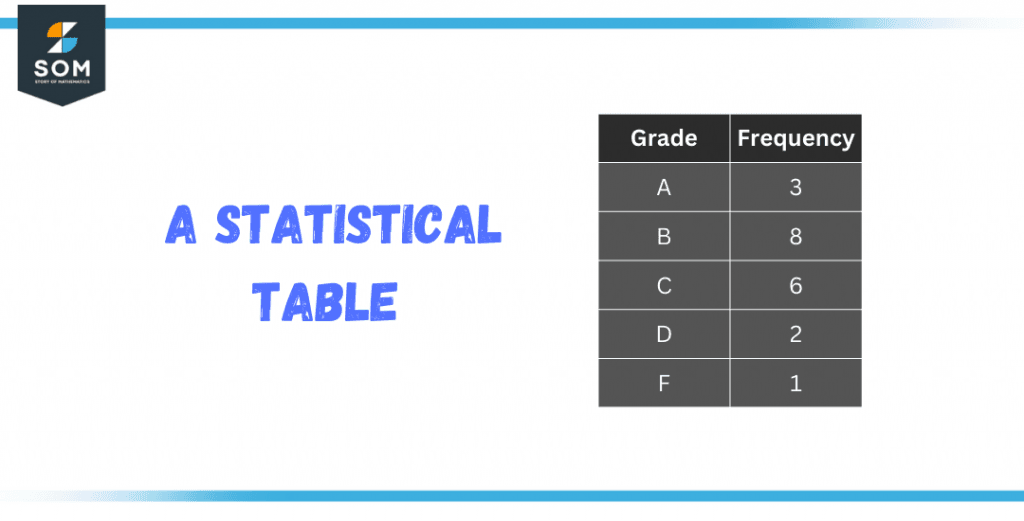
Most engineers treat table schemas like a one-time setup task. You define the columns once, load the data, and move on. That approach collapses the moment you need to join three tables at 2 AM because an alert fired. The definition isn't documentation. It's operational code, and it has the same failure modes as any other production system. It's the practice of formally specifying every structural attribute of a data table before it touches production: column names, data types, constraints, indexes, partition keys, default values, and the relationships between tables. The "science" part is mostly about consistency and predictability. When you skip the formal spec and just create tables on the fly, you get schema drift, ambiguous foreign keys, and queries that work in dev but explode under load. A proper definition covers things people usually forget. Nullable handling rules matter more than you'd think. The difference between NULL and an empty string breaks joins silently for months before anyone notices. Partitioning strategy isn't optional either. I once spent six hours debugging a query that returned correct results but took forty-two minutes because the table had no partition key despite being a twelve billion row analytics store. The definition should have specified that before the table was created. It didn't.
The practical workflow
Here's how it actually works in a team environment. You start with a business requirement document. Not a slide deck. A document that lists the entities, the attributes for each, and how they relate. From that you derive the schema definition. You write it as DDL—CREATE TABLE statements with every constraint explicitly declared. Then you version control it alongside your application code. Every change goes through a migration file with a rollback script. No exceptions. The migration pattern is where most teams fail. They write forward-only migrations and never test the reverse. I've seen production outages caused by a developer who dropped a column to fix a bug, committed the migration, and then realized the rollback wasn't possible because nobody wrote one. The table was down for three hours while someone manually reconstructed the data from backups. Here's a quick example of what a solid definition looks like in practice:
orders table — PostgreSQL Column: order_id, type: UUID, constraint: PRIMARY KEY, nullable: false Column: customer_id, type: UUID, constraint: REFERENCES customers(customer_id) ON DELETE CASCADE, nullable: false
Get the Full Details
Column: status, type: VARCHAR(20), constraint: CHECK (status IN ('pending', 'processing', 'shipped', 'delivered', 'cancelled')), nullable: false, default: 'pending' Column: created_at, type: TIMESTAMPTZ, constraint: DEFAULT NOW(), nullable: false Index: idx_orders_customer_id on customer_id
Partition: range on created_at, monthly buckets That last line about partitioning is critical. If your table is going to grow past a few million rows and you're querying by date ranges, partitioning is not a nice-to-have. It's the difference between a sub-second query and one that times out.
Common pitfalls
Pick a data type and stick with it across the stack. I once inherited a system where order amounts were stored as DECIMAL in one table, FLOAT in another, and VARCHAR in a legacy reporting view. Math operations on those columns produced results that looked right until you tried to aggregate them. FLOAT precision issues turned a straightforward SUM query into a forensic investigation. Two hours lost. A DECIMAL everywhere would have prevented it entirely. Another issue is over-indexing. Every index slows down writes. Insert throughput dropped by roughly 40 percent on a high-volume transaction table because someone added six indexes without measuring the write load first. The definition should specify which columns get indexed and why. "We might need this for filtering" isn't a valid reason. Write down the actual query pattern that requires the index. Null handling is the silent killer. Most ORMs and application layers treat NULL differently than the database does. If your application code expects NULL to mean "not provided" and the database treats it as "unknown," you'll get phantom rows in your counts and broken JOIN logic. Define the rule explicitly in the table spec. Make it a team standard, not a personal preference.

Tooling and constraints
There are tools that help automate this. Liquibase and Flyway for migration management. dbt for transformation logic and documentation. Great Expectations for data quality validation. None of them replace the need for a clear definition document. They enforce whatever you hand them. I use a combination of Flyway for schema migrations and a JSON schema file stored in the same repository that describes the expected structure. The JSON file runs in CI as a validation check. If a migration changes a column type or removes a constraint, the build fails before it hits staging. This caught a bad migration last month that would have dropped the primary key on a critical lookup table. The pipeline stopped it in under two seconds.
When this approach breaks down
Data Table Definition Science doesn't work well for exploratory data science or rapid prototyping. If you're running a proof of concept and the schema changes every day, formal definitions slow you down. In those cases, use an ephemeral database and accept the mess. Just don't let that schema leak into production. There's also a limit to how detailed your definition should be. Over-specifying leads to rigidity. I worked on a project where the table definition required nine different constraint validations before any row could be inserted. Development velocity dropped by about sixty percent because every minor schema change required updating migration files, validation configs, and test data across four repositories. Less is often enough. Define the constraints that prevent actual business problems. Skip the rest. The biggest bottleneck is team coordination. A formal definition process only works if everyone follows it. I've seen schemas become a patchwork of hand-written migrations, direct production edits, and automated tooling all fighting each other. The fix is simple in theory—everyone commits migrations through the same system—but cultural enforcement is hard. Require pull request reviews on all migration files. That's usually sufficient to catch unauthorized changes.
Another limitation: version control doesn't solve data quality. A perfect schema definition tells you nothing about whether the data inside the table is correct. You still need monitoring, validation jobs, and data audits. The definition is necessary but not sufficient for reliable systems.