What Happens When You Stop Drawing Pretty Boxes
I spent years watching people produce Entity Relationship Diagrams that looked beautiful and meant absolutely nothing once the database went live. The diagram would have clean crow's feet notation, proper cardinality markers, and enough entities to fill a large document. Then someone would actually try to query against it and realize the relationships didn't match how the application was trying to use the data. This is why I stopped treating ERD creation as an exercise in making diagrams that please stakeholders and started treating it as the first draft of the actual schema. The process I actually use has four stages that most tutorials skip because they make the methodology look more linear than it is. You start by identifying the core business objects as entities, then map the relationships between them with proper cardinality, normalize the model to remove redundancy, and finally translate it into the actual DDL. The trick is that you do not start with normalization. Beginners almost always begin by normalizing their entities to 3NF before they have even identified the relationships, which means they spend hours making decisions about primary keys and foreign keys on entities that will get reorganized anyway once the relationship mapping exposes issues. My first step is always unstructured. I pull a whiteboard or open a blank diagramming tool and dump every noun I can extract from the requirements without worrying about whether something is an entity, an attribute, or an association. This phase usually takes between thirty minutes and two hours depending on how ambiguous the requirements are. What matters here is volume of ideas, not accuracy. You can refine later. Most people skip this and go straight into drawing entities with perfect notation, which locks them into a structure they cannot easily escape.
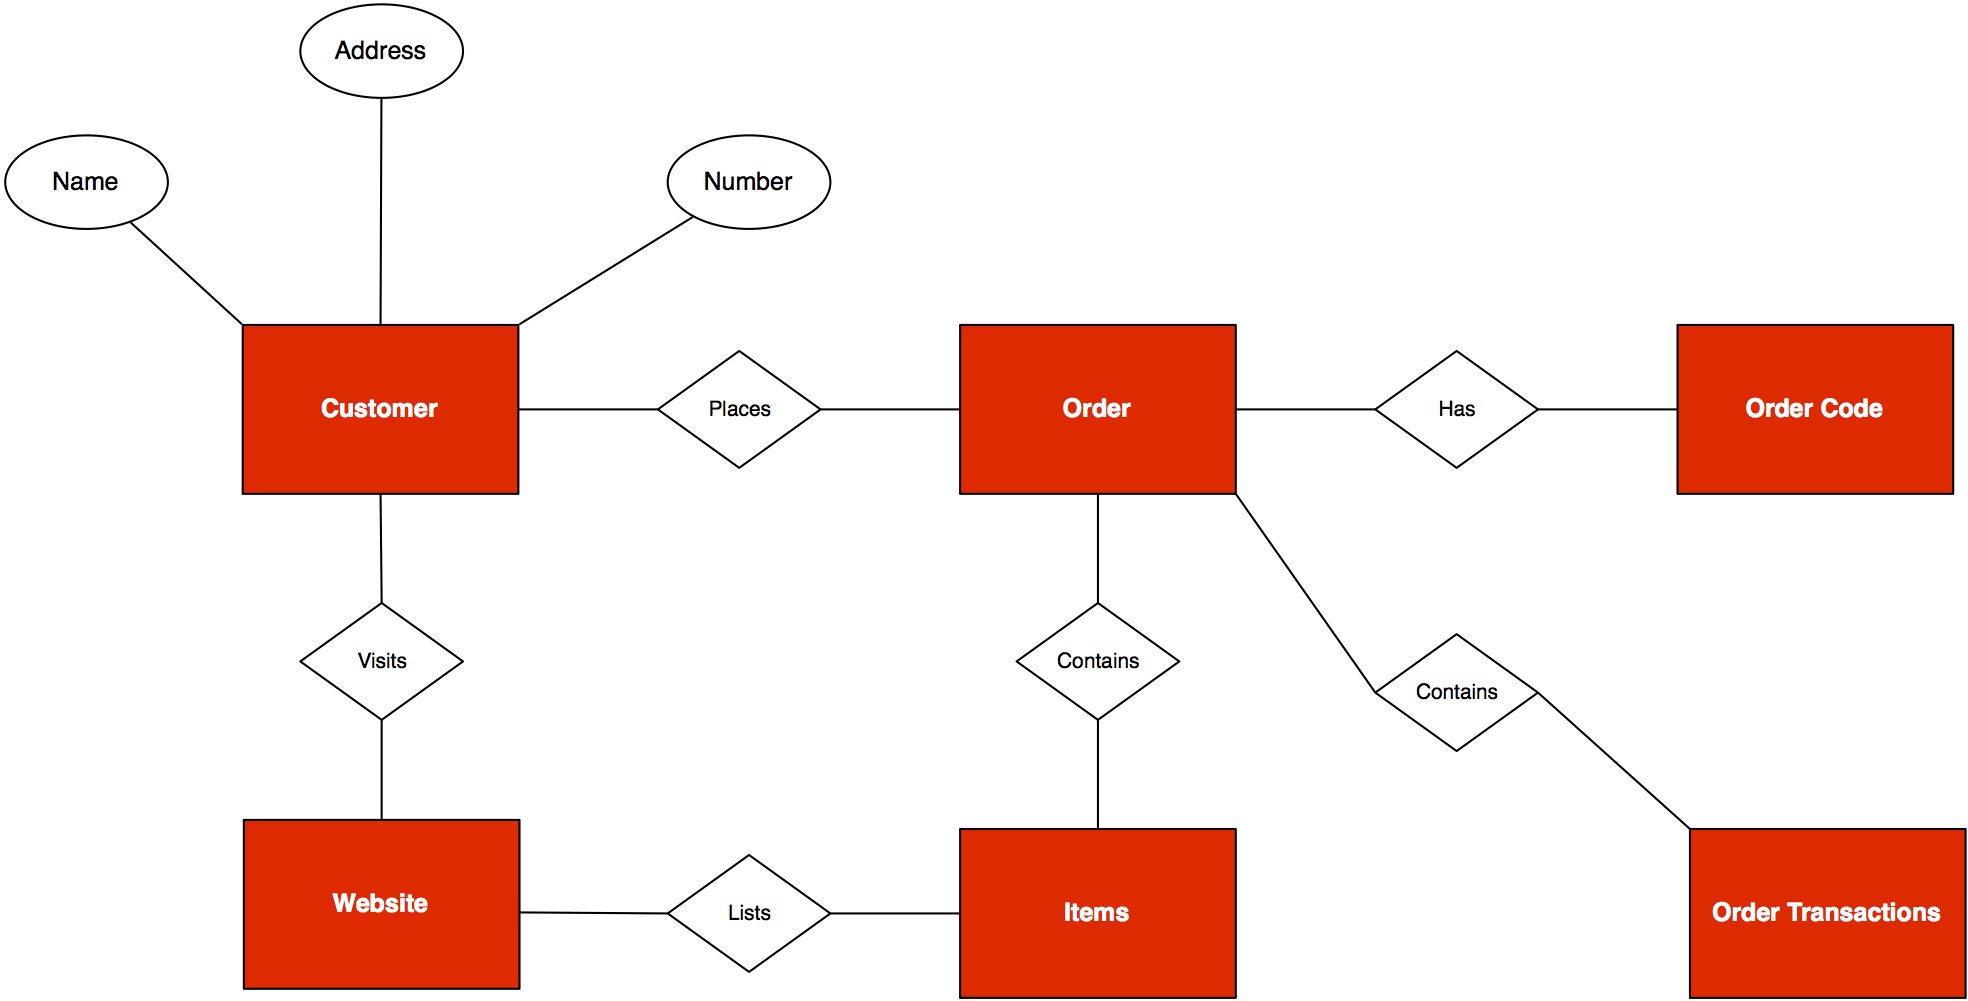
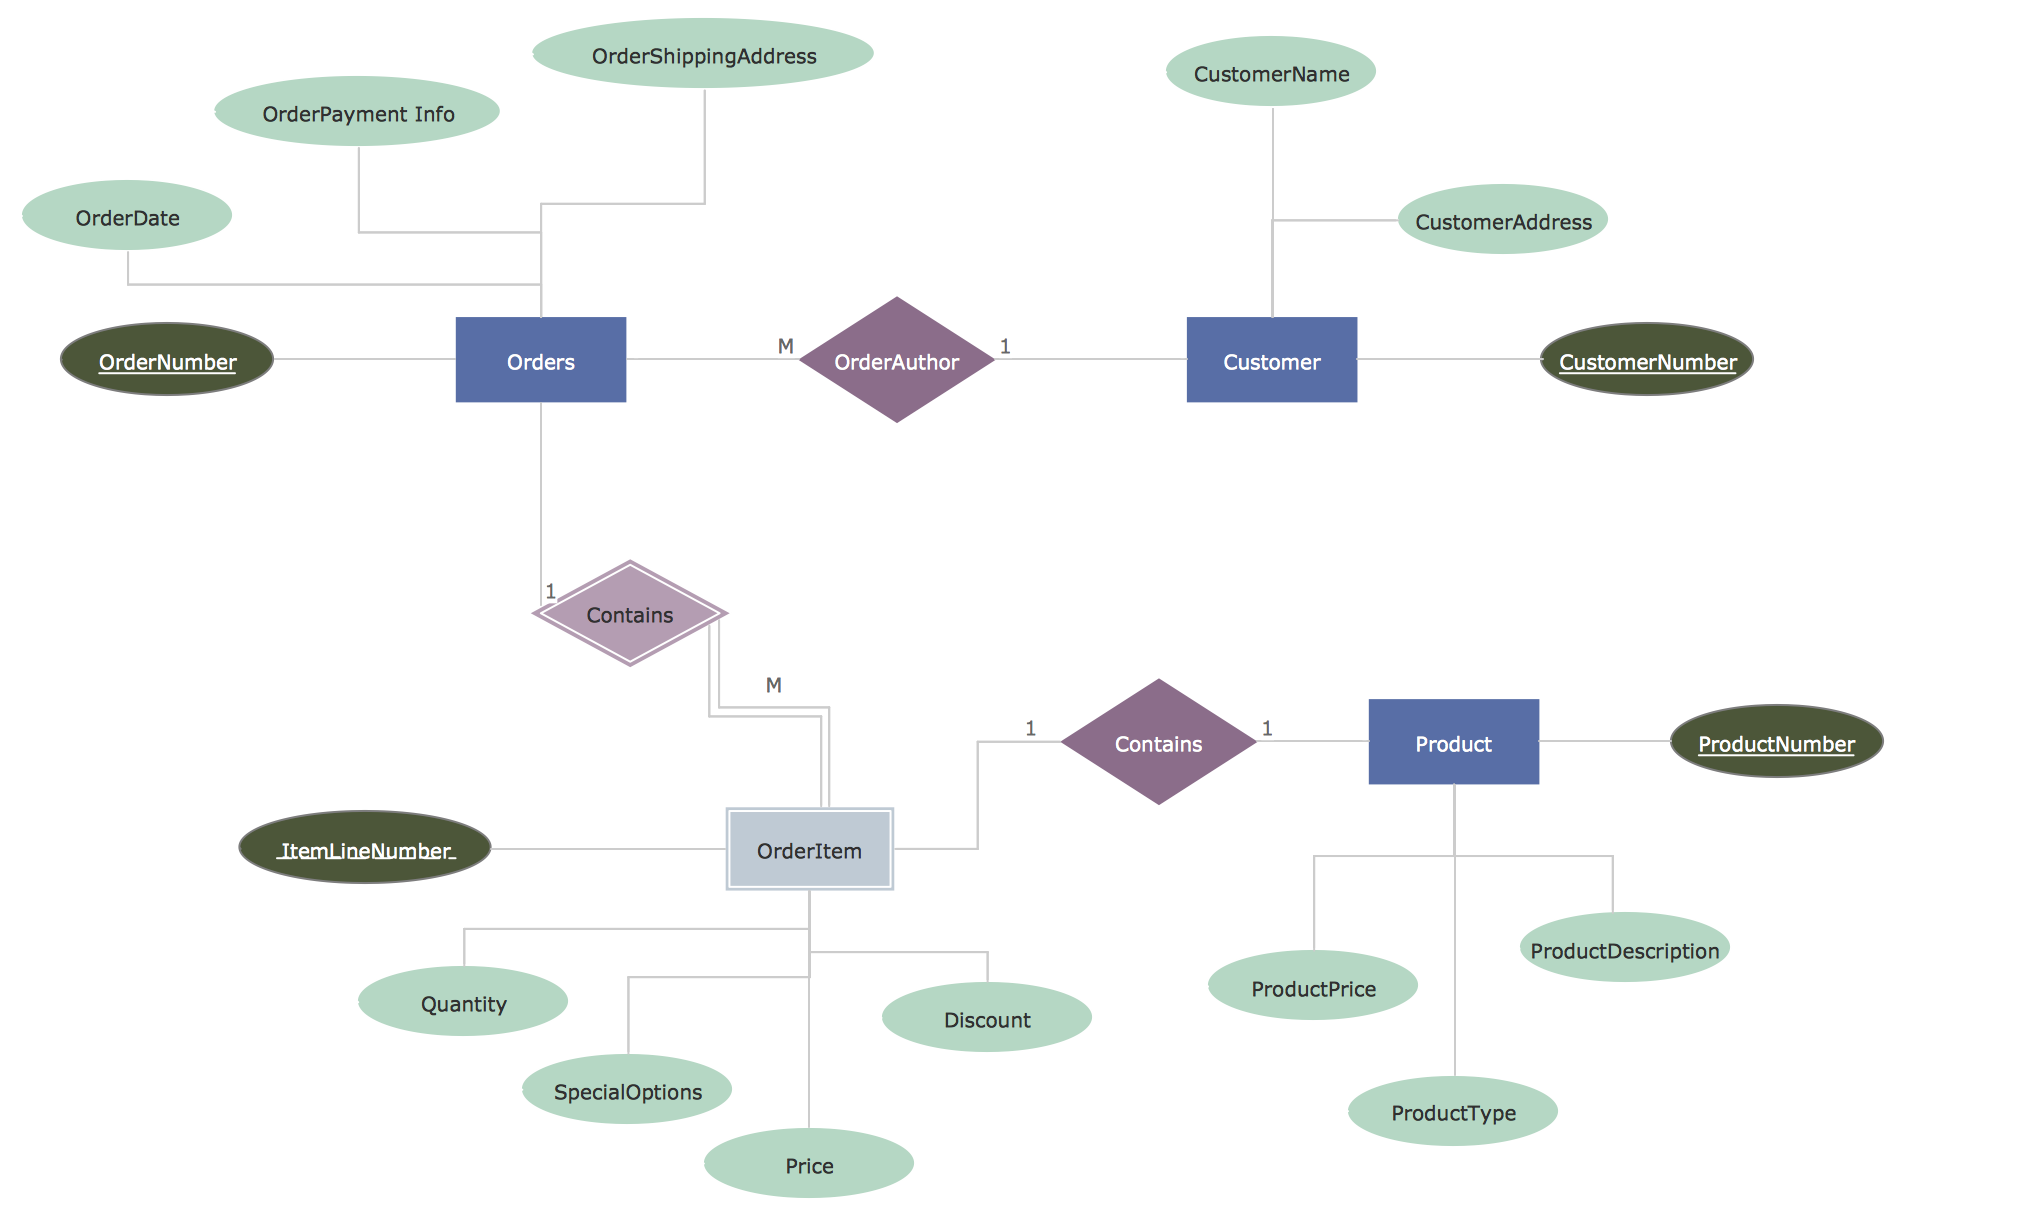
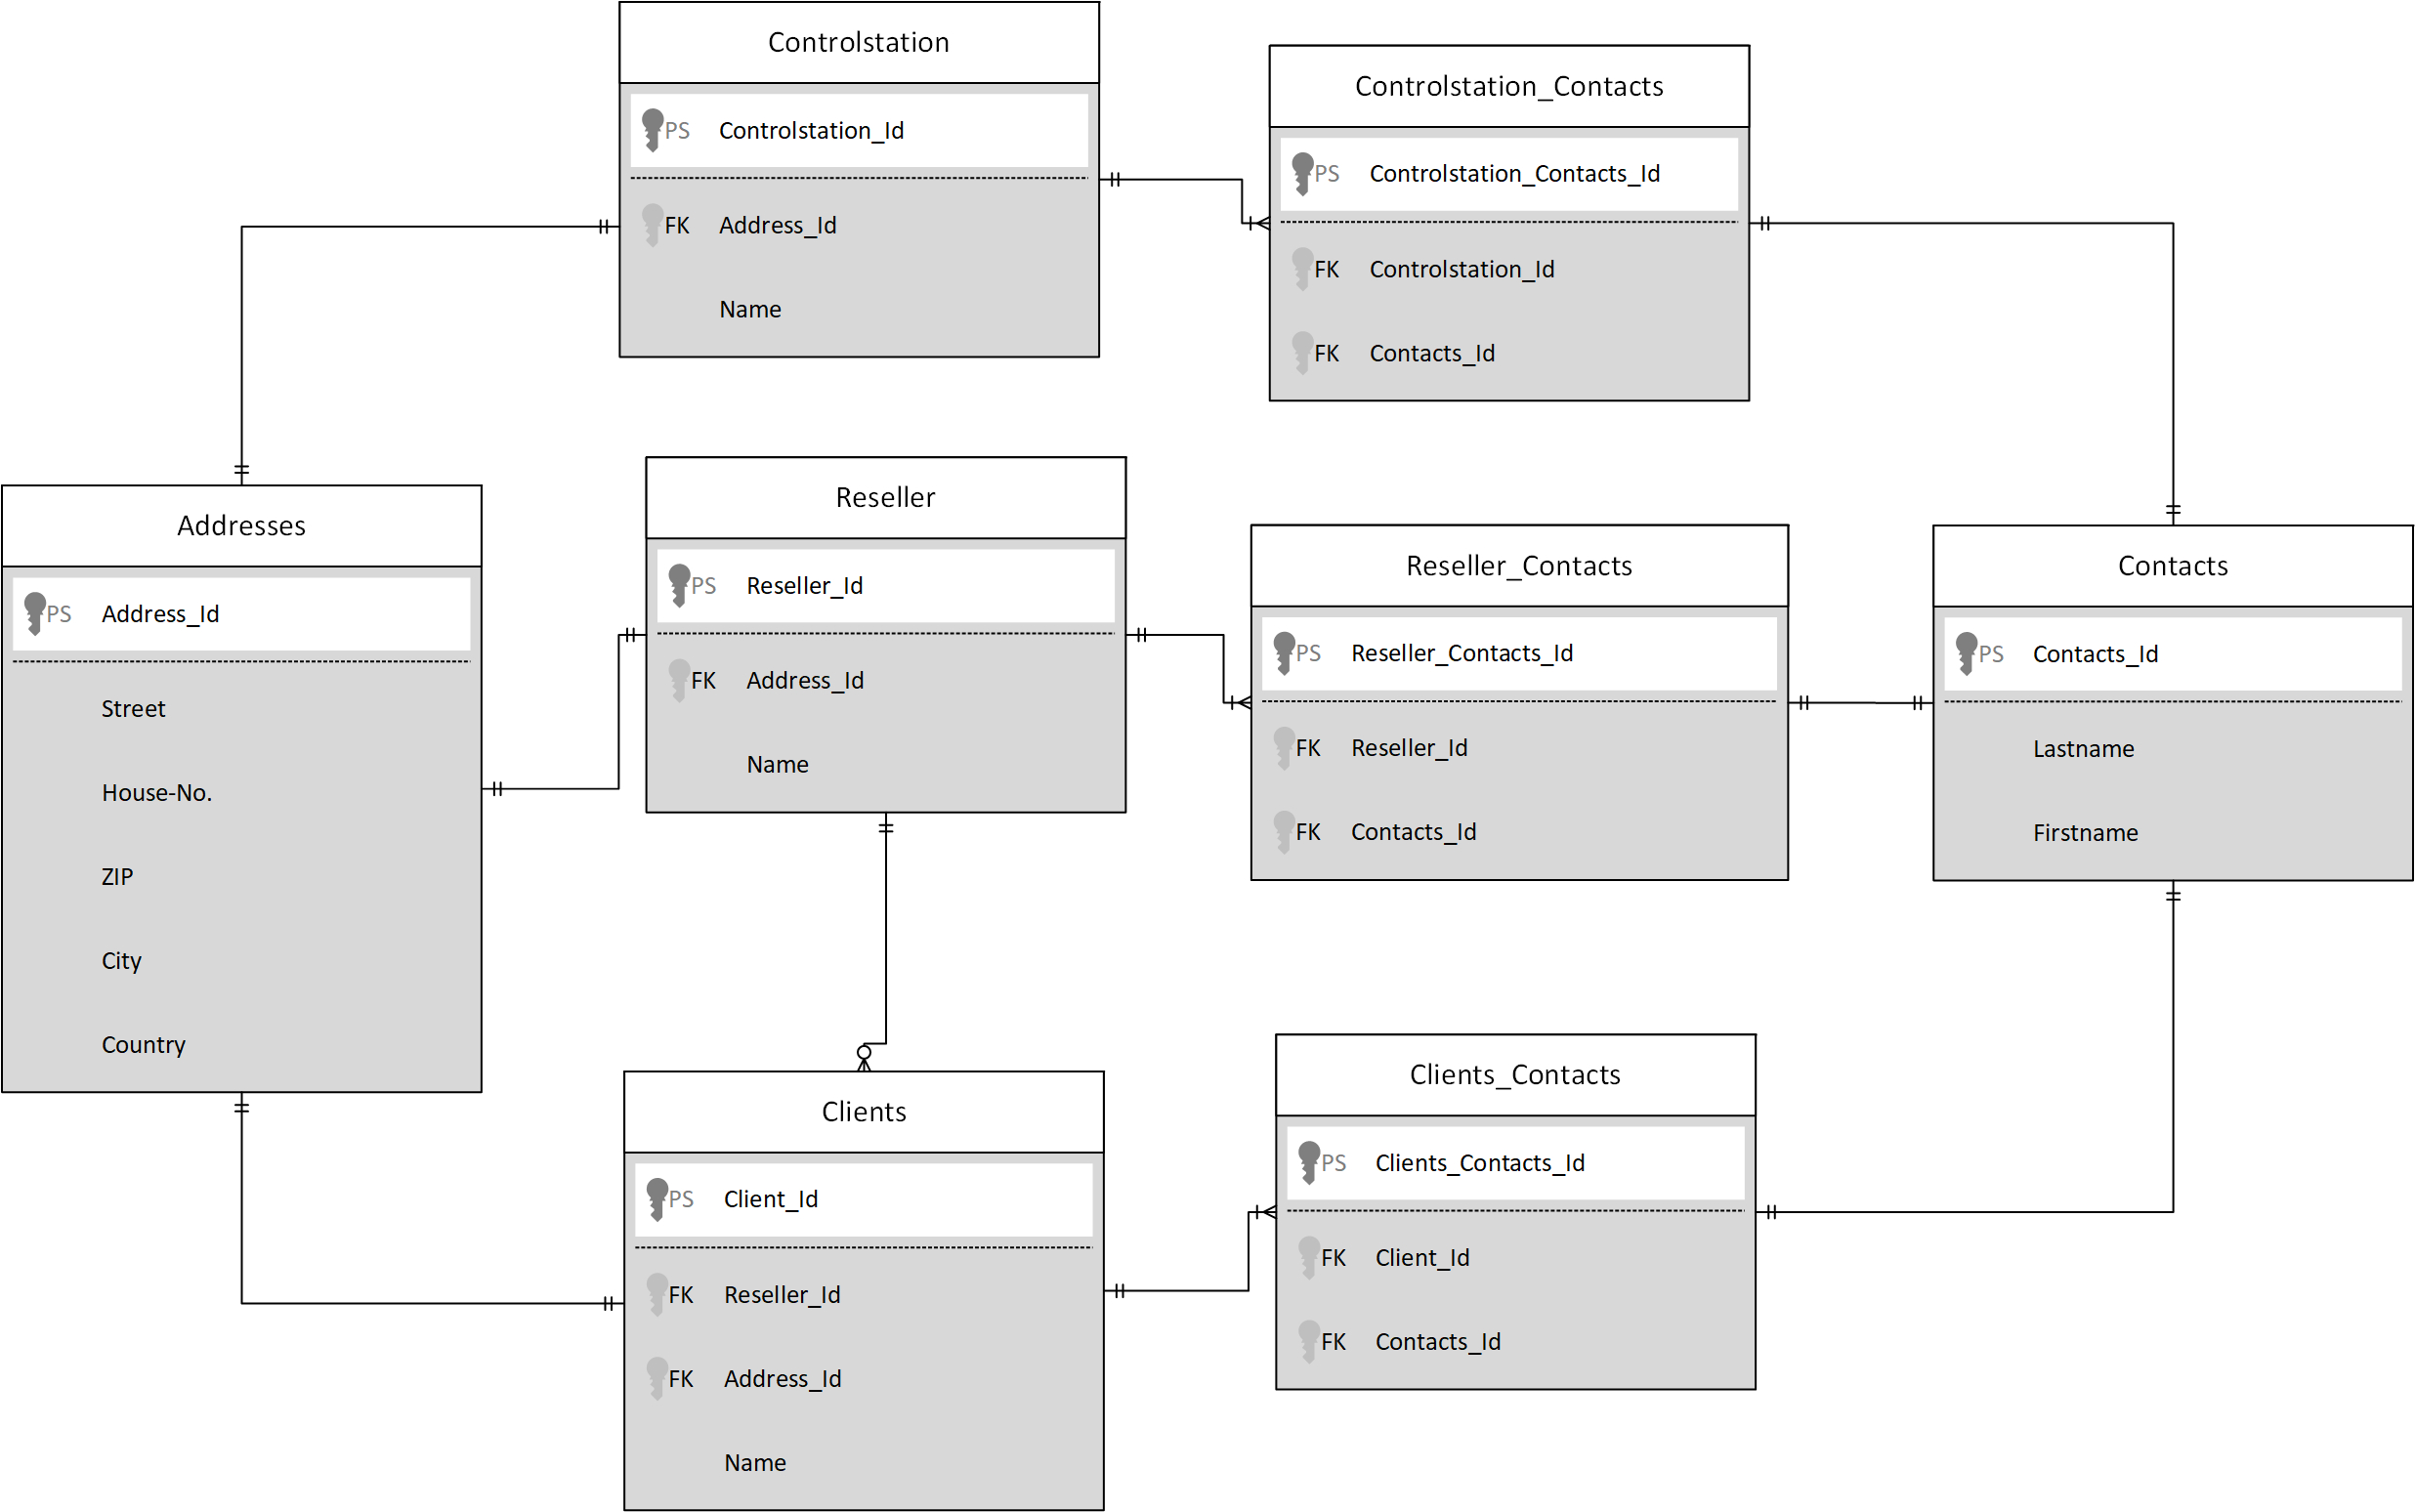
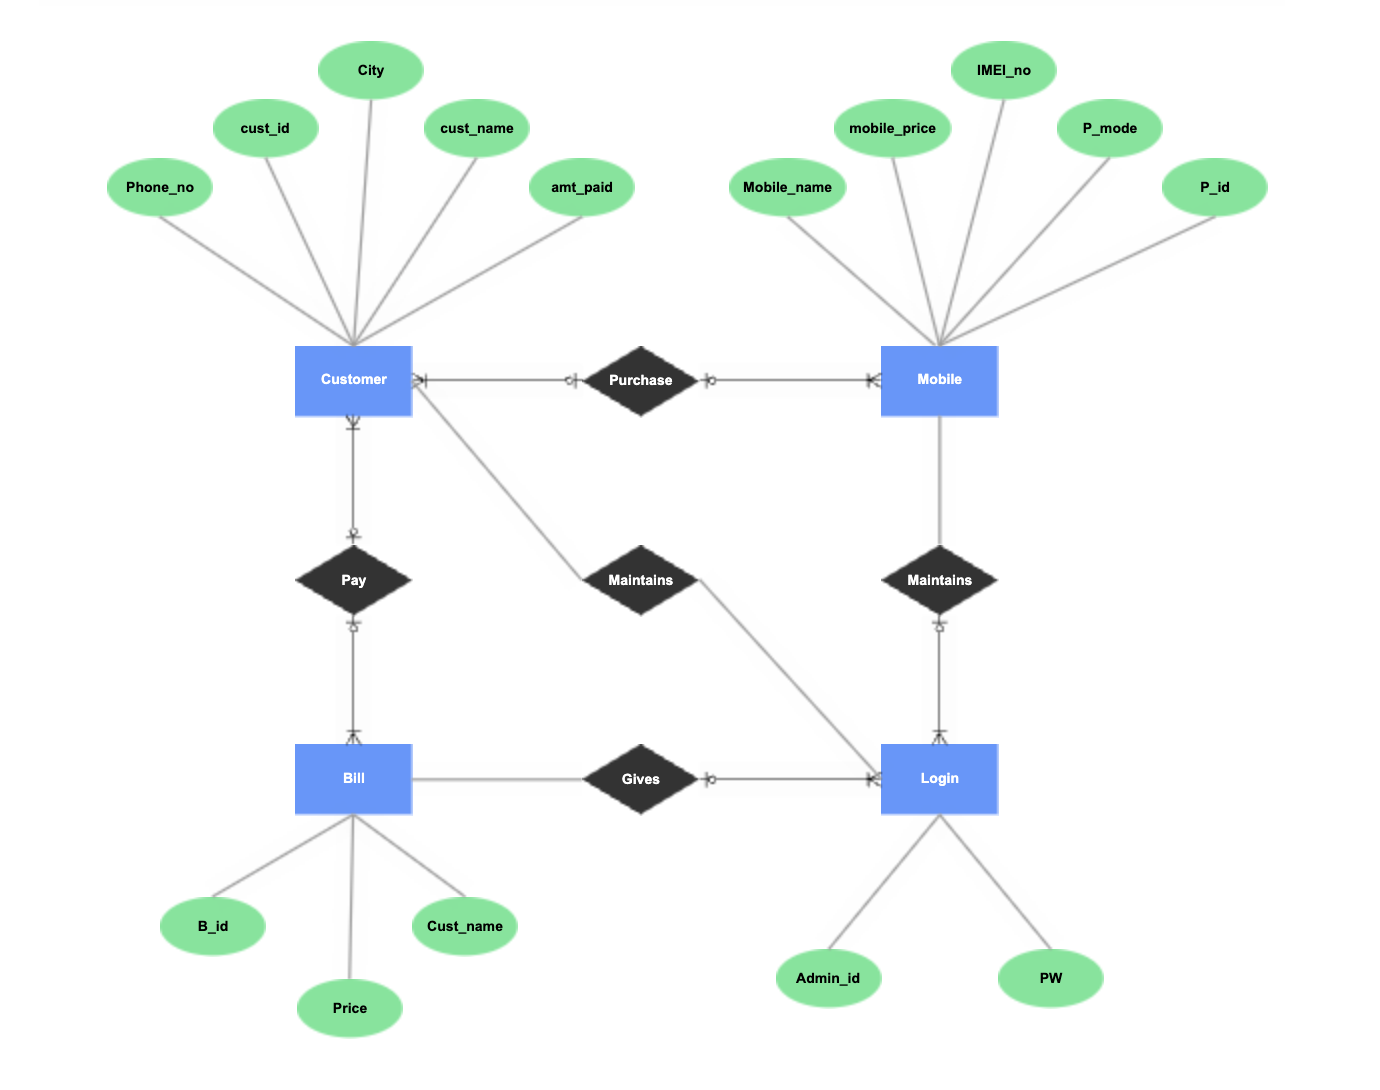
Once I have the raw dump organized, I move to relationships. This is where Database Design Using Entity Relationship Diagrams becomes something other than a drawing exercise. I look at each entity pair and ask whether the connection is mandatory or optional, one-to-one, one-to-many, or many-to-many. The many-to-many cases are the ones that expose design problems early. If you find yourself drawing a many-to-many relationship during this phase, you have two choices. You either create a junction table with its own surrogate key and composite foreign keys, or you reconsider whether the relationship should actually be modeled differently. In practice, I rarely encounter a legitimate many-to-many that does not collapse into something else once you examine the business rules closely.
The Specific Problem That Made Me Change How I Draw ERDs
About three years ago I was working on a logistics platform where the initial ERD showed a clean one-to-many relationship between customers and shipments. The diagram was technically correct. The problem appeared when the business added a requirement that a single shipment could be split across multiple trucks, and each truck could carry parts of multiple shipments during the same route. The clean one-to-many was gone overnight. What I should have done during the initial design phase was explicitly model the shipping schedule as a separate entity with its own relationship chain. Instead, I proceeded with the simpler diagram, built out half the application, and then spent two weeks refactoring the schema because the queries were becoming impossible to write efficiently. The lesson here is that ERDs drawn for the current state of requirements are almost always wrong within six months. You need to anticipate the relationship that the requirements document did not mention yet, or accept that you will be redrawing. Cardinality notation in ERDs is taught as a simple concept, but the practical implications are more complex than most guides suggest. When you mark a relationship as one-to-many between an orders table and an order_items table, that notation is doing several things at once. It tells the developer how to write the join, it tells the database engineer what index to create, and it tells the analyst which table is the parent in referential integrity. The mistake people make is treating cardinality as a descriptive label rather than a constraint you are actively encoding. If your ERD says a customer can have zero orders, but your application code always creates an order when a customer signs up, then your diagram is lying. That mismatch causes problems later when someone reads the ERD as documentation and writes code based on what they see rather than what actually exists in the schema. The more useful skill is learning when to break the standard conventions. I have seen teams enforce strict one-to-one relationships between entities when the data would actually be more efficient stored in a single table with a few sparse columns. An ERD that follows textbook rules perfectly can still represent poor design. The diagram is a communication tool, not a correctness guarantee. What matters is whether the underlying schema supports the access patterns the application actually needs. If your read queries consistently join three tables that the ERD shows as independent entities, you might be better off denormalizing those relationships into a single table regardless of what the diagram says.
Get the Full Details
Normalization Is Not the Same as a Good ERD
This is the point where most people get defensive, but it is worth stating plainly. A normalized database and a well-designed ERD are related but not identical concerns. You can have a perfectly normalized schema represented in a diagram that is still impossible to work with because the abstraction level is wrong. I recently reviewed an ERD for a healthcare data system where every table was in 5NF, every relationship had correct cardinality, and the diagram took up forty pages. The problem was that the model had no concept of temporal validity. Patient records changed over time, but the ERD treated each version as if it were the current state. The diagram was technically accurate for a frozen snapshot of data. It was useless for understanding how the system actually handled history. The workaround I used was to add a separate dimension table for temporal tracking rather than trying to encode time validity into the main entity-relationship structure. The ERD gained complexity but became something the development team could actually reason about. This is the kind of decision that does not appear in any tutorial. It comes from dealing with the gap between what a diagram shows and what the system has to do under real conditions.
When ERDs Fail Completely
There are scenarios where Entity Relationship Diagrams provide diminishing returns and sometimes actively mislead. Document databases and graph databases do not benefit from traditional ERD approaches. If you are designing a schema for MongoDB or Neo4j, spending time on relational ERD notation is usually wasted effort. The relationships in those systems are embedded or traversed rather than declared through foreign keys, so the ERD cannot capture the actual data structure you are building. In those cases, a property list or a traversal map serves better as documentation. ERDs also become unreliable when the data model is highly dynamic. Systems that allow users to define custom fields, flexible schemas, or runtime-modifiable relationships cannot be accurately represented in static diagram notation. The diagram will be outdated the moment someone changes a configuration. For these systems, a JSON schema definition or a migration-based approach communicates the actual state far more reliably than any visual diagram ever could.
Tools That Do Not Get in the Way
The tool choice matters less than most people think, but it does matter enough to avoid the ones that force you into rigid workflows. I use draw.io for quick diagrams because it does not require an account and the export format is stable. For project collaboration, Lucidchart handles the version tracking without being overly opinionated about notation. dbdiagram.io is worth considering if your end goal is generating DDL directly from the diagram, though you need to review the output SQL carefully because the tool sometimes makes assumptions about data types that do not match your requirements. The common thread across all these tools is that they are fast enough to use during the messy early stages and precise enough to serve as documentation once the model stabilizes. Avoid tools that add features you do not need, because those features become distractions during the phases where speed matters most. Once the ERD reaches a stable state, the translation to actual SQL should be automated wherever possible. Most diagramming tools export to SQL, but the exported DDL almost always requires review. Foreign key constraints may be missing, data types may be defaults rather than what you intended, and index declarations are frequently omitted. I spend roughly ten to fifteen minutes reviewing and correcting the generated SQL rather than writing it from scratch. This is still faster than manual DDL creation and far less error-prone than trusting the export completely. The review step is not optional. The first DDL I ever accepted without review had a foreign key on a nullable column, which made the referential integrity constraint meaningless and caused six months of data consistency issues that took an entire weekend to fix. The output DDL should include explicit constraints, named indexes where performance matters, and comments on columns that carry business meaning. A database with good naming conventions and inline documentation saves roughly an hour per week in developer time compared to a schema where every table name and column requires investigation to understand its purpose. ERD tools do not typically generate documentation, so that step falls to you after the diagram is complete.