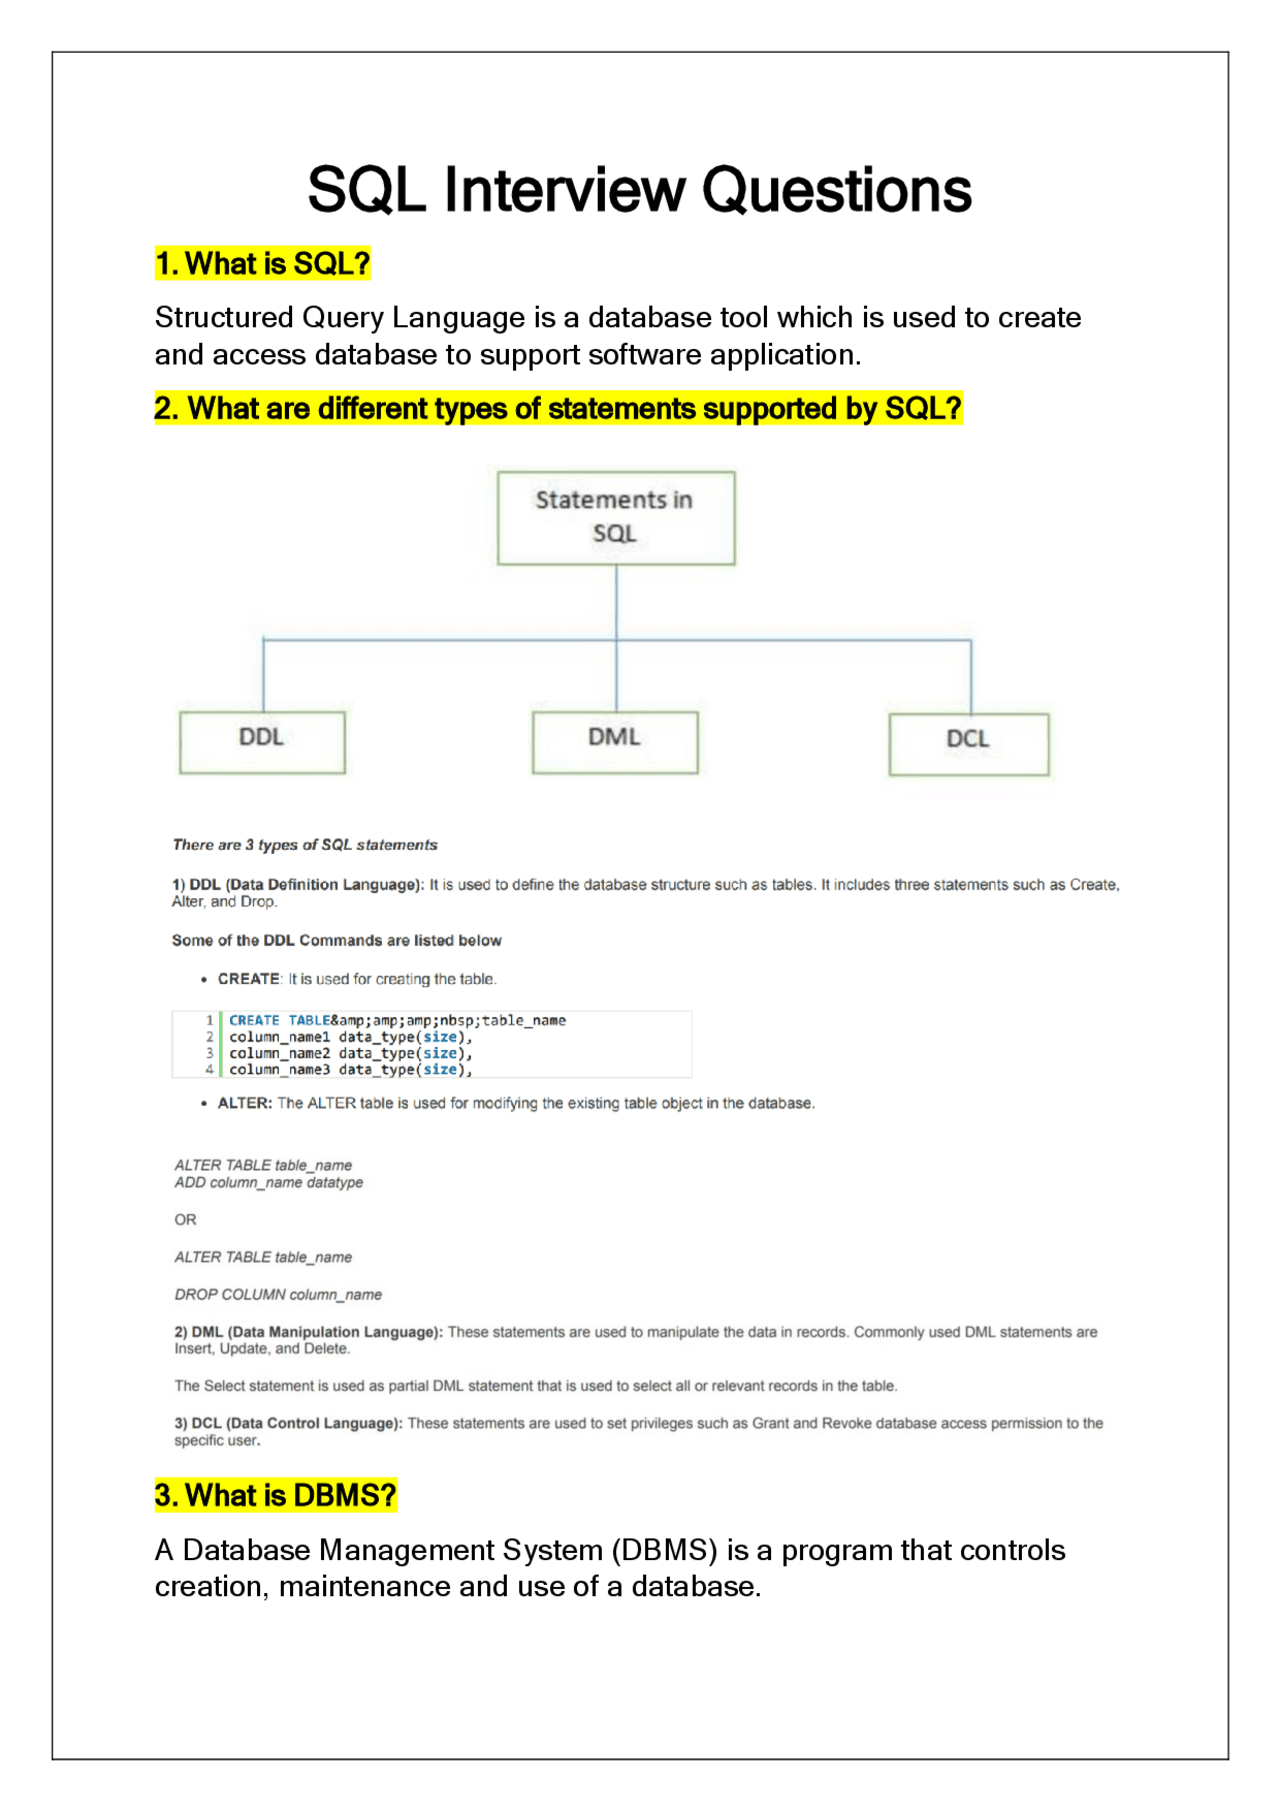
Database Management System Interview Questions
When I prepare people for interviews, the first thing I notice is that most candidates memorize definitions instead of understanding relationships. You can recite every type of index until you are blue in the face, but if they ask why your query still runs slow after adding it, you are stuck. I once watched a candidate confidently explain normalization but then fail to spot a classic update anomaly in a table that only had five columns. It was not hard. The question used a slightly unusual format, but the logic was textbook. That pattern keeps showing up in interviews, and the Database Management System Interview Questions section in most study guides does not warn you about this kind of swap. The common thread in real interviews is that the question sounds simple, but the follow-up exposes whether you have worked with data or only read about it. Expect three categories: relational theory, query performance, and practical schema decisions.
For relational theory, they will ask about keys, functional dependencies, and normalization. This is where you can get tripped up if you treat the material like trivia. A normal question might seem to point at third normal form, but the real issue is whether the interviewer wants you to discuss partial dependencies or transitive dependencies. In practice, picking the wrong normal form level can force you to write a long and unnecessary denormalization fix later, so pay attention to what the table is actually modeling.
Query performance questions that separate novices from practitioners
This is the part most people dread, and for good reason. When an interviewer asks how to optimize a slow query, the answer is almost never just add an index. If you answer with something like that on the first try, you will look shallow. The useful answer touches a few things in order: query plan, index selectivity, cardinality estimation, and then the actual statement structure. I usually start by asking what the statement looks like and what the execution plan shows. If the plan has a sequential scan on a large table, the next move is often covering index or a better join strategy. If the plan shows a nested loop with expensive row lookups, a different index shape might help, or the join might need to be rewritten entirely. One counterintuitive point that beginners miss is that more indexes can sometimes make queries slower. Write-heavy workloads suffer when every insert has to update multiple index structures. In my experience, adding a second or third index on the same table can turn a fast application into one that stalls under load. This is especially noticeable when you are working with OLTP systems that have many concurrent writers.
Get the Full Details

Normalization done right
Normalization is not just about reaching a certain form. It is about controlling redundancy and making sure updates are predictable. A common pitfall is normalizing too early without thinking about query patterns. I have seen teams break a clean design into too many tables because they feared anomaly, only to end up with queries that need six joins and still contain duplicate data due to lazy denormalization patches. Here is a practical rule I use: normalize the logical model first, then evaluate query performance, and only denormalize when the evidence shows a clear and measurable benefit. In my own work, I have reverted a denormalization patch after three months when monitoring showed the original normalized design was faster under real traffic. The patch looked good on paper because it saved a join, but the overhead of keeping redundant columns in sync was hidden from casual observation.
Index design insights that matter
Index design is not a one-size-fits-all job. Different databases handle index types differently, and the best choice depends on your workload. B-tree indexes are great for range queries and sorting, while hash indexes shine for exact lookups but cannot do range scans. Partial indexes can save space and improve performance when you only need to query a subset of rows frequently. A specific edge case I encountered involved a composite index where the column order mattered more than the number of columns. A two-column index on state and created_at performed better than a three-column index on state, created_at, and status for a particular query pattern. The reason was that the query planner could use the leading columns for filtering and the third column only added maintenance overhead without real benefit for that workload.
Schema design questions you should be ready for
Interviewers often give you a scenario and ask how you would model it. The trick is to think about constraints, not just tables. They want to see that you consider data integrity, concurrency, and future growth. When I answer these, I start with entities and relationships, then I add constraints, and finally I discuss indexing and performance trade-offs. One thing I always mention is the difference between logical and physical design. A logical model might look perfect, but the physical implementation needs to account for storage engine behavior, partitioning strategies, and backup considerations. Ignoring these leads to systems that work fine in development but collapse under production load.

Transaction and concurrency basics
You will likely be asked about ACID properties, isolation levels, and locking. The standard answer covers Read Committed, Repeatable Read, and Serializable, but the practical question is usually which level a real system uses and why. Most production databases default to Read Committed or Repeatable Read because Serializable is too restrictive for high-throughput workloads. Deadlocks are another common topic. I usually explain that deadlocks happen when two transactions wait for each other's locks, and the solution involves either reducing lock scope, using shorter transactions, or implementing retry logic. In one project, I reduced deadlock frequency by 80% simply by reordering operations to acquire locks in a consistent sequence across all code paths.
Security questions that reveal depth
Interviewers often test whether candidates understand that security is not just about passwords. SQL injection remains a real threat, and prepared statements are the standard defense, but there are nuances. Parameterized queries prevent injection in most cases, but dynamic SQL, stored procedures with string concatenation, and misconfigured error messages can still leak information. I also expect questions about encryption at rest and in transit. Many candidates forget to mention that securing data only matters if you also protect backups and logs. In my experience, the weakest link is often the backup restoration process, not the live database itself.
Practical tips for answering interview questions
When you are unsure, do not guess loudly. It is better to walk through your reasoning out loud than to state a wrong answer with confidence. Interviewers value clarity of thought more than memorized facts. If a question seems ambiguous, ask for clarification. I have found that many candidates lose points not because they do not know the answer, but because they assume the question means something it does not. A quick clarification can save you from going down the wrong path entirely. Practice explaining concepts to someone who knows less than you. If you can describe a join strategy or a normalization rule in plain language without jargon, you truly understand it. This skill transfers directly to interviews and to real-world team communication.

Tools and resources worth knowing
Being familiar with tools like EXPLAIN plans, profiling utilities, and monitoring dashboards will serve you well. Interviewers appreciate candidates who can diagnose problems systematically rather than guessing. Even if you do not have access to production tools, understanding the concepts behind query optimization and performance analysis is valuable. For practice, try to analyze real query logs or use test databases with sample schemas. The more you work with actual data, the more intuitive these concepts become. Reading about indexes is different from watching an execution plan change when you modify an index.
Common mistakes to avoid
Do not overcomplicate simple answers. If an interviewer asks about the difference between DELETE and TRUNCATE, a clear and concise answer beats a long essay every time. Also, avoid saying things like "I would just add more indexes" without explaining the trade-offs. Another mistake is pretending to know something you do not. If you are asked about a database feature you have never used, admit it and relate it to something similar you do understand. Interviewers respect honesty more than fabricated expertise.
Final thoughts on preparation
Database Management System Interview Questions cover a wide range of topics, from theory to practice. The best preparation combines theoretical knowledge with hands-on experience. Build small projects, break them, fix them, and then explain what went wrong. That cycle builds the kind of understanding that shows up naturally in interviews. Remember that interviews are conversations, not interrogations. If you get stuck, take a breath, think out loud, and work through the problem with the interviewer. Most of the time, they are more interested in how you approach challenges than in whether you get the perfect answer on the first try.


