Picking the Right Dataset For Data Cleaning Practice
Most people grab whatever Kaggle dataset shows up at the top of the search results and immediately hit apply a few pandas functions without thinking about whether the data actually needs cleaning in the first place. That approach works fine for learning syntax, but it won't prepare you for real work. I spent three years doing this stuff professionally before I stopped treating data cleaning as a chore and started treating it as a diagnostic exercise.The mistake beginners make is assuming that messy data is interesting data. Actually, the most valuable practice datasets are the boring ones that have subtle issues hiding under the surface. You want records where dates are sometimes strings, sometimes timestamps, sometimes formatted as MM/DD/YYYY and sometimes DD/MM/YYYY depending on who entered them. You want missing values that aren't just nulls but are represented as blank strings, "N/A", "na", "-" and occasionally just zeros that aren't zeros at all.
Where to Find a Dataset For Data Cleaning Practice
Let me start with the practical options. Kaggle has a dedicated "Getting Started" section with datasets specifically designed for practice. The Titanic dataset is overused but it does have some interesting quirks with the Age and Cabin columns. The House Prices dataset from Ames, Iowa has genuinely messy input data with mixed types in numeric columns. Both are freely downloadable. There's also the OpenML platform, which hosts hundreds of datasets with metadata about their quality. The UCI Machine Learning Repository is older and the documentation is sometimes worse, but the raw data is often less sanitized than what you find on Kaggle. If you want data that looks like it came from an actual company database, look for the Google Analytics Sample Data or the NYC Taxi Trip Duration dataset on BigQuery public datasets. Those have real-world scale and real-world problems.Here is something that surprised me when I first started working with cleaning datasets for production pipelines: the best practice data isn't the kind where everything is broken. It's the kind where roughly 5-10 percent of the issues are obvious and the remaining 90 percent are subtle enough that you'd only catch them if you knew what to look for. A dataset where columns have inconsistent casing or trailing whitespace is fine for your first weekend project. A dataset where the relationship between two columns breaks in exactly three out of forty thousand rows is what you need for actual skill development.
What Actually Makes Data Dirty
I see too many tutorials that focus on removing duplicates and filling null values. That's table stakes. Real data cleaning involves reconciling schemas, handling measurement inconsistencies, dealing with encoding problems, and figuring out when "missing" doesn't mean "unknown" but rather "not applicable." These distinctions matter because they determine how you impute values, and imputing wrong can quietly destroy your model performance.One thing nobody tells you about cleaning datasets is that the cleaning process itself changes the statistical properties of your data. When you drop rows with missing values, you're not just reducing sample size. You're often introducing selection bias that makes your cleaned data unrepresentative of the population you actually care about. I learned this the hard way working on a customer churn prediction project where the missing values in the contract type column weren't random. They were systematically missing for enterprise accounts because those contracts were stored in a different system that didn't export to our analytics pipeline. Dropping those rows made the model perform well in validation but fail completely in production.
Get the Full Details

The Toolkit I Actually Use
Python with pandas and numpy covers about eighty percent of cases. I use pandas for structural operations, numpy for numerical array work, and sometimes DuckDB when I'm dealing with datasets larger than my available RAM. DuckDB lets me run SQL queries directly on CSV and Parquet files without loading everything into memory. The query performance is notably better than pandas for filtering and aggregation, and the syntax is familiar if you know SQL. For exploratory analysis, I rely on ydata-profiling to generate automated data quality reports. It catches a lot of issues you'd otherwise miss, though it tends to produce noisy output on large datasets. The profiling reports are useful as a starting point, not as a replacement for manual inspection. I also use great_tables for creating publication-quality summary tables, and pandasgui when I need to visually inspect data rather than write code to do it.R is still relevant if your organization uses it, but the tooling ecosystem around pandas has widened significantly. Things like polars provide faster data manipulation with a similar API to pandas, and integrates well with the scientific Python stack. For most practice purposes, stick with pandas until you hit a performance wall.
A Specific Problem I Encountered
I was working on a project cleaning transaction data from an e-commerce platform, and I ran into an issue with currency codes. About twelve percent of the rows had a currency_code column that was blank. The obvious assumption was that these were missing values, so I filled them with the most frequent currency in the dataset, which was USD. That turned out to be wrong for a specific reason I hadn't considered.The blank currency codes correlated with orders from a particular vendor who billed in a bundled currency that the platform didn't normalize. The pattern was consistent enough that I could identify it by cross-referencing vendor_id with the date range. The fix wasn't imputation. It was joining in external vendor pricing data to reconstruct the correct currency for those rows. This kind of problem requires you to understand the data generation process, not just the column-level statistics. A purely statistical approach would have quietly corrupted the dataset.
Common Pitfalls
The biggest pitfall is treating every missing value the same way. There's a difference between data that is missing completely at random, missing at random, and missing not at random. Each type requires a different imputation strategy. MCAR data can be handled with simple mean or median imputation without serious bias. MAR data needs conditional imputation based on other observed variables. MNAR data requires specialized techniques like pattern mixture models, and sometimes the only honest answer is to acknowledge that you cannot reliably fill those values. Another common error is premature type conversion. Converting a column to numeric before checking for non-numeric characters will silently produce NaN values for the problematic entries. You end up with less data than you started with and no warning that anything went wrong. Always use the errors='coerce' parameter deliberately and check what got converted before proceeding.Encoding issues are also more common than people expect. UTF-8 is standard, but legacy systems frequently mix encodings within a single file. The solution is usually to detect the encoding using chardet or to read files with latin-1 as a fallback and then normalize. This problem tends to surface more often with international data sources.
How to Structure Your Practice
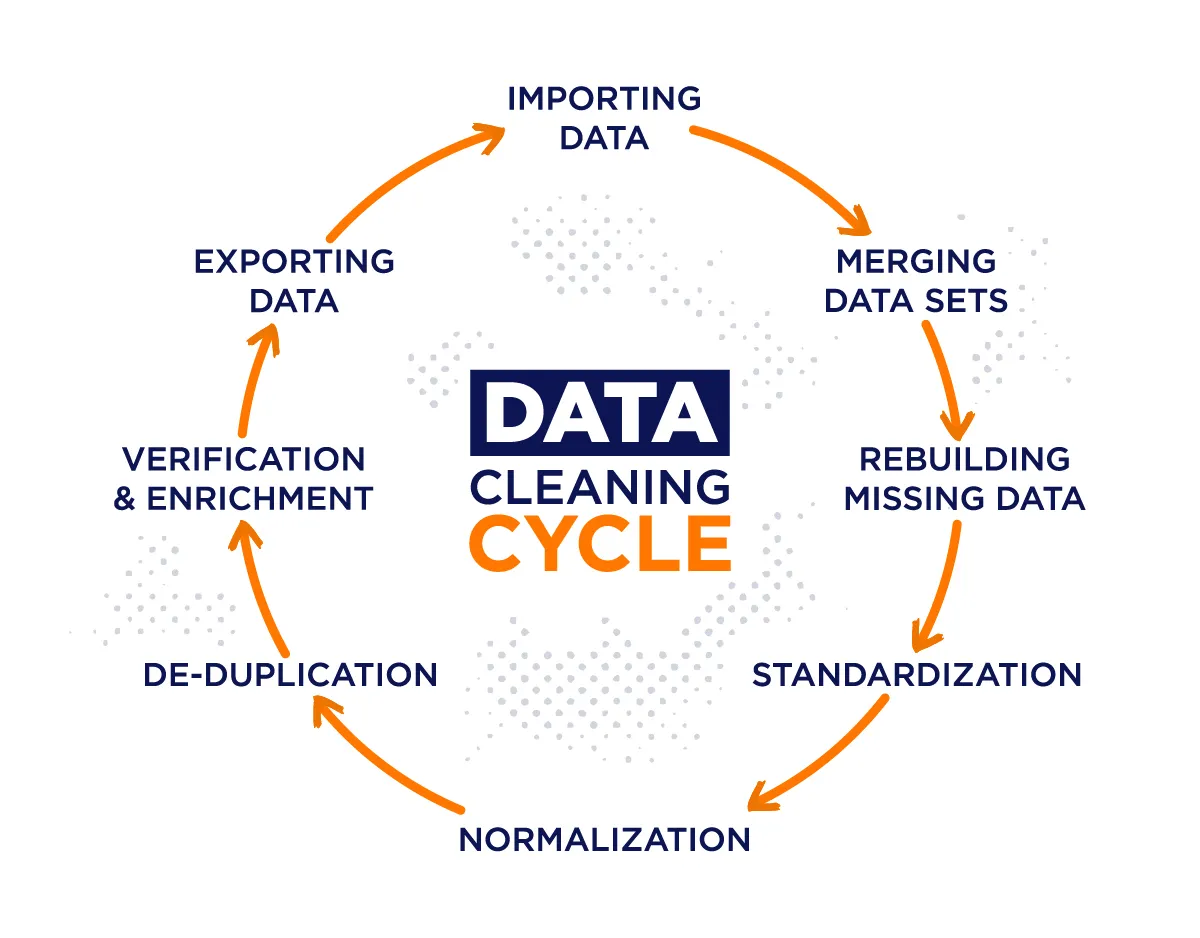
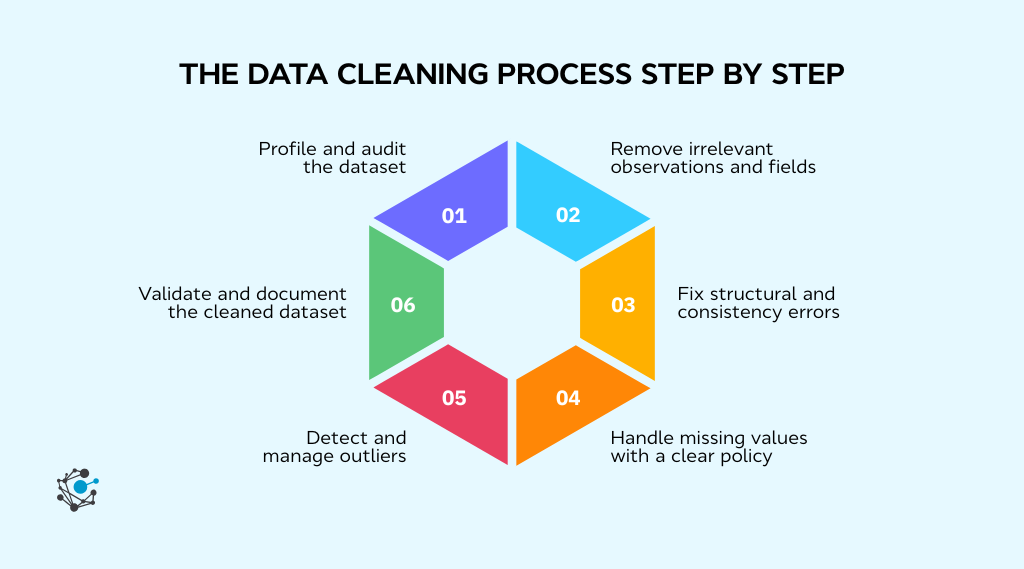
Start with a dataset that has clear structure but hidden problems. Spend time understanding what each column represents before you write any cleaning code. Document your assumptions about the data generation process. Run a profiling report and compare its findings against what you observe manually. Clean the data in stages, saving intermediate versions so you can trace back where errors were introduced.I recommend working through the same dataset multiple times with different goals. First pass is exploratory. Second pass is structural cleaning. Third pass is semantic cleaning where you verify that the relationships between variables still make sense after your transformations. Each pass reveals different issues. This iterative approach is closer to how the work actually happens in production environments.
Limitations to Keep in Mind
Practice datasets will never fully replicate the messiness of production data because they're curated for learning purposes. The problems are contained and solvable. Real data cleaning involves political decisions about what counts as clean enough, stakeholder disagreements on how to handle edge cases, and time pressure that forces you to make tradeoffs you wouldn't make in a controlled environment.No single tool covers all scenarios. Pandas struggles with datasets larger than available memory. SQL-based approaches don't handle unstructured text well. Specialized libraries like dirtycat exist for record linkage but add complexity that isn't always justified. The practical approach is to match the tool to the problem and accept that you'll need to switch between them during a single project.