Setting Up Regression Analysis in Excel
Most people try to run regression directly from the Data Analysis toolpack and immediately hit a wall. The real issue is not the tool, it is how the data is laid out before you even open the dialog box. I have spent years cleaning data for clients who would rather do anything else than fix their source files. What follows is a practical walkthrough based on what actually works in production environments. The first thing you need to understand is that Excel expects your independent variables in adjacent columns and your dependent variable in another single column. It does not handle missing values gracefully, it does not handle text where numbers should be, and it will produce silently corrupted results if your ranges are misaligned. The tool itself is fine for basic OLS regression. The problem is always the input.
Datasets For Regression Analysis Excel
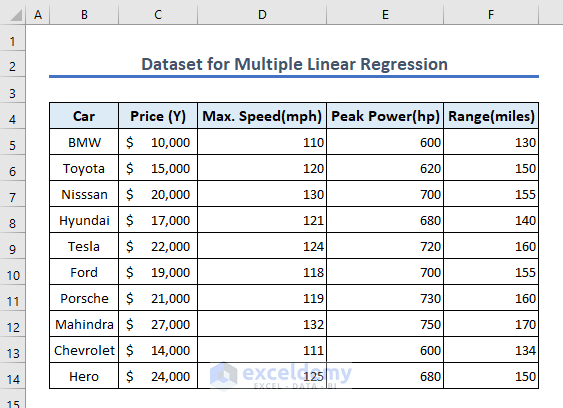
Good datasets for this kind of work share a few traits. They are flat, meaning each row is one observation and each column is one variable. There are no merged cells anywhere in the range. Column headers are in the first row and contain no spaces or special characters that could confuse the analysis. Numeric columns use actual numbers stored as numbers, not numbers stored as text. Date columns, if present, are proper Excel dates, not text strings. When you download or prepare a dataset, check three things before running anything. Confirm there are no blank cells within the intended range. Run the COUNTA function on each column and compare it to the total number of rows to catch hidden empties. Look at the rightmost column of your data and make sure Excel has not treated part of your dataset as a different table because it encountered a blank row or column. I ran into a specific case last year where a client sent me a regression dataset that appeared perfectly clean. The analysis ran without errors and produced an R squared value that looked reasonable. The dependent variable was supposed to be monthly revenue in dollars. It turned out the revenue column was formatted as text with thousands separators embedded in the cells, like $1,234,567. Excel's Data Analysis tool silently skipped the text cells during the regression, so the model was built on roughly sixty percent of the available data. The coefficients were wrong, the standard errors were wrong, and nobody noticed until the predictions were used in a budget meeting. I wrote a quick conversion script using the VALUE function and re-ran the analysis. The new R squared dropped from 0.87 to 0.62 and the coefficient on the main predictor reversed direction. It took about forty-five minutes to fix the entire dataset after the initial discovery.
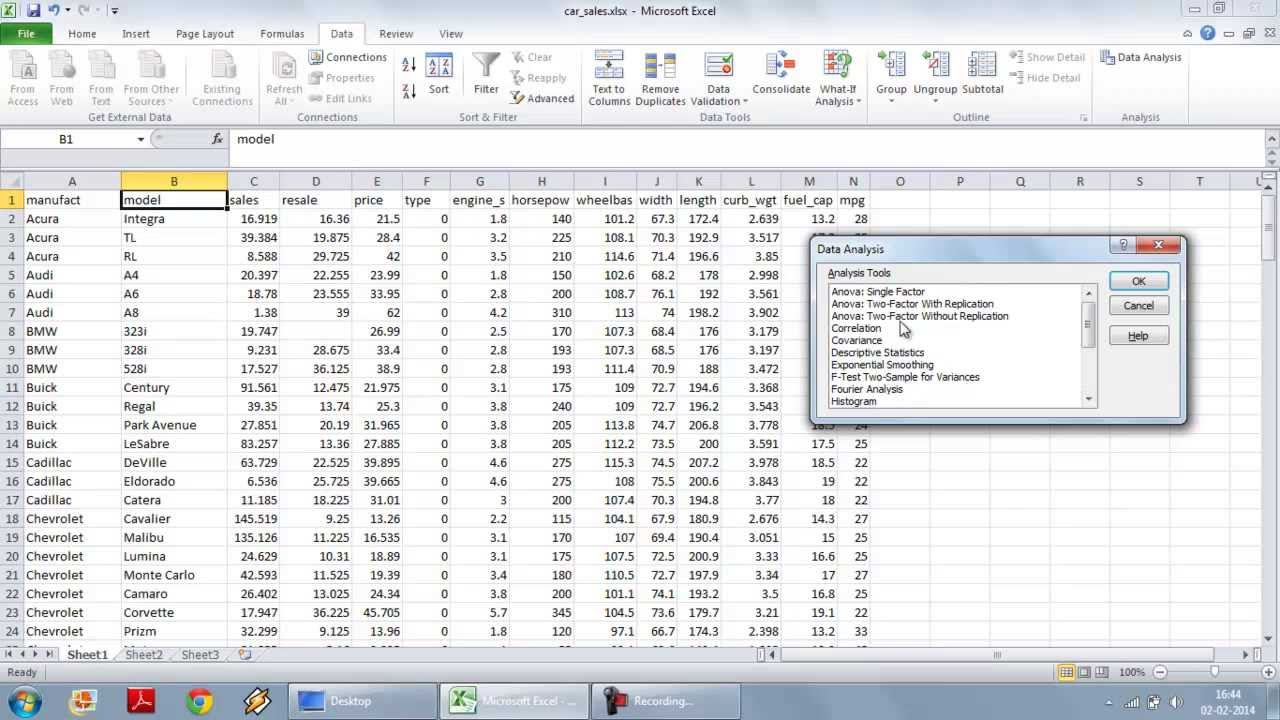
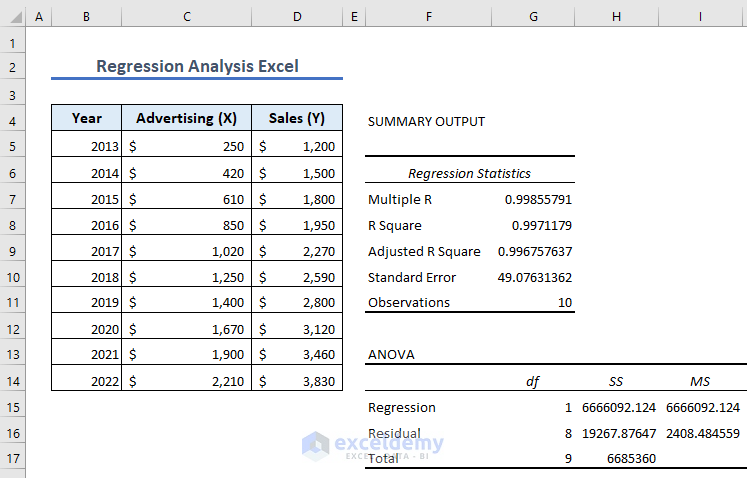
Here is the practical process for running the regression once your data is clean. Go to the Data tab and click Data Analysis. If you do not see that button, you need to enable the Analysis ToolPak from File, Options, Add-ins, go to Manage Excel Add-ins at the bottom, check Analysis ToolPak, and press Enter. That loads the tool into the ribbon. From there select Regression and click OK. In the input section, point the Input Y Range at your dependent variable column including the header. Point the Input X Range at all your independent variable columns including their headers. Check the Labels box if your ranges include headers. Set your desired confidence level, usually 0.05 for standard work. Pick an output range or choose a new worksheet. Press OK. Excel will generate a summary output sheet with the regression statistics, coefficients, standard errors, t statistics, and p values. Reading the output correctly matters more than running the analysis itself. The R Square value tells you the proportion of variance explained by your model. Adjusted R Square adjusts that number for the number of predictors you included, and it is the figure you should rely on when comparing models with different numbers of variables. The standard error in the summary represents the average distance that observed values fall from the regression line. Coefficients are listed under the Coefficients column. The lower limit and upper limit columns at 95% give you the confidence interval for each coefficient. P-value tells you whether each predictor is statistically significant at your chosen alpha level. The t Stat is the coefficient divided by its standard error.
Get the Full Details
A common mistake beginners make is interpreting a low p value as evidence of a large or important effect. A variable can be highly statistically significant with a coefficient that is practically meaningless for your business decision. I had a dataset with over ten thousand rows where several predictors had p values below 0.001 but each one changed the outcome by less than one percent. The model was precise but not useful for forecasting at an individual level. Always look at the magnitude of the coefficient and the practical context, not just the significance stars. Multicollinearity is another issue that Excel does not flag for you. If your independent variables are highly correlated, the regression coefficients become unstable and their standard errors inflate. Excel will still produce a result, but the interpretation becomes unreliable. The variance inflation factor is the standard diagnostic for this. You can calculate it manually for each predictor by regressing that variable against all the other independent variables and computing one divided by one minus the R squared from that auxiliary regression. A VIF above five is worth investigating. A VIF above ten is a clear problem. I typically run these diagnostics in a separate step before trusting any regression output for decision making. Heteroscedasticity is another silent problem. This happens when the variance of the residuals changes across the range of predicted values. Excel does not test for it automatically. You can check by creating a scatter plot of the residuals against the fitted values from the regression output. If the plot shows a funnel shape or a clear pattern, the homoscedasticity assumption is violated. In that case, robust standard errors are the usual remedy, though implementing them in Excel requires additional manual calculation steps.
The Regression tool in Excel has a few hard limitations you should know about. It cannot handle regularization methods like ridge or lasso regression. If you have more predictors than observations, it will fail. It does not support categorical variables with more than two levels unless you manually create dummy variables first. It does not perform residual diagnostics for you beyond the optional plots checkbox. When you need any of those capabilities, you should move to R, Python, or a dedicated statistical package. For most standard business and academic work, Excel is adequate if the data is properly prepared and you understand what the output means. The biggest time savings comes from investing in data cleaning before the analysis step. A well structured dataset with clean numeric columns, no missing values, and properly labeled headers reduces the entire workflow from hours of troubleshooting to roughly fifteen minutes of setup and execution. The tool itself is not the bottleneck. Garbage in, garbage out applies here more than almost anywhere else in quantitative work.
Where to Find Datasets
Several free sources host datasets that work well for practicing regression analysis in Excel. The UCI Machine Learning Repository maintains over a hundred datasets with documented column meanings. The Kaggle Datasets section is larger but requires more filtering since quality varies significantly across uploads. Many government portals, including data.gov in the United States and the European Open Data Portal, publish time series and cross-sectional data suitable for regression work. University course pages often post cleaned datasets along with their problem sets. When sourcing data, prefer datasets that include documentation or a codebook describing each variable. Without that, you will spend more time guessing what the columns represent than actually running analyses. Also verify the licensing terms if you plan to publish or share your results. Some datasets carry restrictions that apply to derivative works. The combination of a clean dataset, the Excel Data Analysis ToolPak, and a basic understanding of what the output means covers the majority of regression tasks in spreadsheet software. Anything beyond that typically requires a different toolchain entirely.