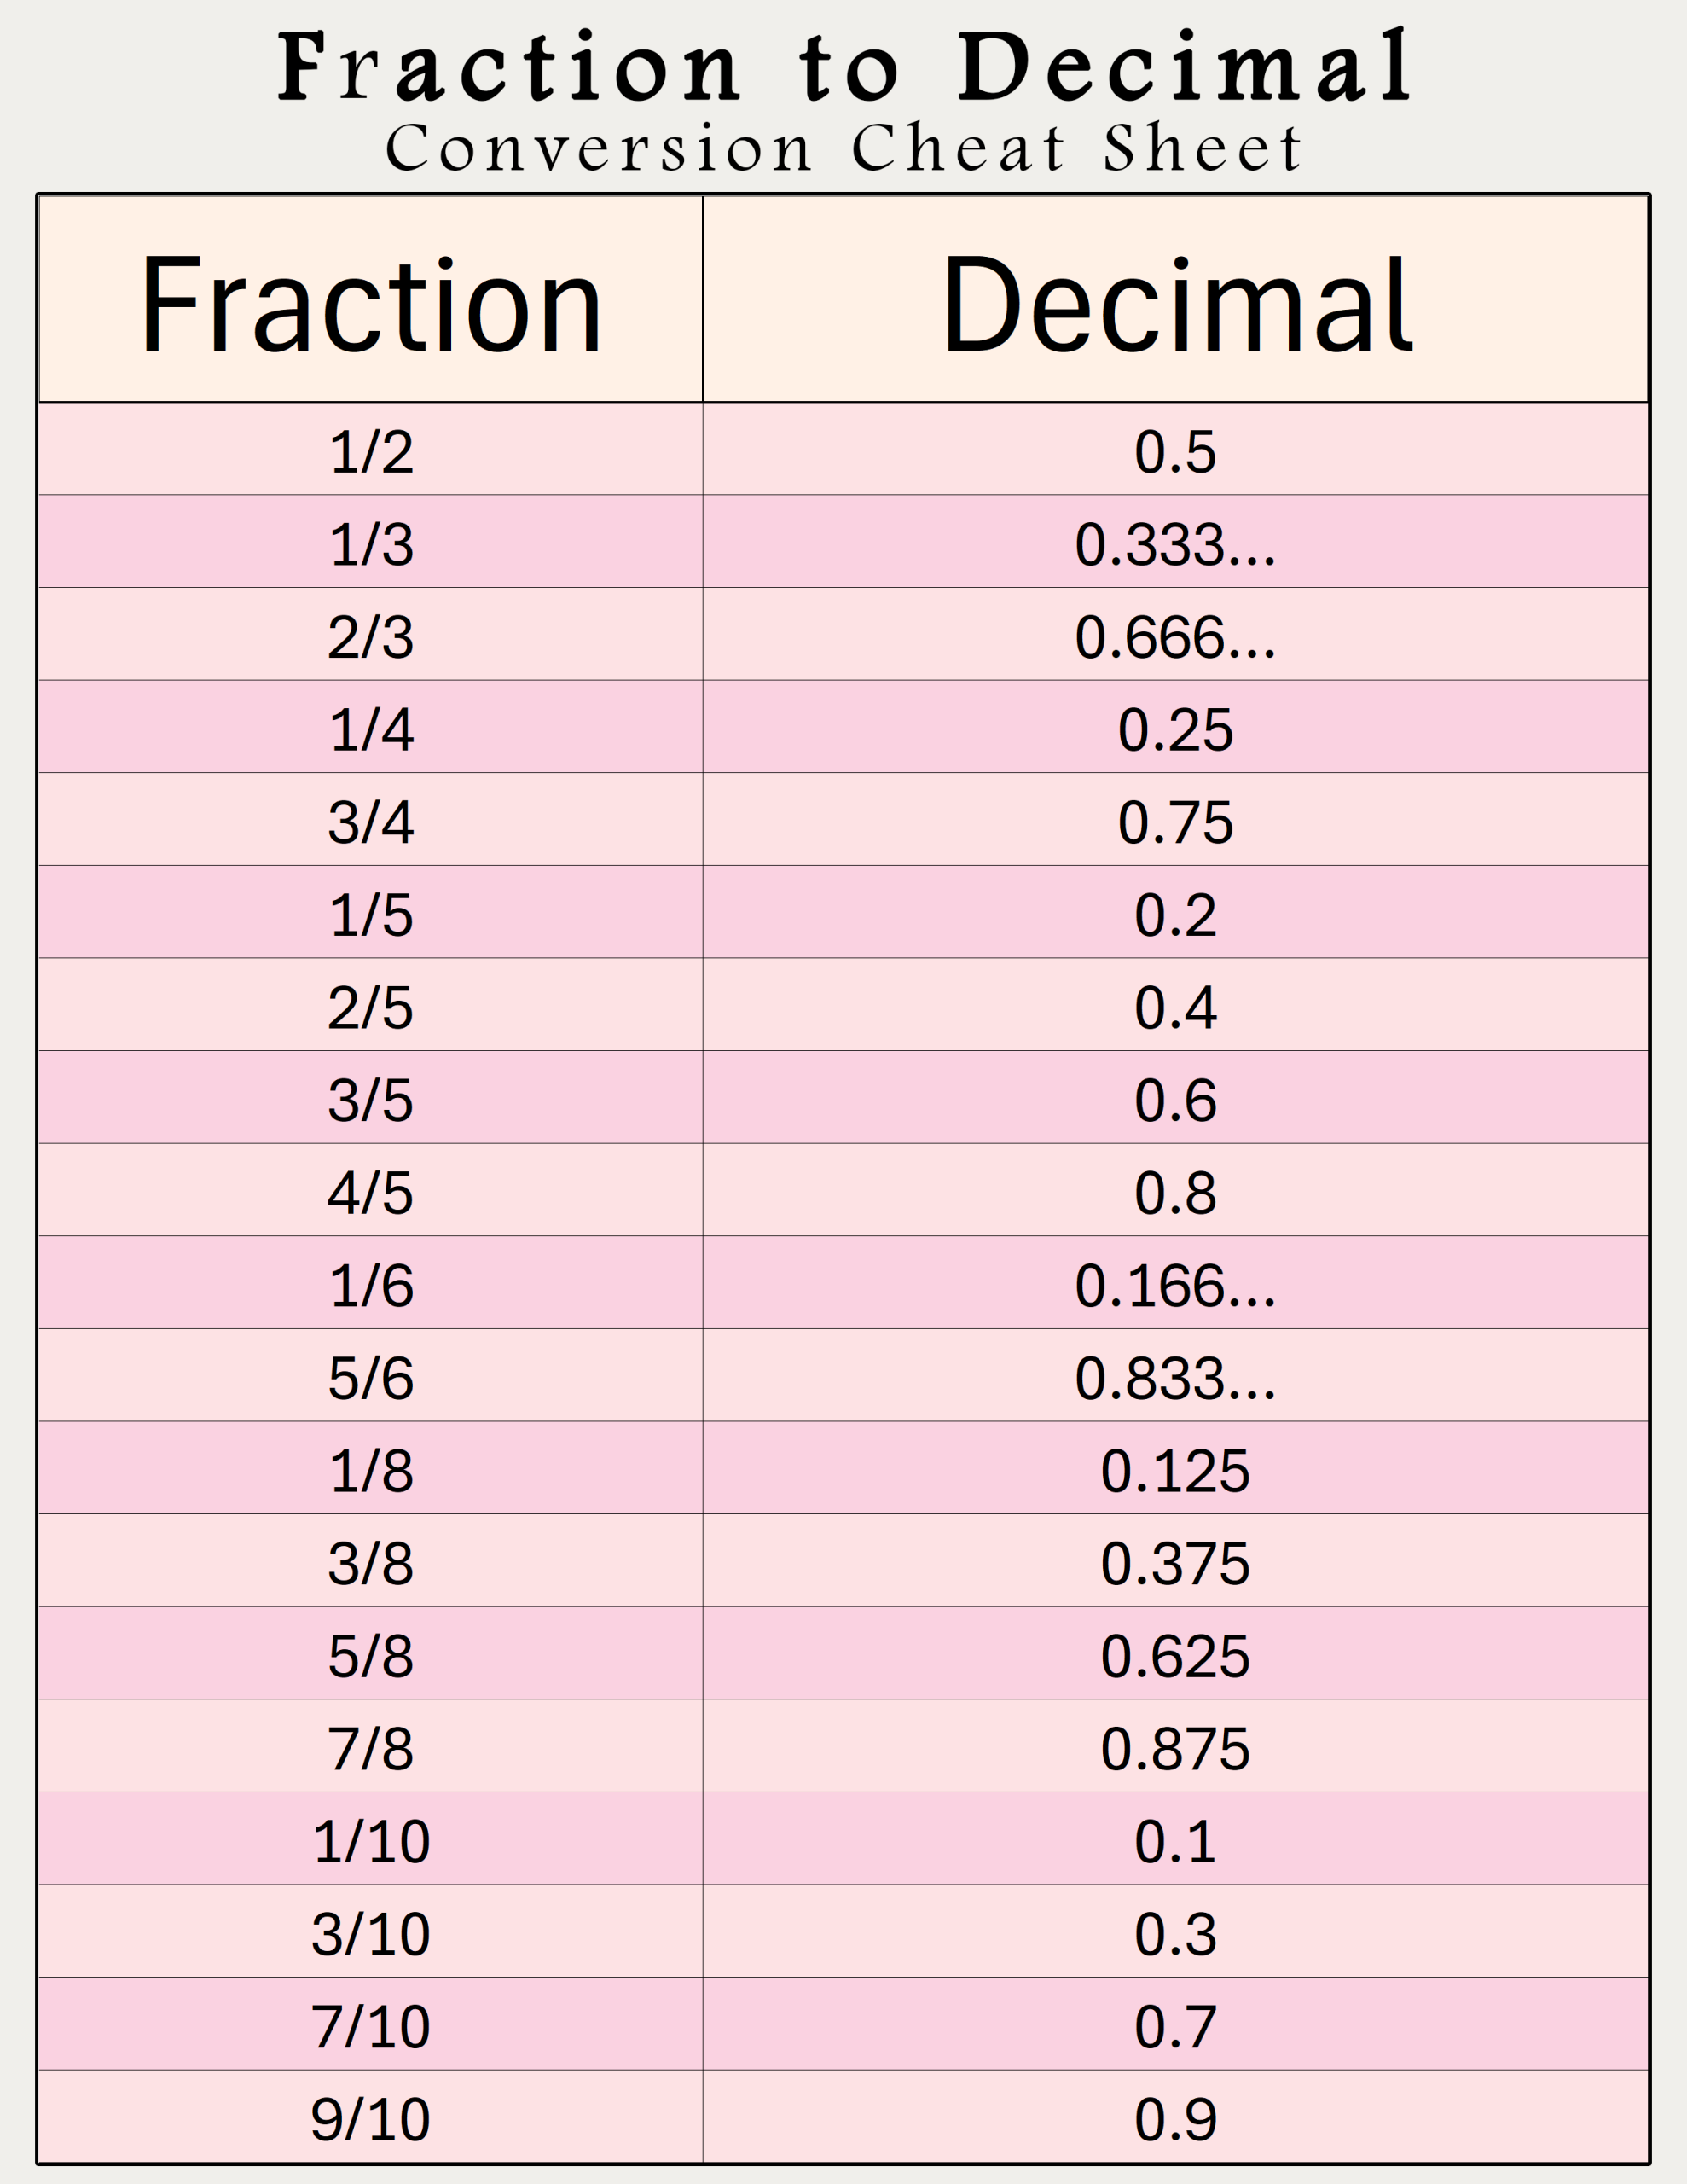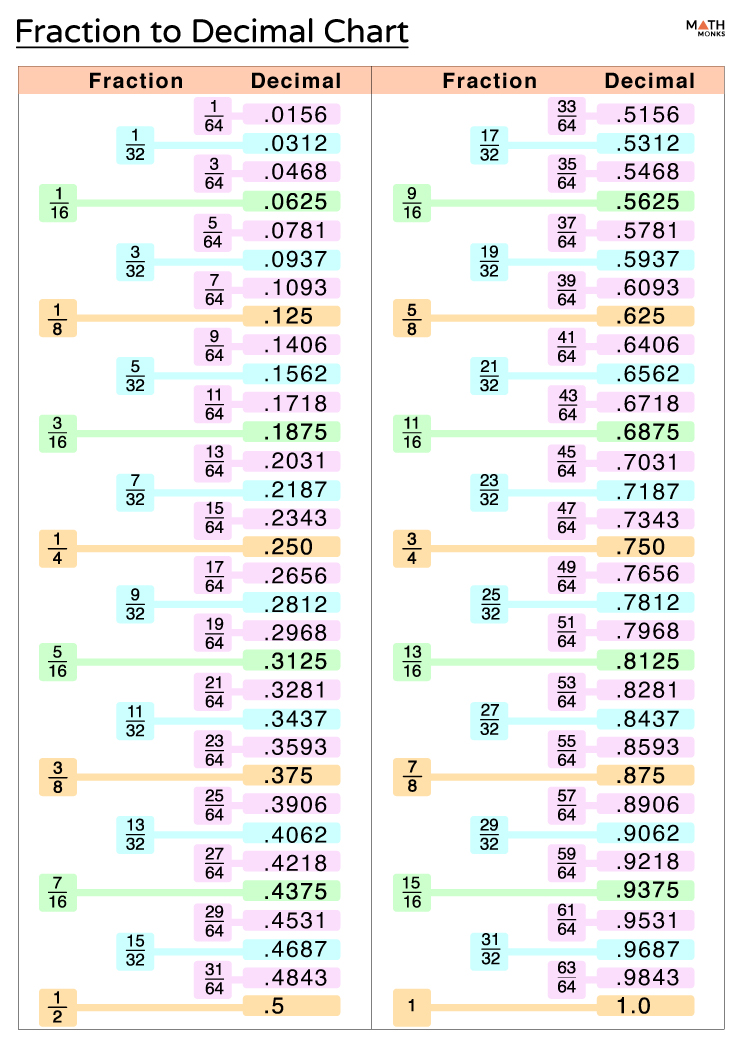
Converting decimal fractions to whole decimal numbers
I deal with this conversion constantly in data migration work. A client sends me CSV exports where every numeric field is formatted as a fraction — 3/8, 7/16, sometimes even 45/128 — and they want clean decimal columns in their SQL database. The actual math is elementary, but the edge cases are what burn people. The core operation is simple division: take the numerator and divide it by the denominator, then format the result as a standard decimal. If your fraction is 5/8, you compute 5 divided by 8, which gives you 0.625. That is the decimal form. Done.
Decimal Fraction To Decimal conversion methods
There are two main ways people handle this, and the choice matters more than you might expect if you are processing large datasets. The manual approach works fine for one-off calculations. You divide the top number by the bottom number and write down the result. I use this when I'm writing reports and need three specific values. For anything beyond that, you automate it. In code, a Decimal Fraction To Decimal conversion in Python looks like this:
from fractions import Fraction frac = Fraction(5, 8) decimal_value = float(frac)
Get the Full Details

print(decimal_value) outputs 0.625 I typically use the Fraction module rather than straight division because it handles reduction automatically. Without it, you might feed in 14/28 and get a messy float that looks wrong even though it is technically correct. For Excel users, the formula is straightforward: =A1/B1 where A1 holds the numerator and B1 holds the denominator. Then format the output cell as a decimal with however many places you need. The danger here is that Excel stores everything as IEEE 754 floating point under the hood, which introduces rounding artifacts at scale.
Where things actually go wrong
Floating point representation is the biggest trap. The fraction 1/10 does not have an exact binary equivalent. In Python, float(1/10) gives you 0.10000000000000001. It is a tiny error, but it accumulates across thousands of rows and breaks financial calculations that require exact cent-level precision. When I hit this in production, I switch to Python's decimal module with explicit precision settings. Instead of float(), I use Decimal(numerator) / Decimal(denominator) and set the context precision to however many places the business actually requires. This is slower but it is exact within your configured precision, and it catches problems before they ship. Another issue is infinite repeating decimals. The fraction 1/3 becomes 0.333333... forever. You have to decide on a cutoff point. Most systems default to 15-17 significant digits before they start repeating due to double precision limits. If your domain requires more than that, you need arbitrary precision libraries or you accept the truncation and document it.
I encountered a specific problem last year where a logistics client had weights stored as fractions with denominators of 64 (sixty-fourths of a pound). When I converted them using standard float division, the sums across invoices drifted by $0.03 to $0.07 per batch. The root cause was cascading floating point error across roughly 40,000 rows. The workaround was switching to integer arithmetic throughout the pipeline — keeping everything as sixteenths or sixty-fourths until the final output stage, then converting once at the end with the decimal module. That eliminated the drift entirely and the reconciliation passed on the first try.

Common pitfalls and what to watch for
Denominator zero is obvious but still worth mentioning because automated pipelines encounter it regularly when source data is dirty. Always validate that the denominator is not zero before performing the division. A simple conditional check prevents the entire batch from crashing. Negative fractions behave differently depending on your language. In some languages, -5/8 might be parsed as negative five divided by positive eight, giving -0.625. In others, integer division rounds toward zero, so -5/8 could evaluate to 0 before you even get to the float conversion. Check your language's behavior with negative operands. Large numerators and denominators can overflow standard integer types. If you are processing fractions from engineering drawings where denominators might be powers of 2 up to 1024 and numerators in the thousands, you should use 64-bit integers or arbitrary precision types. Standard 32-bit integers will overflow and produce garbage results silently.
Here is a practical example that covers most real-world cases: Convert 7/16 to decimal. 7 divided by 16 equals 0.4375. Exact, no rounding needed because 16 is a power of 2 and the division terminates cleanly in binary.
Convert 2/3 to decimal. 2 divided by 3 equals 0.666666... You need to decide how many places to keep. Three decimal places gives 0.667. Six gives 0.666667. Ten gives 0.6666666667. Each is a different level of precision loss. Convert 11/4 to decimal.
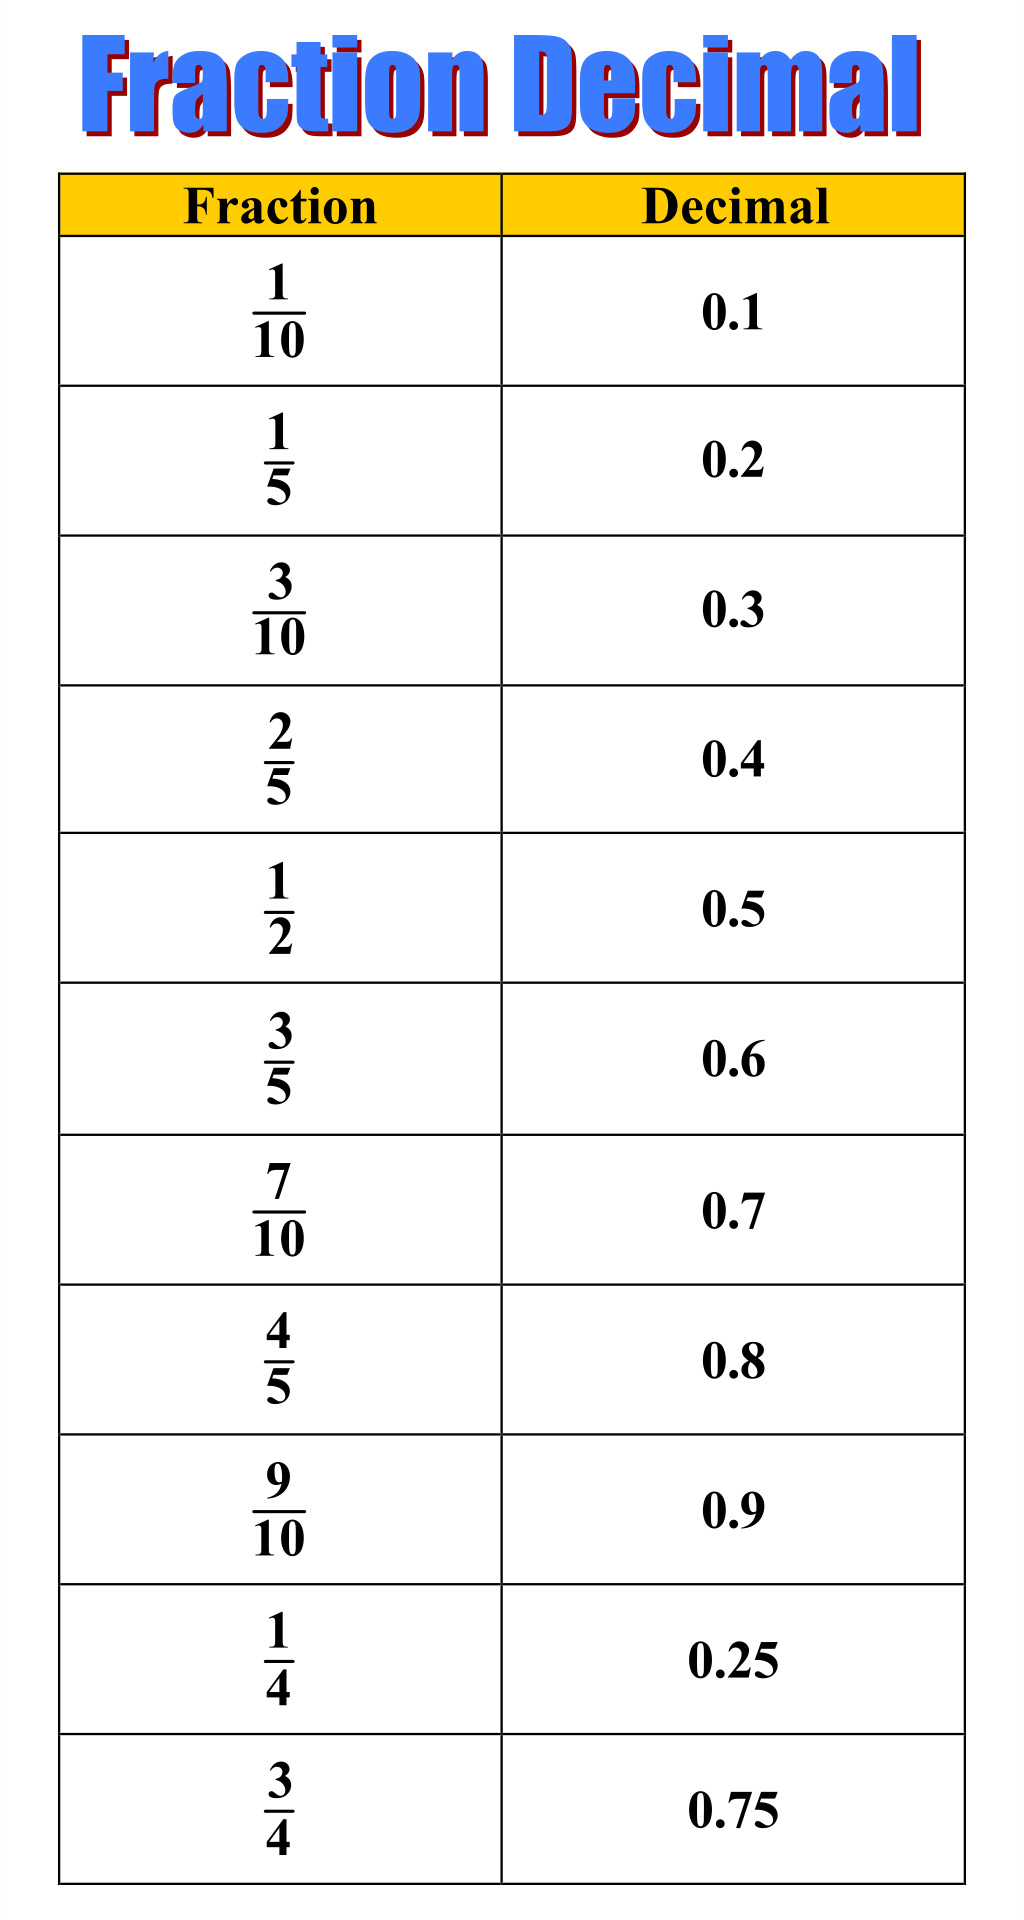
11 divided by 4 equals 2.75. Straightforward because 4 divides evenly into the numerator with a remainder of 3, and 3/4 is exactly 0.75.
When this approach is not the right tool
If you are working in a domain where exact arithmetic is non-negotiable — financial ledgers, tax calculations, cryptographic applications — converting decimal fractions to floating point decimals is the wrong intermediate step. You should keep values in their fractional form as long as possible and only convert at the final output stage. Every conversion introduces potential precision loss, and the loss is irreversible once it happens. For high-volume batch processing where speed matters more than absolute precision, standard float conversion is adequate. The 15-17 digit precision of double-precision floats handles the vast majority of non-financial use cases without anyone noticing. Use the decimal module or equivalent only when you have demonstrated that floating point error is actually causing problems in your output. I usually recommend starting with the simplest method that meets your accuracy requirements, measuring the error if there is any doubt, and only adding complexity when the measurement shows it is necessary. Premature use of arbitrary precision libraries adds overhead and complicates debugging for no measurable benefit in most cases.