Why Your Decision Frameworks Keep Failing In Practice
I spent about seven years building decision models for supply chain and capital allocation at a mid-size manufacturing firm. What I learned is that most professionals treat decision analysis as a documentation exercise rather than a thinking tool. You'll see someone hand you a spreadsheet with twenty tabs, three cascading probability distributions, and a sensitivity table that took two weeks to build. Then they ask if the project is viable. The answer was obvious from the first row of data. The model didn't help them figure that out faster. It just convinced everyone the conclusion was rigorously derived. The core principle behind Decision Analysis For The Professional isn't complex: you identify the decision, map the outcomes, assign probabilities, calculate expected values, and pick the path with the highest utility. That's it. The gap between that description and what actually happens in an organization is enormous. Most of that gap comes from treating every decision as if it deserves the same analytical weight. A $40,000 software purchase doesn't need a Monte Carlo simulation. A $4 million facility expansion does, but probably not the way you're thinking about building it.
Decision Analysis For The Professional: What It Actually Looks Like Day to Day
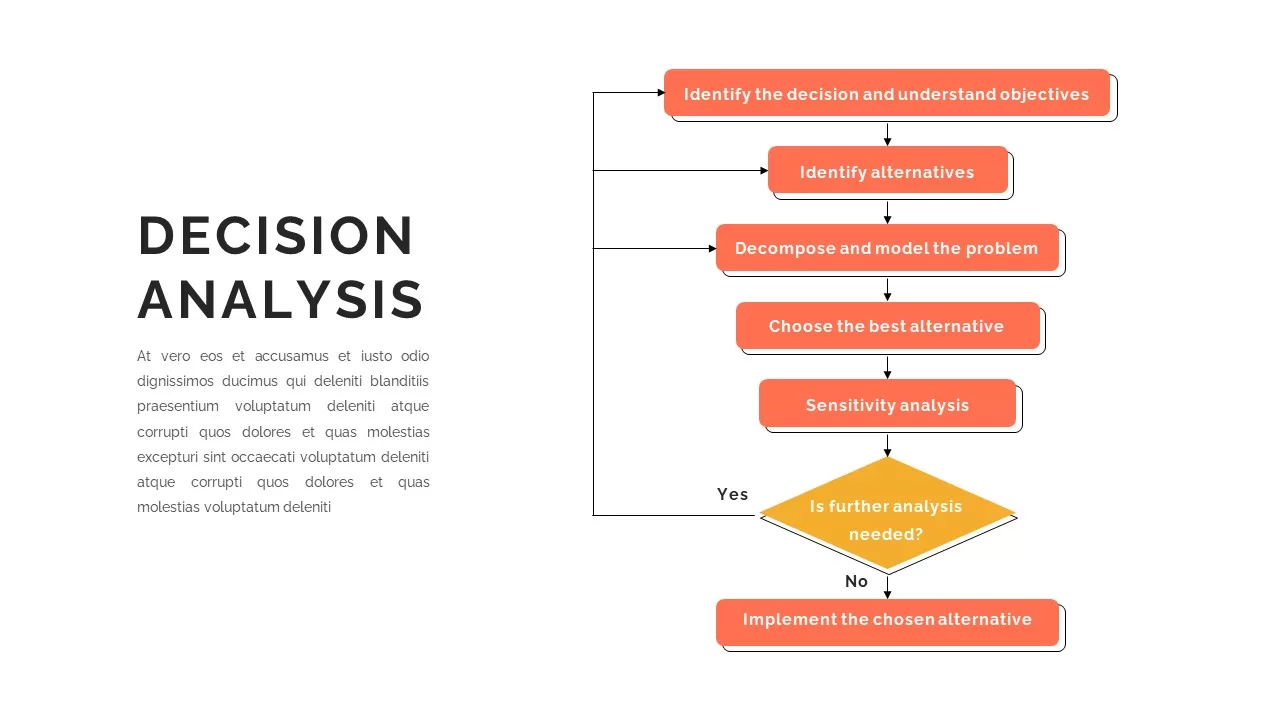
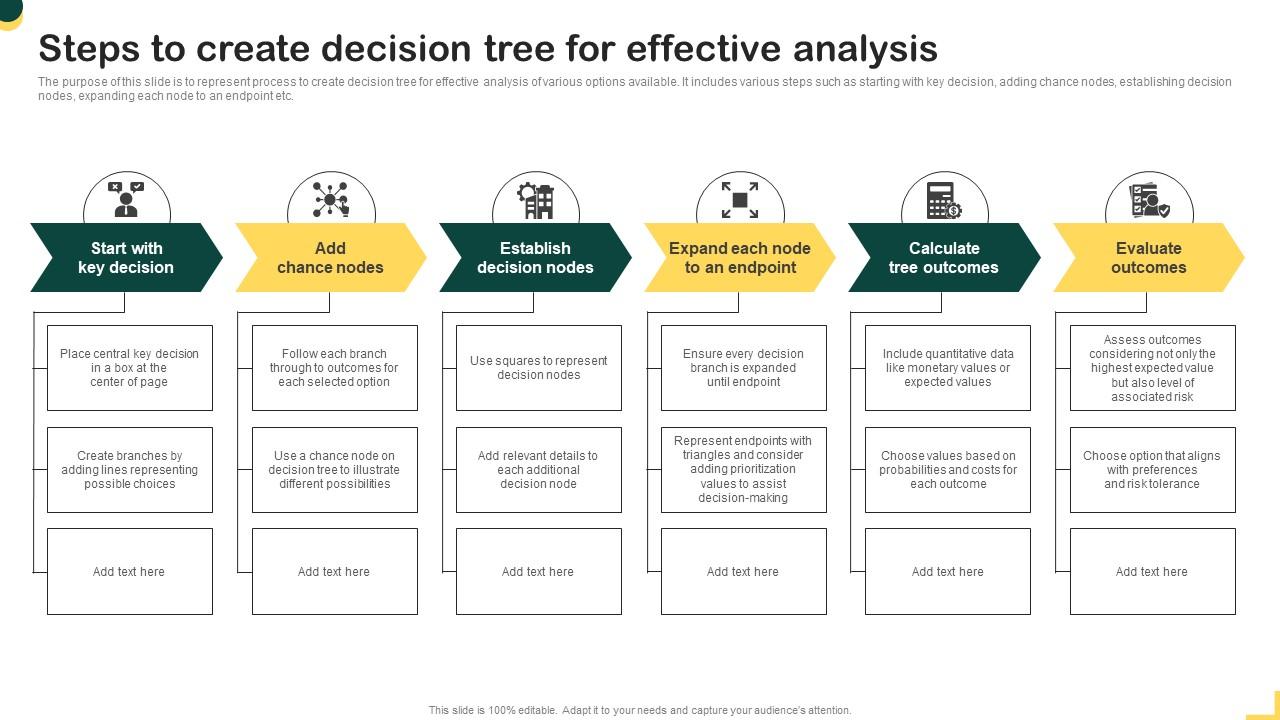
When I say "professional," I'm talking about someone who makes repeated decisions under uncertainty, where the consequences are material but the data is never complete. That could be a project manager choosing between vendor bids, a product lead deciding whether to kill a feature, or a finance person evaluating a acquisition target. The framework is the same across all of them, but the speed and granularity shift dramatically based on stakes and available information. Here's a workflow that actually works without turning into bureaucracy. First, write down the decision in one sentence. If you can't, you don't understand the problem yet. Second, list every real option you have, including the option to do nothing and the option to gather more information before deciding. Third, identify the key uncertain variables that will determine the outcome. Not all variables matter equally. In my experience, three to five variables capture 80 to 90 percent of the outcome variance. Everything else is noise that will make your model look sophisticated without improving your decision quality. Fourth, assign probabilities to those variables. Use whatever data you have. If you don't have data, use your best judgment and document why. Fifth, calculate expected values for each option. Sixth, and this is the part most people skip, run a sensitivity check. Vary each key assumption by twenty percent and see how much the recommendation changes. If flipping one assumption reverses your decision, that variable is critical and you should invest in getting better information about it before committing. If none of the assumptions move the needle, your decision is robust and you can proceed without overthinking.
I ran into a specific edge case with a project where we were evaluating whether to build a custom integration platform or buy one off the shelf. The build option had a lower quoted cost, maybe thirty percent lower. The buy option had higher licensing fees but lower implementation risk. My initial model favored building. Then I identified a key variable I hadn't properly accounted for: the probability of key engineer attrition during the eighteen month development window. I had assigned it at fifteen percent based on historical averages. The attrition risk in this particular team was closer to forty percent because we were in a hypergrowth phase with equity vesting cliffs approaching. When I adjusted that single variable, the expected value of the build option swung negative. We bought the platform. The custom integration eventually would have cost us nearly twice as much in lost productivity and delayed revenue. The workaround I developed was simple and I've used it ever since: whenever a decision depends on human behavior rather than mechanical or market variables, I inflate the uncertainty band by a factor of two. If your base case estimate has a fifty-fifty range, widen it to a seventy-thirty range and recalculate. It's not rigorous statistics. It's recognition that people are more unpredictable than spreadsheets assume. Another counter-intuitive thing about professional decision analysis: the best models are often the ones you tear down quickly. I've seen teams spend weeks refining probability distributions for variables that turned out to be irrelevant after the decision was made. If your analysis takes longer than the decision deadline, you've optimized for the wrong thing. A rough decision made on time beats a perfect decision made too late, every single time. There's a term for this in operations research called the cost of delay, and it's almost always understated in decision models. The cost isn't just the lost opportunity. It's the organizational momentum that shifts while you're still building your spreadsheet.
Get the Full Details
There are also scenarios where decision analysis breaks down entirely, and you need to know when those are. When the probabilities are so uncertain that any numerical assignment is essentially a guess, expected value calculations become misleading. This happens frequently with strategic pivots, new market entries, or technological disruptions. In those cases, real options thinking or scenario planning serves you better than a standard decision tree. You're not calculating expected returns. You're preserving flexibility and buying yourself the right to adjust course later. The math looks different but the discipline of forcing yourself to name your assumptions explicitly still applies. Another failure mode is when the decision maker doesn't actually own the consequence. I've watched senior leadership commission detailed decision analyses for projects where the people who built the models would never be held accountable if the assumptions were wrong. The analysis became performative. It was designed to justify a decision that had already been made politically. The numbers were correct. The conclusion was predetermined. This is worth watching for because it's common enough that you'll encounter it regardless of your industry. If you notice the model seems designed to produce a specific output rather than explore the decision space, step back. Either redesign the analysis or flag the conflict directly. The practical tools are straightforward. Excel or Google Sheets handles most professional decision analysis. You don't need specialized software unless you're running thousands of simulations regularly, and even then, basic Python or R scripts are cheaper and more transparent than black-box tools. The real skill isn't in the tool. It's in knowing which assumptions to challenge, which variables to simplify, and when to stop analyzing and commit. That comes from doing this repeatedly and noticing which decisions actually played out the way you predicted and which ones didn't. The mismatches teach you more than the matches ever will.