Who Actually Makes Decisions In Economics
The way economic decision-making actually works is a lot messier than the textbook versions suggest. You have households, firms, governments, and central banks all operating with different information sets, different time horizons, and different incentive structures. When people ask about Decision Makers In Economics, they are usually looking for a clean framework. The clean framework exists. It does not hold up under scrutiny. I spent years working on policy analysis where we had to model how three separate decision makers would respond to a single tax change. The standard consumer-firm-government breakdown sounded right on paper. What actually happened was that the firm lobbied for a loophole, the household shifted spending to untaxed substitutes, and the government panicked and revised the policy three times before it took effect. By the time you mapped all the moves, the original decision maker nobody even looked at, local municipal regulators, ended up determining the outcome. That is the thing about these models. The actors you ignore always matter more than the actors you focus on.
Understanding Decision Makers In Economics
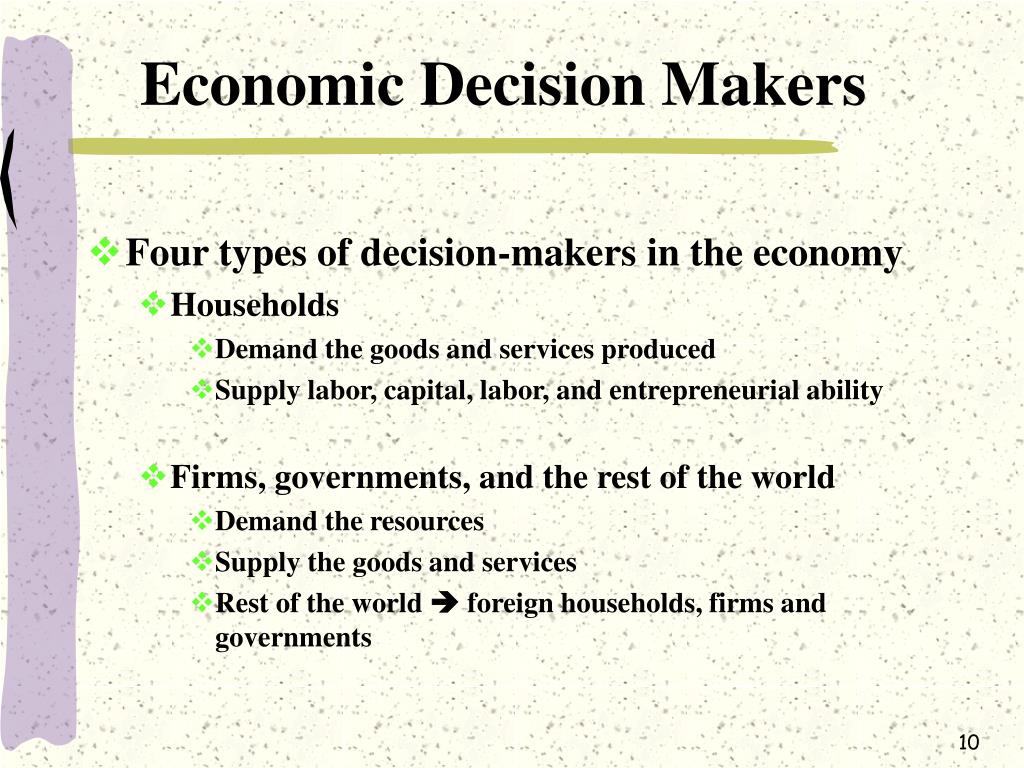
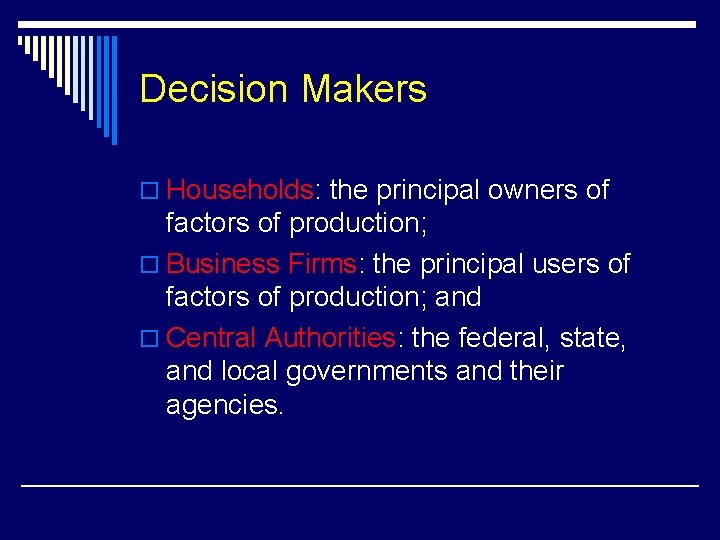
At the basic level, economic decision makers fall into categories defined by what they optimize and what constraints they face. Consumers maximize utility subject to budget constraints. Firms maximize profit subject to technology and market conditions. Governments maximize some objective function, though nobody can agree which one, subject to political constraints. Central banks target inflation and employment. Each has a different functional form behind their choices. The math works cleanly when you keep them isolated. It stops working when they interact. Rational choice theory gives you the baseline. Agents have consistent preferences, process information efficiently, and choose the option that maximizes their objective. That baseline is useful because it gives you a reference point. It is not useful because it is accurate. The gap between the reference point and actual behavior is where the real work happens. I once modeled a subsidy program for small manufacturers. The textbook prediction was that the subsidy would increase output by the elasticity of supply. The actual result was a 40 percent drop in participation. The firms that qualified simply did not apply because the paperwork requirement alone exceeded their capacity to process it. The decision maker in that scenario was not the firm optimizing profit. It was the administrative burden filtering out every firm that could not afford a dedicated compliance person. When I added that constraint to the model, the predictions lined up. The theory was not wrong. The boundary conditions were wrong.
Behavioral economics modified the standard framework by introducing bounded rationality, present bias, and loss aversion. These are not minor corrections. They change the predictions in directions that matter for policy. A consumer with present bias will discount future costs differently than a consumer with exponential discounting. A firm facing prospect theory dynamics will hold onto losing positions longer than expected value calculations would suggest. This is not trivia. It determines whether a carbon tax actually reduces emissions or just shifts reporting patterns. Game theory handles the interaction problem. When multiple decision makers play off each other, you need a framework that tracks strategic dependencies. Nash equilibrium gives you the stable outcome where no player wants to deviate unilaterally. Repeated games add reputation effects. Asymmetric information creates signaling and screening problems. The mechanism design literature turns it around and asks what rules you would set if you wanted to extract specific behaviors from rational players. That is how auction design works now. That is how spectrum allocation works. Those are not academic exercises. They move billions in value. The pitfall most people hit is assuming that all decision makers operate on the same decision loop. Households adjust consumption monthly or quarterly. Firms adjust investment on annual cycles. Governments respond to election cycles. Central banks have longer mandates but still react to data releases. When you model a shock, the timing of each response matters as much as the direction. A policy that looks effective at six months can look like a disaster at eighteen months because the decision makers you modeled adjusted while the ones you did not model responded in a lag you ignored.
Get the Full Details

I worked on a project evaluating a wage subsidy for low-income workers. The initial model predicted a twenty percent employment increase based on labor supply elasticity estimates from the literature. The actual outcome was a six percent increase with significant leakage into areas the model did not cover, like informal work that slipped outside the measurement frame. The problem was that the decision makers in the informal sector do not respond to formal subsidy signals at all. They respond to cash flow constraints and local opportunity structures. Once I stopped treating the formal-informal boundary as exogenous and modeled the transition explicitly, the prediction improved. It still missed by four percentage points because we could not observe the transition rates directly. That is the limit of this approach. You can refine the model until it fits your data, but if the structural parameters are unidentifiable, you are just calibrating noise. Another common mistake is treating preference stability as a given. Preferences shift with context, with framing, and with social norms. An electorate that supports a policy in a survey can reject it once the policy is implemented and the distributional consequences become visible. Firms that signal one set of priorities in press releases make different choices when margins tighten. If you lock preferences in place, your model will predict compliance where there is actually resistance. The fix is to make preference parameters endogenous where it matters and to test the sensitivity of your results to reasonable preference shifts rather than presenting a single equilibrium as definitive. The tools you use depend on what question you are asking. DSGE models handle macro-level decision making across households, firms, and central banks. They are computationally tractable and internally consistent. They also abstract from heterogeneity in ways that matter when you are analyzing distributional effects. Microsimulation models track individual decision paths but require detailed data that is rarely available. Agent-based models relax the rationality assumptions entirely and let behavior emerge from local rules. They are flexible but difficult to validate. The choice among them is not about which is best. It is about which errors you can tolerate for your particular application.
When you need to communicate decision maker analysis to non-specialists, the temptation is to simplify the model until it becomes a story. Stories are memorable. They are also misleading. A cleaner approach is to show the key assumptions explicitly and let the audience see where the conclusions depend on them. If the result flips when you change the discount rate or the elasticity assumption, say so. Hiding that vulnerability does not make the analysis stronger. It makes it fragile in a way that only becomes visible when someone applies it to a case you did not anticipate. There is also the issue of institutional decision making versus individual decision making. Corporate boards, legislative bodies, and committees make choices that no single actor would make alone. The aggregation rule matters. Majority voting can cycle. Committee structures can be gamed. Bureaucratic inertia can override stated objectives. When you model a government as a single utility-maximizing agent, you lose all of that. You gain tractability. You lose accuracy. The tradeoff is real and you should measure how much you lose before you decide it is worth the gain. If you are building a model and want to check whether your decision maker assumptions are driving the results, run a sensitivity analysis on the key behavioral parameters. Change the elasticity, the discount factor, the risk aversion coefficient, and the information structure. If the conclusion survives a wide range of reasonable values, you have something robust. If it flips with a ten percent shift, you have a result that depends on a specific parameter choice, and you should label it as such. That is the standard I apply now. It keeps you from overstating confidence in outputs that are really just artifacts of your assumptions.
The field moves slowly toward better measurement. Linked administrative data, high-frequency surveys, and experimental methods give us more information about actual choices than we had even a decade ago. The models have not kept pace as quickly as the data has. The gap is where the useful work lives. If you can connect a structural model to observed behavior without forcing the data to fit the theory, you will find more signal than noise.