Why Your Dashboard Is Lying to You
Most organizations treat Decision Support System And Business Intelligence as a software problem. It is not. It is an organizational hygiene problem. I spent three years fixing broken BI implementations before I stopped blaming the tooling and started looking at where the data actually lived. Here is how the machinery works when it is built correctly, and where it silently breaks.
The architecture behind Decision Support System And Business Intelligence
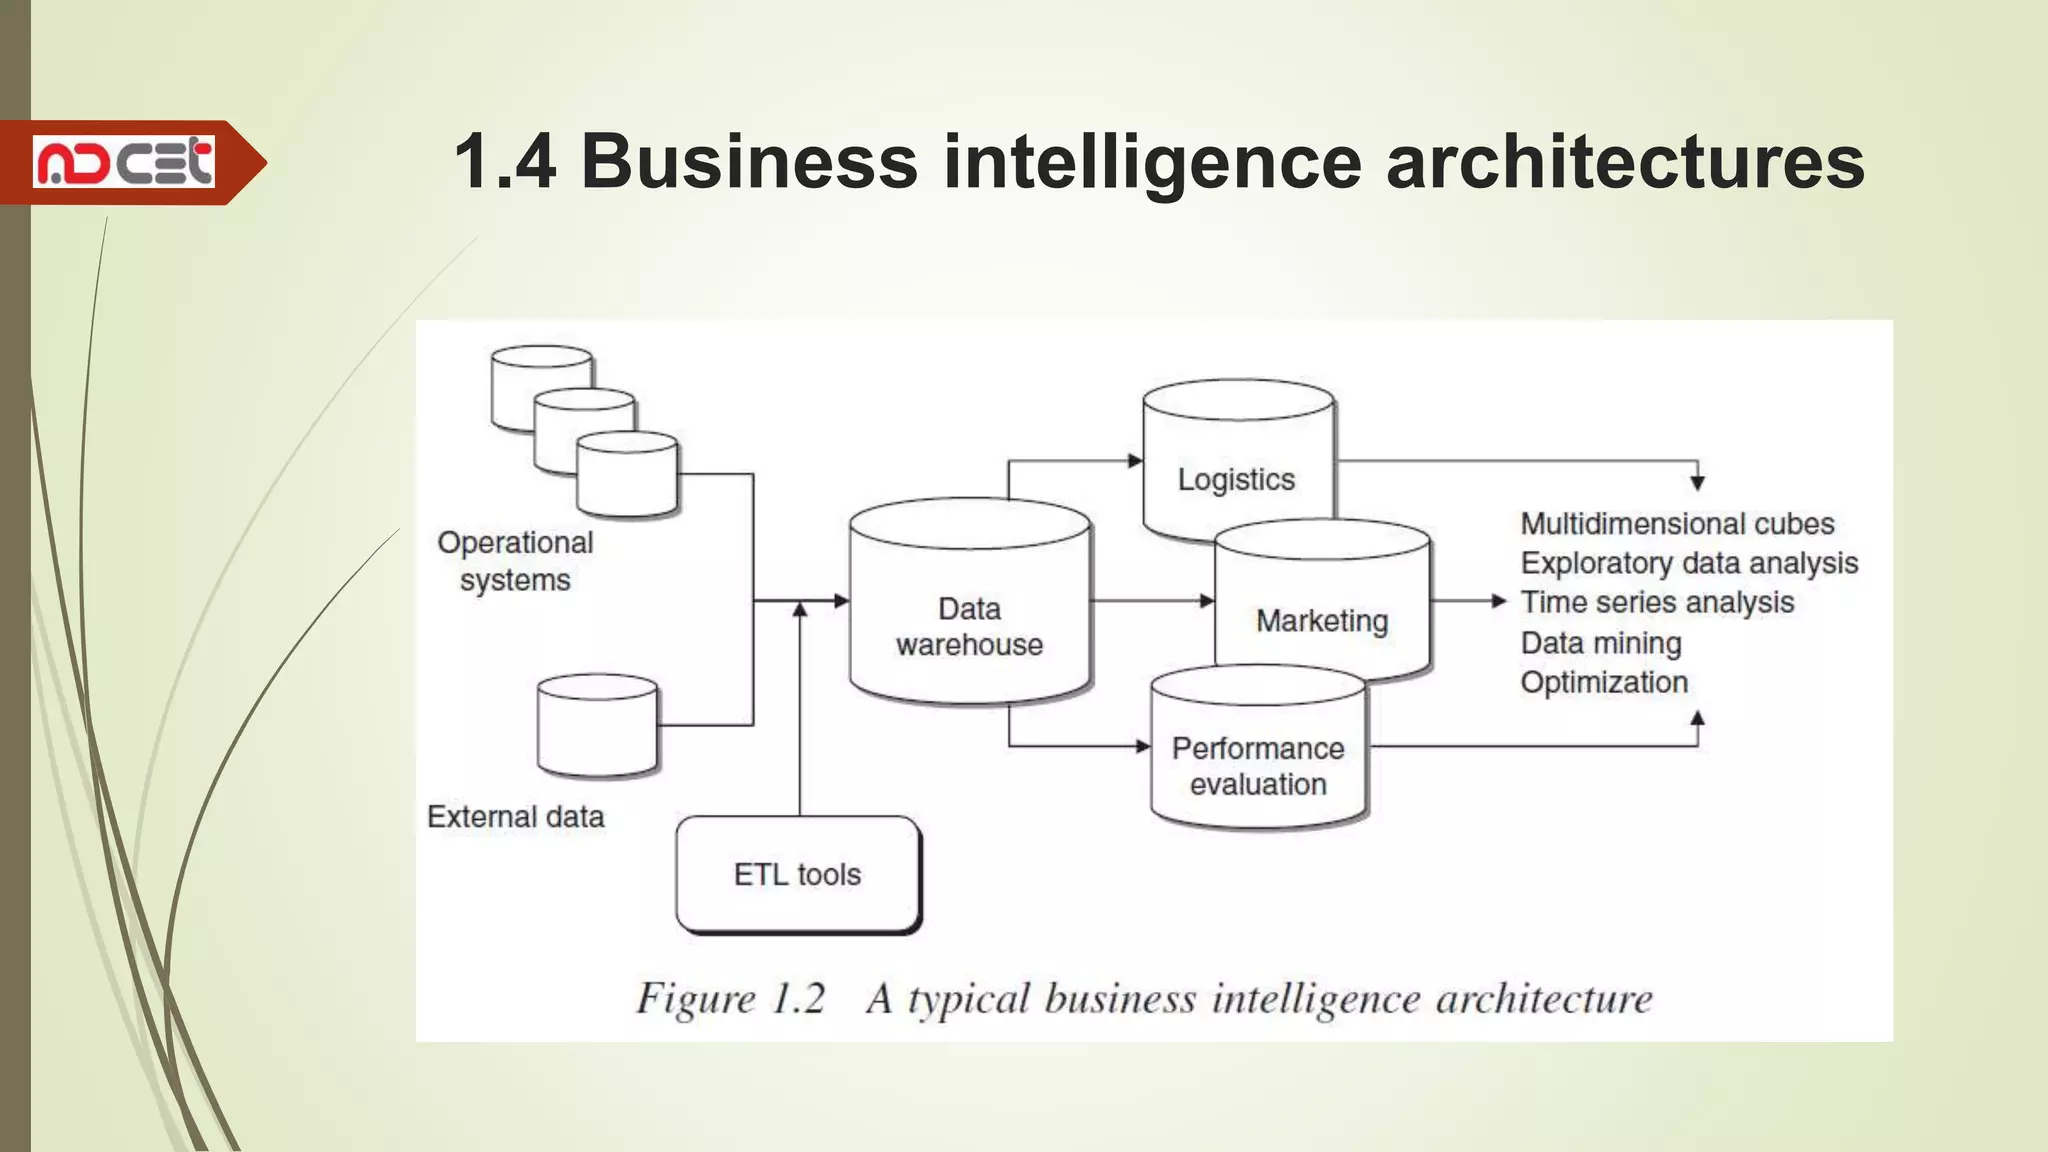
A traditional BI pipeline moves data through four stages: extraction, transformation, loading, and presentation. Each stage introduces friction. Extraction pulls from transactional databases that were never designed for analytical queries. Transformation applies business logic that is often undocumented. Loading deposits the result into a columnar store like Redshift or BigQuery. Presentation renders it as charts that executives interpret as truth. The decision support piece is what happens after the chart loads. It connects structured data to judgment. That connection requires rules, thresholds, and escalation paths. Without those, you have a pretty dashboard and a guessing game. I built a supply chain forecasting model once where the BI layer reported a 94% on-time delivery rate. The number was technically correct. It was also useless because the report only tracked shipments that made it to the delivery partner. Returns, warehouse holds, and carrier transfers were excluded by a joins condition that nobody on the team could remember the origin of. I found it after two weeks of variance analysis. The workaround was building a data quality sentinel that compared row counts at each transformation stage against the source system. When the deviation exceeded 3%, the pipeline flagged it instead of delivering a confidently wrong number.
How to actually implement this without wasting six months
Start with the decision, not the data. Write down three decisions your leadership team makes every week. For each one, trace backward to what information would change the outcome. That reverse engineering tells you exactly what to build. Most teams do the opposite and build everything available, then wonder why nobody uses it. Choose your stack based on refresh frequency, not vendor prestige. Real-time isn't real until it is reliable. A batch model that refreshes every four hours with complete data beats a streaming pipeline that drops events when the broker has a hiccup. I recommend starting with a daily ETL cycle using something like dbt for transformation and a warehouse like Snowflake or BigQuery for storage. Add streaming only when a specific decision cannot wait twenty-four hours. Document your metric definitions in a single source of truth. A metric called "revenue" should mean the same thing in the CFO slide deck as it does in the engineering dashboard. When sales defines it as booked and finance defines it as recognized, your BI system will produce two different numbers and nobody will know which one to trust. Build a centralized semantic layer. It takes more upfront work but prevents the erosion that follows.
Get the Full Details
Common pitfalls that kill these projects
Over-customizing the presentation layer is the fastest way to make a system unmaintainable. Every custom widget is a line of code that needs debugging. Use standard chart types and reserve customization for edge cases that genuinely require it. Most edge cases do not require it. Another pitfall is assuming that data quality fixes belong in the pipeline. They sometimes belong upstream. If your CRM requires a customer ID before a lead can be saved, you do not need a BI-level workaround. You need a workflow change. Pipeline-level fixes for upstream problems are expensive and fragile. And the biggest one: building for the committee instead of the decision maker. A dashboard designed for twelve stakeholders ends up serving none of them well. Design for one person making one decision. Add layers afterward.
Tools that actually move the needle
For transformation, dbt remains the standard for a reason. It turns SQL into version-controlled, tested code. The testing layer catches breaking changes before they reach production. I once caught a broken join that would have misreported a client retention metric by twelve percentage points because a test failed. That test saved a board meeting from bad data. For visualization, look beyond the default templates. Tableau and Power BI are capable, but their defaults optimize for generality, not clarity. Strip out decorative elements. A chart should communicate one idea. If it communicates three, you are giving the viewer too much work to do. For the actual decision support component, consider rule engines like Drools or custom threshold logic embedded in your query layer. Automated alerts should only trigger when a metric crosses a boundary that warrants human intervention. Alert fatigue is real. I saw a team suppress forty percent of their notifications after realizing most alerts were triggered by normal variance, not actual problems.
When this approach fails
Decision Support System And Business Intelligence struggles with unstructured data. Text, images, and free-form notes resist the columnar model. If your critical decisions depend heavily on qualitative input, a traditional BI stack will miss the signal. In those cases, pairing your BI with an LLM-based text analysis layer can bridge the gap, but that adds complexity and cost. It also fails when organizational incentives are misaligned. If a team benefits from appearing competent by reporting positive numbers, no dashboard will fix that. A BI system amplifies what it is fed. It does not correct for motivated reasoning. The bottom line is straightforward. Build the simplest pipeline that answers the most important decision. Test it rigorously. Document everything. Update the documentation when the pipeline changes. Most teams skip two of those steps and then complain that the system is unreliable.