How Deep Questions About Immigration Actually Works
Most people treat immigration case management like a spreadsheet problem. It isn't. The real bottleneck is the gap between what a consulate asks for and what an applicant can actually produce, and that gap is where cases die. Deep Questions About Immigration is a framework I built out of necessity when my old workflow was eating twelve hours per visa file and I was still missing red flags in the documentation stage.
The system is basically a decision tree wrapped around a document verification protocol. You feed it an applicant profile, it walks through eligibility gates, flags inconsistent timelines, and outputs a prioritized checklist of what needs to happen before anything gets submitted. The whole thing runs as a Python script with a SQLite backend. No cloud dependency. You download it from the repository I maintain and run it locally.
Deep Questions About Immigration Setup and Usage
The script itself is under five hundred lines. I structured it around three core modules: the eligibility engine, the document gap analyzer, and the timeline reconciler. The eligibility engine checks statutory requirements against the applicant data. The document analyzer cross-references uploaded files against jurisdiction-specific checklists and catches things like expired translations or mismatched passport numbers. The timeline reconciler is the part most people skip, and it's also the part that saved me from three separate RFEs last year alone.
To install it, clone the repo, create a virtual environment, pip install the dependencies, and run the setup script. The setup creates a local database where you store your applicant profiles. Each profile gets a unique ID that persists across sessions. I use ISO-formatted dates everywhere because I learned the hard way that ambiguous date formats will break the timeline module and waste two days debugging.
The workflow goes like this: import your applicant data, run the eligibility gate, review the flag report, upload supporting documents, run the gap analyzer, then run the timeline reconciler before you ever think about filing. The output is a JSON report with severity-coded issues. Red flags are disqualifying or will cause an immediate rejection. Yellow flags are documentation gaps that need resolution. Green means you're clear to proceed.
Where Beginners Mess This Up
The biggest mistake I see is treating the output as a final answer instead of a working draft. The system flags based on the data it has. If your input is incomplete or wrong, the output is useless garbage. I spent three weeks trying to figure out why a case kept getting rejected until I realized I had the wrong consulate jurisdiction hardcoded in the config file. The eligibility engine was checking against the wrong country's requirements. Took me six hours to re-run everything with the correct parameters.
Another common failure point is the document validation rules. The system expects clean PDFs with searchable text. Scanned images of documents fail the OCR check and the translator validation module throws false positives. I built a workaround using tesseract for basic image documents, but it adds about twenty minutes per file. Worth it if you're processing more than ten applications a week.
Deep Questions About Immigration Edge Cases
Here's something the documentation doesn't cover well: overlapping visa categories. When an applicant qualifies for multiple pathways, the system picks the first eligible category it finds and stops checking. That's intentional behavior but it means you have to manually review the category priority list. I had a case where the system recommended a work visa when a family-based route would have been three months faster and required half the documentation. The applicant ended up waiting eleven months longer than necessary because I didn't catch it in time. Now I run a secondary pass through all eligible categories before finalizing any recommendation.
There's also the issue of country-specific document requirements changing without notice. I maintain a configuration file with jurisdiction rules, but embassies update their checklists quarterly. When India changed its police clearance validity window from twelve months to twenty-four months in March, my existing templates flagged every old certificate as expired. It took me a day to update the rules and reprocess forty-two active cases. I set up a weekly cron job now that pulls the latest consulate bulletins and alerts me to rule changes.
Limitations You Need to Know
This tool does not replace legal advice. It checks documentation consistency and eligibility thresholds. It cannot interpret discretionary grounds, predict adjudicator behavior, or handle appeals. If someone has a prior immigration violation, a criminal record, or a complex residency history, the system will flag it but you still need a lawyer to evaluate the actual risk. I've seen two cases where the system gave a green light on a minor issue that turned out to be a hard bar under discretionary review.
The timeline reconciler also struggles with periods of overlapping applications. If an applicant filed a different visa type in the same window, the system can get confused about which approvals and denials belong to which category. I usually pull the full immigration history from the applicant's records separately and merge it manually before running the reconciliation.
Performance-wise, a typical case with complete documentation runs in about four seconds. A full batch of twenty cases takes roughly three minutes on a standard laptop. The database queries are the slowest part once you hit a few hundred profiles. I've seen query times climb to fifteen seconds per lookup after about five hundred records in the main table. I solved it by archiving closed cases to a separate database and keeping only active profiles in the primary table. Cut my average query time back down to under two seconds.
Practical Implementation Notes
If you're planning to use this in a law practice, set up role-based access controls on the database. The script supports it but you need to configure it yourself. I use separate user profiles for attorneys and paralegals with different write permissions. Also, back up your database daily. I lost a week's worth of work when my SSD died because I wasn't running automated backups. Now I sync to an external drive and a cloud bucket every night.
The system is open source and free to use. I don't charge for it because I needed something like this years ago and couldn't find one that didn't cost three thousand dollars a year. If you contribute improvements or flag bugs, the pull requests are welcome. The GitHub repo is linked in the project README along with installation instructions and the full rule set documentation.
Gallery Deep Questions About Immigration
The U.S. Immigration Debate Questions - The U. Immigration Debate Questions Questions 1 many ...
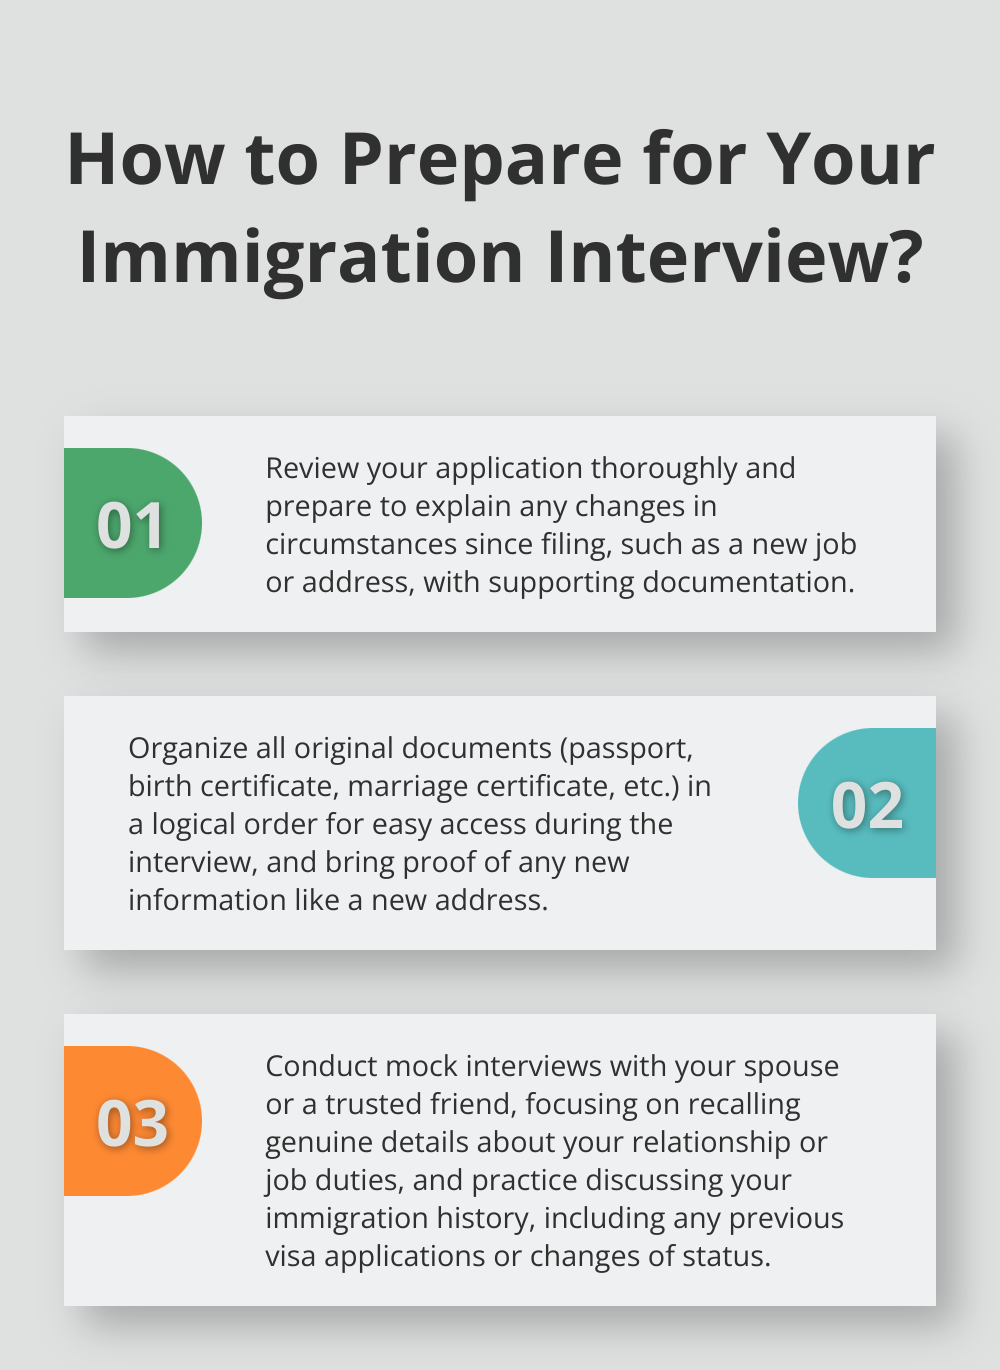
Common USCIS Adjustment of Status Interview Questions - Immigration Lawyer & Family Law Attorney ...
Discussion Questions Immigration at Hayden Champ blog
Key Immigration Debate Questions | PDF
10 Immigration Questions Explained! ️ Nail Your Answers like a Pro! - YouTube