What the Mode Actually Is
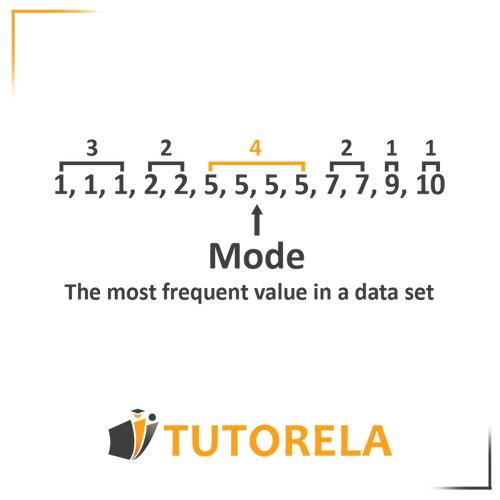
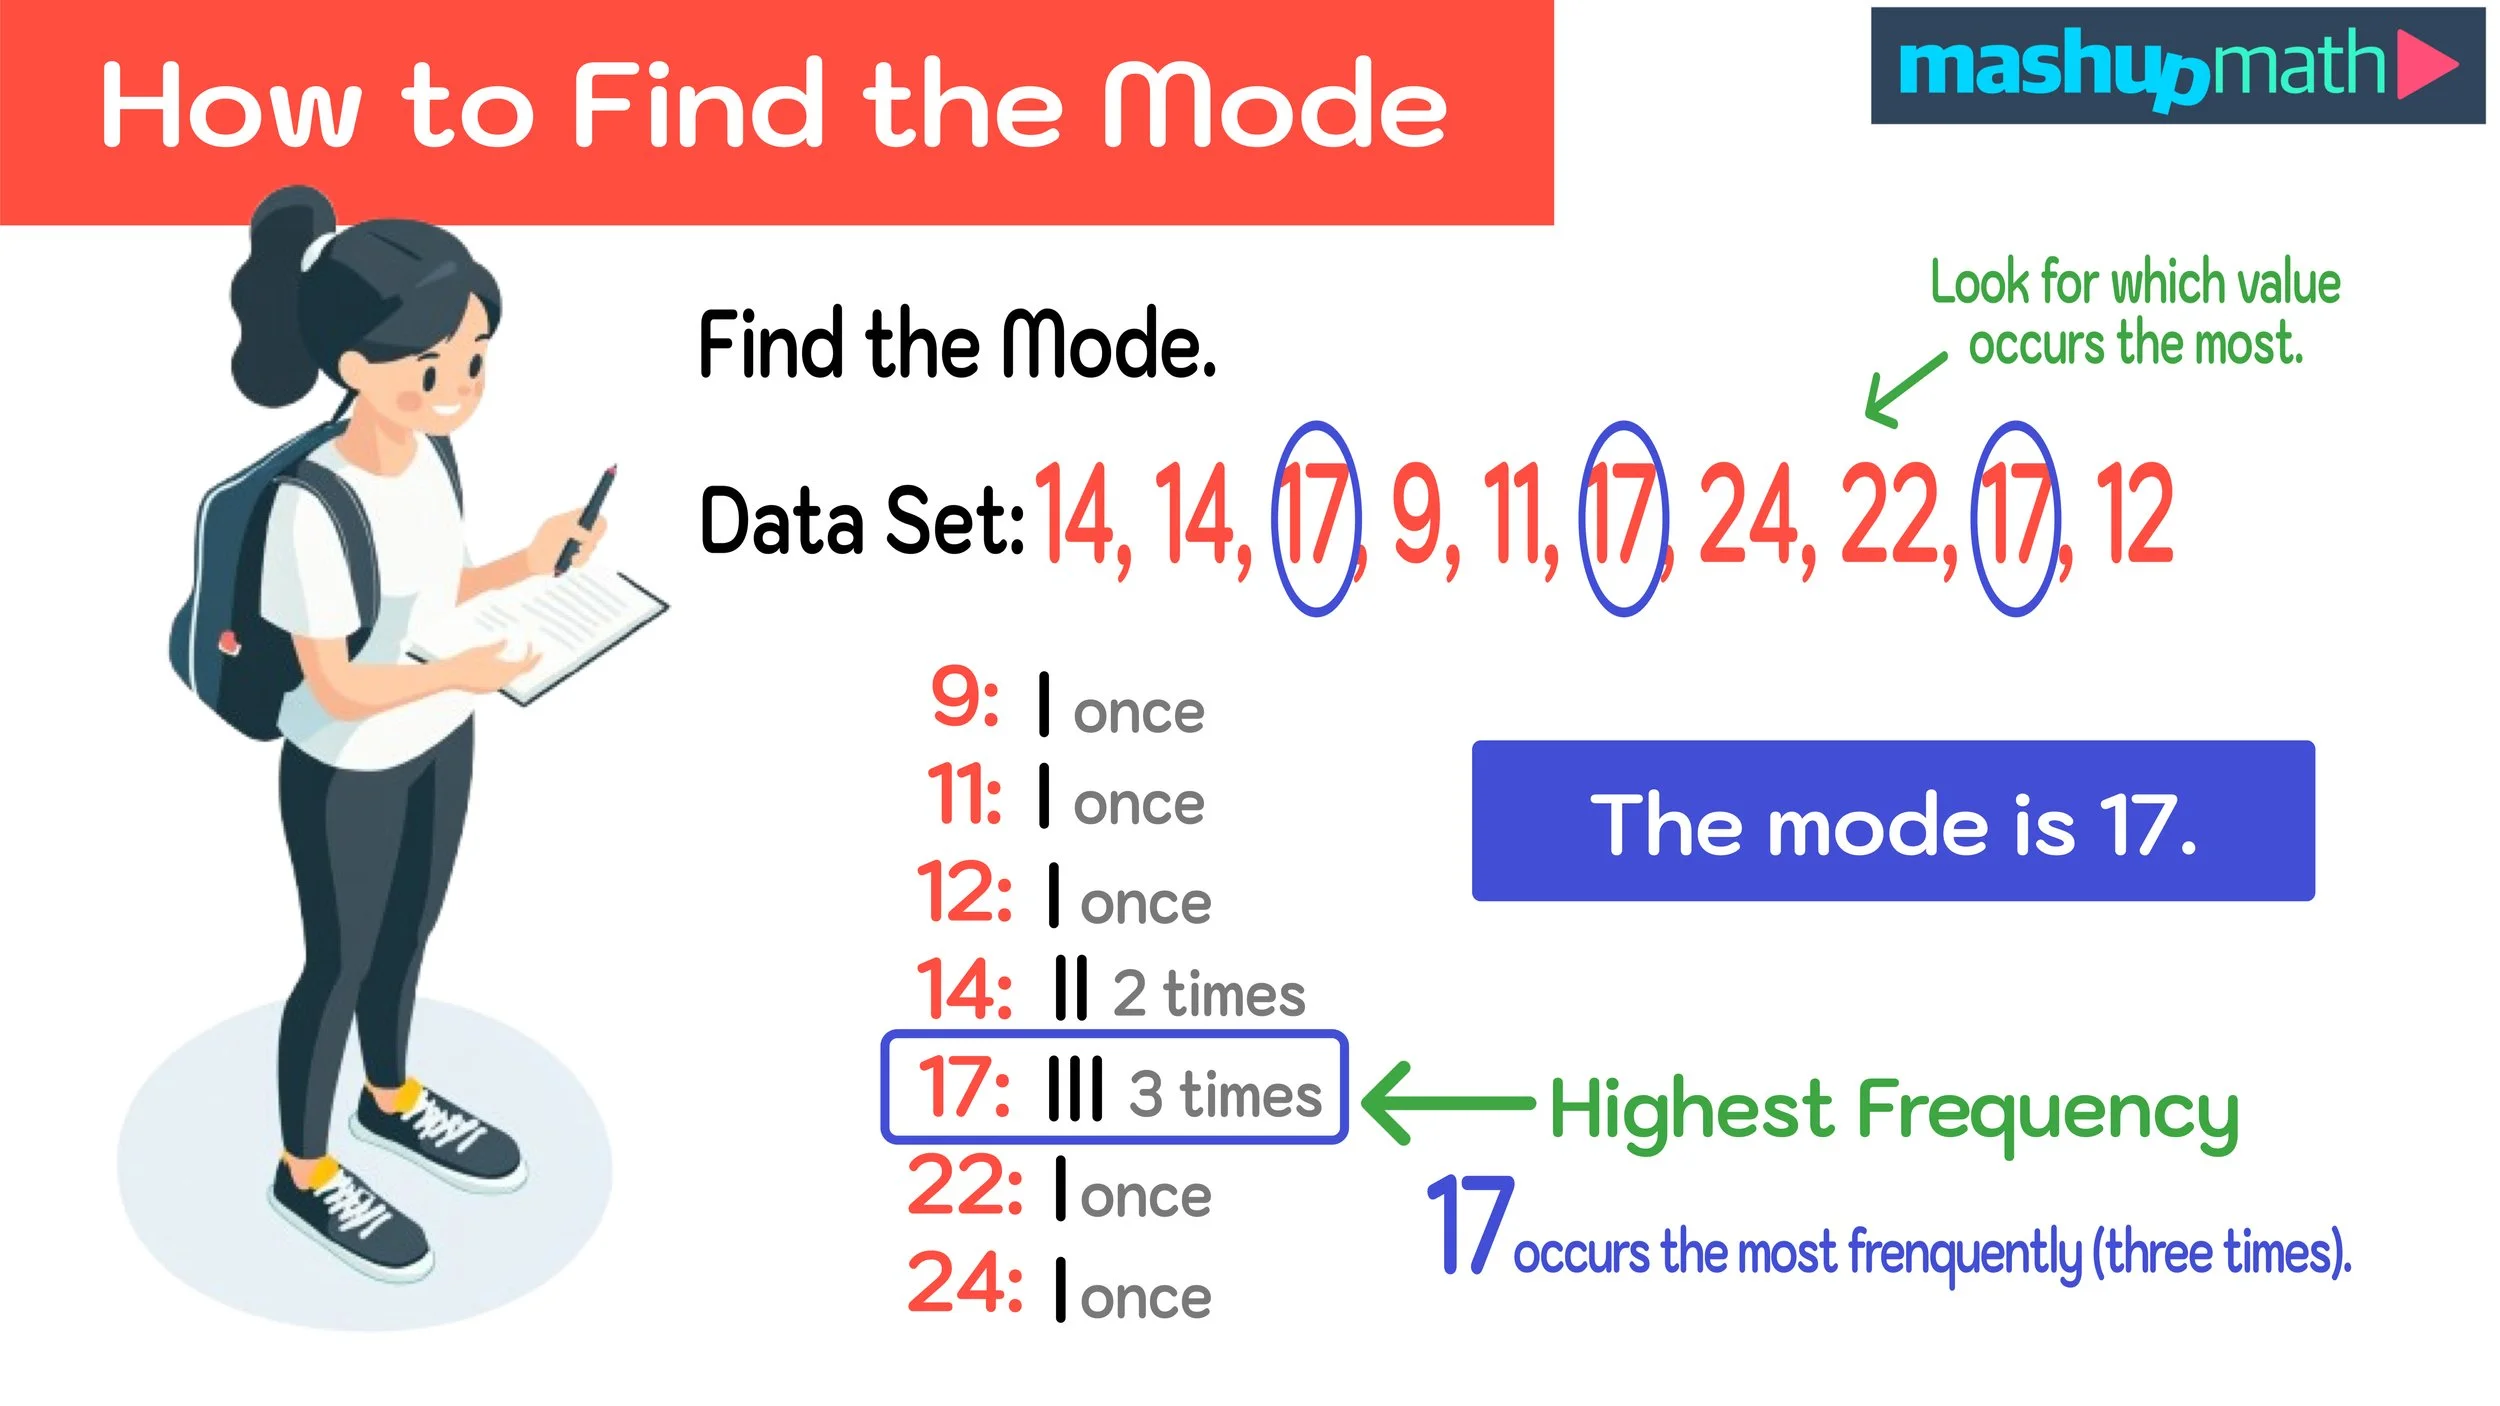
It's the most frequent value in a dataset. That's it. You count how often each number shows up, and whichever one appears the most is your mode. People tend to overcomplicate this because they're used to dealing with mean and median, which require actual arithmetic. The mode doesn't need you to add anything together. You just tally and compare. Here's the practical way to find it without getting tripped up. Take a list like 3, 7, 7, 9, 12, 7, 15. Go through it once and note each unique value. Three shows up once. Seven shows up three times. Nine shows up once. Twelve shows up once. Fifteen shows up once. Seven is your mode. Done. Now let's say you have 4, 4, 6, 6, 8, 8. Every value appears exactly twice. There's no single most frequent number. This dataset is multimodal, specifically trimodal. Some teachers will tell you there's no mode here, which is technically wrong. The correct answer is that there are three modes. This is where people lose points on tests because they've only ever seen single-mode examples in their textbooks.
For larger datasets, like a list of 200 survey responses on a 1-to-10 scale, you don't do this by hand unless you enjoy pain. You group the values into a frequency table. Column A is the possible response values. Column B is how many times each appeared. Scan column B for the highest number and look across to column A. That's your mode. Takes about three minutes on paper, thirty seconds in a spreadsheet. One thing beginners consistently mess up is confusing mode with maximum. They see the biggest number in a dataset and assume that's the mode. If your data is 2, 5, 5, 8, 100, the mode is five, not one hundred. One hundred is the outlier or the maximum. They're completely different concepts. I've corrected this mistake probably a hundred times across different forums and tutoring sessions.
When Mode Is Actually Useful
People ask why you'd ever use mode when mean gives you more information. The answer is categorical data. You can't calculate a meaningful mean for shoe sizes sold at a store if you treat them as numbers, unless you're doing something very specific. But mode tells you immediately which size moves the most units. That's operational intelligence. Retailers use this daily. Similarly, mode works with non-numeric data. Ask people what their favorite color is. Red, blue, blue, green, blue, yellow. The mode is blue. You can't average that. Mean and median require ordered numerical data. Mode just needs counts. I ran into a particularly annoying edge case a while back working with a dataset of customer support ticket categories. The data was text-based: billing, technical, account, technical, technical, billing, closing, technical, and so on, roughly four thousand entries. Standard spreadsheet tools don't have a built-in mode function for text. Excel's MODE function only handles numbers. I ended up writing a simple pivot table grouping all the text categories and counting occurrences, then sorting descending. The mode category was technical at about thirty-eight percent of all tickets. Without that, I would've been manually scanning four thousand rows for fun. It took maybe twenty minutes total.
Get the Full Details

Pitfalls and What Mode Won't Do For You
The biggest limitation is that mode ignores the distribution entirely. A dataset of 1, 1, 1, 1, 1, 100 has a mode of one, but that mode completely misrepresents the spread. You'd be making decisions based on a single repeated value while ignoring that one data point is wildly different. Always pair mode with a measure of spread like range or standard deviation if you're doing anything serious with the data. Another issue is flat distributions. In a uniform dataset where every value appears the same number of times, mode is useless. It gives you no information. If you're analyzing exam scores and every score from 0 to 100 appears exactly once, the mode tells you nothing actionable. In those cases, mean or median is more informative, or you should look at percentiles instead. Bimodal distributions are also tricky. If your data has two clear peaks, reporting a single mode obscures the reality. You might have two distinct customer segments, for example, and the mode would just give you one of them depending on which peak is slightly higher. In that scenario, you'd be better off splitting the data and analyzing each group separately rather than forcing a single mode interpretation.
There's also a common misconception that mode is the "middle" value. It's not. Median is the middle value when data is ordered. Mode is simply the most common value. They can coincide, but they measure fundamentally different things. Confusing them is a basic error that shows up in introductory stats courses constantly.
Quick Reference for Common Scenarios
Single mode: one value appears most frequently. Straightforward. Multimodal: two or more values tie for highest frequency. Report all of them. No mode: all values appear equally. Say so explicitly rather than claiming one exists. Continuous data: mode becomes less useful because exact duplicates are rare. You'd need to bin or group the data first, which introduces its own arbitrariness around where you draw the class boundaries. The takeaway is that mode is a specific tool for a specific job. It's not the default measure of central tendency. It's the one you reach for when you have categorical data, when you need to know the most typical case quickly, or when the average would be misleading due to outliers. Use it appropriately and it's fine. Try to make it do work it wasn't designed for and you'll get bad results.