What actually happens when you keep taking samples
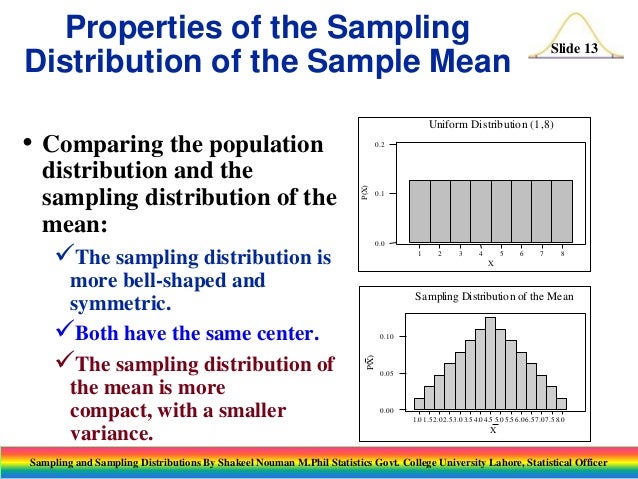
I spent three weeks last year debugging a production anomaly that turned out to be nothing more than someone misapplying the central limit theorem to a distribution with infinite variance. Their sample means weren't converging to anything normal because Cauchy distributions don't cooperate with CLT assumptions. That kind of thing makes you pay close attention to what the sampling distribution actually is before you start building pipelines on top of it. A sampling distribution is simply the probability distribution of a statistic calculated from repeated random samples drawn from a population. The sampling distribution of the mean specifically tracks what happens to the sample average when you repeatedly draw samples of a fixed size n from the same population and compute the mean each time. It is not the distribution of the population itself. It is not the distribution of individual observations. It is the distribution of the means.
How to Define The Sampling Distribution Of The Mean in practice
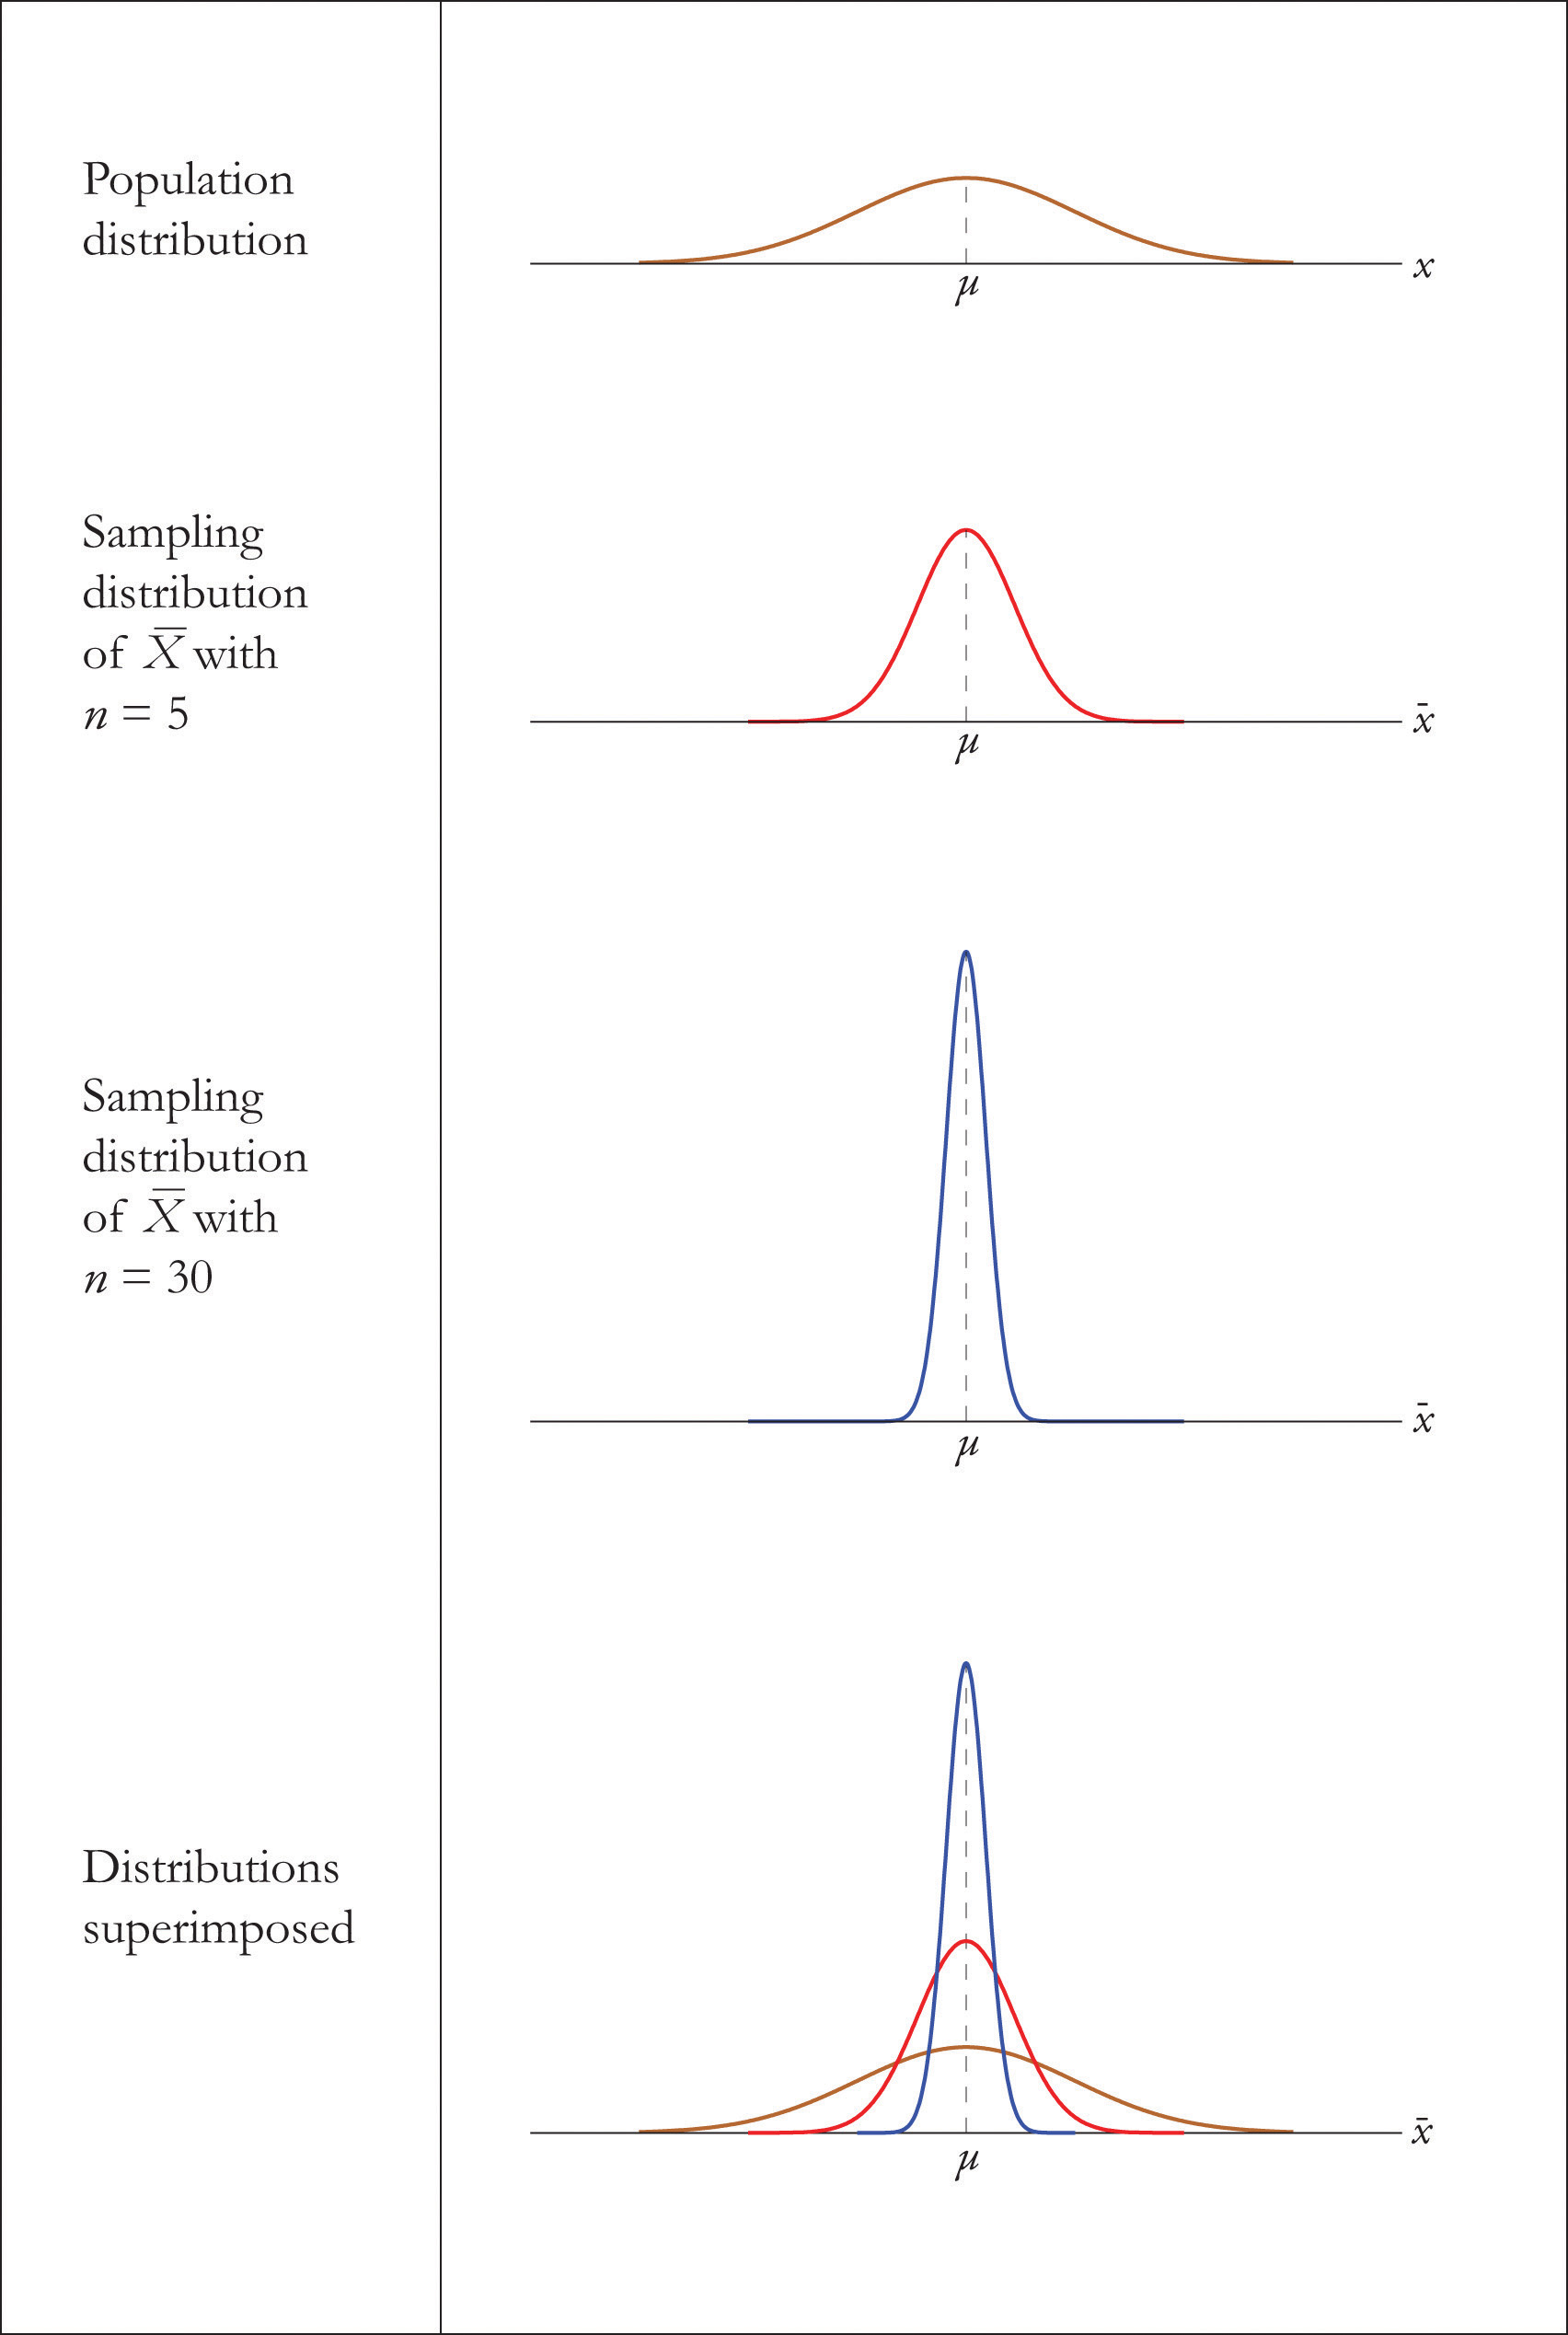
The mechanics are straightforward enough on paper. Take a population with mean mu and standard deviation sigma. Draw samples of size n. Compute each sample mean. Collect those means. Plot them. What you get is approximately normal with mean equal to mu and standard error equal to sigma divided by the square root of n, provided n is large enough and the population isn't pathological. The standard error shrinks as your sample size grows. That is the single most important practical takeaway. Going from n equals 25 to n equals 100 cuts the standard error in half, not quarters. People confuse the relationship because they think sample size affects variance linearly when it actually affects the standard deviation of the sampling distribution through a square root scaling. That detail matters when you are doing power calculations or planning how many observations you actually need to detect a given effect size. I ran into a real issue once where we were aggregating revenue per transaction across regional warehouses. The underlying population was heavily right-skewed with a long tail of outlier orders. Our sample size was forty per region, which theoretically should have been enough for CLT to kick in. The sampling distribution looked normal in a histogram, yes, but the tails were still too fat for the confidence intervals we were computing. Standard error formulas gave us tighter bounds than the data actually supported. The workaround was switching to a bootstrap-based estimation of the sampling distribution instead of relying on the analytic normal approximation. Bootstrapping the means forty thousand times gave us empirical percentiles that reflected the true spread, and our interval estimates finally matched out-of-sample validation. Took about an extra hour of compute but saved us from shipping incorrect margin forecasts.
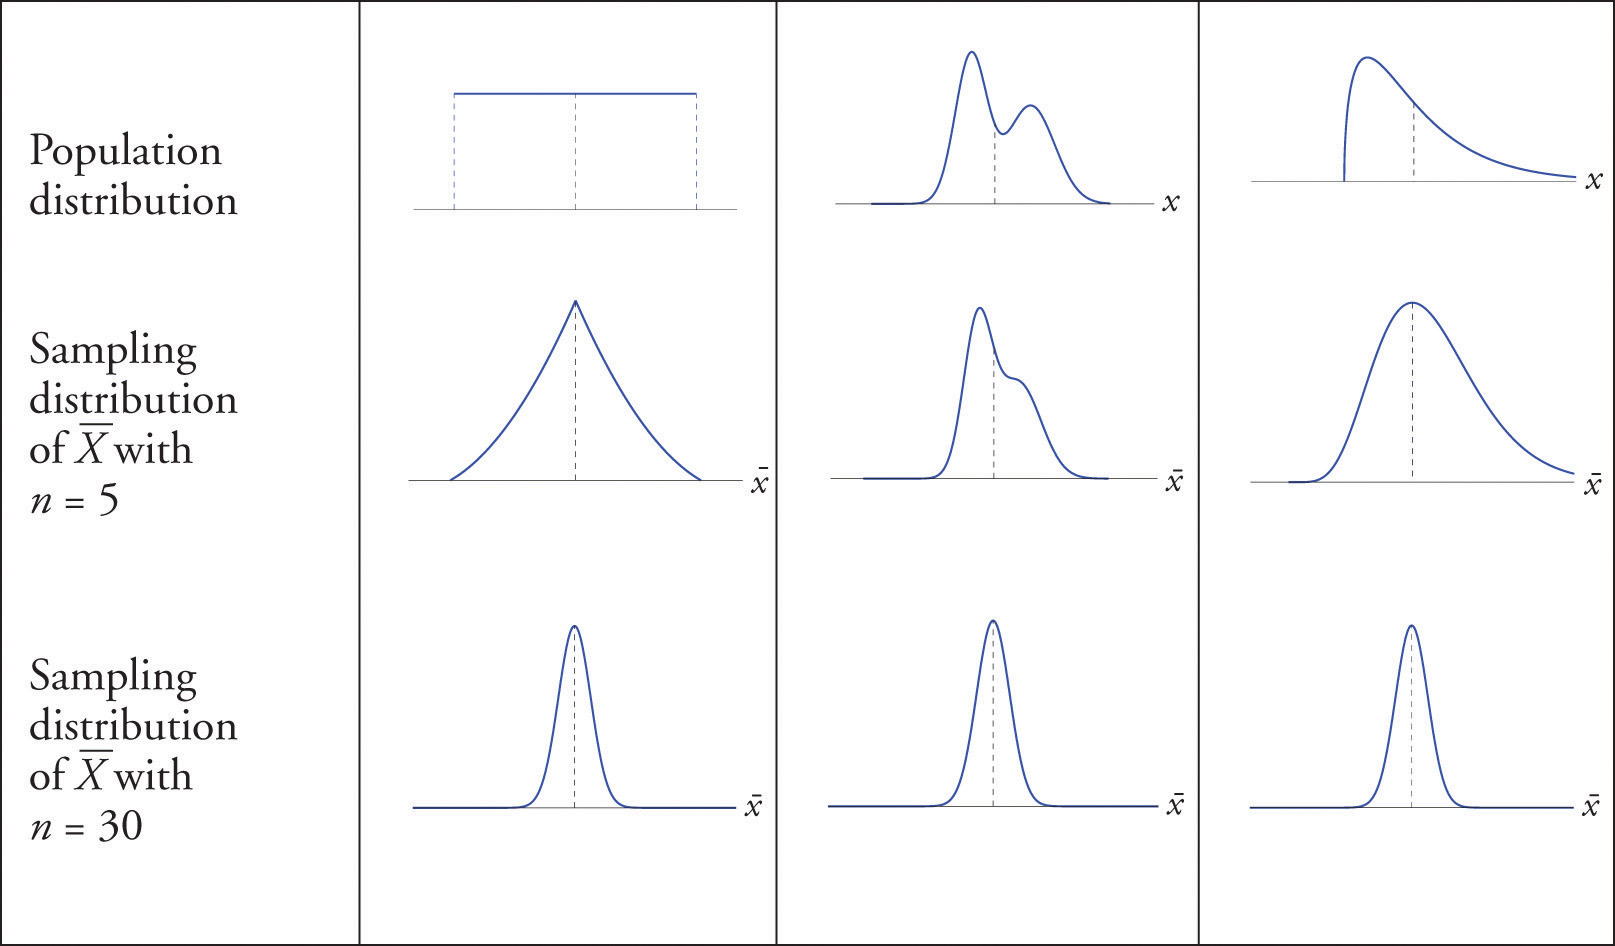
Here is something most introductory courses gloss over. The sampling distribution of the mean is centered at the population mean regardless of the population shape. That is true even for bimodal or uniform populations. But the rate at which it becomes normal depends heavily on the population's skew and kurtosis. A uniform population with moderate skew reaches near-normality around n equals thirty. A strongly skewed exponential distribution might need n equals fifty or sixty before the approximation is reliable for hypothesis testing. And if your population has heavy tails, like a Pareto with shape parameter below two, the variance is undefined and the whole framework breaks down before you even get started. Another common blind spot involves independence. The standard formulas assume sampling with replacement or a population large enough that sampling without replacement doesn't meaningfully change the composition. When your sample exceeds five percent of the population, you need the finite population correction factor. I have seen analysts skip this entirely when working with small geographic cohorts, which inflated their standard errors by roughly ten to fifteen percent and produced misleadingly wide confidence intervals. The correction multiplies the standard error by the square root of one minus n over N, where N is the population size. It is a small adjustment but it shifts conclusions when you are working with tight margins. If you are implementing this yourself rather than running it through a statistical package, the computational path is simple enough that you can write a clean loop in Python or R. Generate your population data, sample with replacement repeatedly, store the means, and then inspect the resulting distribution against the theoretical normal curve. Visual inspection alone will surface issues like skew or heavy tails that a textbook example never shows you. I usually plot the sampled means alongside a normal density curve using the theoretical standard error on top of the actual data to see where they diverge.
Get the Full Details
The biggest limitation of relying on the sampling distribution of the mean is that it tells you nothing about individual variation within your samples. Two populations can share the same mean and the same sampling distribution of the means at a given sample size, yet be completely different underneath. One could be tightly clustered around the mean while the other is wildly dispersed. If your decision-making depends on understanding the spread of individual outcomes rather than the precision of the estimated mean, the sampling distribution alone will mislead you. In those cases you need to examine the full distribution of the raw data or use methods like prediction intervals instead of confidence intervals for the mean. Also worth noting, the central limit theorem approximation is asymptotic. It gets better with larger n but there is no universal threshold that applies to every population. Thirty is a heuristic, not a law. For business data, which is rarely well-behaved, I tend to treat it as a minimum floor and verify with simulation before trusting the normal approximation for any inference that affects real money.