Range isn't what most people think it is at first
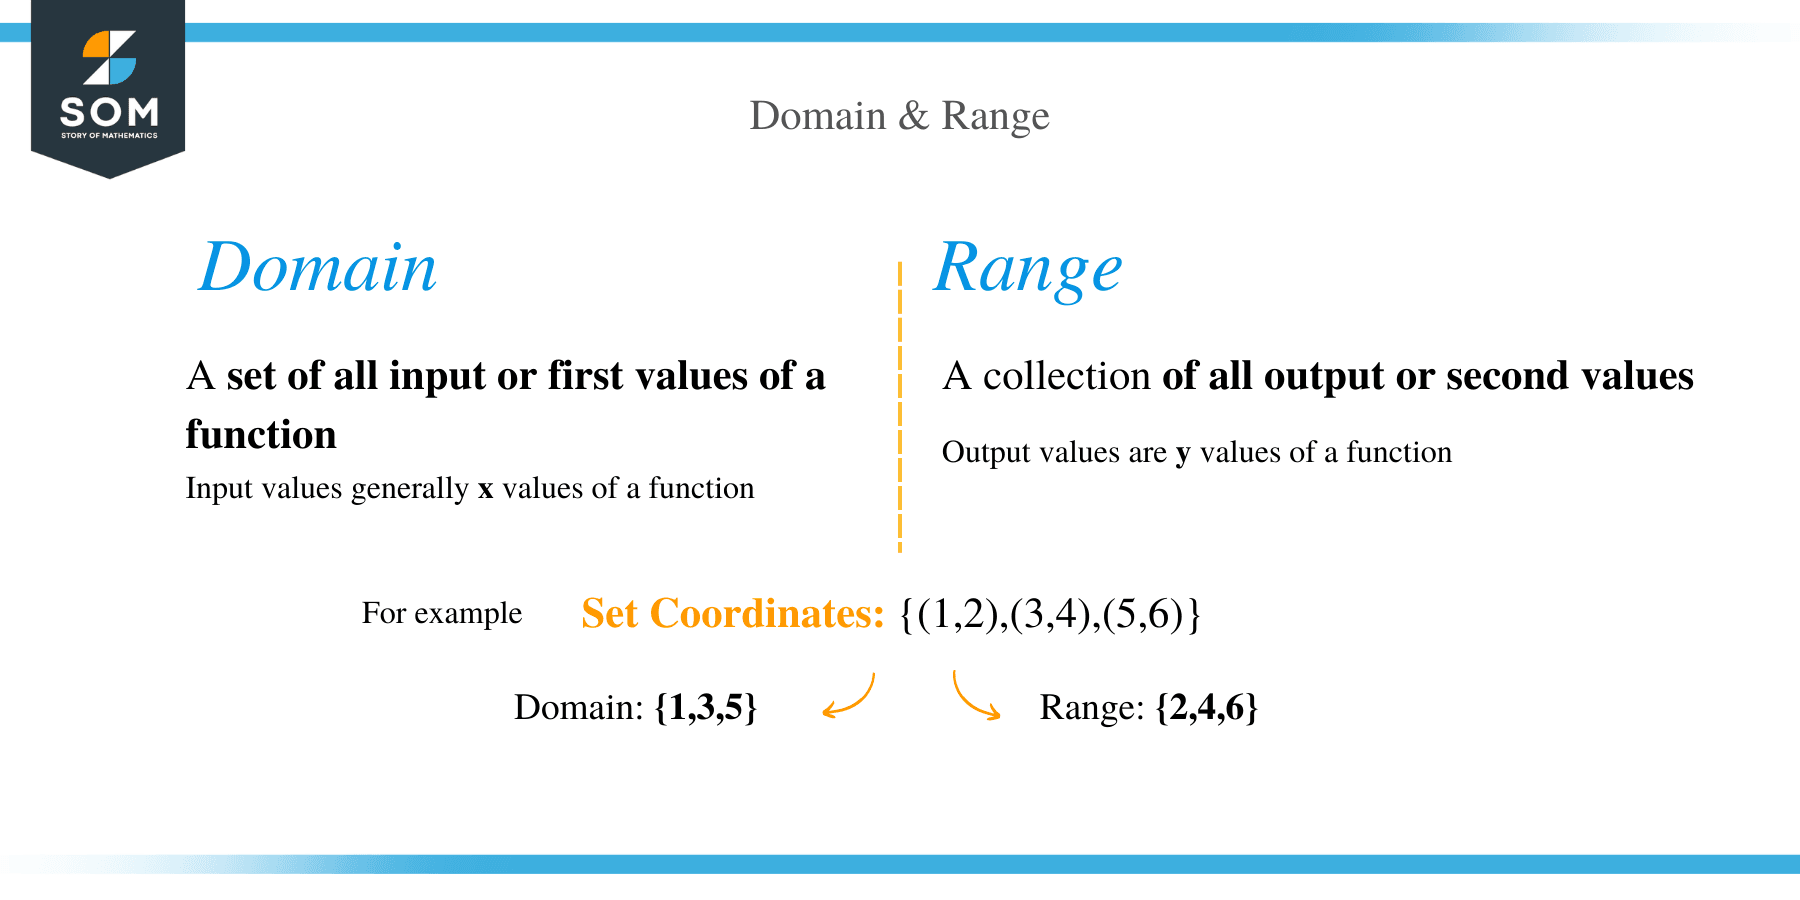
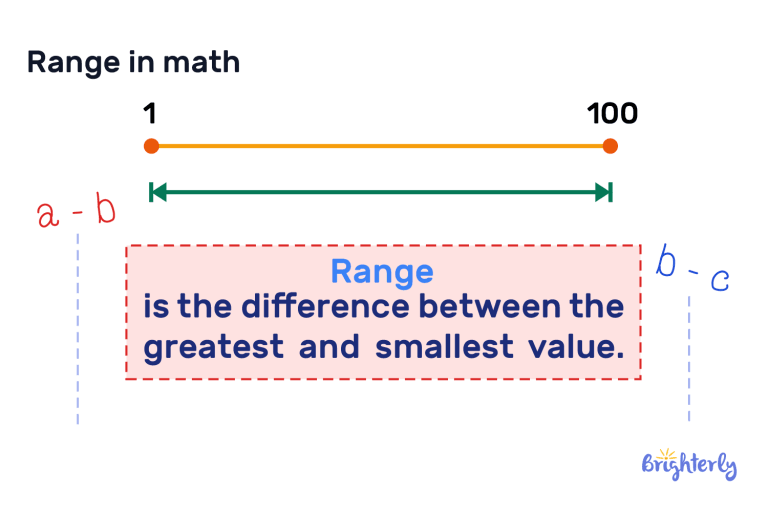
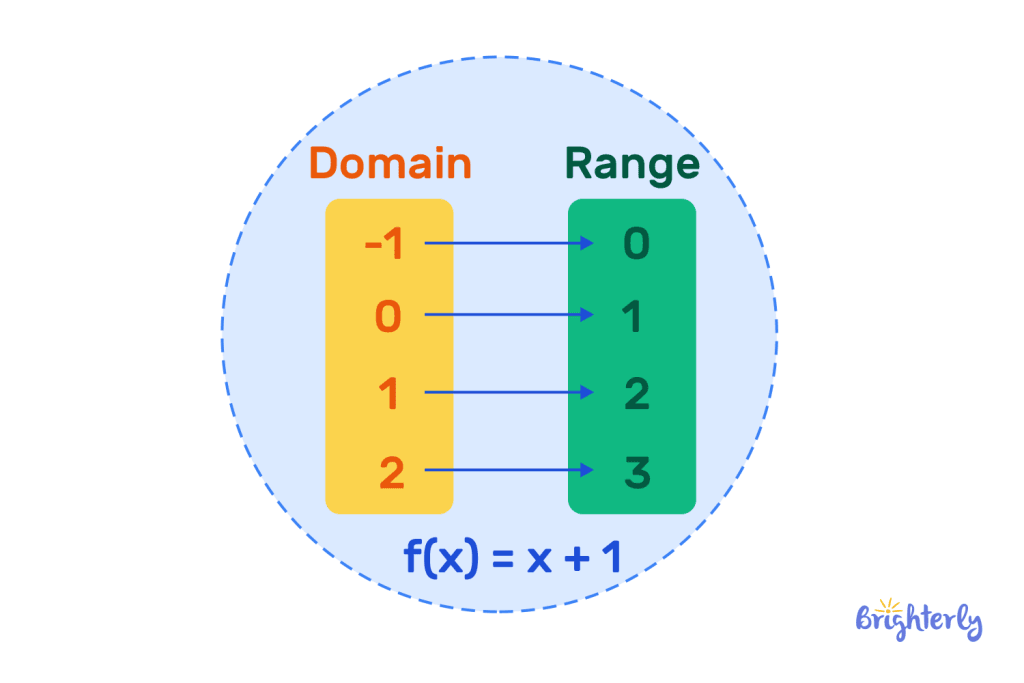
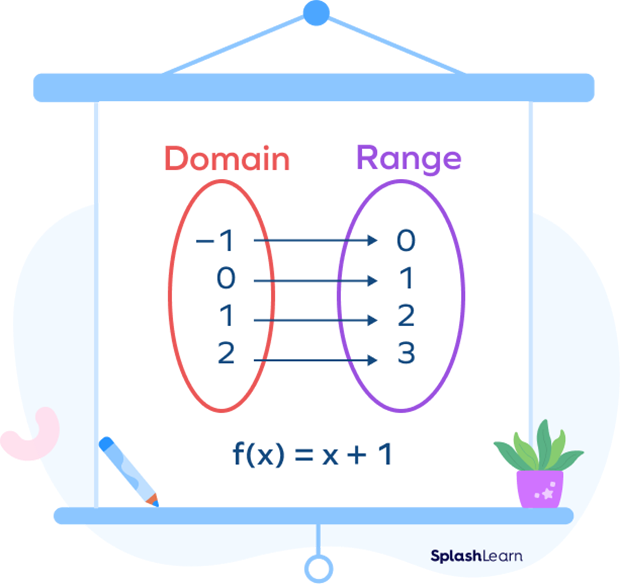
When I first learned range in school, I thought it was just the difference between the highest and lowest numbers in a set. That's the descriptive definition, sure, but it's barely enough for anything beyond middle school homework. The functional definition — the set of all output values a function actually produces — is where things get messy, and also where you'll run into actual problems. Range is the collection of every possible result that comes out of a function when you feed it every allowable input. Domain is the inputs. Range is the outputs. That's the core distinction that trips people up less than you'd think. The real difficulty isn't memorizing that — it's figuring out the range when the function itself isn't cooperative. I've spent years watching students and even professionals fumble this because they treat range as something you eyeball. You can't eyeball it reliably for anything beyond linear functions and simple quadratics. Here's how you actually compute it in practice.
For polynomial functions, the approach depends entirely on the degree. A linear function like f(x) = 3x + 7 has a range of all real numbers, period. There's no restriction. A quadratic like f(x) = x² - 4x + 3 requires you to find the vertex first. The vertex occurs at x = -b/(2a), which gives x = 2 in this case. Plug it back in and you get f(2) = -1. Since the parabola opens upward, the range is [-1, ). If it opened downward, you'd flip that to (-, -1]. That's straightforward, but it's also the easy case. Rational functions are where people start making mistakes. Take f(x) = 1/(x - 2). The domain excludes x = 2 because of division by zero. The range, though, is all real numbers except y = 0. This is counter-intuitive for most people because they focus so hard on the domain restriction that they forget to check whether any output value is actually unreachable. The horizontal asymptote at y = 0 tells you exactly what to exclude from the range. Radical functions need a different lens. For f(x) = (x - 3), the domain starts at x = 3, and the range is [0, ). The square root never produces a negative output by convention, so negative y-values simply don't exist for this function. But if you have f(x) = -(x + 1) + 5, the range flips to (-, 5]. The negative sign in front of the radical inverts everything, and the +5 shifts the ceiling.
Exponential functions follow a pattern that's easy to miss if you're rushing. For f(x) = 2^x, the range is (0, ). The function never touches or crosses y = 0, no matter how large or small x gets. Add a vertical shift like f(x) = 2^x - 3 and the range becomes (-3, ). The horizontal asymptote moves down with the shift. This rule holds for any exponential of the form f(x) = a·b^(x-h) + k — the range is always bounded by that k value, open-ended on whichever side the exponential growth directs.
Get the Full Details
How I actually determine range under pressure
In my work, I don't derive ranges from scratch every time. I use a combination of algebraic analysis and boundary checking, and I've developed a system that cuts the process down significantly. Here's the method I rely on. Step one is identifying the function type. Linear, quadratic, rational, radical, exponential, trigonometric — each category has its own playbook. You waste a lot of time if you try to force a rational function method onto an exponential one. Step two is analyzing restrictions. Domain restrictions often mirror range restrictions in predictable ways. If x = 5 is excluded from the domain of a rational function, there's usually a horizontal asymptote or a hole that corresponds to a specific y-value excluded from the range.
Step three is solving for the inverse where possible. This is the most powerful technique and the one most people don't use because they find it tedious. If you can algebraically solve y = f(x) for x in terms of y, then the domain of the inverse function gives you the range of the original. Take f(x) = (2x + 1)/(x - 3). Set y = (2x + 1)/(x - 3), cross-multiply to get y(x - 3) = 2x + 1, expand to yx - 3y = 2x + 1, collect x terms to get x(y - 2) = 3y + 1, and solve for x to get x = (3y + 1)/(y - 2). The inverse has a restriction at y = 2, which means the original function's range excludes y = 2. This method works for any function where you can isolate x algebraically. Step four is checking boundary behavior. What happens as x approaches positive infinity? Negative infinity? Any vertical asymptotes? These limits tell you where the function's outputs head, and that directly maps to the range boundaries.
A specific problem I ran into that broke my usual workflow
Something unusual came up recently with a composite function involving both a rational expression and a square root: f(x) = ((x + 1)/(x - 4)). My standard approaches kept giving me incomplete answers because the interaction between the radical and the rational expression created constraints I wasn't accounting for properly. The algebraic inverse method failed here because solving y = ((x + 1)/(x - 4)) for x introduces a squared term that creates extraneous solutions. The boundary analysis alone missed the fact that the expression inside the radical must be non-negative, which creates a compound inequality. The domain isn't just x 4 — it's x -1 or x > 4, because the rational expression (x + 1)/(x - 4) needs to be 0. Once I mapped out the domain correctly, I evaluated the function at the boundary points and at test values in each interval. At x = -1, f(-1) = 0. As x approaches 4 from the right, the function grows without bound. As x approaches negative infinity, the ratio (x + 1)/(x - 4) approaches 1, so the function approaches 1 = 1. But since x can go all the way to -1 and the function is continuous on (-, -1], it actually takes on every value between 0 and 1 inclusive, plus all values greater than 1 from the (4, ) branch. The range turned out to be [0, ). The key insight was that the horizontal asymptote at y = 1 didn't create a gap — the left branch of the domain covered everything below it while the right branch covered everything above. I learned to always sketch the function after doing the algebra rather than trusting the algebra alone. The sketch caught the continuity I'd overlooked.
Common traps that waste serious time
People confuse range with codomain constantly. In formal mathematics, the codomain is the set you declare the function maps into, while the range is the actual subset of the codomain that gets hit. In most applied contexts, these are treated as the same thing, but in higher-level courses and rigorous proofs, the distinction matters and mixing them up will cost you points or worse, correct conclusions in research. Another trap is assuming that finding the domain automatically gives you the range. They're related but not identical. A function can have a domain of all real numbers and a range that's only positive reals, like the exponential example above. Don't shortcut this step. Trigonometric functions deserve special attention because their ranges are bounded in ways that feel arbitrary if you haven't seen them enough. Sine and cosine both have ranges of [-1, 1]. Tangent has a range of all real numbers, which surprises people who see the asymptotes and assume there are gaps. There aren't. The function covers every real y-value between its asymptotes. Secant, cosecant, and cotangent have their own constraints that you should memorize rather than derive each time.
Piecewise functions are perhaps the most common source of errors. Each piece has its own range, and the overall range is the union of all piece ranges, but only considering the portion of each piece that falls within its specified domain. I've seen people take the full range of each algebraic piece regardless of the domain restriction, which inflates the answer. Always constrain each piece to its actual domain before combining.
What range calculations can't do for you
Range analysis breaks down completely for functions defined only numerically or through black-box simulations. If you're working with empirical data, simulation outputs, or functions given as lookup tables, there's no algebraic way to determine the range. You need to scan the data, and even then you might miss narrow intervals if your sampling is coarse. In those situations, the best approach is dense numerical sampling combined with optimization routines, and even that isn't guaranteed to find every local extremum. High-degree polynomials also resist clean analytical range determination. A fifth-degree polynomial can have up to four turning points, and solving for each one requires finding the roots of its derivative, which is itself a fourth-degree polynomial. There's no general formula for roots above degree four, so you're stuck with numerical approximation methods. The range will be all real numbers for odd-degree polynomials with positive leading coefficient, but confirming that rigorously involves limit analysis that most people skip. If range determination is central to your work — say you're doing optimization or control theory — and you're dealing with complicated functions repeatedly, symbolic computation tools like SymPy or Wolfram Alpha will save you hours. They handle the algebraic manipulation and boundary analysis faster and more accurately than manual computation. The trade-off is that you lose visibility into why the answer is what it is, which matters when you're teaching or defending your work to someone who asks for derivation steps.
The definition itself is simple. Applying it reliably to anything beyond textbook examples is where the actual work begins. Most of the difficulty isn't in the concept — it's in recognizing which tool applies to which function type and executing the algebra without introducing extraneous solutions or missing boundary conditions. That comes from doing enough problems that the patterns stop feeling arbitrary.