Actuarial Science Is Just Applied Probability With Billions of Dollars on the Line
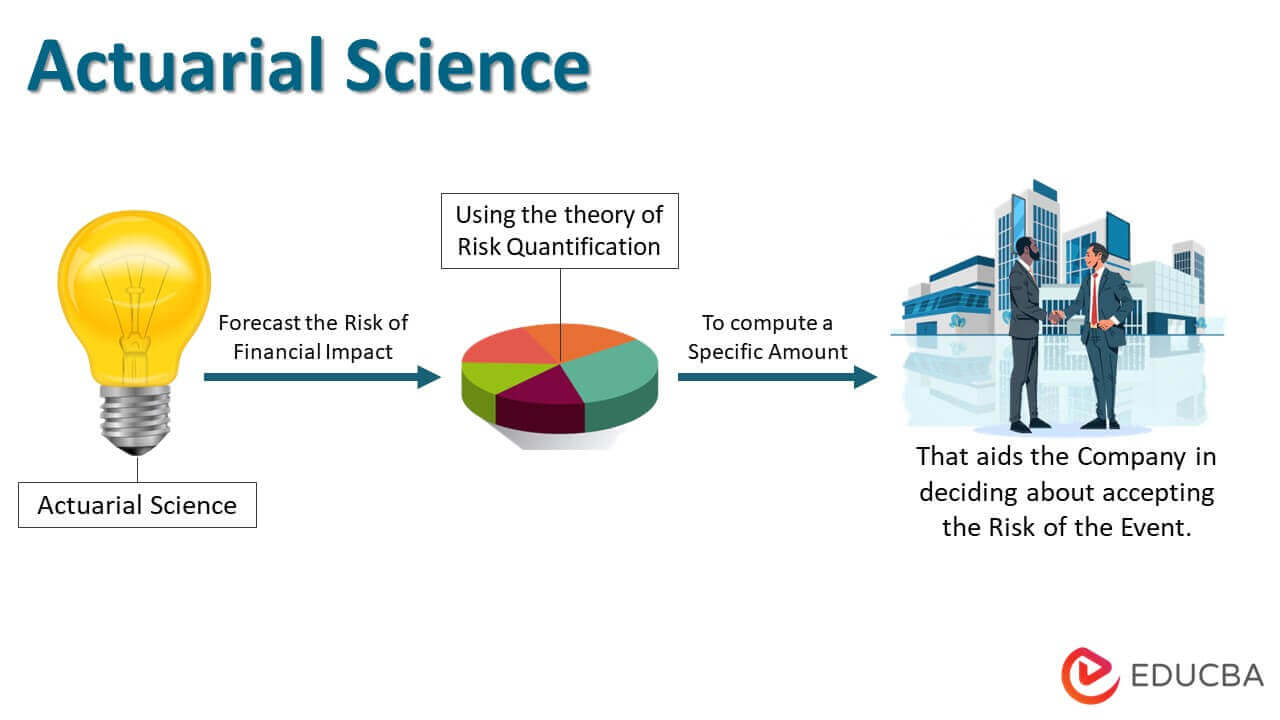
Most people hear the word and picture a stuffy professional crunching numbers in a suit. That is half right. The rest is understanding human behavior at scale. When I first sat in on a reserving meeting for a major property casualty writer, the actuary didn't even look up from his screen. He just said the loss ratio was drifting because the IBNR development factors had shifted three months out. Nobody questioned him. That is the job. You build models that predict how much money a company will need to pay future claims, and then you answer to regulators about whether you got it right. The formal definition comes out to something like the discipline that quantifies risk using mathematics, statistics, and financial theory to assess uncertainty in insurance, finance, and other industries. That is accurate. It is also about as exciting as a spreadsheet dependency chart. The practical definition is simpler: actuarial science is the practice of taking messy real-world data, fitting probability models to it, and converting those models into dollar reserves, premiums, and capital requirements that keep companies solvent. You are not predicting what will happen to any single person. You are predicting what will happen to a million people. The law of large numbers does the heavy lifting. Your job is making sure the inputs are not garbage. I spent most of my early career in health insurance reserving. One project stands out because it broke three assumptions I had grown comfortable with. We were running a chain-ladder development on a workers' comp block, and the tail factor kept spiking every time we added a new accident year. The model said reserves needed to grow by eighteen percent. The underwriters said that was impossible because rates had been raised twelve months prior. Neither side was wrong. The issue was a claim severity trend that had quietly accelerated due to a change in medical treatment protocols at three large hospital networks in the Southeast. Standard development factors assumed linear severity growth. The data was curving. I ended up pulling individual claim records, flagging claims from those networks, and building a separate severity curve just for that subset. It took about forty hours of work that no textbook would have flagged as necessary. The final reserve was fifteen percent higher than the original chain-ladder output, and the auditors had no grounds to complain because the adjustment was fully documented and traceable to a specific change in care patterns rather than a modeling whim.
This is where the real work lives. Not in the formulas. In the decisions about which formulas to trust and which to override when reality refuses to cooperate with a clean distribution.
How the Work Actually Happens
Start with data. A lot of it. Claims databases, policyholder exposure records, premium transactions, reinsurance contracts, economic indicators, sometimes demographic tables pulled from government sources. The data is never clean. Columns are missing, dates are formatted inconsistently, and claims get re-opened and closed so often that the audit trail resembles a detective novel. The first step is always cleaning and validating. If you skip this, everything downstream is unreliable. There is no shortcut. Once the data is usable, you pick a model. In life insurance, you might use mortality tables adjusted for improving trends. In property and casualty, you are more likely to run reserving methods like Mack's chain ladder, Bornhuetter-Ferguson, or Cape Cod. In pensions, you look at survival models and discount rates. In each case, you are estimating expected payouts and discounting them to present value. The difference between methods usually comes down to how much you trust prior assumptions versus how much you trust the observed data. Bornhuetter-Ferguson leans on expected loss ratios and is more stable with thin data. Chain ladder relies entirely on observed development patterns and can be volatile when you have few data points. Neither is wrong. They answer different questions. Model validation is where most beginners fail. You fit a model, you get a result, and you feel satisfied. That satisfaction is dangerous. You need to run back-testing, check residuals, compare against alternative methods, and stress the inputs. If your model says reserves should be $42 million but a simpler method gives $38 million and a more complex method gives $45 million, you cannot just pick the middle number and move on. You need to understand why the methods disagree. Usually it is because one method captures a trend the others miss, or one method is being dragged by an outlier development pattern. The actuary who ignores the disagreement gets audited. The actuary who documents it and picks a defensible position keeps their license.
Get the Full Details

Tools and Environment
The industry runs on Excel, which is painful because Excel was never designed for actuarial work, and it shows. Every spreadsheet has a limit. Every circular reference is a time bomb. Every manual copy-paste is an error waiting to happen. Excel persists because it is everywhere and because actuaries are trained to build custom solutions when the standard tools do not fit. Then there is dedicated actuarial software like Prophet, AXIS, Prochain, and MGAL. These are powerful but expensive and rigid. You spend more time learning the software than solving the problem sometimes. Python and R have become standard for data manipulation and certain modeling work. I use Python for data cleaning, statistical testing, and building custom reserving routines. R is still useful for certain credibility theory applications and for generating the kind of plots actuaries like to hand to management. SQL is non-negotiable if you are pulling from large claims databases. Knowing it saves you from begging the IT department to run queries for you, which will cost you three days of delay and at least two coffees you did not need. For documentation and audit readiness, everything must be reproducible. If you ran a model today and someone asked you to rerun it in six months, you should be able to produce the same result without guessing which cell contained the assumption you changed. I keep a version-controlled repository for every significant model. Git is not glamorous. It prevents catastrophic mistakes.
Counter-Intuitive Things Beginners Miss
The first thing is that more data is not always better. Adding recent claims to a reserving model can actually degrade accuracy if those claims are incomplete and still developing. The model may interpret the low paid amounts as a favorable trend when they are just artifacts of incompleteness. This is why development periods matter and why truncating recent years is often the right call. The data looks better with more observations. The model performs worse. The second thing is that your model will rarely be right, and being approximately right is the goal. Actuarial reserves are not predictions. They are estimates with confidence intervals. A good actuary does not produce a single number and claim it is correct. A good actuary produces a range, explains the uncertainty, and recommends a position that satisfies both solvency requirements and business practicality. Regulators do not want precision. They want prudence. The difference matters when you are testifying at an examination. A third thing that trips people up is the gap between pricing and reserving. They use similar methods but answer different questions. Pricing sets the premium before claims are known. Reserving estimates claims after they have started occurring. A price that looks adequate in retrospect may have been set too low because the actuarial assumptions at the time were optimistic. The reserving actuary does not get to blame pricing. They work with what the claims tell them. Similarly, the pricing actuary cannot blame reserving for poor profitability. The two functions feed each other but operate on different information sets. Understanding that tension is part of the job.
Limitations and Where the Discipline Struggles
Actuarial science works well for risks that are frequent, predictable, and independent. Auto insurance, mortality, disability incidence. These are the bread and butter. It works less well for low-frequency high-severity events. Catastrophe modeling exists for this, but the outputs are wide and sensitive to assumptions about climate, construction quality, and exposure growth. The 2020s have been a rough period for catastrophe models everywhere. Hurricanes behaved differently than historical patterns predicted. Wildfire exposure grew faster than models adjusted for it. This is not a failure of the discipline. It is a reminder that the models are built on past data and the past is not a reliable guide when the underlying risk environment is changing. Credit risk and market risk sit outside traditional actuarial scope but have been absorbed into actuarial work through Solvency II frameworks and internal capital models. The math overlaps. The culture does not. Actuaries are trained to think in terms of policyholder obligations. Financial engineers think in terms of trading books and hedge ratios. Mixing the two approaches without respect for the different objectives produces models that look rigorous and mean very little. The biggest bottleneck in the profession is not mathematical. It is data quality and access. Companies hoard data. Systems do not talk to each other. Legacy mainframes hold claims data that requires custom extraction scripts. An actuary who cannot get clean data spends more time building pipelines than doing actuarial work. This is not trivial. It is the difference between spending four hours validating a model and four days writing Python scripts to join three datasets that should have been joined already.

What You Should Actually Do If You Want to Enter This Field
Take the exams. They are difficult and they signal competence. But do not treat exam passage as the destination. It is a threshold. The real learning happens when you apply exam knowledge to messy data and defend your assumptions to someone who has seen every excuse before. Seek out mentors who will critique your work, not praise it. Join a professional society and read the discussion papers. The casual conversation at a local section meeting will teach you more about practical judgment than any textbook chapter. Learn to code properly. Not spreadsheet macros. Proper Python or R with version control, unit tests for critical functions, and clear documentation. The industry is moving in this direction whether you like it or not. Those who adapt early have a significant advantage. Those who cling to Excel-only workflows will find themselves marginalized within five years. And when you encounter a model that does not make sense, trust your instinct and investigate. The answer is almost always in the data. It is not a modeling flaw. It is a data story you have not yet read. I have lost count of the times I thought I had a bad model and turned out to have found a real operational change that the numbers were capturing perfectly. The models were fine. My expectation of what the models should show was wrong.