Working with artificial selection is less glamorous than textbooks make it sound
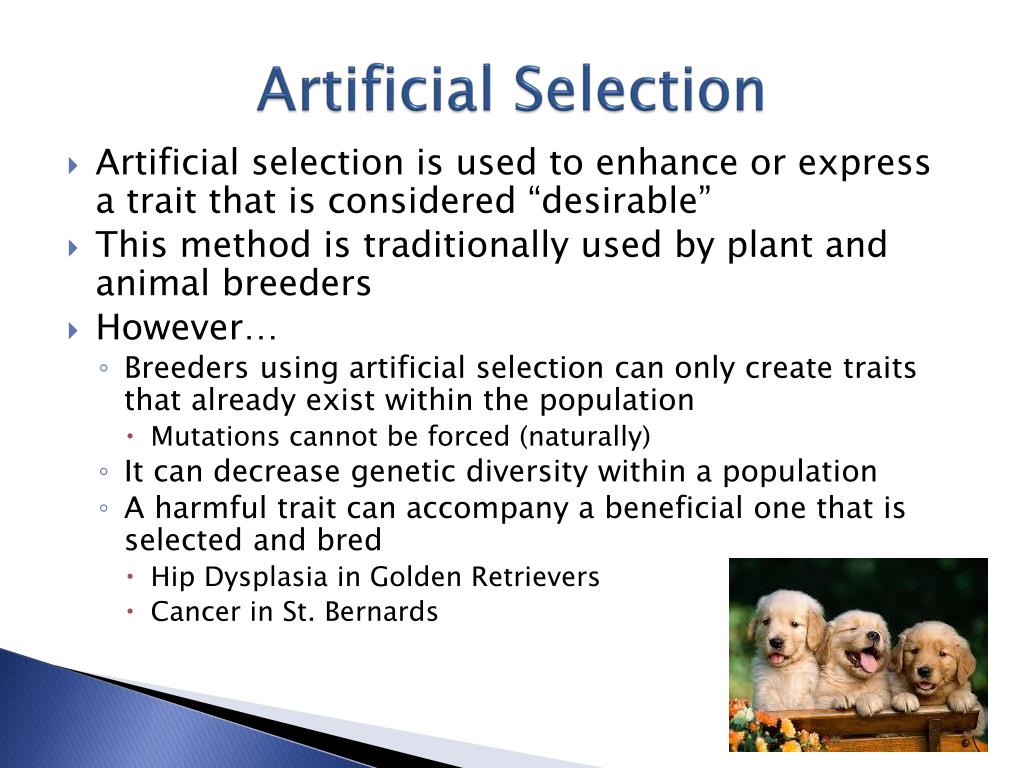
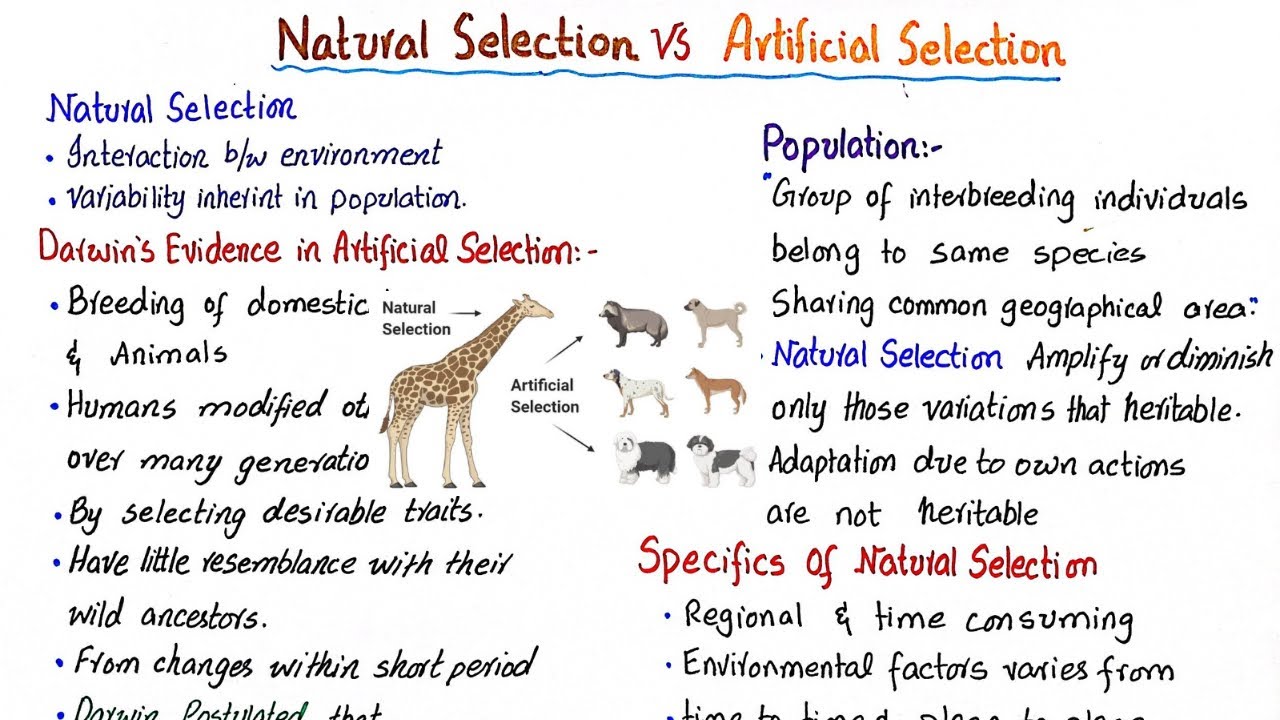
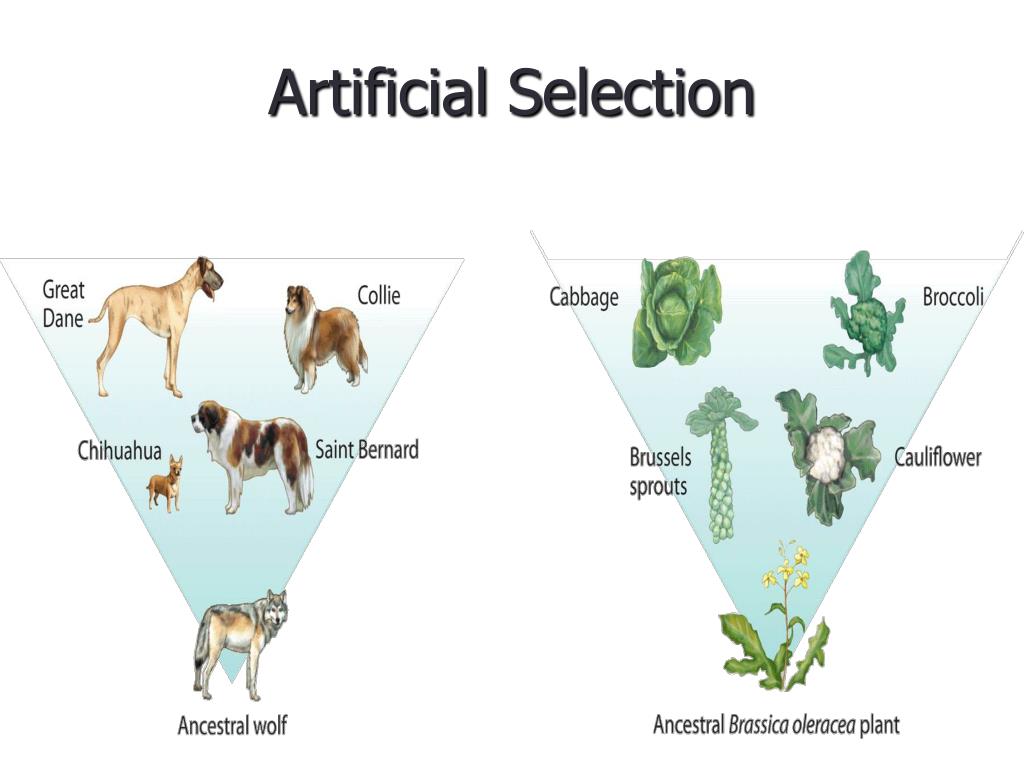
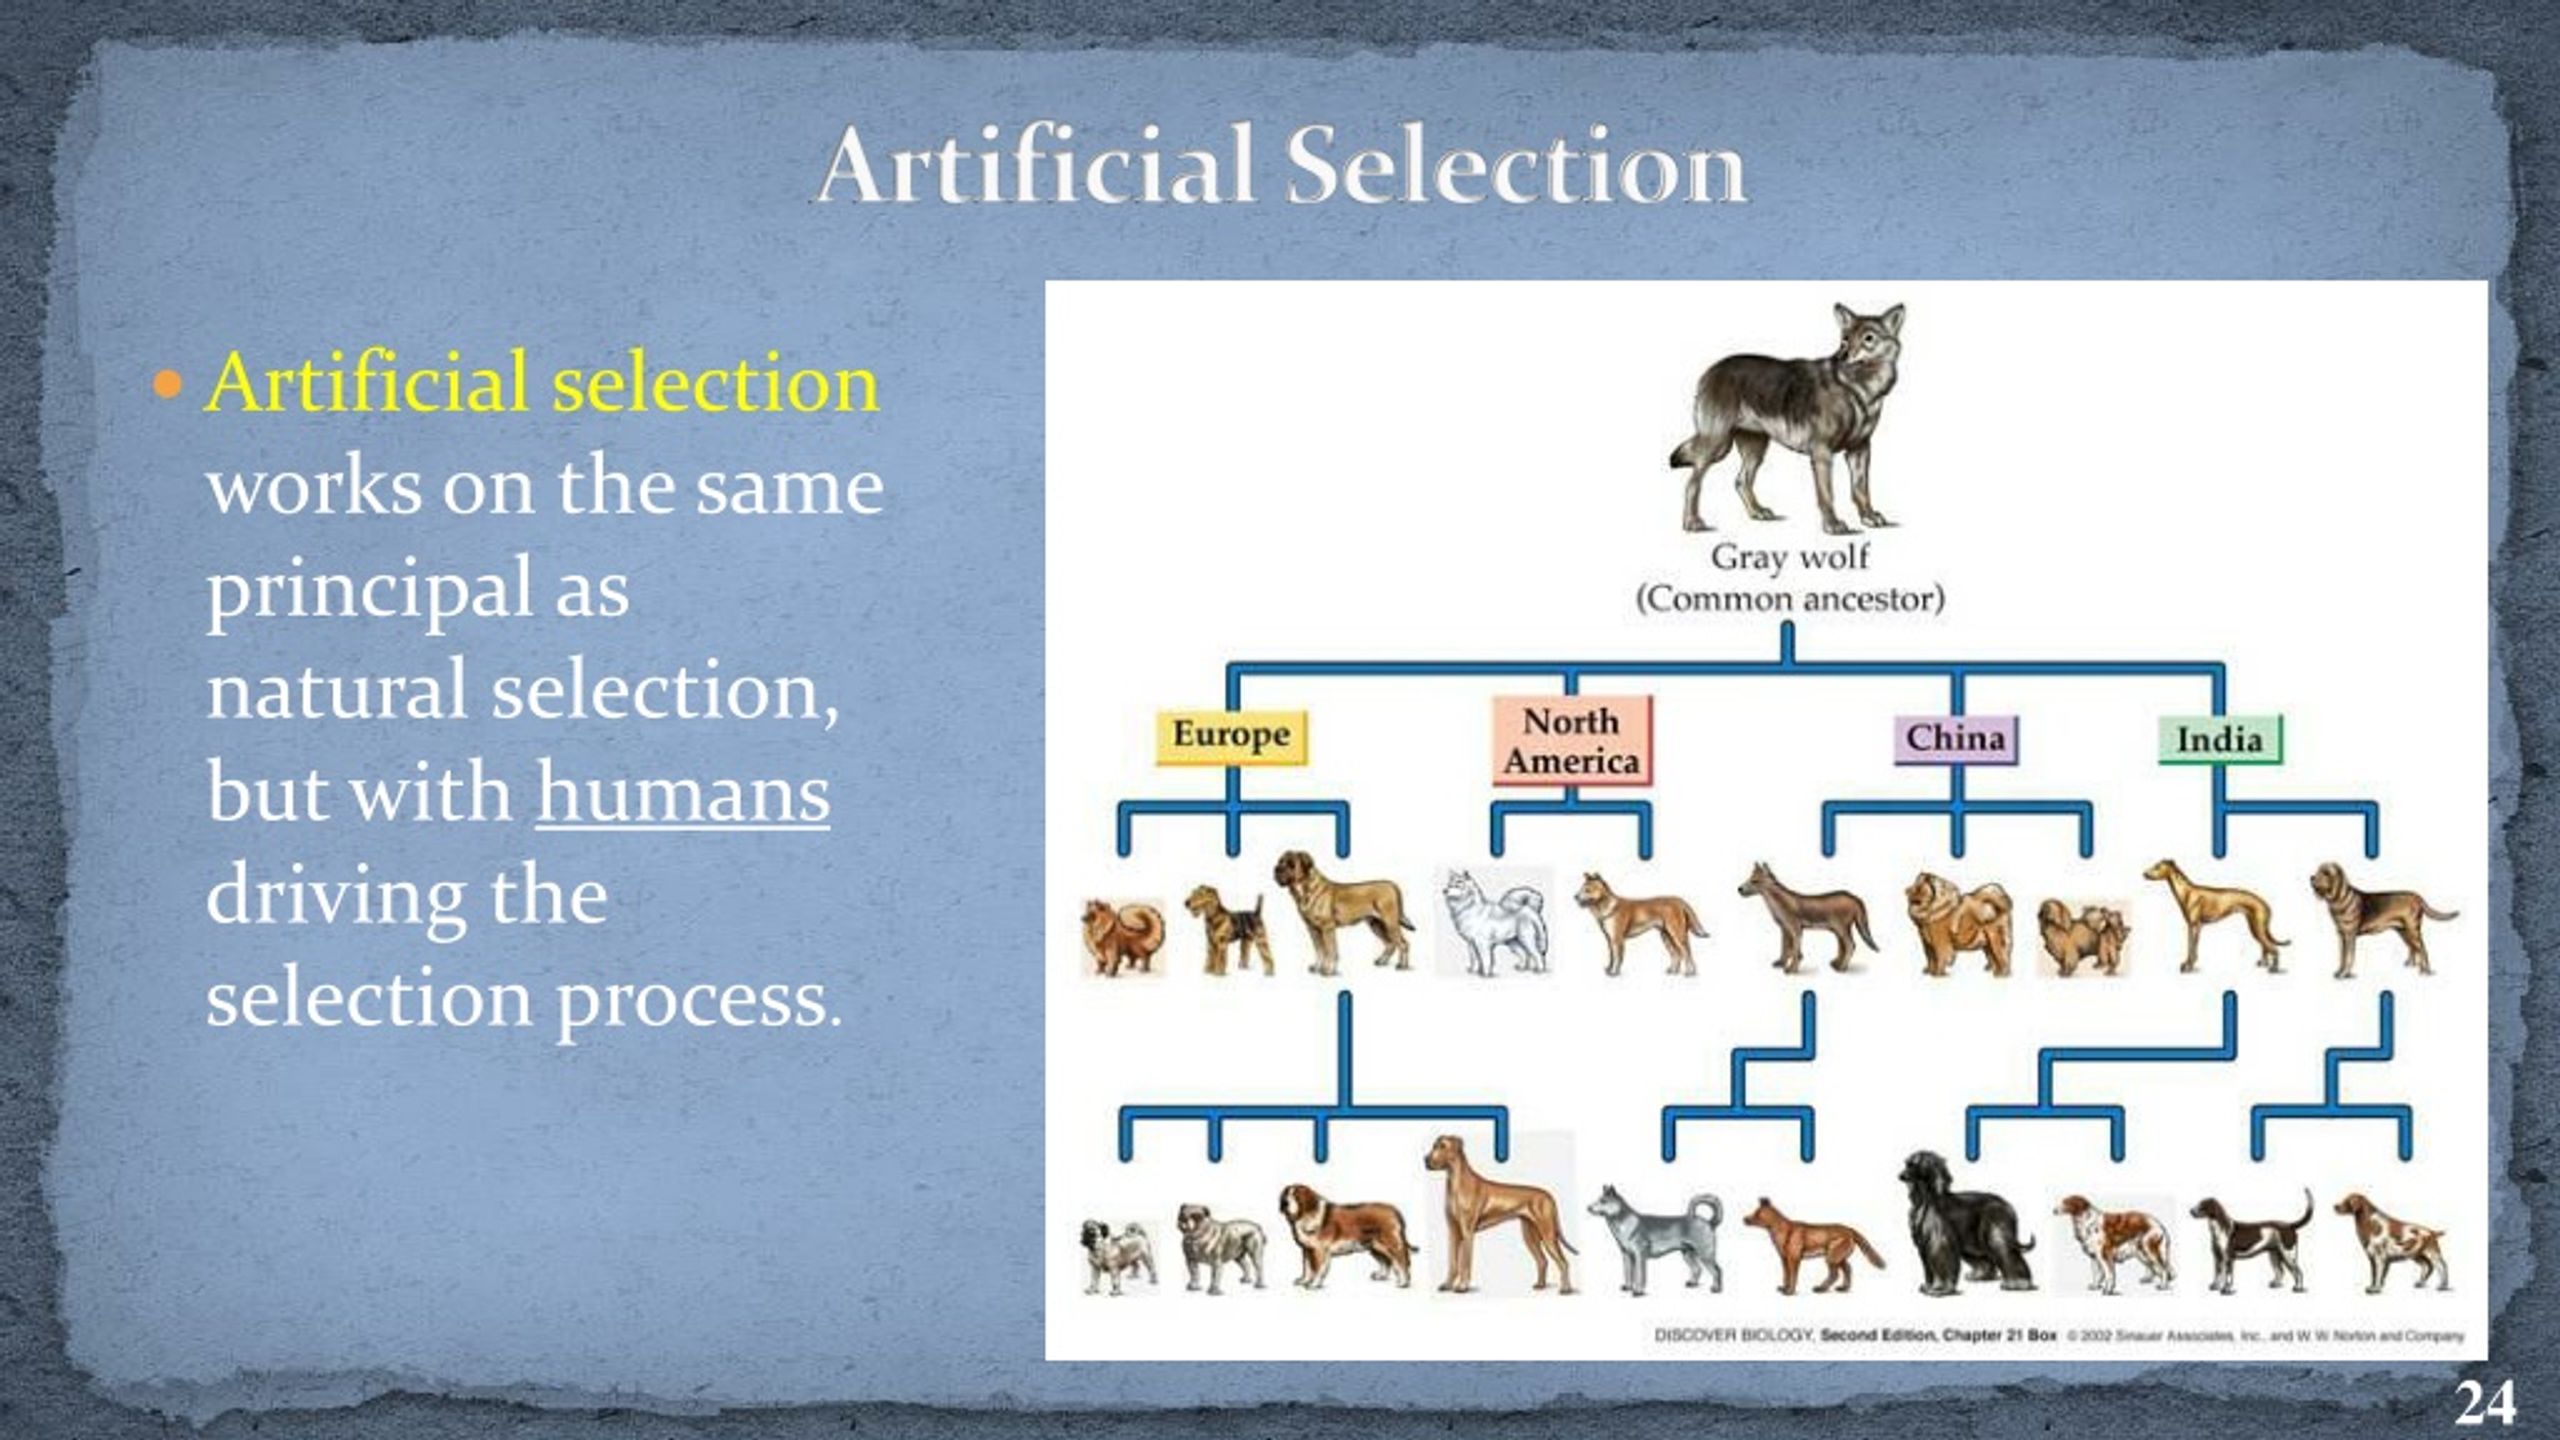
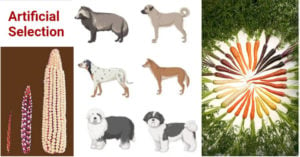
You pick a trait. You breed organisms that have it. You keep doing that until the population looks different. That's the short version. In practice it's slower and messier because you're dealing with living things that don't follow equations. Artificial selection is the intentional breeding of organisms with desired phenotypic traits over successive generations to shift the genetic composition of a population. It's the human-directed version of natural selection. Humans choose the parents instead of environmental pressure. The mechanism is the same: differential reproductive success based on heritable variation. The term itself just means that. But people conflate it with gene editing or genetic engineering, and that's a real problem when you're trying to explain timelines and capabilities to someone who doesn't know the difference. It's not CRISPR. It's mating decisions. That matters for everything from project planning to regulatory frameworks.
I spent three years running a small livestock breeding program where the goal was to select for disease resistance in a heritage chicken line. We weren't doing genomic selection. We were using pedigree-based estimated breeding values, which is the old-school approach. The definition is clean on paper. The execution is full of small compromises.
How it works in practice
Start by quantifying the trait. You can't select for something you can't measure, and measurement error is a silent killer of selection programs. If your trait has low heritability, you'll need much larger family sizes to get the same genetic gain. A trait with h² around 0.1 might need three to five times more candidates than a trait with h² around 0.5 to achieve the same response per generation. Then you calculate the selection differential or intensity. The breeder's equation (R = h² × S) still governs everything. R is the response, h² is narrow-sense heritability, and S is the selection differential. You can accelerate response by increasing selection intensity, but pushing that too far reduces the effective population size and brings inbreeding along for the ride. That's the first counter-intuitive thing people miss: stronger selection doesn't always mean faster improvement over multiple generations. It often means faster decay of genetic diversity and a subsequent slowdown. The second thing people miss is that artificial selection works on what's already in the population. You can't select for alleles that don't exist. When I ran into that wall with the chicken line, we wanted to select for resilience to a specific pathogen that wasn't present in our foundation stock. No amount of mating strategy was going to produce resistance. We had to introgress from an external source population. That's not a failure of selection. That's a limitation of selection.
Get the Full Details
The practical workflow
Define your objective trait(s) and assign them economic or functional weights if you're doing multi-trait selection. You can't optimize everything at once. Picking one primary trait and tracking a couple of correlated secondary traits usually works better than chasing ten goals and changing none effectively. Measure the trait accurately. Repeat measurements across environments reduce environmental noise and give you a better estimate of the true breeding value. A single measurement is rarely enough unless the trait is highly heritable and easily scored. Estimate breeding values. Best linear unbiased prediction (BLUP) is the standard method. It handles relatedness, fixed effects, and missing data better than simple phenotype selection. Pedigree-based BLUP works. Genomic BLUP works better when you have the data, but it's not a requirement for meaningful selection.
Select and mate. Decide on your mating system. Mass selection, family selection, or within-family selection each have different trade-offs. Family selection maintains more diversity. Within-family selection is more intense but risks losing favorable alleles through drift. You choose based on your constraints. Track inbreeding. This isn't optional. Monitor the inbreeding coefficient per generation. Keep F below 1% per generation if you want to avoid inbreeding depression eating into your gains. For small populations, you might need to accept a higher rate and manage the consequences explicitly.
Where it breaks down
Artificial selection fails when the genetic variance for your target trait is zero or near-zero. It also fails when correlated traits drag you in the wrong direction. I saw a dairy cattle program where selecting aggressively for milk yield accidentally reduced fertility because the genetic correlation between those traits was strongly negative. They spent four generations gaining yield and lost two seasons of breeding efficiency. The net result was economically neutral to negative. The correlation was well documented in the literature. Nobody in the room applied it. It also fails when your environment changes faster than your generations. If you're selecting for drought tolerance but the climate regime shifts fundamentally during your program, you're optimizing for a moving target. The response you got wasn't wrong. It was irrelevant. The biggest bottleneck I encountered personally was managing the trade-off between selection intensity and effective population size in a small foundation flock. We were working with about 200 breeding individuals and wanted to improve egg production by roughly 5% per generation. After two generations of intense selection on a single family line, our inbreeding coefficient had climbed to 12.5%. Hatchability dropped. Egg shell quality deteriorated. The trait we selected for was plateauing while health metrics degraded. The workaround was straightforward but unpopular: we rotated males more frequently, capped the contribution of any single sire to 10% of the next generation, and started tracking inbreeding depression alongside our primary trait. Genetic gain slowed to about 2.5% per generation, but we stopped digging ourselves into a hole. Two percent steady improvement beats five percent then collapse.
Common pitfalls to avoid
Don't confuse phenotypic superiority with genetic superiority. A great phenotype can be the result of a favorable environment, not favorable genes. That's why progeny testing exists. It's expensive and slow, but it separates the two. Don't ignore antagonistic pleiotropy. A gene that improves one trait might harm another through shared biological pathways. Screening for those effects early saves years of wasted work. Don't run selection in a single environment and expect broad adaptation. Genotype-by-environment interaction means your selected genotypes might perform poorly outside the conditions you tested them in. Multi-environment trials aren't glamorous. They're necessary.
When to use something else
If you need a specific allele that isn't in your population, artificial selection won't get it there. Marker-assisted backcrossing or genomic selection with introgression from wild relatives is faster. If you're working on a timescale where generations are decades long and you need results in years, you're looking at the wrong tool regardless of how well you understand the definition. Artificial selection is a powerful approach for gradual, cumulative improvement within a population's existing genetic architecture. It's not a magic wand. It's a slow engine with real constraints, and the people who get good results are the ones who respect those constraints instead of treating them as suggestions.