
What Iteration Actually Means in Math
Iteration is just repeating a process where you feed the output of one step back into the same process as the input for the next step. That's really all there is to it. People overcomplicate it because textbooks love to dress it up in fancy language, but at its core it's a loop with a rule. The technical definition goes something like this: an iterative method is a procedure that generates a sequence of approximations x_1, x_2, x_3... where each term is computed from the previous one using a fixed rule called an iteration function. The sequence either converges to a specific value or it doesn't. If it converges, you've got an answer. If it diverges, you've got a problem. I remember working through a numerical analysis problem back when I was doing simulation work for a fluid dynamics project. I was trying to find the steady-state temperature distribution across a metal plate using the Jacobi iterative method on a 200x200 grid. The issue wasn't that the method didn't work—it was that the convergence was painfully slow, taking something like 8,000 iterations to get within acceptable tolerance. What actually saved me was switching to the Gauss-Seidel method, which uses the most recently updated values immediately rather than waiting for a full sweep. That cut it down to roughly 3,500 iterations on the same problem. Same math, different ordering, significantly less wall-clock time.
Here's the thing beginners miss: iteration and recursion are not the same thing, even though they look similar. Recursion is about a function calling itself to build up a call stack and then unwinding it. Iteration is about state transformation—you have a current value, you apply a rule, you get a new value, you repeat. Iteration is generally more memory-efficient because you don't need to track a stack. In practice, any recursive algorithm can be rewritten iteratively, but not every iterative process has a clean recursive equivalent.
How Iteration Works in Practice
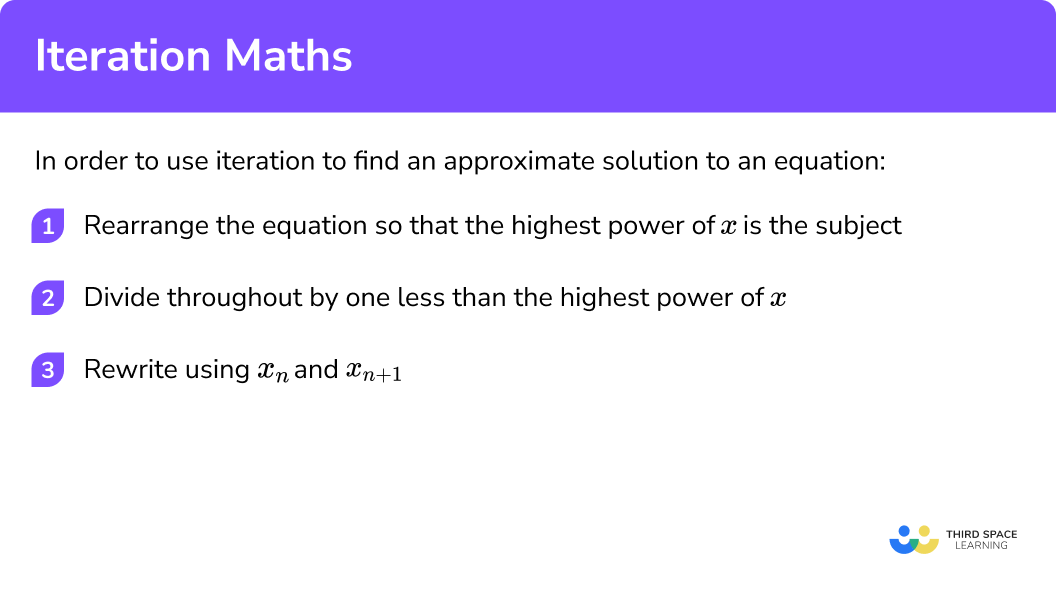
Let me walk through a concrete example. Say you want to approximate the square root of 2. You can use the Newton-Raphson iteration, which is one of the most commonly used iterative methods in all of applied mathematics. The iteration function is: x_{n+1} = (x_n + S/x_n) / 2, where S is the number you're finding the square root of and x_n is your current guess. Start with x_0 = 1. The next term is (1 + 2/1) / 2 = 1.5. Then (1.5 + 2/1.5) / 2 = 1.4167. Then (1.4167 + 2/1.4167) / 2 = 1.4142. You're already within three decimal places of the actual value after just three iterations. The sequence is squeezing toward sqrt(2) from above, and each step roughly doubles the number of correct digits. That's what quadratic convergence looks like in practice.
Get the Full Details
The key insight here is that the initial guess matters, but not nearly as much as people think. Newton-Raphson converges for any positive starting value when finding square roots. But that's not true for every function. I once had a colleague who tried to use Newton's method to find roots of cos(x) - x = 0 and started at x = 10. It diverged completely because the derivative was too small relative to the function value at that point. Starting at x = 0.5 instead worked fine because you're closer to the actual root near 0.739. A bad starting point can send an iterative method spiraling off to infinity or into a limit cycle, and there's no guarantee beforehand which behavior you'll get.
Common Pitfalls
Divergence is the most obvious failure mode. But there are subtler problems. One is premature stopping—you declare convergence when you're actually still far from the answer because your tolerance is too loose. I've seen engineering specs where people used a tolerance of 1e-3 and called it done, only to realize later that the accumulated error across thousands of iterations was throwing off downstream calculations by a noticeable margin. Setting a tolerance of 1e-12 or tighter is usually safe unless you have a reason to believe the problem is ill-conditioned. Another problem is stagnation. The iteration keeps running but the values barely change from step to step, not because you've reached the answer but because you've hit a flat region of the function where the derivative is nearly zero. This is particularly common with poorly scaled problems. The fix is usually preprocessing—rescaling your variables so that the function behaves more uniformly across the domain. There's also the issue of oscillation. Some iteration functions produce a sequence that bounces back and forth between two or more values instead of settling down. The simplest example is x_{n+1} = -x_n, which just alternates between whatever you start with. More realistically, this happens when the absolute value of the derivative of your iteration function at the fixed point is greater than or equal to 1. If |g'(x*)| >= 1, where g is your iteration function and x* is the fixed point, the iteration won't converge to that fixed point from nearby starting values. Checking this condition before you run the iteration can save you a lot of wasted computation.
When Iteration Fails Completely
Not every problem is suitable for an iterative approach. If the iteration function isn't continuous in the region you're working in, or if the domain has holes, the sequence might jump around unpredictably. I ran into this with a system of nonlinear equations where one of the variables could approach zero, making a term blow up. The iteration would occasionally produce a near-zero value, then the next step would produce something astronomically large, and the whole sequence would become useless. The workaround was to add a small regularization term that prevented any variable from getting too close to zero, which stabilized the iteration at the cost of a tiny bias in the final result. For most applications, that trade-off is completely acceptable. For problems where iteration is too slow or unreliable, direct methods are an alternative. Solving a linear system Ax = b directly using Gaussian elimination gives you an exact answer (up to floating-point precision) in a single pass rather than approximating it over many iterations. But direct methods scale poorly. Gaussian elimination is O(n^3) for an n-by-n system, while iterative methods like conjugate gradient can solve the same problem in roughly O(n^1.5) or better depending on the matrix structure. For large sparse systems, which is most of what you encounter in real work, iteration is often the only practical option regardless of its flaws.

A Quick Reference for Getting Started
Pick an appropriate iteration function for your problem. Make sure it has a fixed point at the value you're trying to find. Check that the derivative of the iteration function at that fixed point has absolute value less than 1. Choose a starting value reasonably close to the expected answer. Run the iteration and monitor the difference between successive terms. Stop when that difference falls below your tolerance. Verify the result makes sense—plugging it back into the original equation is the cheapest sanity check you can do. The whole process usually takes about as long as writing a few lines of code and letting it run. On a modern machine, even a million iterations of a simple loop completes in well under a second. The hard part isn't the computation—it's setting up the right iteration function and choosing parameters that actually converge. That comes from doing it enough times until you develop a sense for what works and what doesn't.


