What the Mean Actually Is
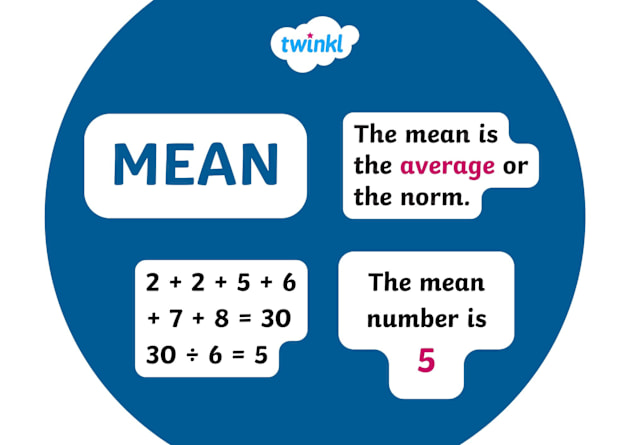
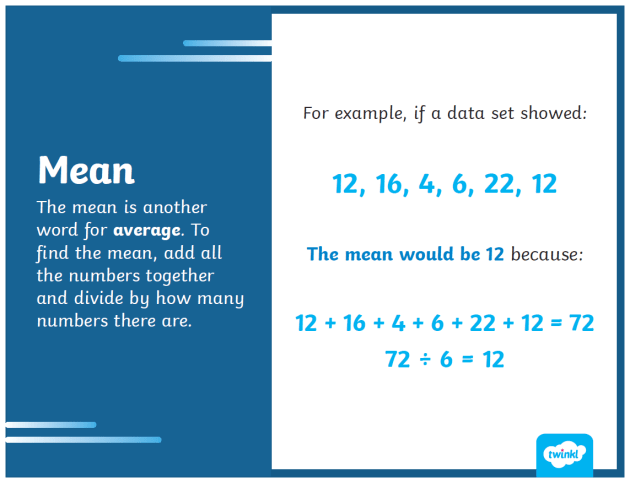
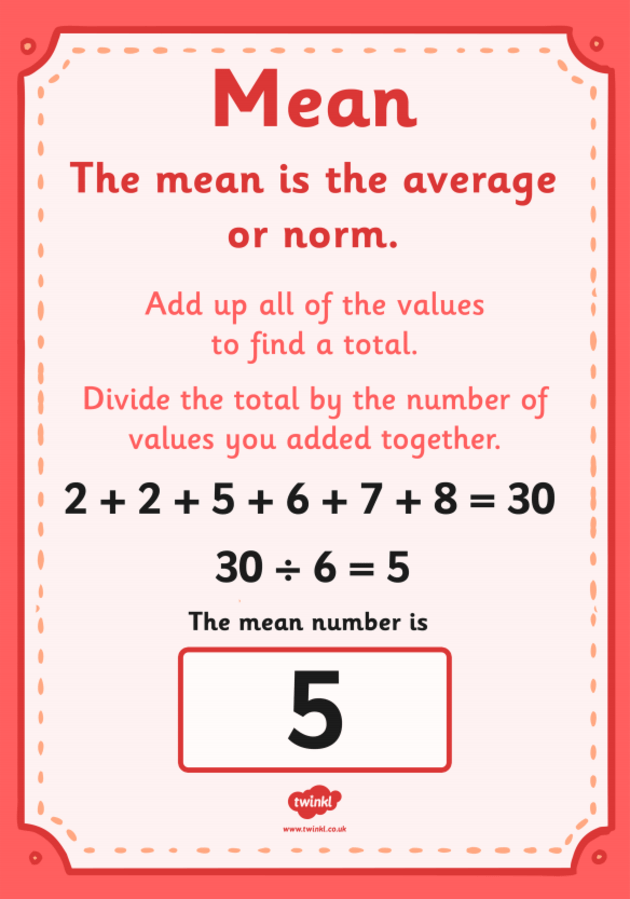
The mean is just a single number that stands in for a whole bunch of other numbers. You add them all up and divide by how many there are. That's it. Nothing fancy. People call it the average sometimes, which is confusing because average can mean three different things depending on who you're talking to. I spent years working with datasets where the mean was completely useless for describing what was actually happening. You'd look at a distribution of values and think everything was normal until you realized half the data was clustered one way and the other half was way out somewhere else. The mean sat right in the middle looking respectable while hiding the fact that your data was split into two completely different groups.
Definition Of Mean In Mathematics Explained
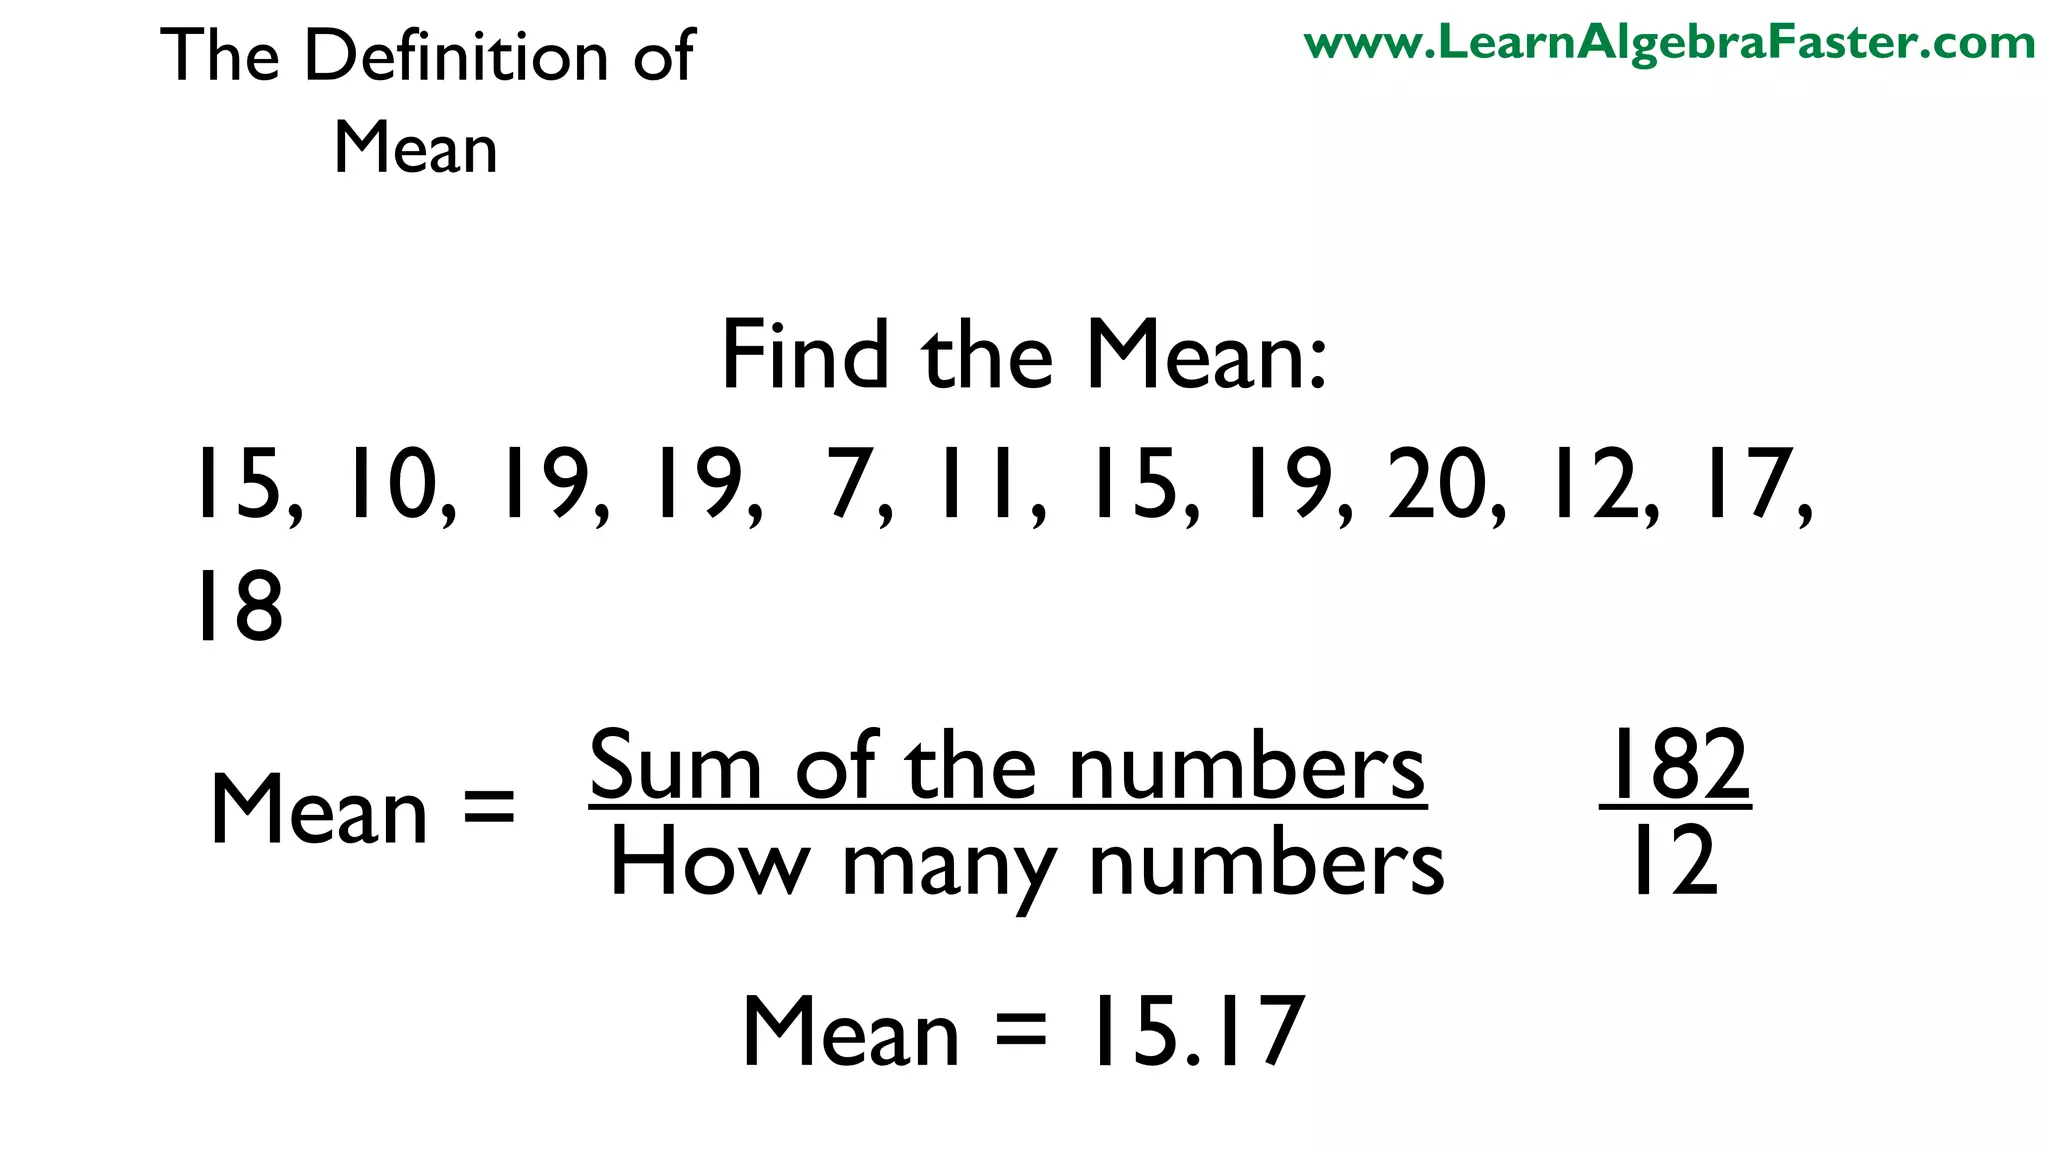
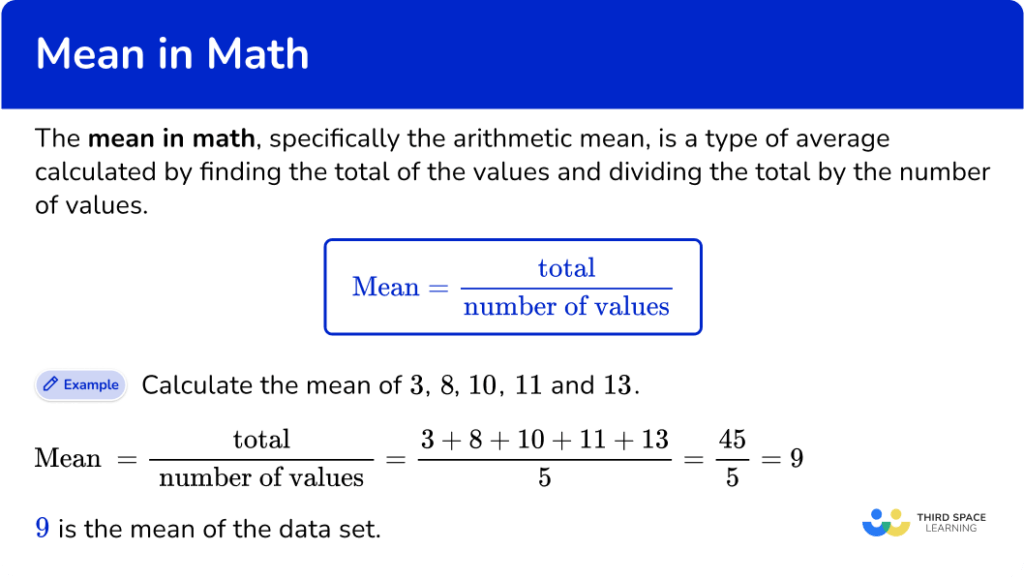
Here's how you actually calculate it when you're sitting there with a spreadsheet or writing code. Take your list of numbers. Add every single one together. Count how many numbers you have. Divide the sum by the count. The result is your mean. Example that actually matters: I had a dataset last year with transaction amounts from an e-commerce platform. Most purchases were between $20 and $80. But we had a few high-value orders over $5000. The mean came out to about $147 per transaction. That number looked fine on a dashboard. It was completely wrong for understanding typical customer behavior because those few large orders pulled the average up significantly.
When the Mean Lies to You
The arithmetic mean has a specific weakness that shows up constantly in practice. It's sensitive to extreme values, which statisticians call outliers. One really large or really small number can drag the mean away from where most of your data actually lives. This isn't a bug. It's just how the math works. You need to know when to trust it and when to look elsewhere. In my experience, the mean works fine when your data is roughly symmetric. Most natural measurements follow this pattern. Heights of people, weights of animals, test scores in a large class. These distributions tend to cluster around a central value with equal spread on both sides. The mean gives you a reasonable summary in these cases. But skewed distributions are where the mean becomes misleading. Income data is the classic example. A small percentage of people earn vastly more than everyone else. The mean income tells you something, but it doesn't represent what most people actually make. The median, which is the middle value when you sort everything, usually tells a more honest story in these situations.
Get the Full Details
How I Work With Means in Practice
When I'm analyzing data now, I calculate the mean first, then immediately check the median and standard deviation. If the mean and median are within about 10 percent of each other, I'm usually comfortable using the mean as a summary. When they diverge more than that, I dig deeper into the distribution before making any claims. Here's a specific edge case I encountered recently. I was working with server response times for an API. Most requests completed in under 200 milliseconds. But every now and then, a request would take several seconds due to garbage collection pauses or network timeouts. The mean response time was about 340 milliseconds. That sounded acceptable. But looking at the 95th percentile, which showed 95 percent of requests completed faster than a certain threshold, revealed that 5 percent of users were waiting much longer. For that situation, I switched to reporting the median response time, which came out to 185 milliseconds. That number better represented what most users experienced. I still calculated the mean because it has uses in certain calculations, but I didn't lead with it when presenting results to stakeholders.
Common Mistakes I See People Make
One mistake that drives me crazy is averaging averages. You'll see someone take the mean from one group, the mean from another group, and then average those two numbers together. This gives wrong results when the groups have different sizes. The correct approach is to combine all the raw data and calculate one mean from everything. Another frequent error is treating the mean as if it represents an actual data point. The mean of {1, 2, 100} is 34.33. No one in that dataset actually has a value anywhere near 34.33. The mean is a mathematical construct, not necessarily a realistic value. It's useful for calculations and comparisons, but don't pretend it describes any real observation. People also forget that the mean only works with numerical data. You can't calculate a meaningful mean for categories like colors, names, or yes-no responses unless you've encoded them as numbers first. And even then, you need to think carefully about whether that encoding makes sense for your question.
Alternatives When the Mean Fails
When your data has extreme outliers or a strong skew, consider using the trimmed mean instead. You remove the top and bottom 5 percent of values, then calculate the mean from what's left. This reduces the influence of outliers while keeping the simplicity of averaging. A 5 percent trim usually removes the worst extremes without discarding too much data. The geometric mean is another option for certain types of data. It's calculated by multiplying all the values together and taking the nth root, where n is the count of values. This works well for growth rates, ratios, and data that spans multiple orders of magnitude. Investment returns are a common use case. If you had returns of 50 percent one year and minus 33 percent the next, the arithmetic mean would suggest about 8.5 percent annual growth. The geometric mean shows you actually broke even, which is the truth. For highly irregular data with multiple peaks, neither the mean nor the median captures the full picture. You might need to look at the entire distribution, report multiple statistics, or use visualization to show what's actually happening. No single number will tell the whole story in these cases.
Quick Reference for Calculation
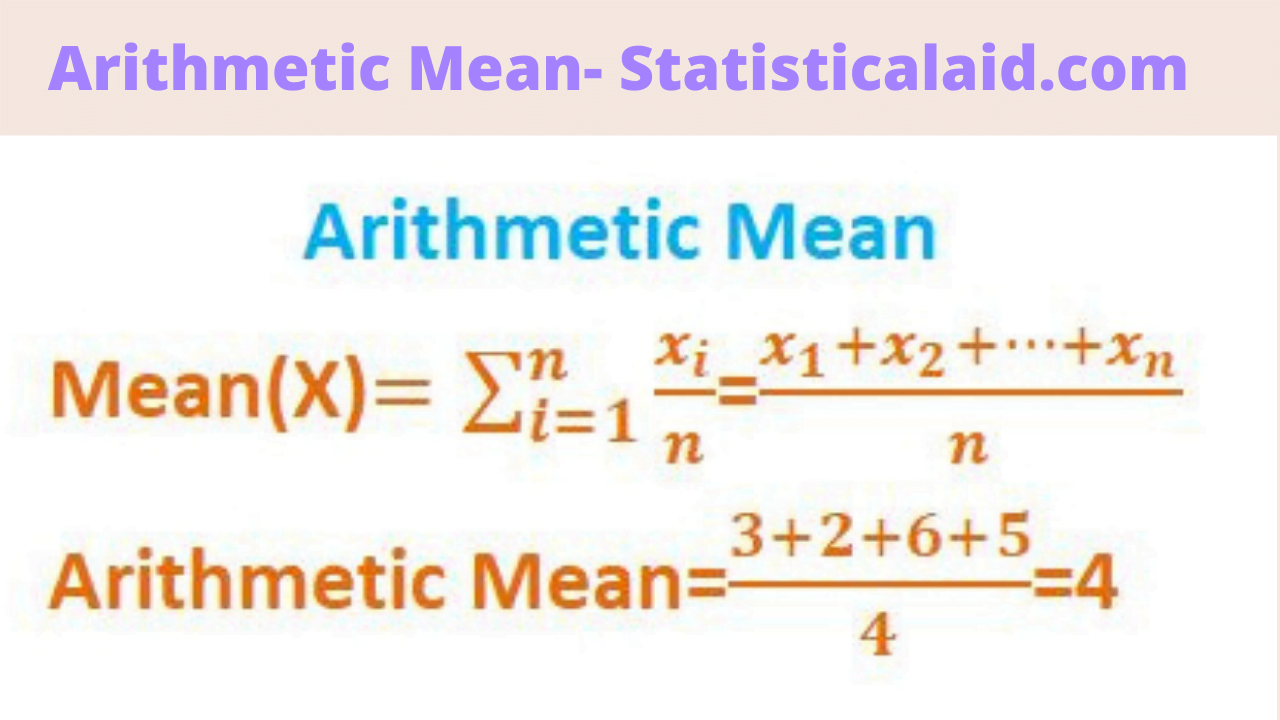
If you need to compute a mean by hand, here's the process without any extra commentary. Write down all your values. Add them together. Count how many values you have. Divide the sum by the count. Double-check your arithmetic. The result is your mean. When using a calculator or spreadsheet, the function is usually called AVERAGE or MEAN depending on the software. Make sure you select the correct range of cells. A common error is including labels or text cells in the selection, which can cause problems in some programs. Excel handles this reasonably well by ignoring text, but other tools might behave differently. For large datasets with millions of values, computational efficiency matters. The standard algorithm requires one pass through the data to sum everything and a second operation to divide. This is O(n) time complexity, which is about as good as it gets. You can't compute a mean without looking at every value at least once, so there's no shortcut around that.
Where I See Means Used Correctly
The mean shines in controlled experiments where you're measuring something with relatively consistent results. Quality control in manufacturing is a good example. If you're measuring the diameter of bolts produced on an assembly line, the mean diameter tells you whether the process is centered correctly. You pair it with standard deviation to understand the variation, and you get a complete picture of what the process is doing. Sensor readings are another area where the mean helps. If you have a temperature sensor that bounces around a bit due to noise, taking the mean of multiple readings gives you a more stable estimate of the actual temperature. This is why data loggers often report averaged values. A single reading might be off by a degree or two. Ten averaged readings usually get you much closer to the truth. Finance uses means extensively, though not always wisely. Portfolio managers report average returns, analysts calculate average earnings per share, and risk models use mean assumptions. The mean is a useful building block in these calculations, but you need to understand its limitations when interpreting the results. Average returns don't guarantee anything about future performance, and past averages are not predictors of what comes next.
My Rule of Thumb
I usually report the mean when my data is roughly symmetric and free of extreme outliers. I check the shape of the distribution first, preferably with a histogram or box plot. If the mean and median are close and the spread looks reasonable, I use the mean. If the data is skewed or has clear outliers, I lean toward the median or report both numbers with a note about the distribution shape. This approach has served me well across multiple projects. It's not perfect, and I still get surprised occasionally when a dataset behaves in an unexpected way. But starting with a visual check and comparing multiple summary statistics catches most problems before they turn into embarrassing mistakes in reports or presentations.