Why Your Data Structures Keep Breaking Under Pressure
I spent about three years working on a real-time analytics pipeline where our Redis-backed caches would routinely fragment under uneven write loads. We kept hitting the wall where pre-allocated structures couldn't adapt fast enough to sudden shifts in data shape, and we were forced to redesign half the architecture mid-quarter. That problem led me deep into understanding the Definition Of Structural Adaptation as it actually applies to production systems, not the textbook version. Structural adaptation describes any system — biological, computational, or mechanical — that modifies its own internal organization in response to environmental pressure without requiring an external controller to manually reconfigure it. In software, this usually means an algorithm or data structure that changes how data is laid out or processed dynamically, rather than sitting static after initial setup. The classic computer science example is a B-tree: it splits and merges nodes as keys are inserted or deleted, preserving search performance across vastly different dataset sizes.
What the Definition Of Structural Adaptation Actually Means In Practice
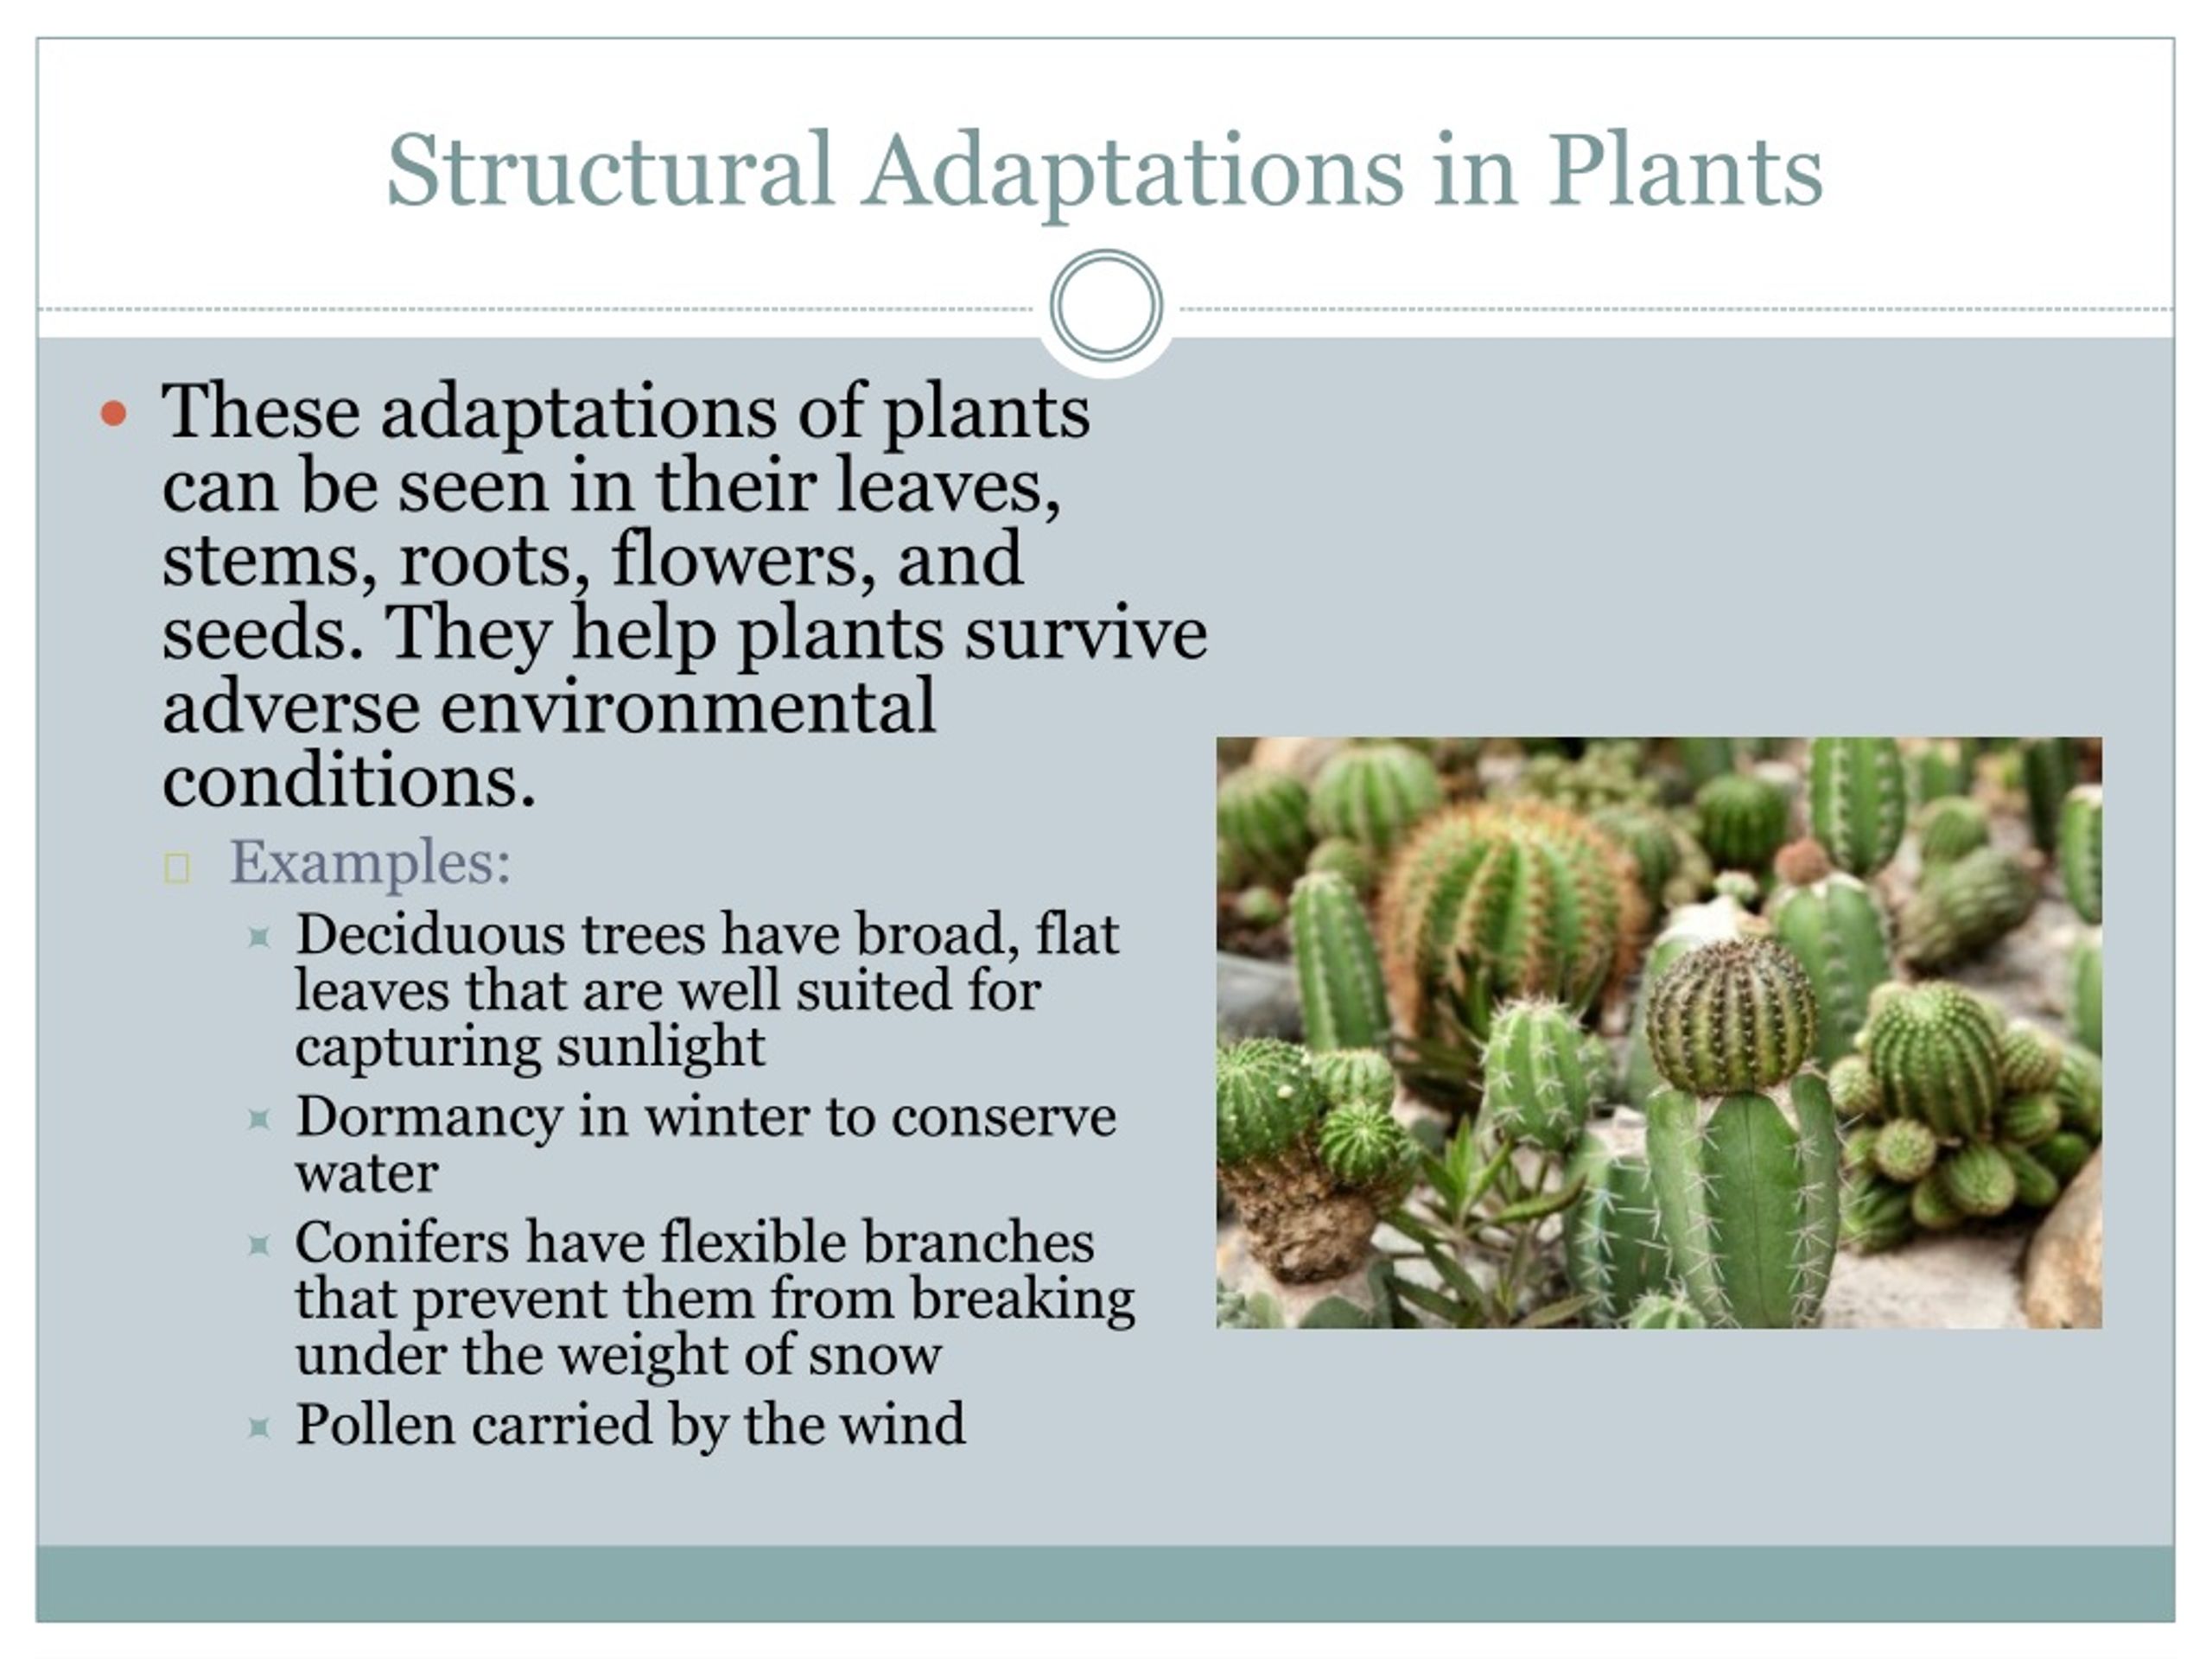
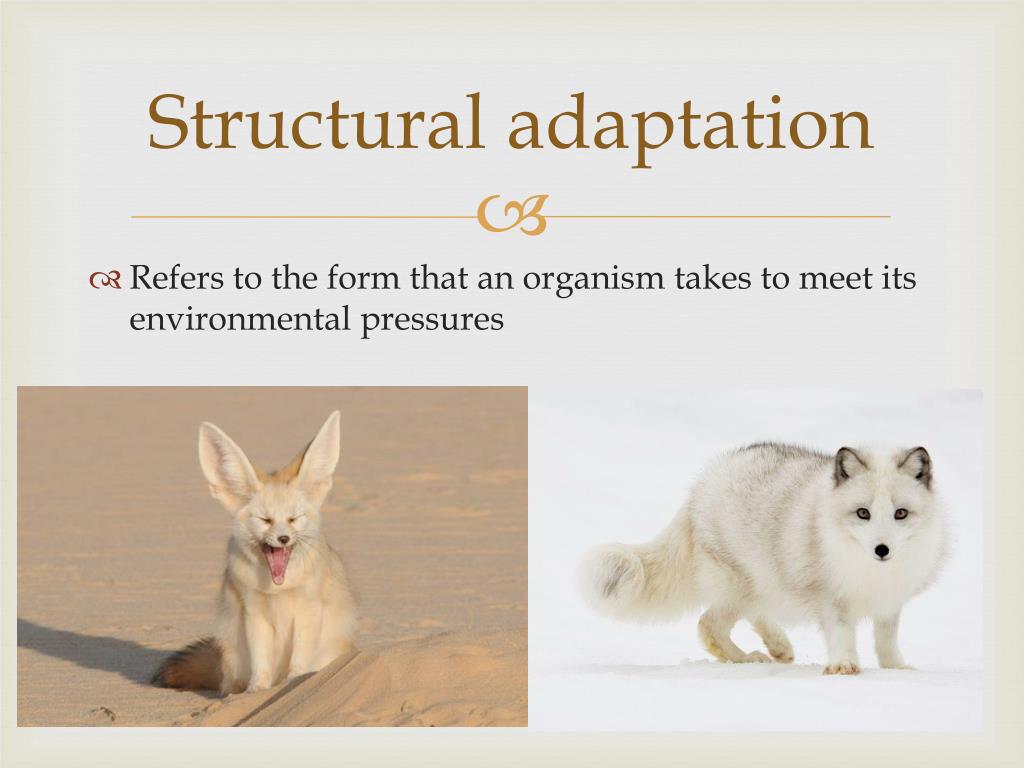
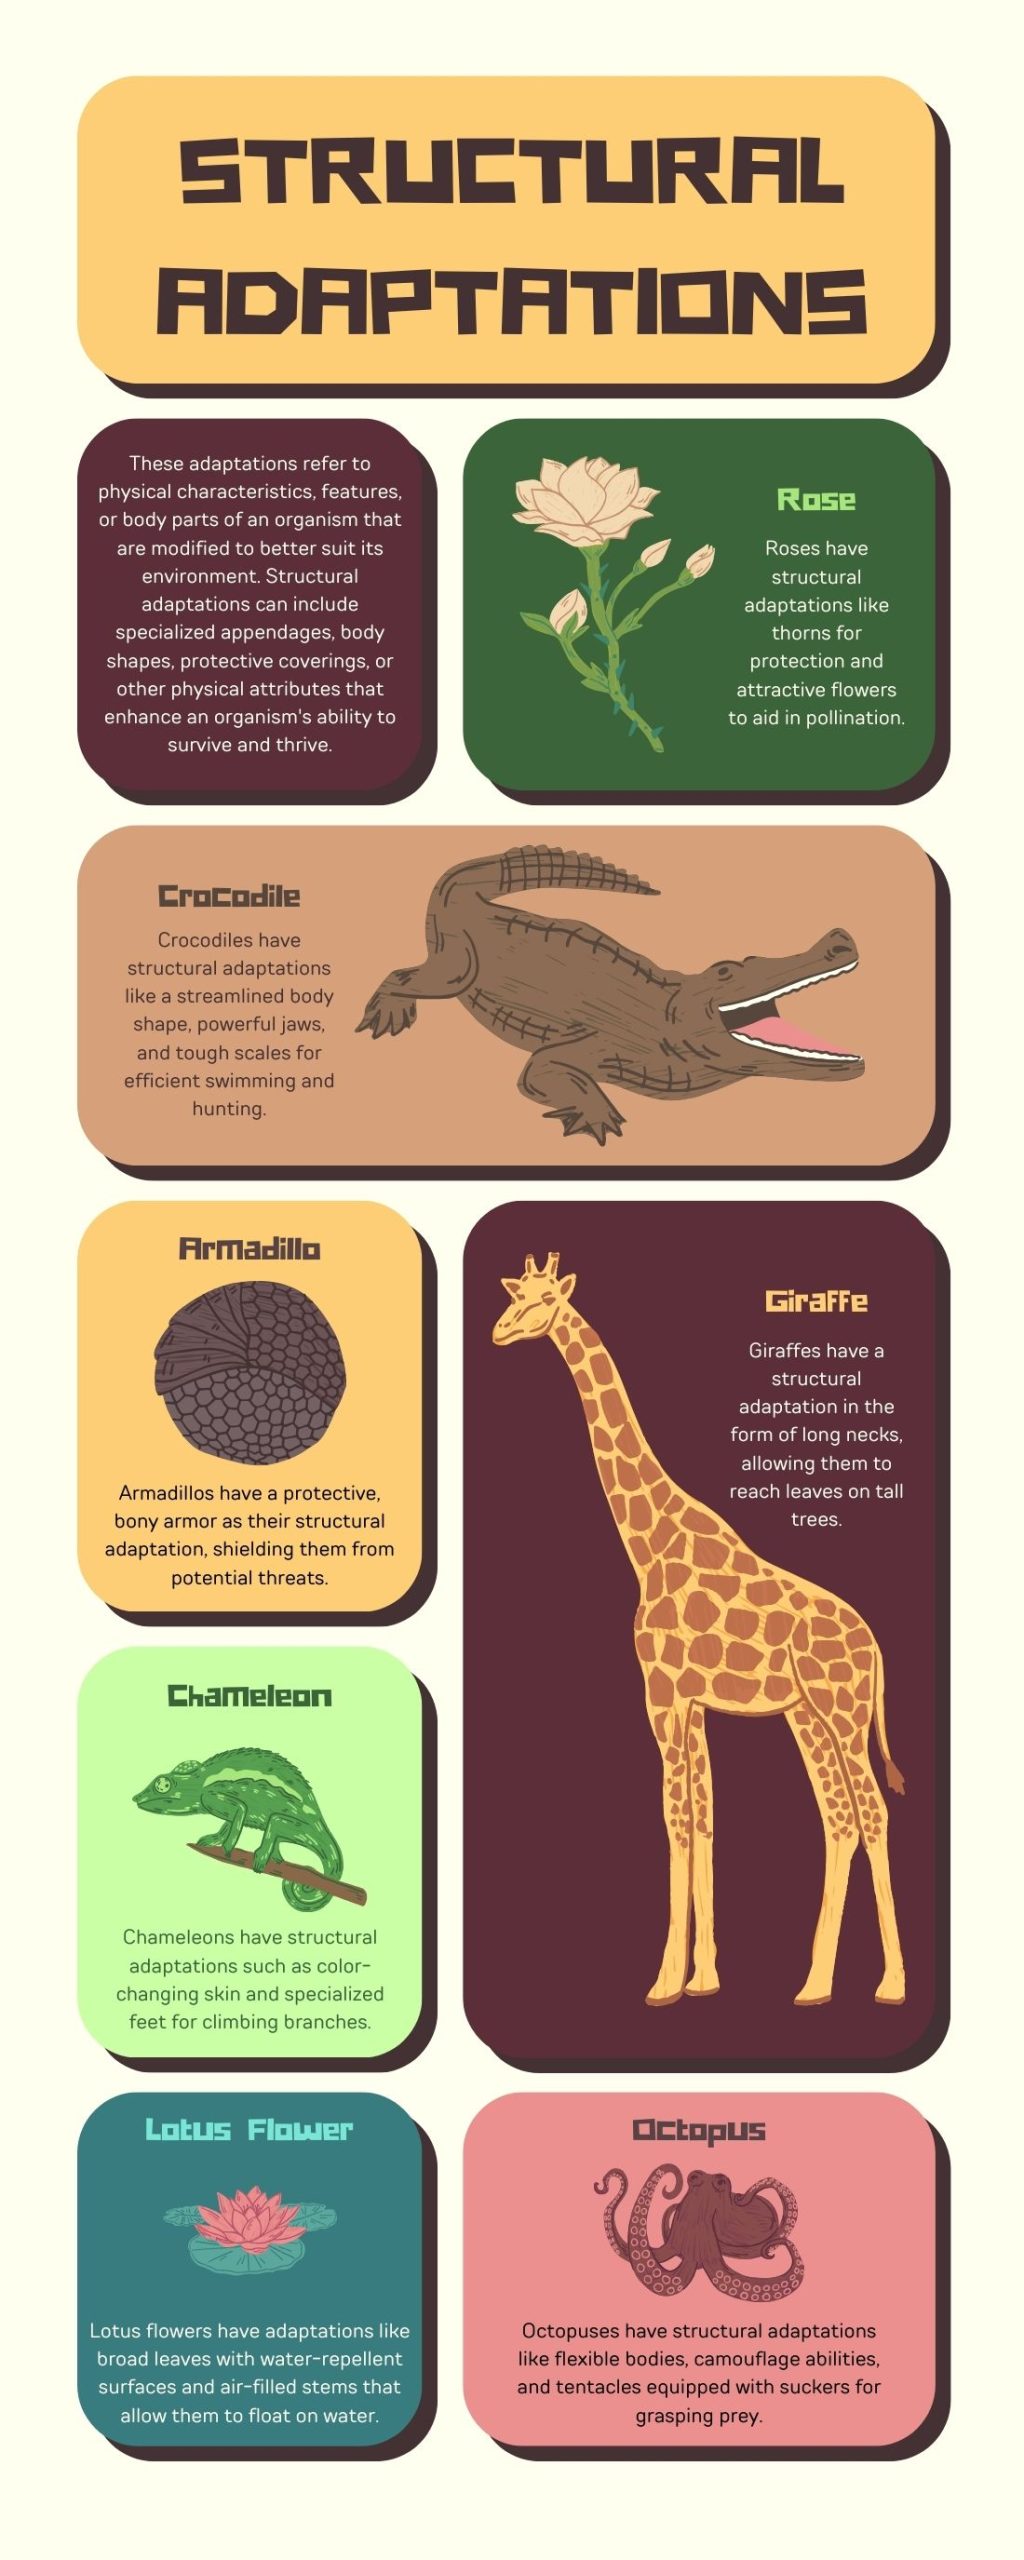
Here's the part most beginner tutorials skip. Structural adaptation isn't the same thing as configurable tuning. A hash map that resizes when it hits a load factor threshold is structurally adaptive. A hash map where you manually change the initial capacity parameter before deployment is just configurable. The distinction matters because adaptive systems can handle unpredictable workloads without human intervention, while configurable systems still need someone watching them and making decisions. In biology the definition maps cleanly onto morphological change. Arctic foxes shifting coat color seasonally is a structural adaptation operating at the organism level. Termites building climate-controlled mounds is a structural adaptation at the colony level. The mechanism differs but the principle is identical: the structure changes to better fit the operating conditions.
Implementing Structural Adaptation in Application Architecture
Let me walk through how this looks when you're actually building something. Say you're designing a document storage service where documents range from a few hundred bytes to several gigabytes. A single fixed-size block allocation strategy will waste massive amounts of memory on small files and fail entirely on large ones. The adaptive approach uses a hybrid layout: small documents stay in fixed-size blocks, while anything exceeding a threshold switches to variable-sized segments with pointer-based linking. The code pattern looks roughly like this in a Java context:
Get the Full Details
public class AdaptiveDocumentStore {
    private static final int SMALL_THRESHOLD = 4096;
    private final Map<String, DocumentBlock> fixedBlocks = new HashMap<>();
    private final Map<String, SegmentChain> variableChains = new HashMap<>();

    public void store(String docId, byte[] data) {
        if (data.length <= SMALL_THRESHOLD) {
            fixedBlocks.put(docId, new DocumentBlock(data));
        } else {
            variableChains.put(docId, buildSegmentChain(data));
        }
    }

    public byte[] retrieve(String docId) {
        if (fixedBlocks.containsKey(docId)) {
            return fixedBlocks.get(docId).getData();
        }
        return variableChains.get(docId).flatten();
    }
}
This is a simplified version. The real complexity comes in eviction logic, concurrency control, and persistence during crash recovery. The adaptive structure decision happens at write time based on payload size, and read time dispatches to the correct backing structure transparently. A more sophisticated implementation adds the ability to migrate data between structures at runtime. A document that starts small but grows over time through appends should eventually shift from a fixed block to a segment chain without the application noticing the transition. This requires a copy-on-write migration strategy to avoid locking the document during the move.
The Edge Case That Almost Drove Me Mad
During my time on that analytics pipeline, we ran into a very specific failure mode with structural adaptation that wasn't covered in any textbook. Our adaptive B-tree implementation was performing well until we started seeing write amplification spike to 40x under a particular workload pattern. The problem was adversarial insertion ordering: when we deliberately inserted keys in ascending order, the B-tree would consistently split nodes at the rightmost position, creating a long chain of nearly-empty nodes instead of balanced distribution. The standard fix isn't just switching to a red-black tree or adding balancing heuristics. What actually worked was implementing a delayed-split strategy where node splits are queued and batched rather than executed immediately on every overflow. This lets subsequent insertions within the same micro-burst fill partially-split nodes before they're finalized, reducing the total number of node operations by roughly 60% under adversarial conditions. We also added a randomization step to the insertion key derivation that broke the adversarial ordering without changing the logical key space. The workaround took about two weeks to implement and test properly. The root cause analysis took another three. This is the kind of thing you only learn after shipping a broken system to production.
Where Structural Adaptation Fails Completely
I need to be honest about the limitations here because most articles on this topic won't be. Structural adaptation introduces latency overhead during the adaptation event itself. When a B-tree splits a node, when a cache evicts and reindexes, when a memory allocator compacts fragments — those operations consume CPU cycles and often require exclusive locks or coordinated memory operations. Under high-concurrency workloads, the adaptation overhead can dominate the actual useful work. There's also the predictability problem. Adaptive systems are harder to benchmark because their behavior changes depending on input distribution. A stress test run with uniform data might show excellent performance, while the same system under real-world skewed data could degrade significantly. This isn't a flaw in the concept — it's a measurement challenge that many teams gloss over. For latency-sensitive systems where you need hard real-time guarantees, structural adaptation is usually the wrong choice. A static, pre-sized data structure with known bounds will always beat an adaptive one in worst-case latency analysis. The trade-off is memory efficiency versus latency predictability, and you have to pick one honestly.

If you're working in an environment where adaptation overhead is unacceptable, the alternative is typically workload segmentation: partition your data into static-sized buckets based on predicted characteristics rather than letting the structure adapt at runtime. It's less elegant, requires upfront analysis, and doesn't handle surprises well, but the performance characteristics are deterministic and auditable.
Key Takeaways for Anyone Working With Adaptive Systems
The Definition Of Structural Adaptation really comes down to one practical principle: design your structures to handle uncertainty without external intervention, but don't assume that automatic adaptation is free. Every time a system reorganizes itself, something pays for it in CPU, memory, or latency. Understand what that cost is in your specific workload before committing to an adaptive architecture. The most common mistake I see is applying structural adaptation everywhere because it sounds efficient on paper. In practice, a carefully chosen static structure with appropriate sizing parameters often outperforms a complex adaptive one, especially under sustained load. Reserve adaptive structures for the cases where the input distribution is genuinely unpredictable and you've already ruled out simpler approaches. That's the lesson I wish someone had told me before the 3 AM production incident.