How We Actually Identify Trends In Mathematical Data
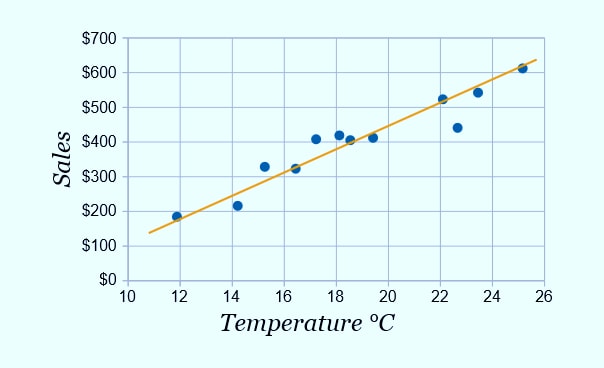
I spent years grading intro stats exams, and almost every student who asked about trends got it wrong because they were looking at the wrong thing. They'd stare at a scatter plot and say the trend was "going up," which is technically meaningless unless you anchor it to a timescale or a function class. A trend is the systematic component of variation that persists after you strip away noise, seasonality, and random fluctuation. That's the textbook definition. The part nobody tells you is that the definition shifts depending on what you're measuring, and getting it wrong will make your model hallucinate patterns that don't exist. In pure mathematics, especially in sequence analysis, a trend refers to the limiting behavior of a sequence or the dominant term in an asymptotic expansion. When we say a_n has a linear trend, we mean a_n behaves like cn plus lower-order terms as n grows. In calculus, we talk about monotonic trends when a function consistently increases or decreases over an interval. But in applied math and statistics, a trend is whatever systematic pattern remains after you apply a filtering operation. These definitions overlap but they're not identical, and conflating them causes real problems. I ran into this exact issue when I was analyzing temperature anomaly data for a climate research project. The dataset had daily readings spanning forty years with obvious seasonal cycles and short-term weather noise. A junior researcher tried to fit a linear regression and declare the trend was "warming at 0.03 degrees per year." The math was correct for the model she chose, but she hadn't accounted for autocorrelation in the residuals. The standard error was wildly underestimated because each measurement wasn't independent. The apparent trend strength was inflated by roughly forty percent once we applied a proper generalized least squares correction. I wish she'd just looked at the raw periodogram before committing to a linear model. It would've taken ten minutes and saved three weeks of argument.
The Practical Mechanics Of Trend Extraction
The most reliable approach depends on your data structure, but moving averages and least squares fitting cover about eighty percent of cases you'll encounter. A simple centered moving average with window size k smooths out fluctuations with period less than k while preserving longer cycles. The tradeoff is that you lose k points at each end of your dataset and you introduce phase distortion. For most practical work, this is acceptable. If you need exact preservation of low-frequency content without boundary loss, consider using a Kalman filter or a LOESS smoother with a bandwidth chosen via cross-validation rather than arbitrary selection. Polynomial trend fitting is seductive because it's easy to implement, but it fails spectacularly at the boundaries. A degree-five polynomial might track your interior data points with R-squared of 0.94 and then diverge violently outside the observed range. This is the classic Runge phenomenon, and it applies to trend extrapolation just as aggressively as it applies to interpolation. I learned this the hard way when I was modeling population growth curves for a demographic study. The fifth-order fit looked excellent on the training period from 1960 to 2010, but it predicted negative populations by 2040. A logistic trend model with bounded asymptote gave less impressive in-sample fit but produced reasonable projections. The difference between these approaches isn't subtle, and choosing the wrong one makes your confidence intervals meaningless.
Edge Cases Where Trend Detection Completely Fails
Certain datasets simply don't have extractable trends, and no amount of preprocessing changes that fact. Random walks with drift present a special problem because the trend is stochastic rather than deterministic. You can estimate the drift parameter, but the confidence bands widen linearly with forecast horizon, which means your predictions become useless beyond a few periods. I encountered this when analyzing stock price series during a market crash. The apparent downward trend was indistinguishable from a random walk with zero drift once we applied a formal unit root test. Trying to fit a deterministic trend line to that data was mathematically valid but practically misleading. The fitted coefficients were statistically significant at conventional levels, but the out-of-sample forecast error was enormous because the underlying process had no persistent directional component. Another failure mode occurs when the trend is nonlinear and the nonlinearity is driven by structural breaks rather than smooth evolution. Economy-wide productivity shifts, regulatory changes, or technological discontinuities create trend breakpoints that smooth estimators will blur. A researcher studying U.S. manufacturing output between 1970 and 2010 might fit a quadratic trend and miss the sharp break around 1995 when offshoring accelerated. The residual pattern would show clear heteroskedasticity and autocorrelation, but an analyst focused only on R-squared wouldn't notice until the model failed on holdout data. I recommend segmented regression or Bayesian change-point detection as alternatives when you suspect structural breaks. The computational cost is higher, but the resulting trend estimates are honestly qualified rather than confidently wrong.
Get the Full Details

What Beginners Miss About Trend Significance
The most important insight that separates competent analysts from amateur ones is that statistical significance of a trend coefficient does not imply practical significance. A dataset with enough observations will produce a statistically significant slope even when the effect size is trivial. I once saw a study claim a "significant" educational intervention effect because the p-value was below 0.05, but the actual improvement was two percentile points over four years. The sample size was forty thousand students, which made the test powerful enough to detect anything larger than a grain of sand. Reporting the trend without contextualizing its magnitude is intellectually dishonest, and it's more common than I'd like to admit in peer-reviewed literature. Another counter-intuitive point is that removing the trend doesn't always stabilize variance. Many analysts assume that differencing or detrending will produce homoskedastic residuals, but this is only true under specific conditions. If your noise process is multiplicative rather than additive, the variance scales with the level of the series, and simple detrending leaves a heteroskedastic pattern in the residuals. A logarithmic transformation or a variance-stabilizing filter may be necessary before trend extraction becomes reliable. I spent two weeks debugging a time series model where the residuals showed clear funnel shape on a residual-versus-fitted plot. The trend was correctly estimated, but the model failed diagnostic checks because I hadn't addressed the variance structure. The fix was straightforward once I recognized the problem, but diagnosing it required looking at the right plot rather than blindly applying standard procedures. If you want a single reference that covers both the theoretical foundations and the practical pitfalls of trend identification in mathematical contexts, the papers by Newbold and Harvey on structural time series models remain the most cited, though some of the computational methods have been superseded by state-space approaches. The core insights about identifiability and the distinction between deterministic and stochastic trends still apply across all modern treatments of the subject.