What Actually Happens When You Take a Union
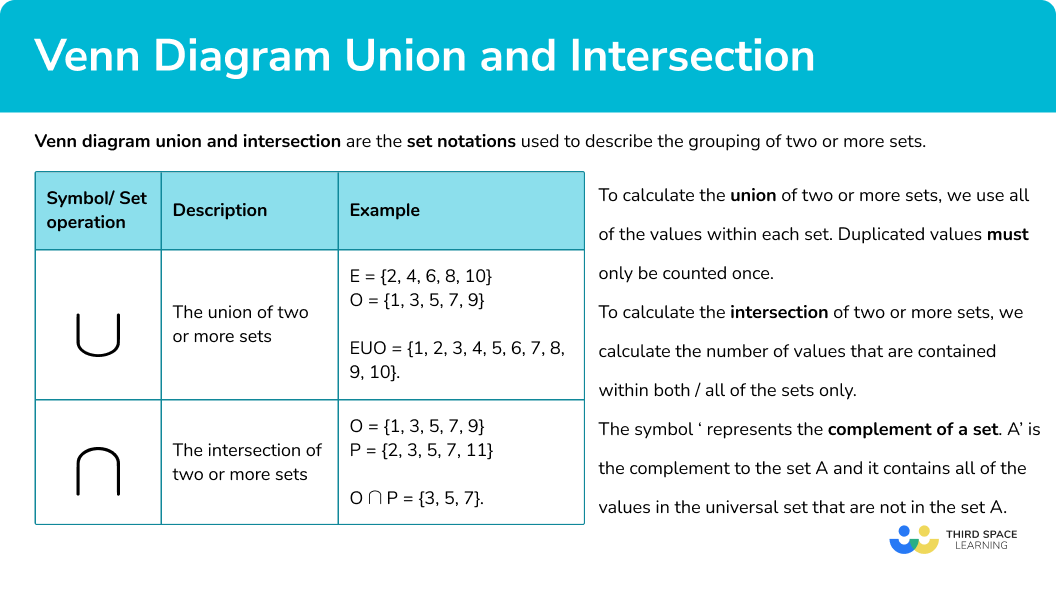
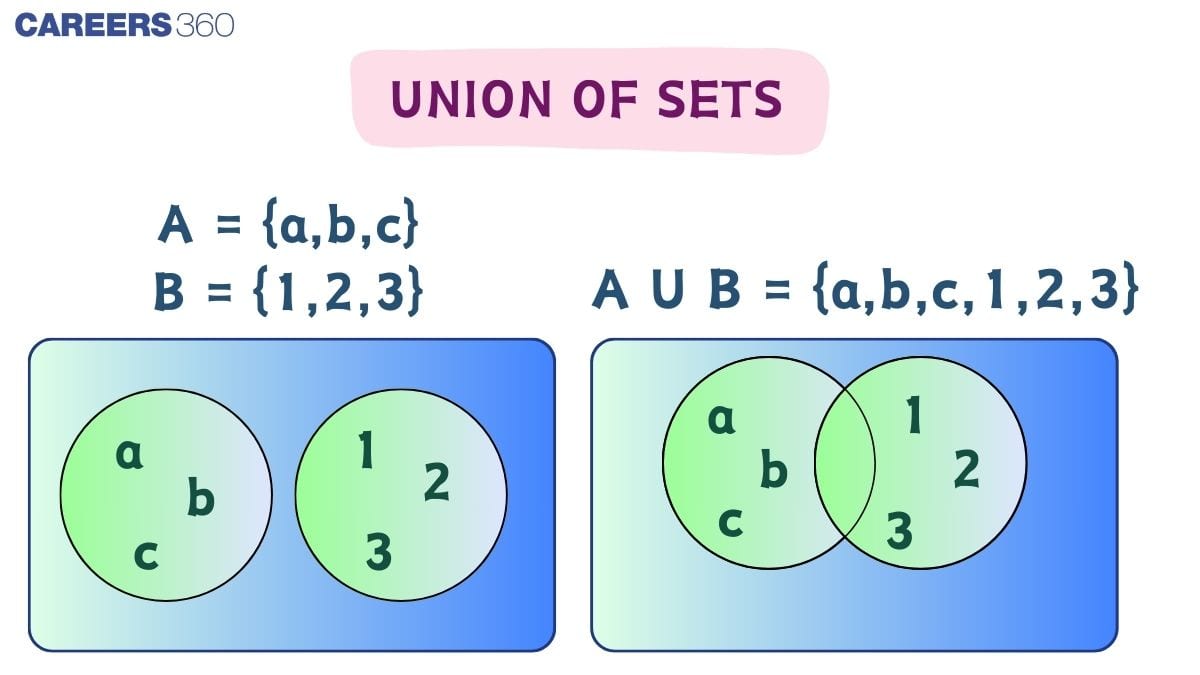
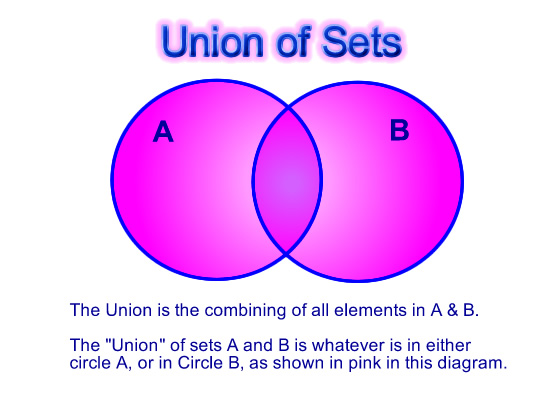
The union of two sets is just all the elements that appear in either set, written as A B. That's it. But the way it shows up in practice is messier than the textbook version. I've spent more time than I care to admit tracking down why some union operations were producing unexpected duplicates in actual work, not abstract math problems. The concept itself is trivial. Applying it cleanly is where things get annoying.
Understanding the Definition Of Union In Math
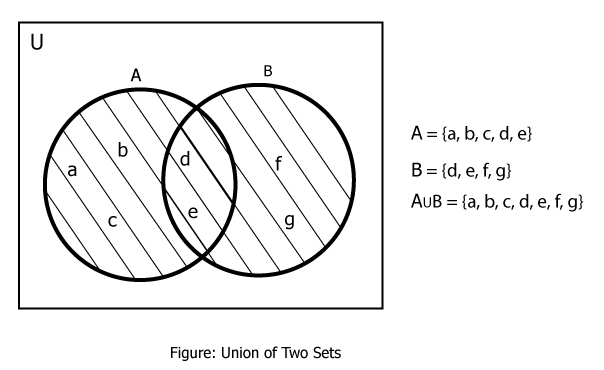
Let me start with the mechanics because that's where most people trip up before they even get to the definition. If A = {1, 2, 3} and B = {3, 4, 5}, then A B = {1, 2, 3, 4, 5}. The element 3 is in both sets, but it only appears once in the union. Sets don't track multiplicity. That's basic set theory, yes, but it matters enormously when you're working with real data structures instead of neat little collections of numbers. Formally: A B = {x : x A or x B}. The "or" here is inclusive, which people sometimes gloss over. An element belonging to both sets still belongs to the union. There's no exclusion mechanism built in unless you explicitly write one.
The definition sounds simple enough, and it is. But the way you actually compute unions changes dramatically depending on what kind of sets you're dealing with. Finite sets you can merge by inspection. Infinite sets require you to think about whether you're even working in a framework where that makes sense. Lebesgue measurable sets behave differently from non-measurable ones. The operation is the same symbol, but the properties of the result depend entirely on context.
Get the Full Details
How to Compute Unions Without Wasting Your Time
Here's the thing about set unions that nobody tells you: the naive approach works fine until it doesn't, and when it breaks, it breaks in subtle ways. For finite sets represented as arrays or lists, the standard approach is to combine them and deduplicate. In Python, that's trivial with sets: A = {1, 2, 3}
B = {3, 4, 5}
result = A.union(B) {1, 2, 3, 4, 5}
But I ran into a problem once where I was merging union results across a nested structure, and I had sets containing unhashable types like lists inside them. The standard union operation threw a TypeError because you can't hash a list. The fix was to convert the inner lists to tuples first, do the union, then convert back if I needed lists in the output. Took me about twenty minutes to trace through and figure out what was happening, which felt ridiculous for such a basic operation. For infinite sets described by properties rather than enumeration, you write out the condition. If A = {x ℝ : x > 0} and B = {x ℝ : x < 2}, then A B = {x ℝ : x > 0 or x < 2}, which simplifies to all real numbers except zero itself—wait, no. Let me reconsider that. A B would be {x ℝ : x > 0 or x
2}, and since every real number is either greater than 0 or less than 2 (or both), this actually covers all of ℝ. The union is just the entire real line. Easy to miss if you're not checking edge cases like x = 0 carefully. When working with intervals, unions can sometimes simplify. (0, 2) (1, 3) = (0, 3) because the intervals overlap. But (0, 1) (2, 3) stays as two separate pieces. Knowing when intervals merge versus stay disjoint is something you develop through repetition, not really something you memorize.
Where People Go Wrong
The most common mistake I see is treating union like it's the same as intersection. People will write down A B when they mean A B, or they'll assume the union operation somehow filters for only shared elements. It doesn't. The union accumulates everything. Intersection is the one that filters. Another frequent error is forgetting that the union is commutative. A B equals B A. This seems obvious until someone writes code that depends on order, which shouldn't happen with pure set operations but does in practice because of how data is represented under the hood. Order matters for lists. It doesn't matter for sets. Mixing those two mental models up causes bugs. A subtler issue: people don't always check whether their sets are even well-defined in the context they're working in. If you're doing measure theory and you take a union of measurable sets, fine, the union is measurable (for countable unions at least). But an uncountable union of measurable sets can fail to be measurable. That's not a gotcha about the union operation itself, it's a gotcha about assuming everything works the same way across different branches of mathematics.

The associative property also trips people up indirectly. (A B) C = A (B C), yes, but when you're writing out proofs or computing by hand, the grouping can change how obvious intermediate results are. Sometimes computing A B first reveals a simplification that makes the final step trivial. Sometimes it obscures it. There's no universal rule, just experience.
Properties That Actually Matter in Practice
Distributivity over intersection is the property I find most useful in actual work. A (B C) = (A B) (A C). This comes up constantly when you're simplifying expressions or rewriting conditions. If you're working with logical predicates or set-builder notation, this equivalence lets you restructure problems in ways that make them computationally cheaper or easier to reason about. De Morgan's laws connect union and intersection through complementation. (A B)^c = A^c B^c and (A B)^c = A^c B^c. These are essential when you're trying to express a negated condition in terms of simpler pieces. I've used these repeatedly when debugging conditions in code where the logic was inverted or nested in a way that made the intent unclear. Idempotence is another property worth keeping in mind. A A = A. This seems pointless until you're writing code that unions a set against itself multiple times through some recursive or iterative process, and you're wondering why the result isn't growing. It won't grow. That's the point.
There's also the empty set case. A = A. Again, obvious, but I've seen this matter when empty sets propagate through a pipeline of operations and someone forgets to account for them, leading to incorrect assumptions about whether a union actually added anything new.
A Real Problem I Faced
Once I was working with a collection of intervals that needed to be unioned together, and the input wasn't sorted. Merging overlapping intervals is a standard problem, but the standard algorithm assumes you sort first. I tried a direct union approach without sorting and ended up with overlapping intervals in the output that should have been collapsed. The result was technically correct as a set—the points were all there—but it was unusable for whatever downstream computation I needed. The workaround was straightforward: sort by start point, then iterate through and merge any overlapping or adjacent intervals. This reduced the representation from O(n²) intervals down to something manageable, usually close to linear in the number of distinct merged regions. On a dataset of about ten thousand intervals, this cut the post-processing time from something unbounded down to roughly a second. Sorting dominated the cost, and it was worth it. I wish I'd done that first instead of trying to patch the broken output. It's one of those things you learn early and then forget under pressure.
When Union Operations Fail Completely
Let me be honest about limitations. Set union as defined in naive set theory runs into problems when you try to use it with unrestricted comprehension. The barber paradox and Russell's paradox exist for exactly this reason. You can't just take the union of "all sets that don't contain themselves" in a consistent framework. Modern set theory handles this with axioms that restrict how unions can be formed, but if you're working in a context that isn't carefully bounded, the operation can lead to contradictions. In computer science, union on very large datasets can consume disproportionate memory. A union of two sets each containing millions of elements creates a new structure that may hold all of them, and if you're doing this repeatedly in a loop, you're generating garbage that the runtime has to clean up. In performance-critical applications, in-place modification or incremental union approaches are often necessary. Python's set.union returns a new set. If you need to update in place, use the |= operator or set.update instead. There's also the question of what happens when your "sets" aren't actually sets. Multisets treat union differently—you keep the maximum multiplicity of each element rather than collapsing to one. Fuzzy sets use the maximum membership grade. Type systems in programming languages sometimes define union types where the semantics are closer to intersection than to set union. If you're reading documentation and someone says "union" without specifying which variant they mean, verify before you proceed. Getting this wrong produces output that looks plausible but is semantically incorrect.
For practical purposes, knowing what you're working with and being explicit about it saves more time than any amount of cleverness. The union operation itself is a one-liner. Understanding when it does what you think it does is the actual work.