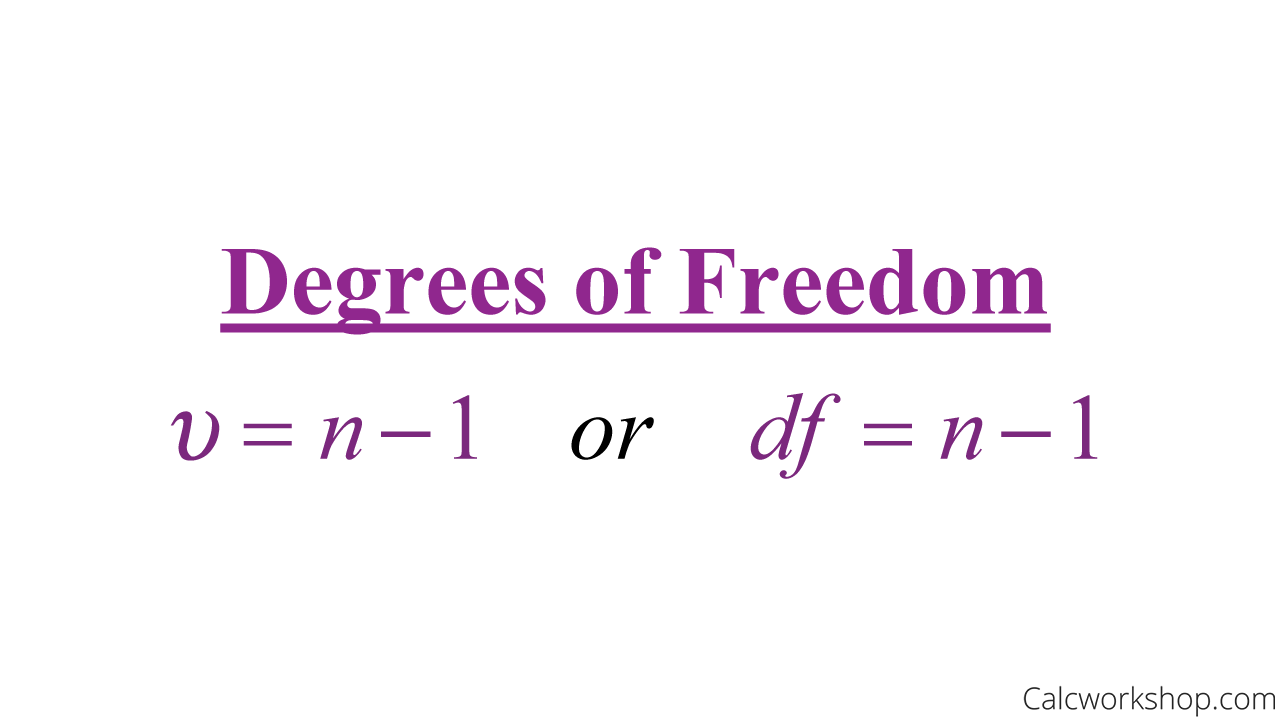
Working With Degrees of Freedom in Practice
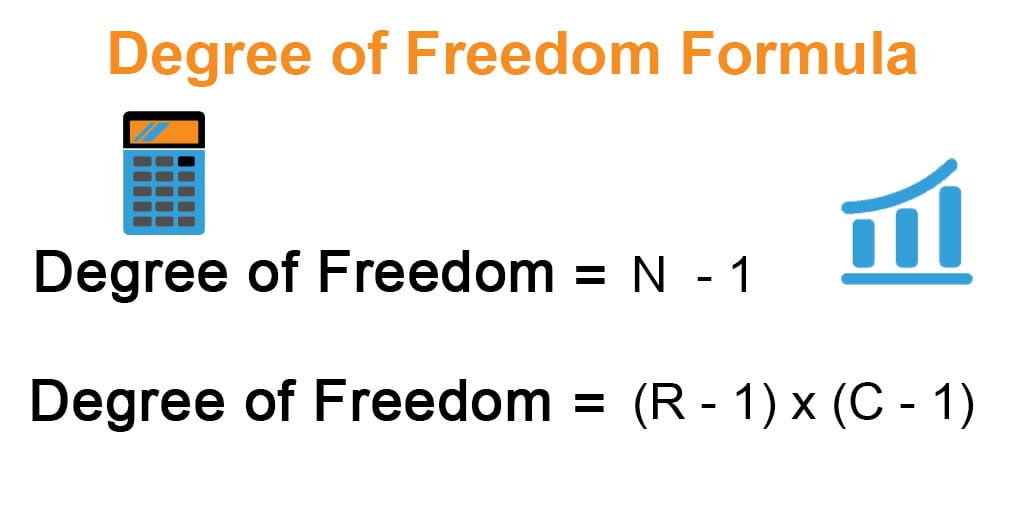
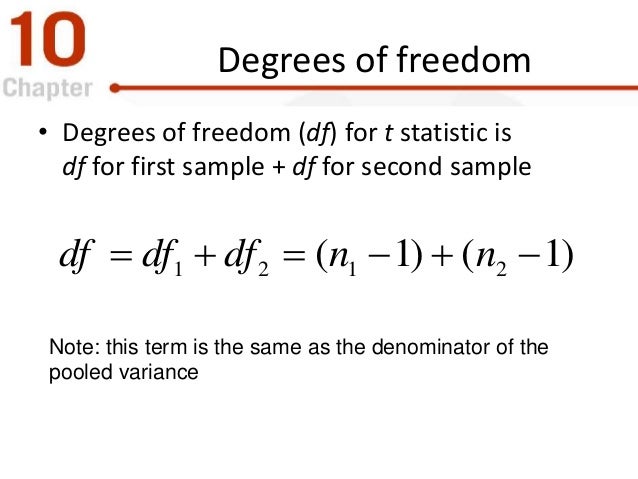
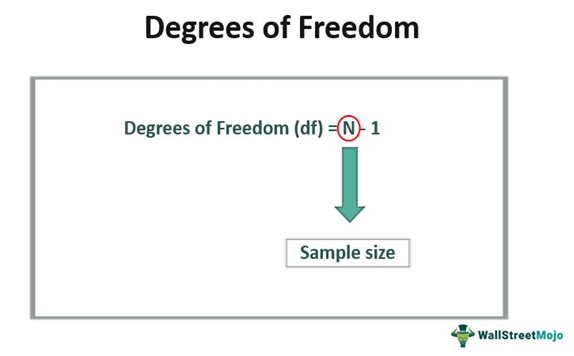
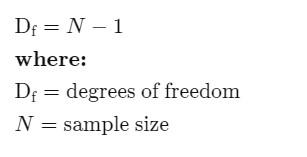
The Degree Of Freedom Formula is essentially a counting exercise that tells you how many independent values you can freely change in a system before everything else locks into place. In statistics it's most commonly expressed as n minus 1, but the idea extends across engineering, physics, and experimental design in ways that matter more than textbooks usually admit. Take a sample of size n. If you know the mean, you only have n minus 1 independent pieces of information because the last value is forced to make the average match. That subtraction isn't arbitrary. It's the number of constraints you've placed on the data. In ANOVA, the formula expands: degrees of freedom for the numerator become k minus 1 where k is the number of groups, and the denominator gets n minus k. You're still counting constraints, just partitioning them by source of variation. I remember running a two-way ANOVA on some response time data last year and getting absurdly low p-values that didn't replicate. The problem wasn't my analysis software. It was that I had heavily unbalanced groups with very different variances, and I hadn't accounted for the fact that the effective degrees of freedom were being inflated by the model structure. I ended up switching to a Welch's ANOVA approach and then using a bootstrap to confirm the result. Cut two days of back-and-forth down to a single afternoon once I stopped forcing the data into a standard textbook framework.
How To Calculate It Step By Step
First, define what system or model you're working with. Are you calculating for a t-test, an ANOVA, a regression, or a mechanical linkage? Each one uses the same core idea but applies it differently. For a one-sample t-test, take your sample size and subtract one. For a chi-square goodness of fit, it's the number of categories minus one minus the number of parameters you estimated from the data. For linear regression, it's n minus p minus one where p is the number of predictors. Track every constraint you impose. Every estimated parameter, every boundary condition, every fixed value subtracts from your freedom. Most people miss the ones that come from estimation. If you calculate the mean from your data to then test against that mean, that's already one constraint. If you estimate a variance as well, that's another in some contexts. One thing that trips people up constantly: degrees of freedom aren't just about sample size. They're about the relationship between your data and your model. A regression with five predictors and 30 observations has 24 degrees of freedom. A regression with the same five predictors and 30 observations but three of those predictors are perfectly collinear effectively has fewer because the model can't distinguish their individual contributions. You need to check that your design matrix has full rank before trusting the output.
Where It Breaks Down
The formula assumes your observations are independent. If you have repeated measures, clustered data, or time series, the effective degrees of freedom drop somewhere between your nominal value and one, depending on how correlated your data points are. I've seen people use standard t-test formulas on paired longitudinal data and end up with confidence intervals that were far too narrow. The fix isn't a different formula on paper, it's recognizing that your effective sample size is smaller than your raw count. Multilevel models or generalized estimating equations handle this better, though they come with their own assumptions and convergence headaches. Another blind spot: small samples with high-dimensional models. When n is close to p, the degrees of freedom become so low that power collapses and p-values stabilize near random. Regularization methods like ridge or lasso sacrifice unbiasedness to recover some estimation stability, but you're no longer doing standard hypothesis testing in the traditional sense. You need to be honest about what you're actually measuring. If you want the reference sheets I use, the NIST engineering statistics handbook has clean tables for the common cases and they update freely online. Most university stats department websites also have worked examples that go beyond the basic textbook version.
Get the Full Details