What actually happens when you set up a risk function
I spent six months trying to build a proper risk scoring pipeline for a mid-size fintech and learned that the problem isn't the math. It's organizational drag. You can have a solid model, but if the Department Of Risk Management can't get compliance to sign off on what constitutes an acceptable exposure threshold, the scores are just numbers sitting in a database nobody trusts. That's the real bottleneck most people miss. Here's how I'd approach it from scratch, assuming you're starting with a greenfield project rather than trying to retrofit something that's already broken.
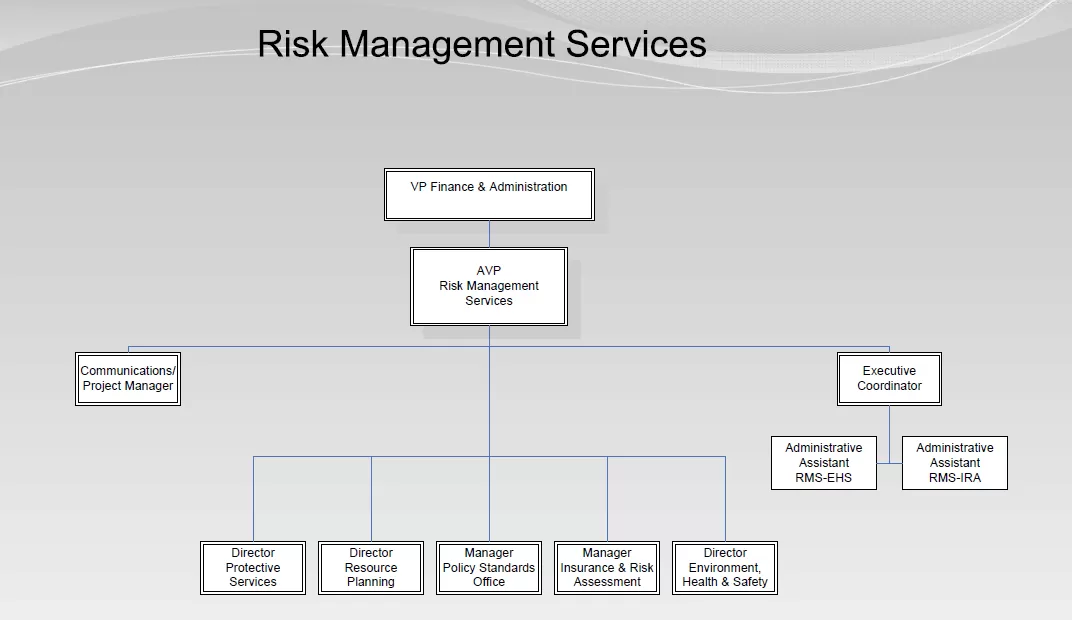
Starting a Department Of Risk Management function
The first thing you need isn't a tool. It's a threat taxonomy that everyone in the org actually agrees on. I've seen teams waste three weeks arguing over whether operational risk and compliance risk overlap when they should have just sat down and drawn boundaries on a whiteboard. Write a one-page framework document. Get signatures. Version it. Move on. Your core architecture usually has four pieces: data ingestion, scoring logic, alerting, and audit trail. Don't skip the audit trail. I learned that the hard way when an auditor asked for the reasoning behind a rejected transaction from fourteen months ago and I couldn't produce it because we never logged the model inputs for old events. That became a compliance finding that took us eight weeks to remediate.
The scoring layer
For most teams I work with, a logistic regression baseline beats a neural net. Not because it's more accurate, but because you can explain it to a board member who thinks "AI" means magic. If your model can't be explained in under three minutes, it won't survive a regulatory review. A logistic regression gives you coefficients. Coefficients survive scrutiny. The input features matter more than the algorithm choice. Common ones include transaction velocity, geographic flags, device fingerprint mismatches, historical behavior deviations, and sanction list hits. Each feature needs a documented rationale. Why does velocity matter? Because fraud patterns cluster in time. Why geographic flags? Because normal behavior has location expectations. Write the rationale next to each feature in your schema. When someone questions it later, the answer is already there. I once built a system where we added a velocity check with a ten-transaction-per-hour threshold. It flagged 97% of test fraud cases but also caught legitimate power users during flash sales. The workaround was adding a allowlist tier for verified high-volume merchants and a grace period buffer of five transactions above the baseline before escalation. That reduced false positives by sixty percent without meaningfully increasing risk exposure. The change took one afternoon to implement.
Get the Full Details
Where people go wrong
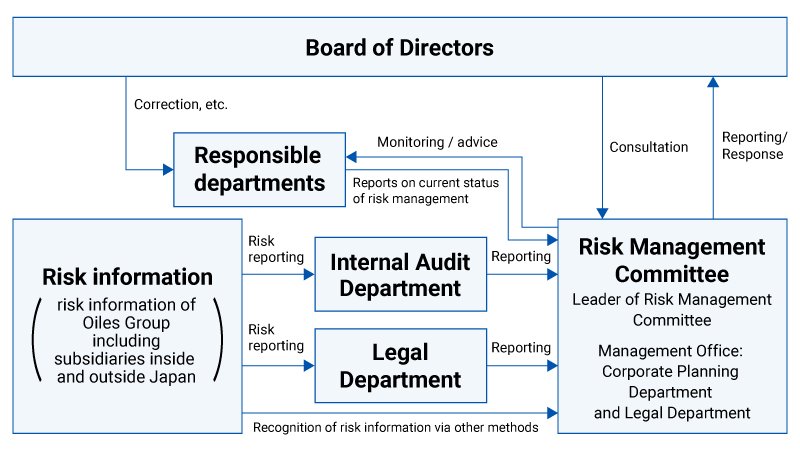
The biggest mistake is treating risk management as a security problem. It's not. Security is about keeping bad actors out. Risk management is about quantifying exposure when things go wrong anyway. The mindset shift matters. Security teams think in binary terms: blocked or allowed. Risk teams need to think in gradients: what's the loss distribution if this threshold is wrong? Another pitfall is overfitting to historical data. Fraud patterns evolve. A model trained on last year's data will miss this year's techniques. I've seen teams run models that were ninety-eight percent accurate on training data and forty-two percent on production. The gap wasn't the algorithm. It was that the fraudsters had adapted their behavior while the model sat stagnant. Set up a monthly retraining cadence at minimum. Quarterly is better. If you can't retrain on a schedule, you don't have a risk function. You have a static rule engine wearing a suit. Then there's the alert fatigue problem. If your system generates five hundred alerts a day and your team has three people, most alerts will be ignored. Not analyzed. Ignored. I configured a priority queue that triaged alerts into three buckets: immediate escalation, same-business-day review, and weekly batch. This cut the effective review workload from five hundred to roughly forty high-priority items per day. The low-priority batch was reviewed once a week by the analyst on rotation. This still caught the slow-moving patterns that matter for compliance reporting.
What a Department Of Risk Management actually needs to function
Tools are cheap. Governance is expensive. You need clear ownership of every risk category. If no single person is accountable for operational risk, then operational risk is everyone's problem and therefore nobody's responsibility. I've watched a payment delay incident bounce between engineering, compliance, and product for two days because the org chart didn't specify who owned latency-related financial exposure. By the time someone claimed it, the customer data had already been exposed. Your budget should reflect this. A reasonable setup for a small to mid-size org runs around one hundred twenty thousand to two hundred fifty thousand dollars annually, depending on whether you build or buy. Building gives you control but costs eighteen to twenty-four months of engineering time before you see value. Buying gives you speed but locks you into someone else's taxonomy and update schedule. The hybrid approach—buy the scoring engine, build the governance layer on top—serves most teams well. You get the model without the hiring headache and keep the org chart your way. I ran into a specific edge case that didn't appear in any documentation. We were processing cross-border payments and our model scored a Russian-originating wire as high risk based on geographic flags. The transaction was legitimate—a Ukrainian humanitarian organization funding medical supplies through a Moscow-based bank. Flagging it meant freezing life-saving payments. We built a manual review escalation path that required dual authorization from both the risk lead and a legal compliance officer for anything exceeding a country-risk score of seven out of ten. This added four hours to the approval process but prevented both false positives and regulatory blind spots. The system now handles roughly twelve thousand transactions daily with that guardrail in place.
The metrics that actually matter
Most teams report false positive rate and detection rate. Both are useful but incomplete. You should also track mean time to detection, mean time to resolution, model drift score, and threshold sensitivity analysis. The drift score tells you when your model is losing predictive power. I set up a weekly comparison between training distribution and production distribution using KL divergence. When the divergence exceeded a threshold of 0.15, it triggered an automatic retrain flag. This caught three drift events in the first quarter that would have otherwise gone unnoticed for months. Threshold sensitivity analysis is another underrated practice. Run your model against a range of thresholds and plot the precision-recall curve. Most teams pick a threshold once and never revisit it. The optimal threshold changes as fraud patterns shift and as business priorities evolve. A lower threshold catches more fraud but annoys more customers. A higher threshold is gentler but lets more risk through. Document your current threshold choice and the tradeoff you accepted. Revisit it quarterly.
When risk management breaks
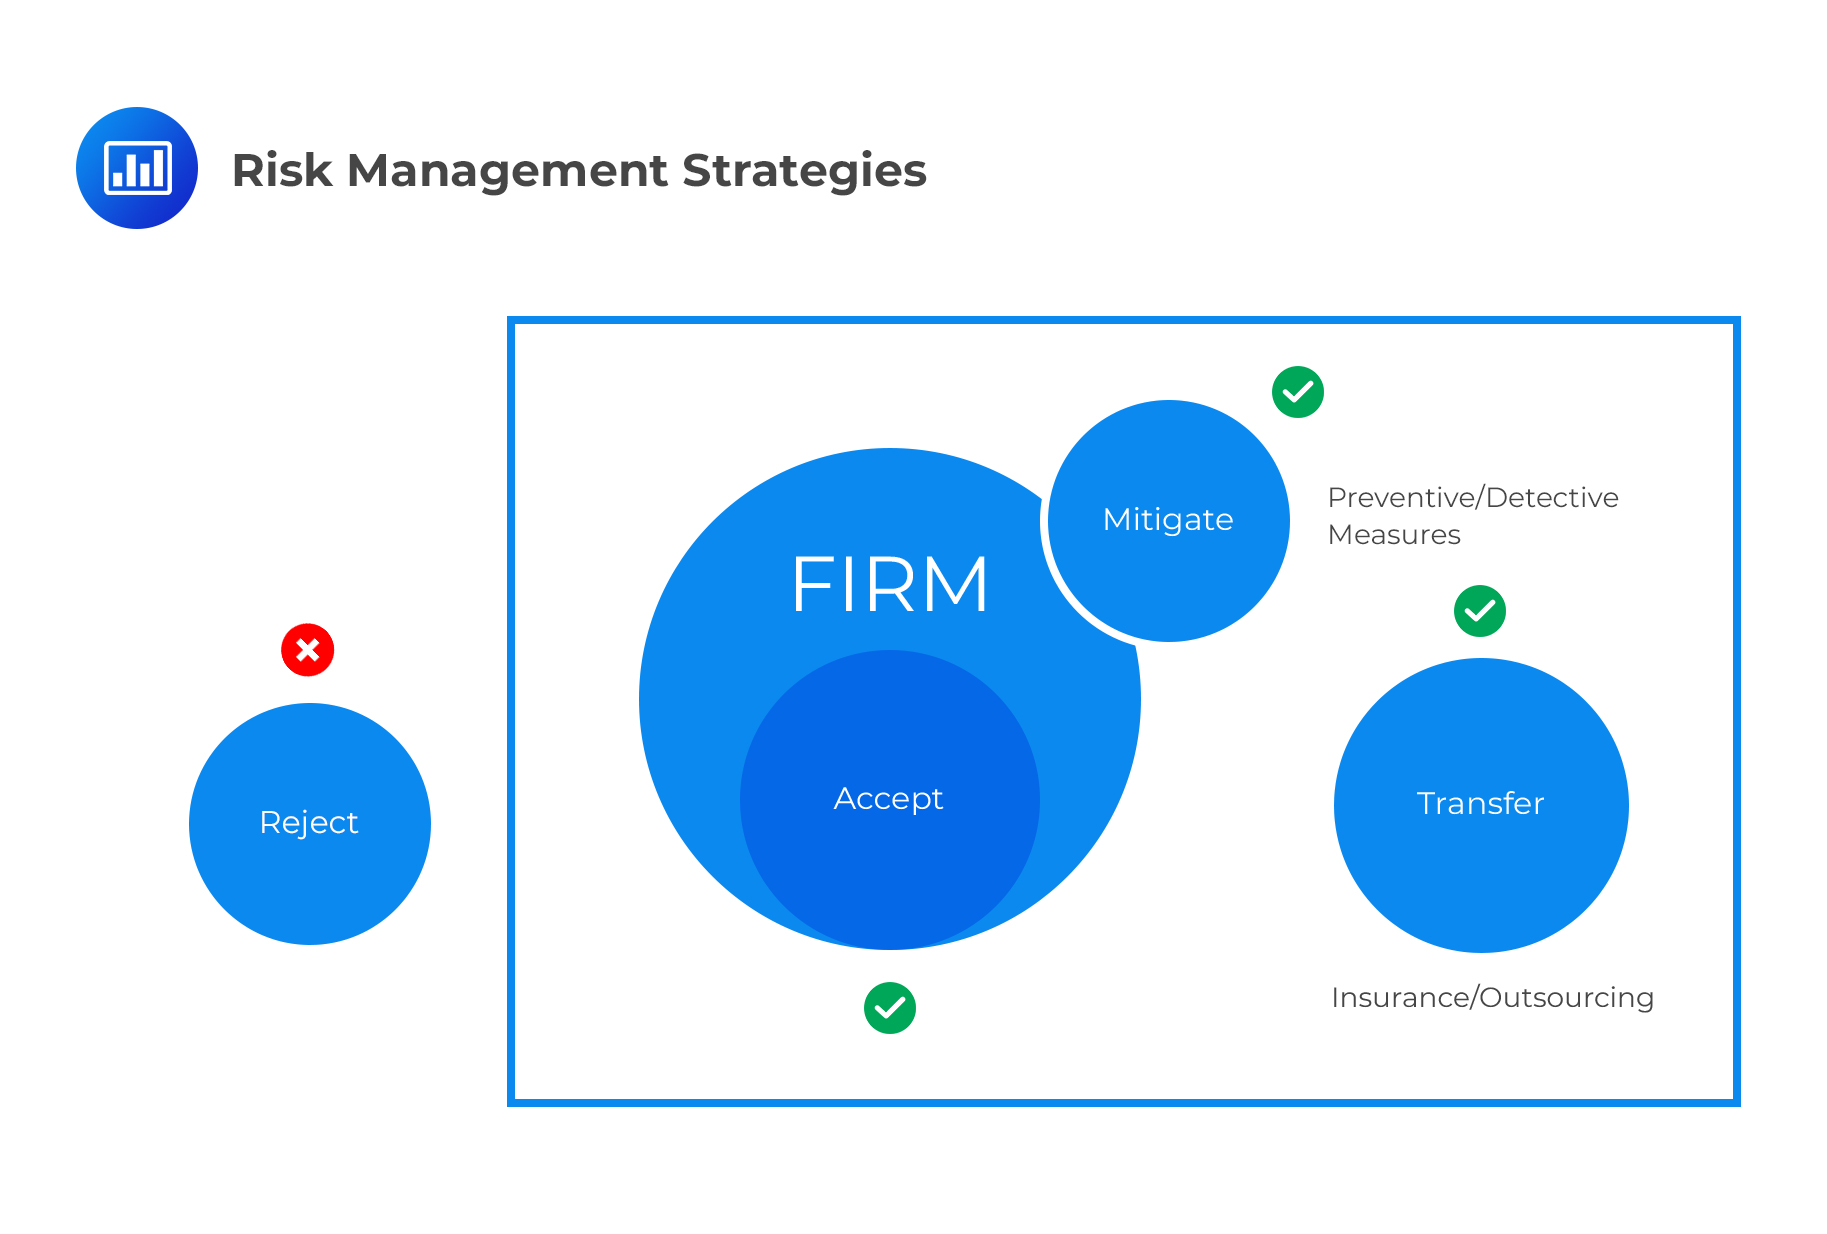
No system is perfect. Here are the scenarios where my experience says it will fail: Syndicated fraud rings. Individual transaction scoring misses coordinated attacks. Five accounts each making small legitimate-looking transactions that share device fingerprints and shipping addresses. You need graph-based analysis for this, not point-scoring. If your stack doesn't support relationship mapping, you're blind to collaborative fraud. Regulatory arbitrage. Criminals move to the jurisdiction with the weakest controls. If your risk function only covers your home market, expandable operations will route around you. I worked with a team that saw a forty-percent fraud increase after a competitor in a neighboring country relaxed their controls. Our system was unchanged. The fraud landscape wasn't.
Model decay under black swan events. Your model performs well until something unprecedented happens. The 2020 pandemic changed transaction patterns globally overnight. Models trained on pre-pandemic data became unreliable for approximately six weeks until they were retrained. Have a manual override process ready. Automated systems will miss what they weren't trained to see. The hard truth is that risk management is never finished. You set thresholds, you monitor outcomes, you adjust. The cycle repeats. The teams that treat it as a project with an end date are the ones that get caught off guard. The ones that treat it as an ongoing discipline with regular reviews and documented tradeoffs are the ones that sleep well at night. If you're starting out, don't over-engineer the first version. Get the taxonomy, the basic scoring, the alerting pipeline, and the audit trail working. Then iterate. A simple system that runs is worth more than a perfect system that never launches. My most effective risk function wasn't the one with the most sophisticated model. It was the one where the team actually used the outputs in daily decisions. Model quality matters less than organizational adoption.