Setting Up Your First Experiment
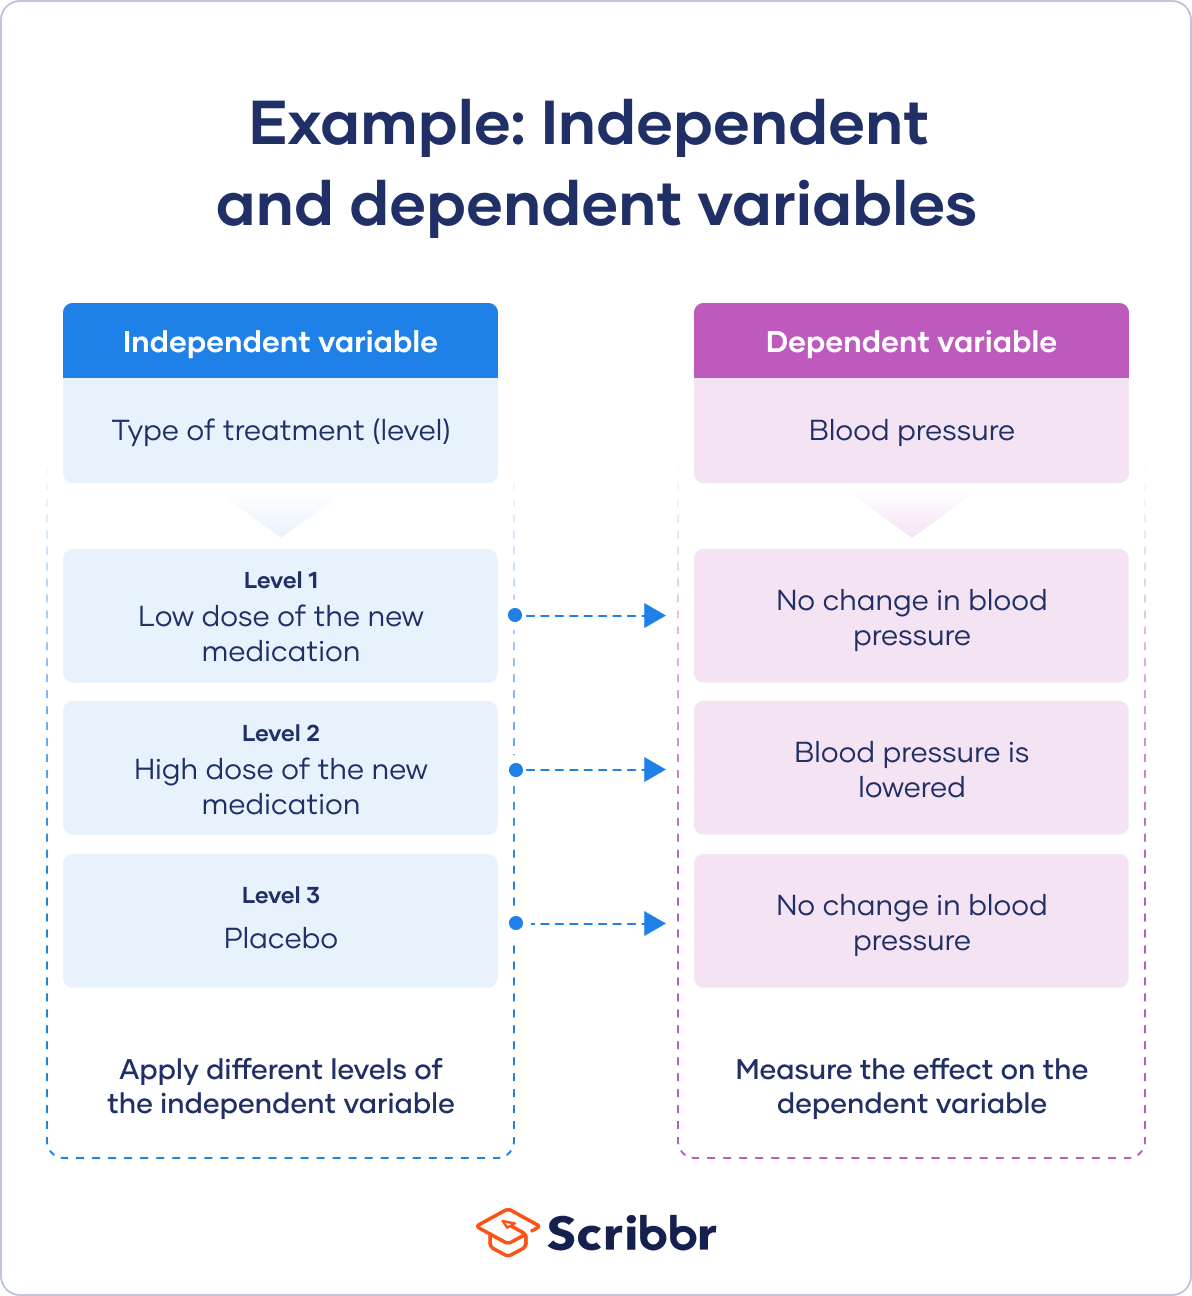
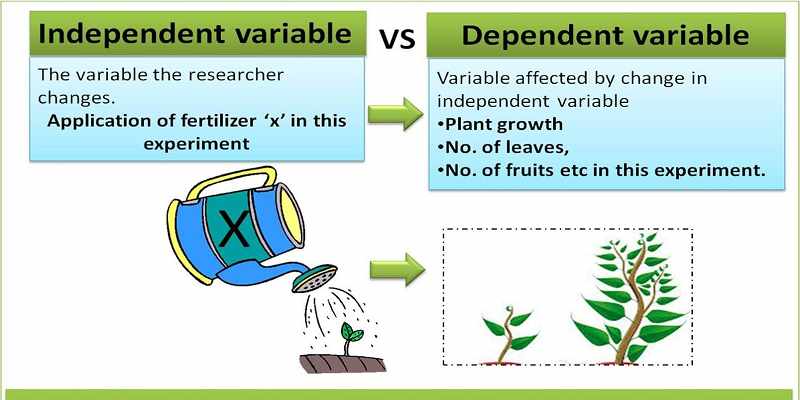
I spent three months wrestling with a regression model where the results kept flipping direction depending on which variable I treated as the input. It wasn't a math error. It was a conceptual one. I had confused what was driving the system with what was responding to it. This is the core of the Dependant Vs Independent Variable problem, and it shows up constantly in fields from econometrics to clinical trials. The independent variable is what you control or categorize. The dependent variable is what you measure as the outcome. That definition is correct but useless on its own because real data rarely respects those categories cleanly.
Understanding the Dependant Vs Independent Variable Relationship
In a controlled lab setting, the distinction is usually straightforward. You change temperature and measure reaction rate. Temperature is independent. Reaction rate is dependent. But outside a controlled environment, you spend most of your time dealing with observational data where causation is murky at best. A colleague of mine once ran a logistic regression to predict patient readmission rates using hospital stay duration as the independent variable. The model produced a statistically significant coefficient. Then a clinician pointed out that longer stays are often a result of complications, which are also what drive readmissions. The variable was simultaneously a cause and an effect, which completely broke the causal interpretation. I've seen this happen in marketing attribution models too. Conversion rate gets modeled as dependent on ad spend, but the ad spend itself is adjusted weekly based on conversion performance. The feedback loop means neither variable is truly independent. The workaround in my experience is to treat the relationship as directional rather than strictly causal. Use temporal ordering when possible. If the supposed independent variable must exist before the dependent variable can change, that's one data point in favor of the model. Lag structures in time series data help here. A distributed lag model where past values of X predict current values of Y removes some of the simultaneity problem without requiring a randomized controlled trial.
Common Mistakes That Break Your Analysis
The biggest mistake I see is reversing the variables after you've already collected data. Someone will build a model, get unexpected results, and then swap which variable is X and which is Y to make the coefficients look better. That doesn't fix the model. It just changes the interpretation. The statistical relationship between two variables is symmetric in correlation but asymmetric in regression. Switching X and Y changes the slope, the intercept, and the R-squared interpretation. The Pearson correlation stays the same, but that's not what you're using the model for. Another issue is treating categorical variables as if they're continuous when they're not. I once reviewed a study where socioeconomic status was coded as a single numeric variable ranging from one to five. The researcher treated it as interval data and ran a linear regression. The coefficients implied that moving from category three to four produced the same change in the outcome as moving from one to two. That assumption was unsupported and misleading. The fix is either to treat the variable as ordinal with appropriate modeling or to dummy code it and interpret each category separately. Both approaches are more work. Neither gives you a false sense of precision. Measurement error in the independent variable is another quiet model killer. When X has noise, the regression coefficient gets attenuated toward zero. This is called attenuation bias and it means your effect size is systematically underestimated. The bigger the measurement error relative to the true variance in X, the worse it gets. Instrument calibration issues, self-reported data, and proxy variables all introduce this problem. I learned to check the reliability of my independent variables before running any model. A Cronbach's alpha below 0.7 for a multi-item scale is a warning sign. Single-item measures are even worse but far more common in industry datasets than you'd expect.
Get the Full Details

When the Framework Falls Apart
There are scenarios where the independent-dependent variable structure simply doesn't work. Systems with strong feedback loops resist this framing entirely. Economic supply and demand, ecosystem dynamics, and most organizational behavior models involve mutual determination. Forcing one variable into the independent slot and another into the dependent slot produces a model that describes only one direction of a bidirectional relationship. Structural equation modeling handles this better by allowing reciprocal paths, but it requires larger sample sizes and stronger theoretical assumptions about the direction and magnitude of each path. Another limitation is that the framework assumes you can identify at least one variable that isn't influenced by the outcome. In practice, hidden confounders often violate this assumption. An unmeasured variable affects both your supposed independent and dependent variables, creating a spurious relationship. Randomized experiments solve this by design. Observational studies never fully solve it. Propensity score matching, instrumental variable approaches, and difference-in-differences designs attempt to approximate randomization but each comes with its own set of assumptions that are rarely testable with the data at hand. If you're working with purely correlational data and need actionable insights, I recommend treating your model as a prediction tool rather than a causal one. Forecasting frameworks don't require clean variable separation. They only require that past patterns hold going forward. That's a weaker claim but often a more honest one. Causal claims require evidence that goes beyond what a single regression can provide. The Dependant Vs Independent Variable distinction is a useful starting point for organizing your thinking. It becomes dangerous when you forget that it's a simplification of reality, not reality itself.