Understanding Derivatives and Their Role in Real Problems
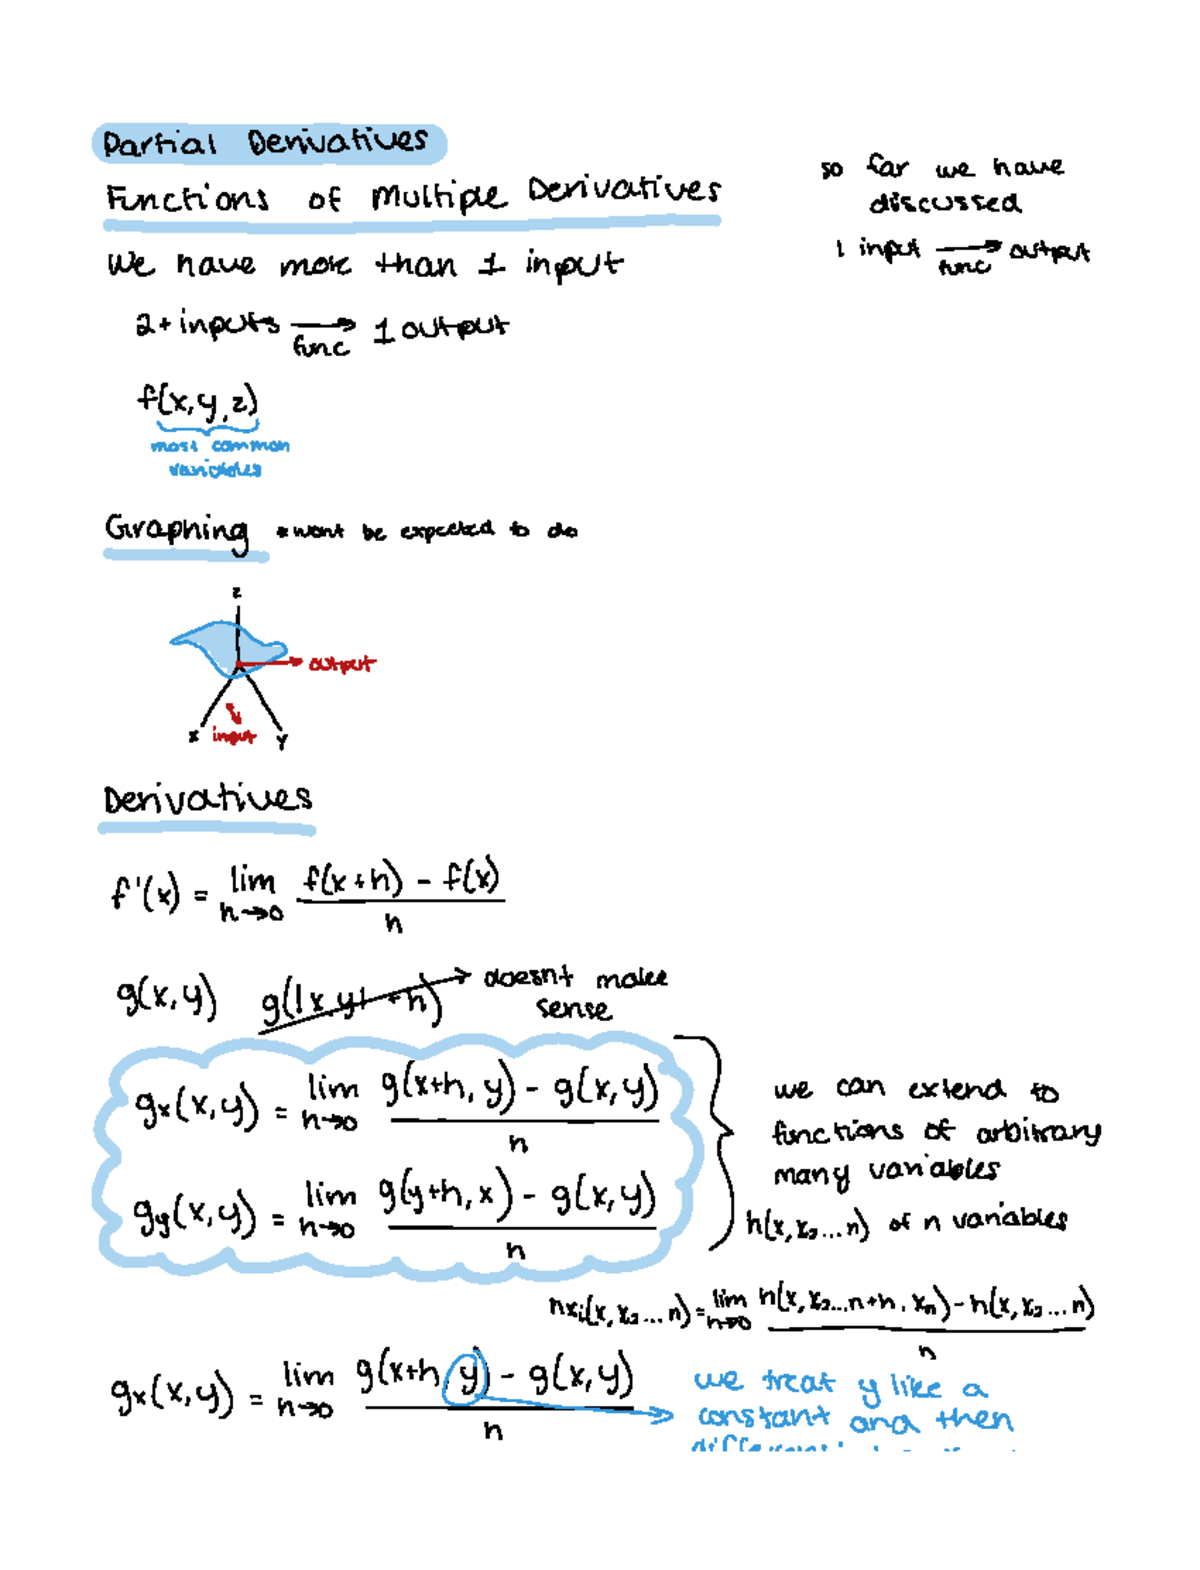
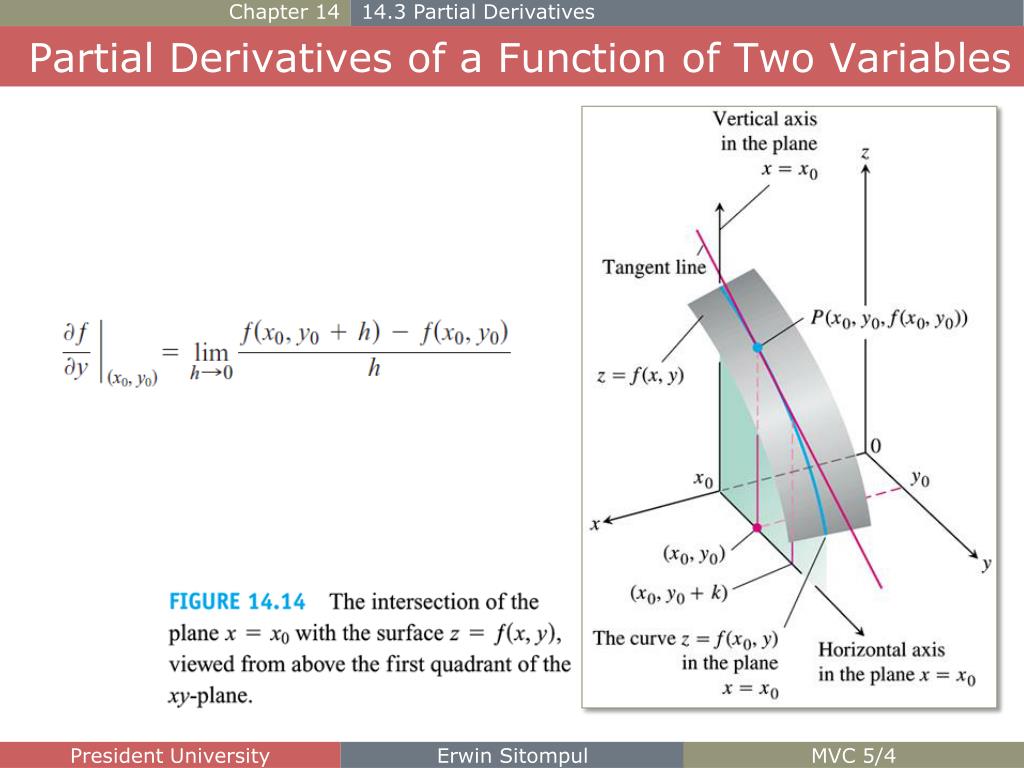
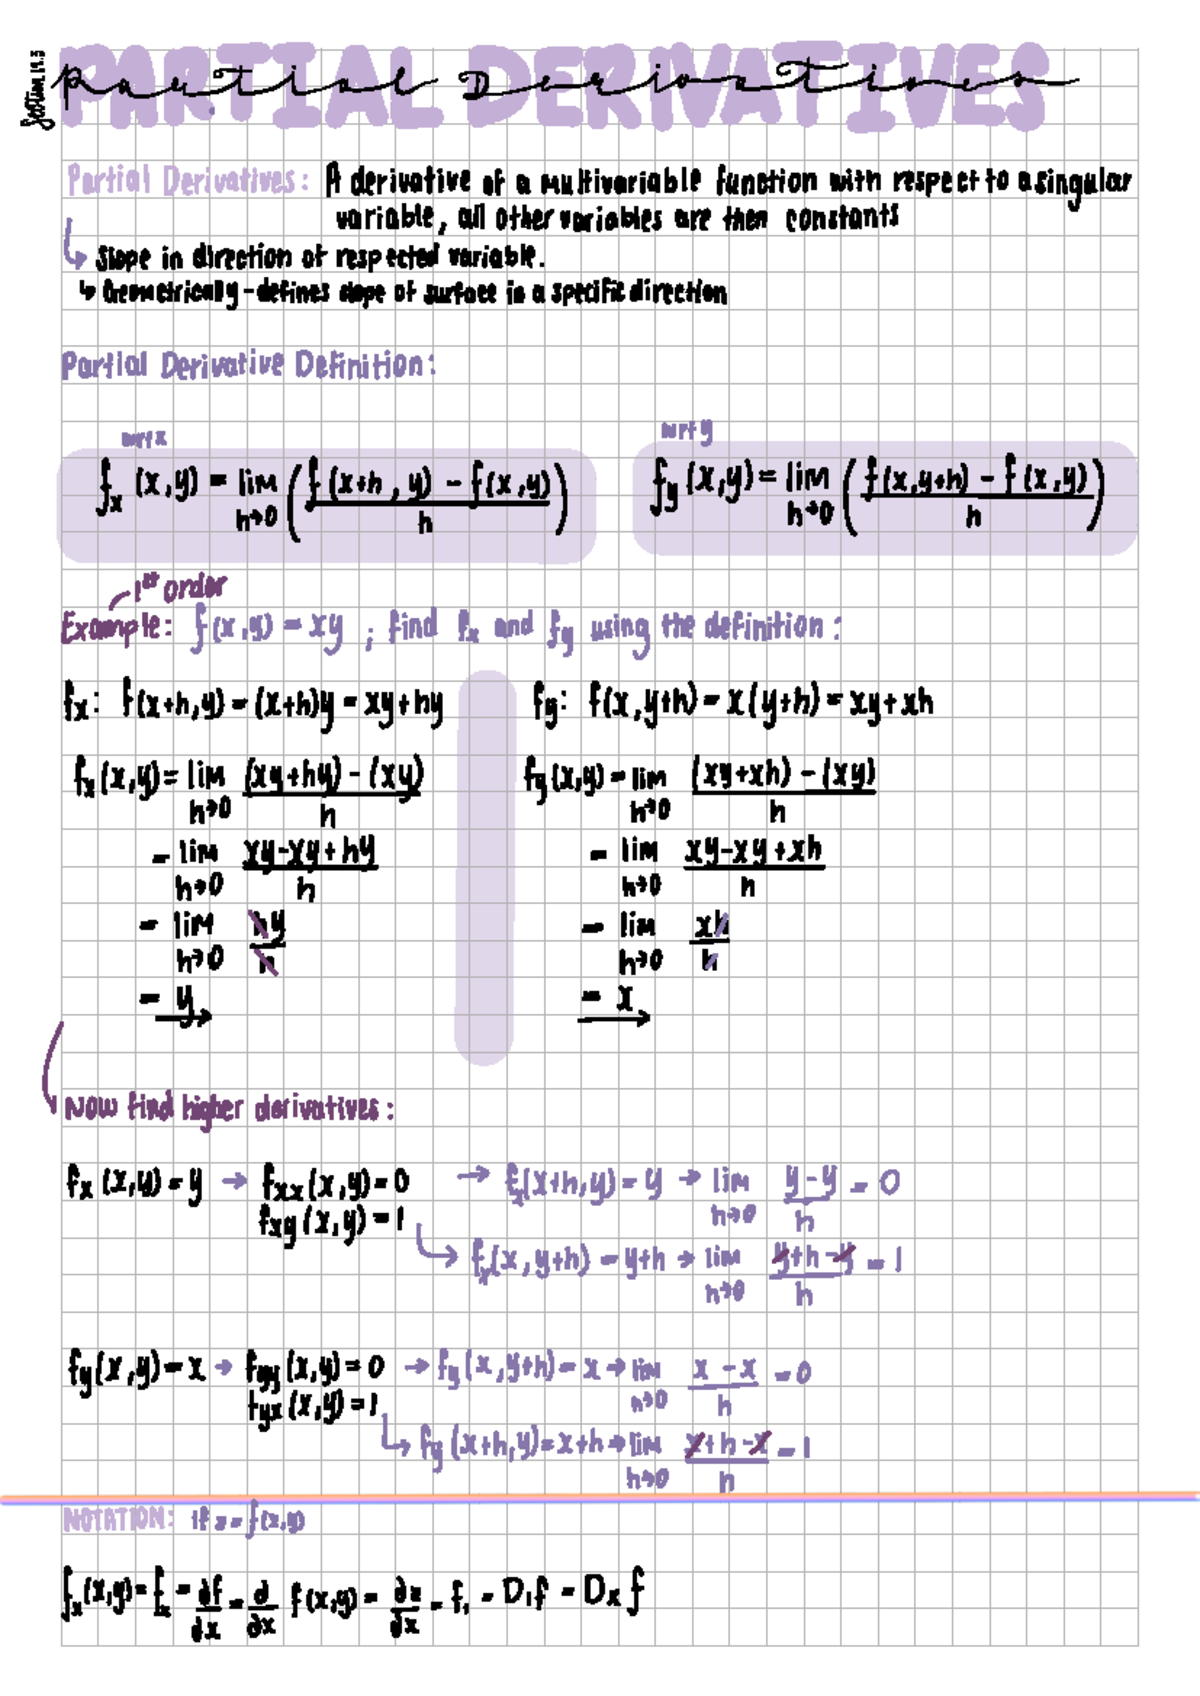
Derivatives are just rates of change, said more formally as the slope of a curve at a specific point. In practice, you use them when something depends on multiple variables and you need to know how a small shift in one variable affects the outcome while holding everything else constant. That second part is where partial derivatives come in, and honestly most people mix the two up early on because textbooks present them as if they're entirely different subjects. They aren't. I spent years working on optimization problems for engineering systems, and the first thing I learned was that derivatives alone don't solve anything. You need to set them correctly and interpret them right. A derivative tells you direction and steepness. It doesn't tell you whether a critical point is a maximum, minimum, or saddle point without further analysis.
Derivatives And Partial Derivatives in Practice
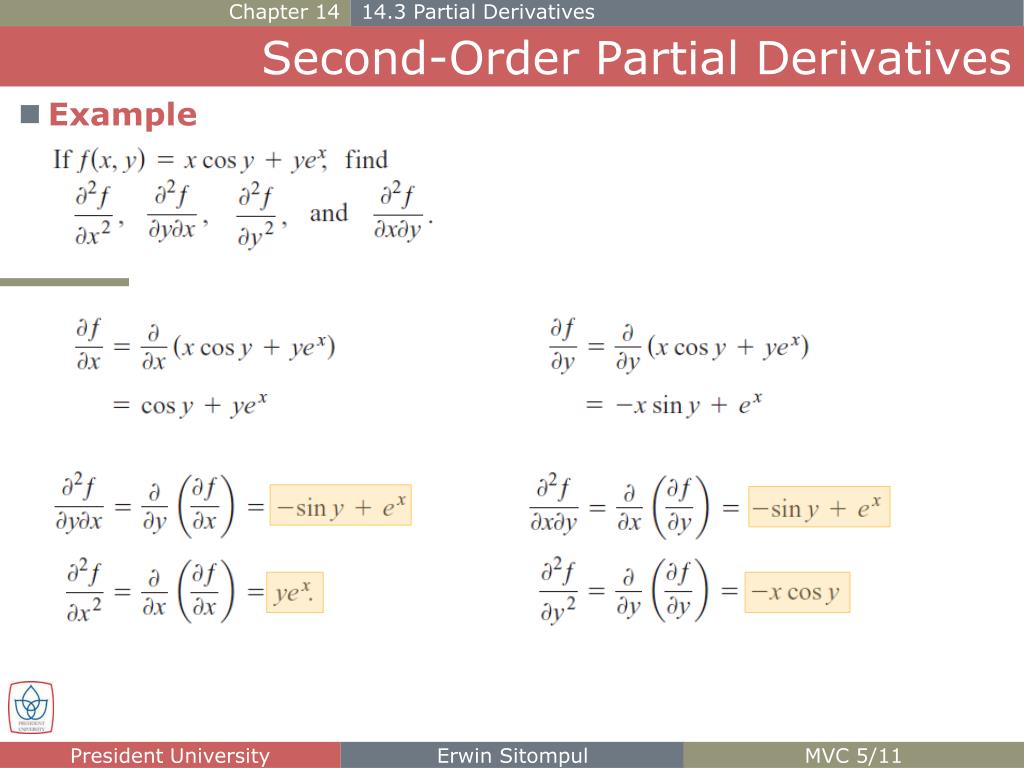
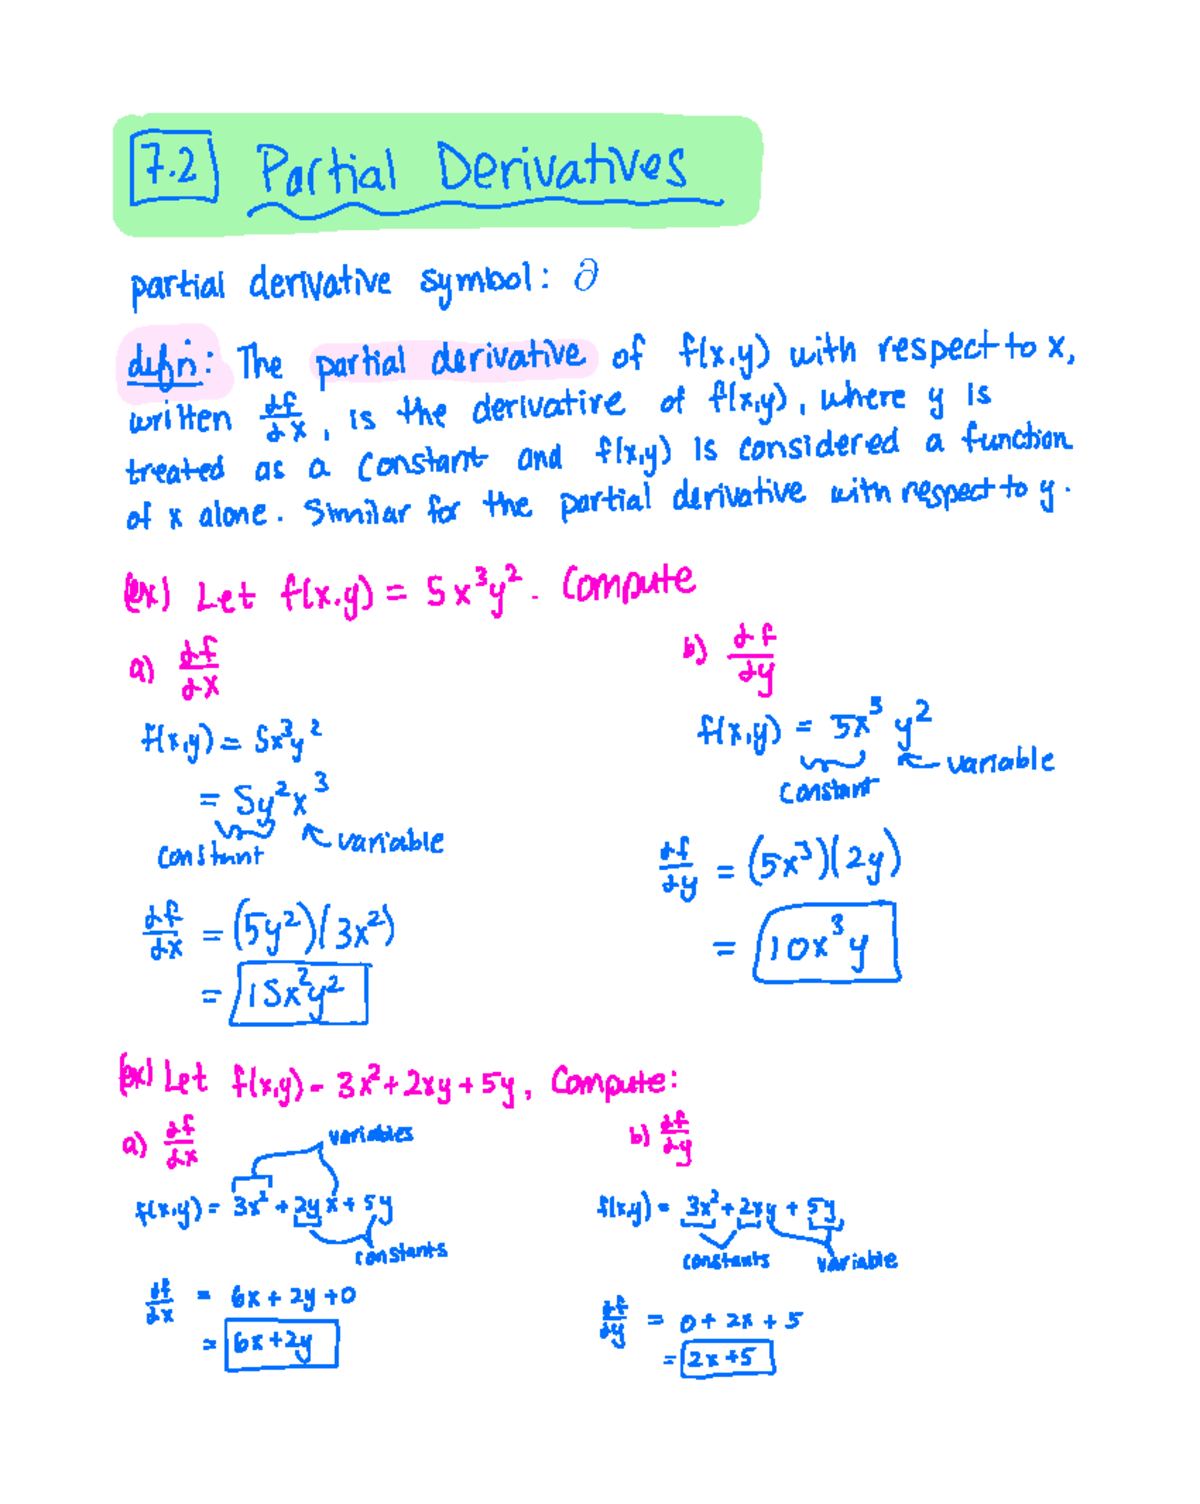
Let me show you how this actually works instead of giving you abstract definitions. Say you have a function f(x,y) = 3x² + 2xy + y² - 4x. You want to find where this function reaches a minimum, maybe because that function represents cost in a manufacturing setup and x and y are material quantities. To find critical points, you take the partial derivative with respect to x and set it equal to zero, then do the same for y. The partial with respect to x gives you 6x + 2y - 4 = 0. The partial with respect to y gives you 2x + 2y = 0. Solving these simultaneously, you get x = 2 and y = -2. That's your critical point. But here's where most people stop and assume they're done. They aren't. You need the second derivative test for functions of multiple variables, which involves the Hessian matrix. You compute f_xx = 6, f_yy = 2, and f_xy = 2, then calculate the determinant D = f_xx * f_yy - (f_xy)² = 6*2 - 4 = 8. Since D is positive and f_xx is positive, this critical point is a local minimum. If D had been negative, you'd have a saddle point. If D were zero, the test would be inconclusive and you'd need another approach entirely. The single biggest mistake I see beginners make is forgetting that partial derivatives treat other variables as constants during differentiation, then treating them as if they still vary when they plug the results back in. It sounds minor but it cascades into wrong gradients, which in optimization means you're walking in the wrong direction. I once had a junior analyst running gradient descent on a neural network loss function and getting convergence that looked correct on paper but produced terrible predictions. The issue was a sign error in the partial derivative of the cross-entropy term with respect to one of the weights. Took me thirty seconds to spot after he'd spent two days debugging his data pipeline.
Another counter-intuitive thing worth noting: total derivatives and partial derivatives serve completely different purposes even though they look similar. The total derivative accounts for how all variables change together, which matters in chain rule applications. If x and y both depend on a parameter t, then df/dt = (f/x)(dx/dt) + (f/y)(dy/dt). Skipping the chain rule terms is another common error, especially in physics and economics where variables are interdependent by definition.
Get the Full Details
When Derivatives Break Down
Here's what nobody tells you about working with derivatives in production environments. They fail silently at non-differentiable points. Absolute value functions, ReLU activations in neural networks, constraints with kinks, piecewise definitions, discontinuities. If your function has a corner or a jump, the derivative doesn't exist there and standard optimization algorithms will either crash or converge to garbage. I ran into this building a structural load simulator where the stress function involved a max() operation across multiple load cases. The gradient was zero almost everywhere and undefined at the switching points, which is exactly where the interesting behavior lived. I worked around it by replacing the max function with a smooth approximation using log-sum-exp, which preserved the behavior to within numerical tolerance and gave me continuous gradients throughout the domain. That tradeoff cost about an extra 15% computation time per iteration, which was acceptable for the batch jobs we were running. Numerical differentiation is another trap. People who don't have symbolic tools available sometimes fall back on finite difference approximations, computing derivatives by evaluating f(x+h) - f(x) / h for small h. This looks fine until h gets too small and floating-point precision ruins everything, or h gets too large and the approximation becomes inaccurate. The optimal h depends on your machine epsilon and the scale of your problem, usually somewhere between 10^-8 and 10^-4 for double precision. There's no universal setting, and blindly picking h = 0.001 will give you wrong answers half the time without any warning sign. If you're working with symbolic expressions, SymPy in Python handles derivatives automatically and supports partial differentiation through its diff method. For numerical work, JAX is worth learning because it computes exact gradients through autodiff rather than finite differences, and it compiles to XLA for speed. Automatic differentiation isn't magic, though. It requires your function to be composed of differentiable operations, and it breaks on control flow that depends on the input values themselves, like early returns or loops whose iteration count depends on the data. I've seen entire research pipelines break because someone used a conditional statement inside a differentiable function without realizing it created a non-differentiable path.
The practical takeaway is that derivatives are tool number one for understanding how systems respond to change, but they're only as reliable as your ability to verify them. Always check your derivatives against numerical approximations when possible. Always test edge cases. And never trust a critical point until you've confirmed its nature with the second derivative test or an equivalent method. I've spent far too many late nights fixing models that looked optimal on the surface because I skipped that verification step the first time around.