Transcription, Translation, and the Machinery Behind It
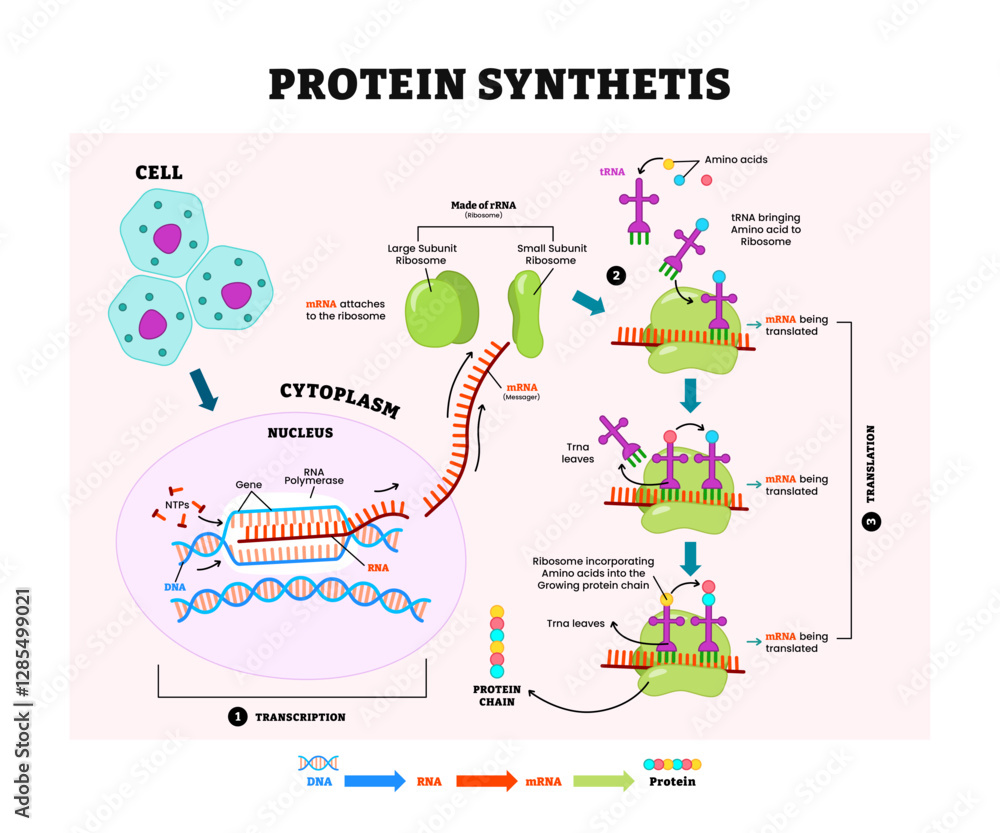
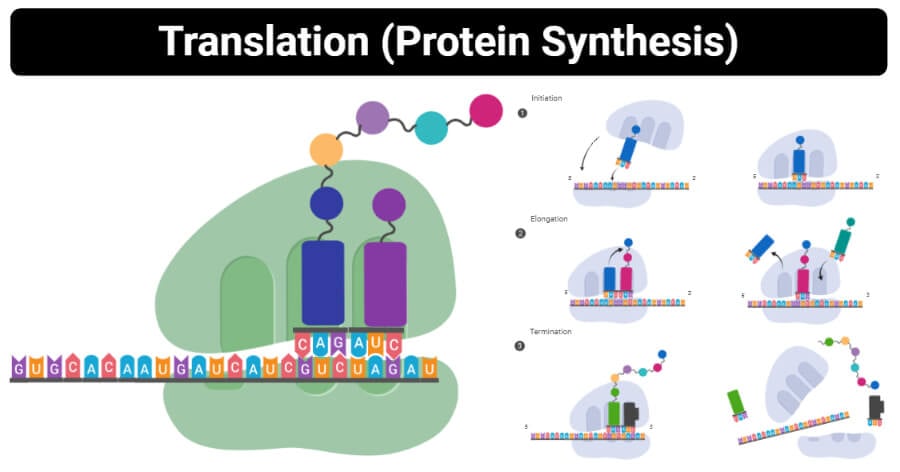
Protein synthesis is the cellular process by which DNA instructions are converted into functional proteins. It happens in two main stages: transcription, which occurs in the nucleus (or nucleoid region in prokaryotes), and translation, which happens at the ribosome in the cytoplasm. The whole thing is essentially a decoding operation. A gene is read, copied into messenger RNA, and then that RNA is used as a template to string amino acids together in a specific order. The standard way to describe the process of protein synthesis starts with initiation. RNA polymerase binds to a promoter region on the DNA, unwinds the double helix, and reads the template strand in the 3 prime to 5 prime direction. It builds a complementary strand of mRNA in the 5 prime to 3 prime direction, using uracil instead of thymine. Once the polymerase hits a terminator sequence, the mRNA strand detaches and moves to the ribosome. That is transcription. Translation is the next step, where the ribosome reads the mRNA three nucleotides at a time. Each three-nucleotide codon corresponds to a specific amino acid, and transfer RNA molecules bring the matching amino acids to the growing chain. The ribosome links them together with peptide bonds, and when it hits a stop codon, the whole thing falls apart and releases the polypeptide.
Describe The Process Of Protein Synthesis
There are details that get skipped in textbook summaries but matter a lot if you actually work with this stuff. Post-transcriptional modification is one of them. In eukaryotes, the initial RNA transcript, called pre-mRNA, gets spliced, capped, and polyadenylated before it ever leaves the nucleus. Introns are removed, exons are stitched together, and a 5 prime cap plus a poly-A tail are added for stability and ribosome recognition. Prokaryotes don't do any of that. Their mRNA is essentially ready to translate the moment it is synthesized, which is why bacterial protein production is significantly faster than in eukaryotic cells. Another thing people routinely miss is that ribosomes themselves have catalytic activity. The peptidyl transferase center that forms peptide bonds is a ribozyme, not a protein. The ribosomal RNA does the chemical work. The proteins associated with the ribosome are mostly structural or regulatory scaffolding. This was a genuinely surprising finding when it came to light and it shifted how people think about the evolution of the translation machinery. The ribosome is fundamentally an RNA machine, and the protein components were layered on later. I spent some time optimizing recombinant protein expression in E. coli a few years back, and the bottleneck turned out to be codon usage. The gene I was trying to express had a high frequency of rare codons for that particular bacterial strain, which meant the tRNA supply ran out mid-translation. The ribosomes stalled, the nascent chains misfolded, and the yield was basically garbage. The fix was straightforward in hindsight: I switched to a Rosetta strain of E. coli that carries extra copies of the rare tRNA genes, and the expression went from barely detectable to several milligrams per liter of culture. It is a reminder that the process is only as efficient as the rarer components it depends on, and a gene sequence that works fine on paper can behave completely differently inside a cell that lacks the right molecular tools to read it.
Folding is another step that is routinely treated as an afterthought. A newly synthesized polypeptide chain does not just spontaneously settle into its functional shape. Molecular chaperones like GroEL and GroES in bacteria, or Hsp70 and Hsp90 in eukaryotes, actively assist in folding by preventing premature aggregation and giving the chain a chance to find its correct conformation. Without chaperones, a lot of proteins either misfold or form insoluble aggregates. This is especially relevant when you are expressing eukaryotic proteins in bacterial systems, since the chaperone landscape is different and the reducing environment of the cytoplasm can interfere with disulfide bond formation. That is why sometimes you have to route the protein through the periplasm or use specialized expression strains to get anything functional out. Post-translational modifications also add a layer of complexity that basic descriptions ignore. Phosphorylation, glycosylation, ubiquitination, acetylation, methylation, and proteolytic cleavage can all happen after the chain is synthesized, and they can completely change what the protein does. Insulin is a classic example. It is made as proinsulin, a single polypeptide chain, and then a segment is cleaved out to produce the active two-chain hormone. Without that cleavage step, you just have an inactive precursor sitting around. The whole process is error-prone by design. Misincorporation rates during translation are roughly one in ten thousand, which sounds low but adds up over billions of operations in a single cell. Quality control mechanisms exist to catch and degrade defective proteins, primarily through the ubiquitin-proteasome system in eukaryotes or ClpXP and Lon proteases in bacteria. But those systems are not perfect, and misfolded proteins do accumulate over time, which is one of the factors linked to age-related cellular dysfunction and diseases like Alzheimer's and Parkinson's.
Get the Full Details

If you are studying this for an exam, the standard pathway covers transcription, RNA processing, translation, and folding. If you are actually working with it, the standard pathway is just the starting point, and most of the problems you encounter come from everything else happening around it. Gene expression levels depend on promoter strength, mRNA stability, codon bias, tRNA availability, ribosome traffic, chaperone capacity, and degradation rates, all of which interact in ways that are hard to predict without empirical testing.