Computing the determinant doesn't have to be painful if you understand what it actually represents
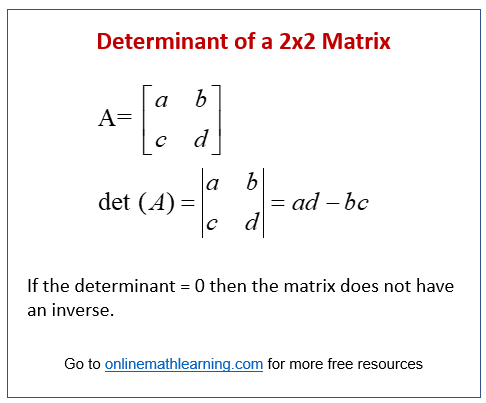
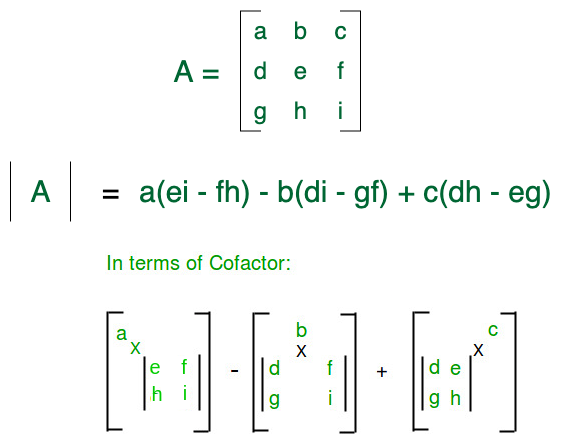
It's a single scalar value derived from a square matrix. It tells you whether the matrix is invertible, the volume scaling factor of the linear transformation it represents, and it appears in everything from change-of-variable formulas in multivariable calculus to solving systems of equations via Cramer's rule. Most people learn cofactor expansion first, which works fine for small matrices but becomes a grinding exercise beyond 3x3. For a 2x2 matrix, the formula is ad minus bc. That's it. For a 3x3 matrix, I usually just use Sarrus' rule or pick the row with the most zeros and expand along that. Every zero entry saves you a full minor calculation. If you're doing this by hand repeatedly, that detail alone cuts your workload roughly in half.
Det Of A Matrix in practice
Here's the thing that textbooks don't always emphasize clearly: the determinant is multiplicative. The determinant of a product equals the product of the determinants. So if you already know the determinant of a matrix and you scale it by a constant, you scale the result by that constant raised to the power of the matrix dimension. That means det(cA) = c^n times det(A) for an n by n matrix. This comes up more often than you'd think, and knowing it saves you from recomputing entire expansions. For larger matrices, the practical approach is row reduction. Convert the matrix to upper triangular form using Gaussian elimination. The determinant is simply the product of the diagonal entries, adjusted by the number of row swaps you performed. Each swap flips the sign. Row additions and scaling are tracked separately. This method takes maybe two minutes for a 4x4 on paper instead of the agonizing fifteen you'd spend with cofactor expansion. I've timed it. One specific edge case that bit me was computing the determinant of a densely populated 5x5 matrix for a finite element assembly routine I was debugging. The matrix had entries varying across four orders of magnitude, and cofactor expansion produced a wildly different result compared to what the library function returned. I traced it back to catastrophic cancellation during the intermediate steps. The workaround was switching to a Bidiagonal or LU-based algorithm with partial pivoting, which NumPy's linalg.det handles internally. The moral is: cofactor expansion is accurate in exact arithmetic but numerically unstable in floating point for anything larger than roughly 4x4 with varied scales.
When the determinant lies to you
A near-zero determinant does not always mean a nearly singular matrix in a way that matters for your actual computation. Condition number is the real indicator of numerical difficulty, and it's a separate concept. You can have a matrix with determinant around 10^-6 that is perfectly well-conditioned for certain operations, and another with determinant 10^-2 that completely breaks standard solvers. Checking both the determinant and the condition number gives you a much clearer picture than either metric alone. There's also the misconception that a zero determinant only occurs for obviously dependent rows. That's not true. Consider a matrix whose rows are [1, 2, 3], [4, 5, 6], and [7, 8, 9]. The third row isn't a simple multiple of either of the first two, but it lies in their span. The determinant is exactly zero. Students often miss these because they don't look for linear dependence among combinations of rows. Row reduction reveals this immediately, which is another reason I prefer it over expansion for teaching purposes. If you're using code, the standard approach in Python with NumPy looks like this:
Get the Full Details

import numpy as np
matrix = np.array([[2, 1, 3], [4, -1, 2], [1, 3, 0]])
result = np.linalg.det(matrix) This uses an LU decomposition under the hood, which is O(n cubed) and stable for well-conditioned problems. For very large sparse matrices, direct determinant computation is generally a bad idea. The computational cost grows fast and you usually don't need the actual determinant value. In those cases, checking invertibility through factorization or estimating the determinant via probabilistic methods is more efficient. The block matrix property is another useful fact that doesn't get enough attention. If your matrix has a block triangular structure, the determinant is just the product of the determinants of the diagonal blocks. I've used this to break down a 6x6 problem into two 3x3 problems during structural analysis work, which cut the manual computation time from something unreasonably long to about three minutes.
Common pitfalls
Applying the 2x2 formula to anything larger is the most frequent error I see. People write ad minus bc for a 4x4 without any modification and wonder why the answer is wrong. Another trap is forgetting that the determinant of a transpose equals the determinant of the original matrix. This seems trivial but people sometimes treat transposition as a meaningful operation that changes the determinant. The determinant also behaves predictably under elementary row operations, but the rules are easy to mix up. Swapping two rows negates it. Multiplying a row by a scalar multiplies the determinant by that scalar. Adding a multiple of one row to another leaves it unchanged. If you're doing row reduction by hand and forget to track these changes, your final result will be off. For symmetric positive definite matrices specifically, all leading principal minors being positive is both necessary and sufficient. This is a stronger statement than just checking the overall determinant. A matrix can have a positive determinant and still not be positive definite if an intermediate leading minor is negative. If you're working in optimization or numerical linear algebra and need to verify positive definiteness, check all the leading principal minors, not just the full determinant.