Getting Detection In Remote Sensing to Work in Practice
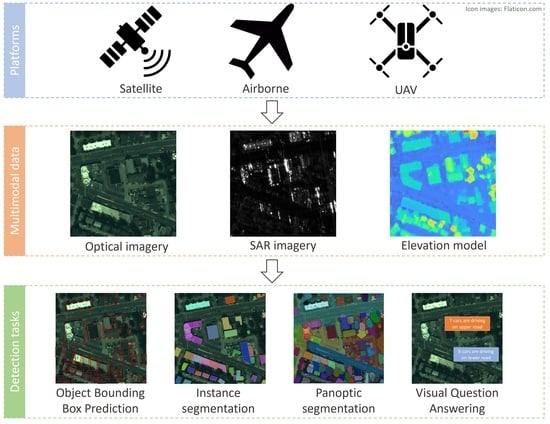
Detection In Remote Sensing is fundamentally about spotting objects, changes, or patterns in imagery collected from satellites, aircraft, drones, or other airborne platforms. The process spans everything from manual visual interpretation to fully automated deep learning pipelines. Most people start by reading about convolutional neural networks and object detection architectures, then spend three weeks frustrated that their model keeps predicting buildings where there are none. I spent about four years working on detection pipelines for high-resolution satellite imagery before I stopped trying to force every problem into a YOLO architecture. Here is what actually matters.
Core Detection In Remote Sensing Techniques
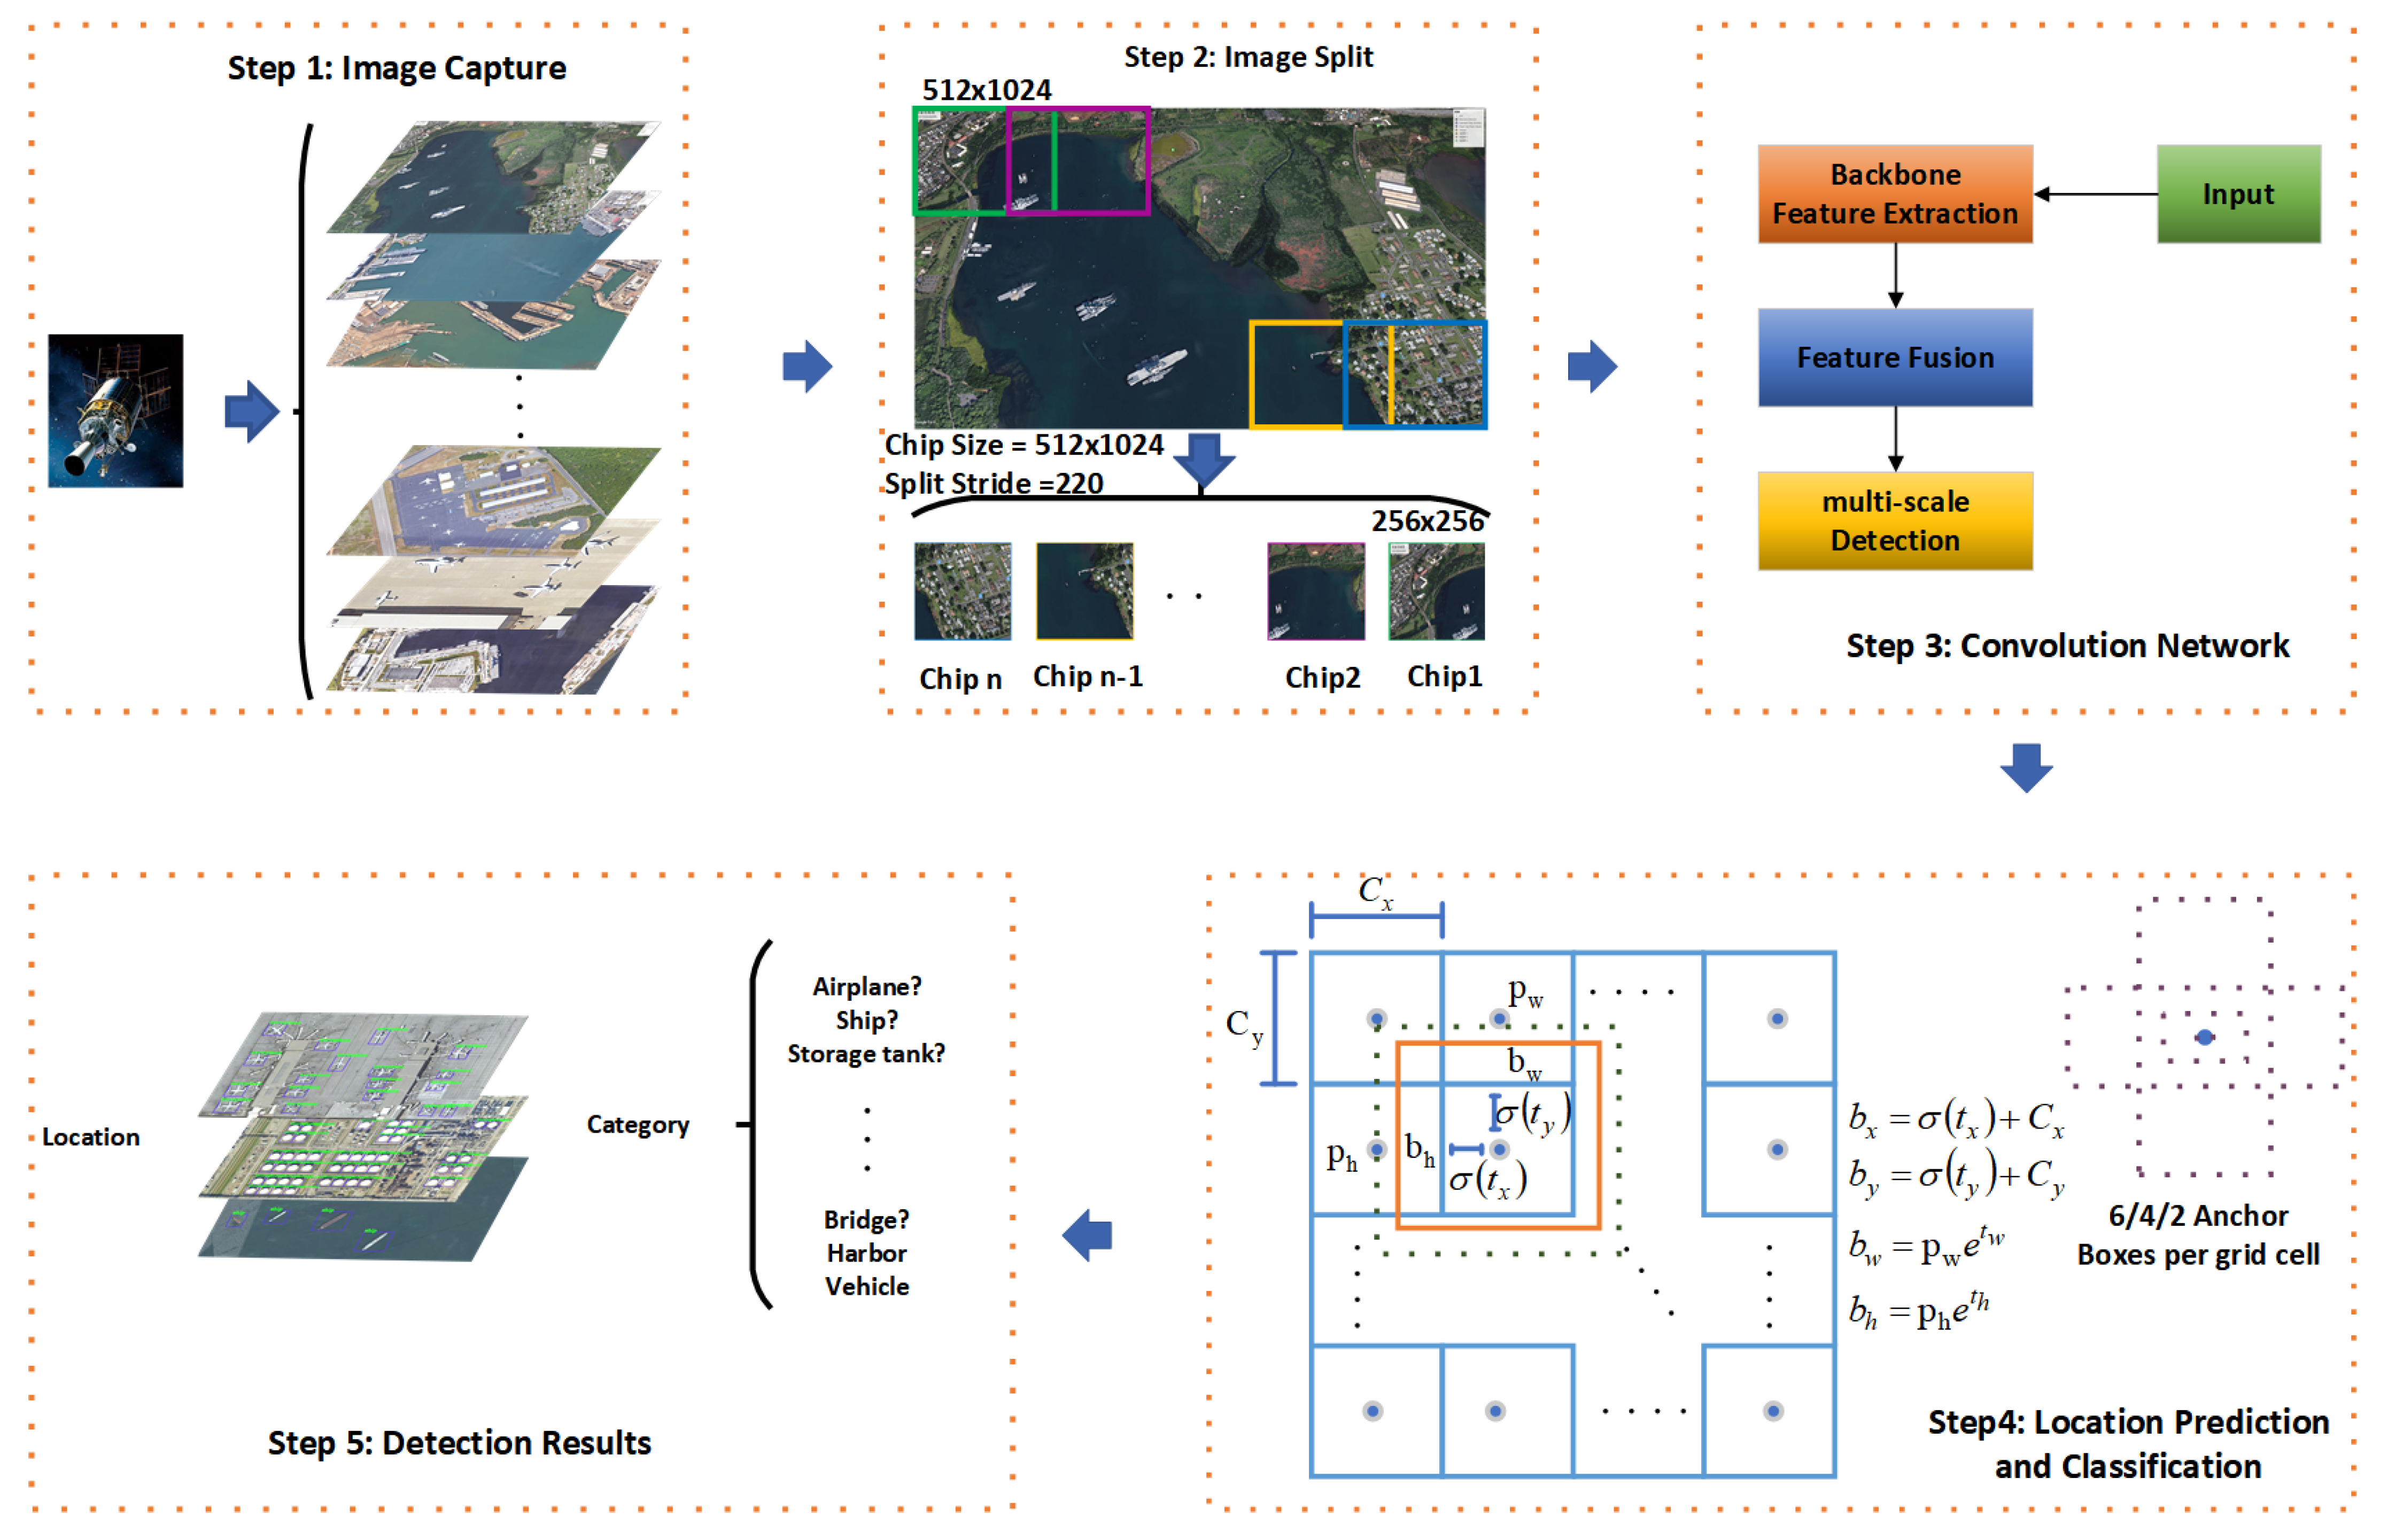
The workflow typically involves several stages. You acquire imagery from a source like Sentinel-2, Planet, or a commercial drone platform. You prepare annotations using tools like Label Studio, CVAT, or AGFT. You train a detection model. You validate against holdout imagery. You deploy for inference. The models most commonly used are YOLO variants, Faster R-CNN, Mask R-CNN for segmentation-aware detection, and more recently, vision transformer approaches like DETR and its descendants. Each has different tradeoffs. YOLO is fast and works well for real-time applications. Faster R-CNN tends to be more accurate on small objects but requires significantly more compute. DETR removes the need for anchor boxes but can be finicky to tune. For remote sensing specifically, one critical difference from general computer vision is object orientation. A standard YOLO head assumes axis-aligned bounding boxes. Ships, runways, and wind turbines are often oriented at arbitrary angles. Rotated bounding boxes or oriented detection heads make a noticeable difference. I have seen models gain 4 to 7 percent mAP just by switching to a rotated box detector like S2ANet or RoI Transformer.
The annotation problem nobody warns you about
Annotation quality is the single biggest bottleneck in remote sensing detection projects. Satellite imagery has peculiar issues that don't exist in everyday photography. Objects are small relative to image size. A vehicle in a 10-meter-per-pixel Landsat image might occupy fewer than 20 pixels. Class ambiguity is common: is that shadow a truck or a pile of gravel? Clouds and cloud shadows create false positives that look identical to the target class. I once trained a vehicle detection model on aerial drone imagery and it performed beautifully on the training set with an mAP of 0.82. When I deployed it on a different drone flight line taken three months later under slightly different sun angles, the mAP dropped to 0.31. The model had learned lighting conditions, not vehicles. The workaround was collecting multi-season data during annotation and applying aggressive domain augmentation including random brightness shifts, solar angle simulation, and test-time augmentation during inference. This brought the deployed mAP back up to around 0.71, which was acceptable for the use case. If you are working with very high resolution commercial imagery, consider sub-images. Processing full 6000 by 6000 pixel panoramas at once causes GPU memory issues and makes annotation impossibly slow. Tile the imagery into 512 or 1024 pixel patches with some overlap, annotate at tile level, and then stitch predictions back together during inference.
Get the Full Details
Practical training setup
A reasonable starting point for a satellite-based vehicle or ship detection task: Training on a single RTX 4090 typically takes between 6 and 14 hours for a YOLOv8 model on a 3,000 image dataset. That is not fast, but it is manageable. If you are using a transformer-based detector, expect 2 to 3 times longer. The most expensive mistake I have seen repeatedly is evaluating on the same spatial region as the training data. If your training and test images come from the same geographic area, the model is not learning to generalize. It is learning the texture of that particular landscape. Always split by geography, not randomly. Use a train-test split based on distinct regions, different cities, or different acquisition dates separated by at least six months.
Another issue is ignore labels. In satellite imagery, many objects are too small or too ambiguous to label reliably. Some annotation platforms let you mark regions as ignore. If you do not use this feature, the model will try to learn from poorly annotated or unlabeled regions and performance degrades quietly over time. Turn on ignore regions and exclude those areas from loss computation.
When detection fails entirely
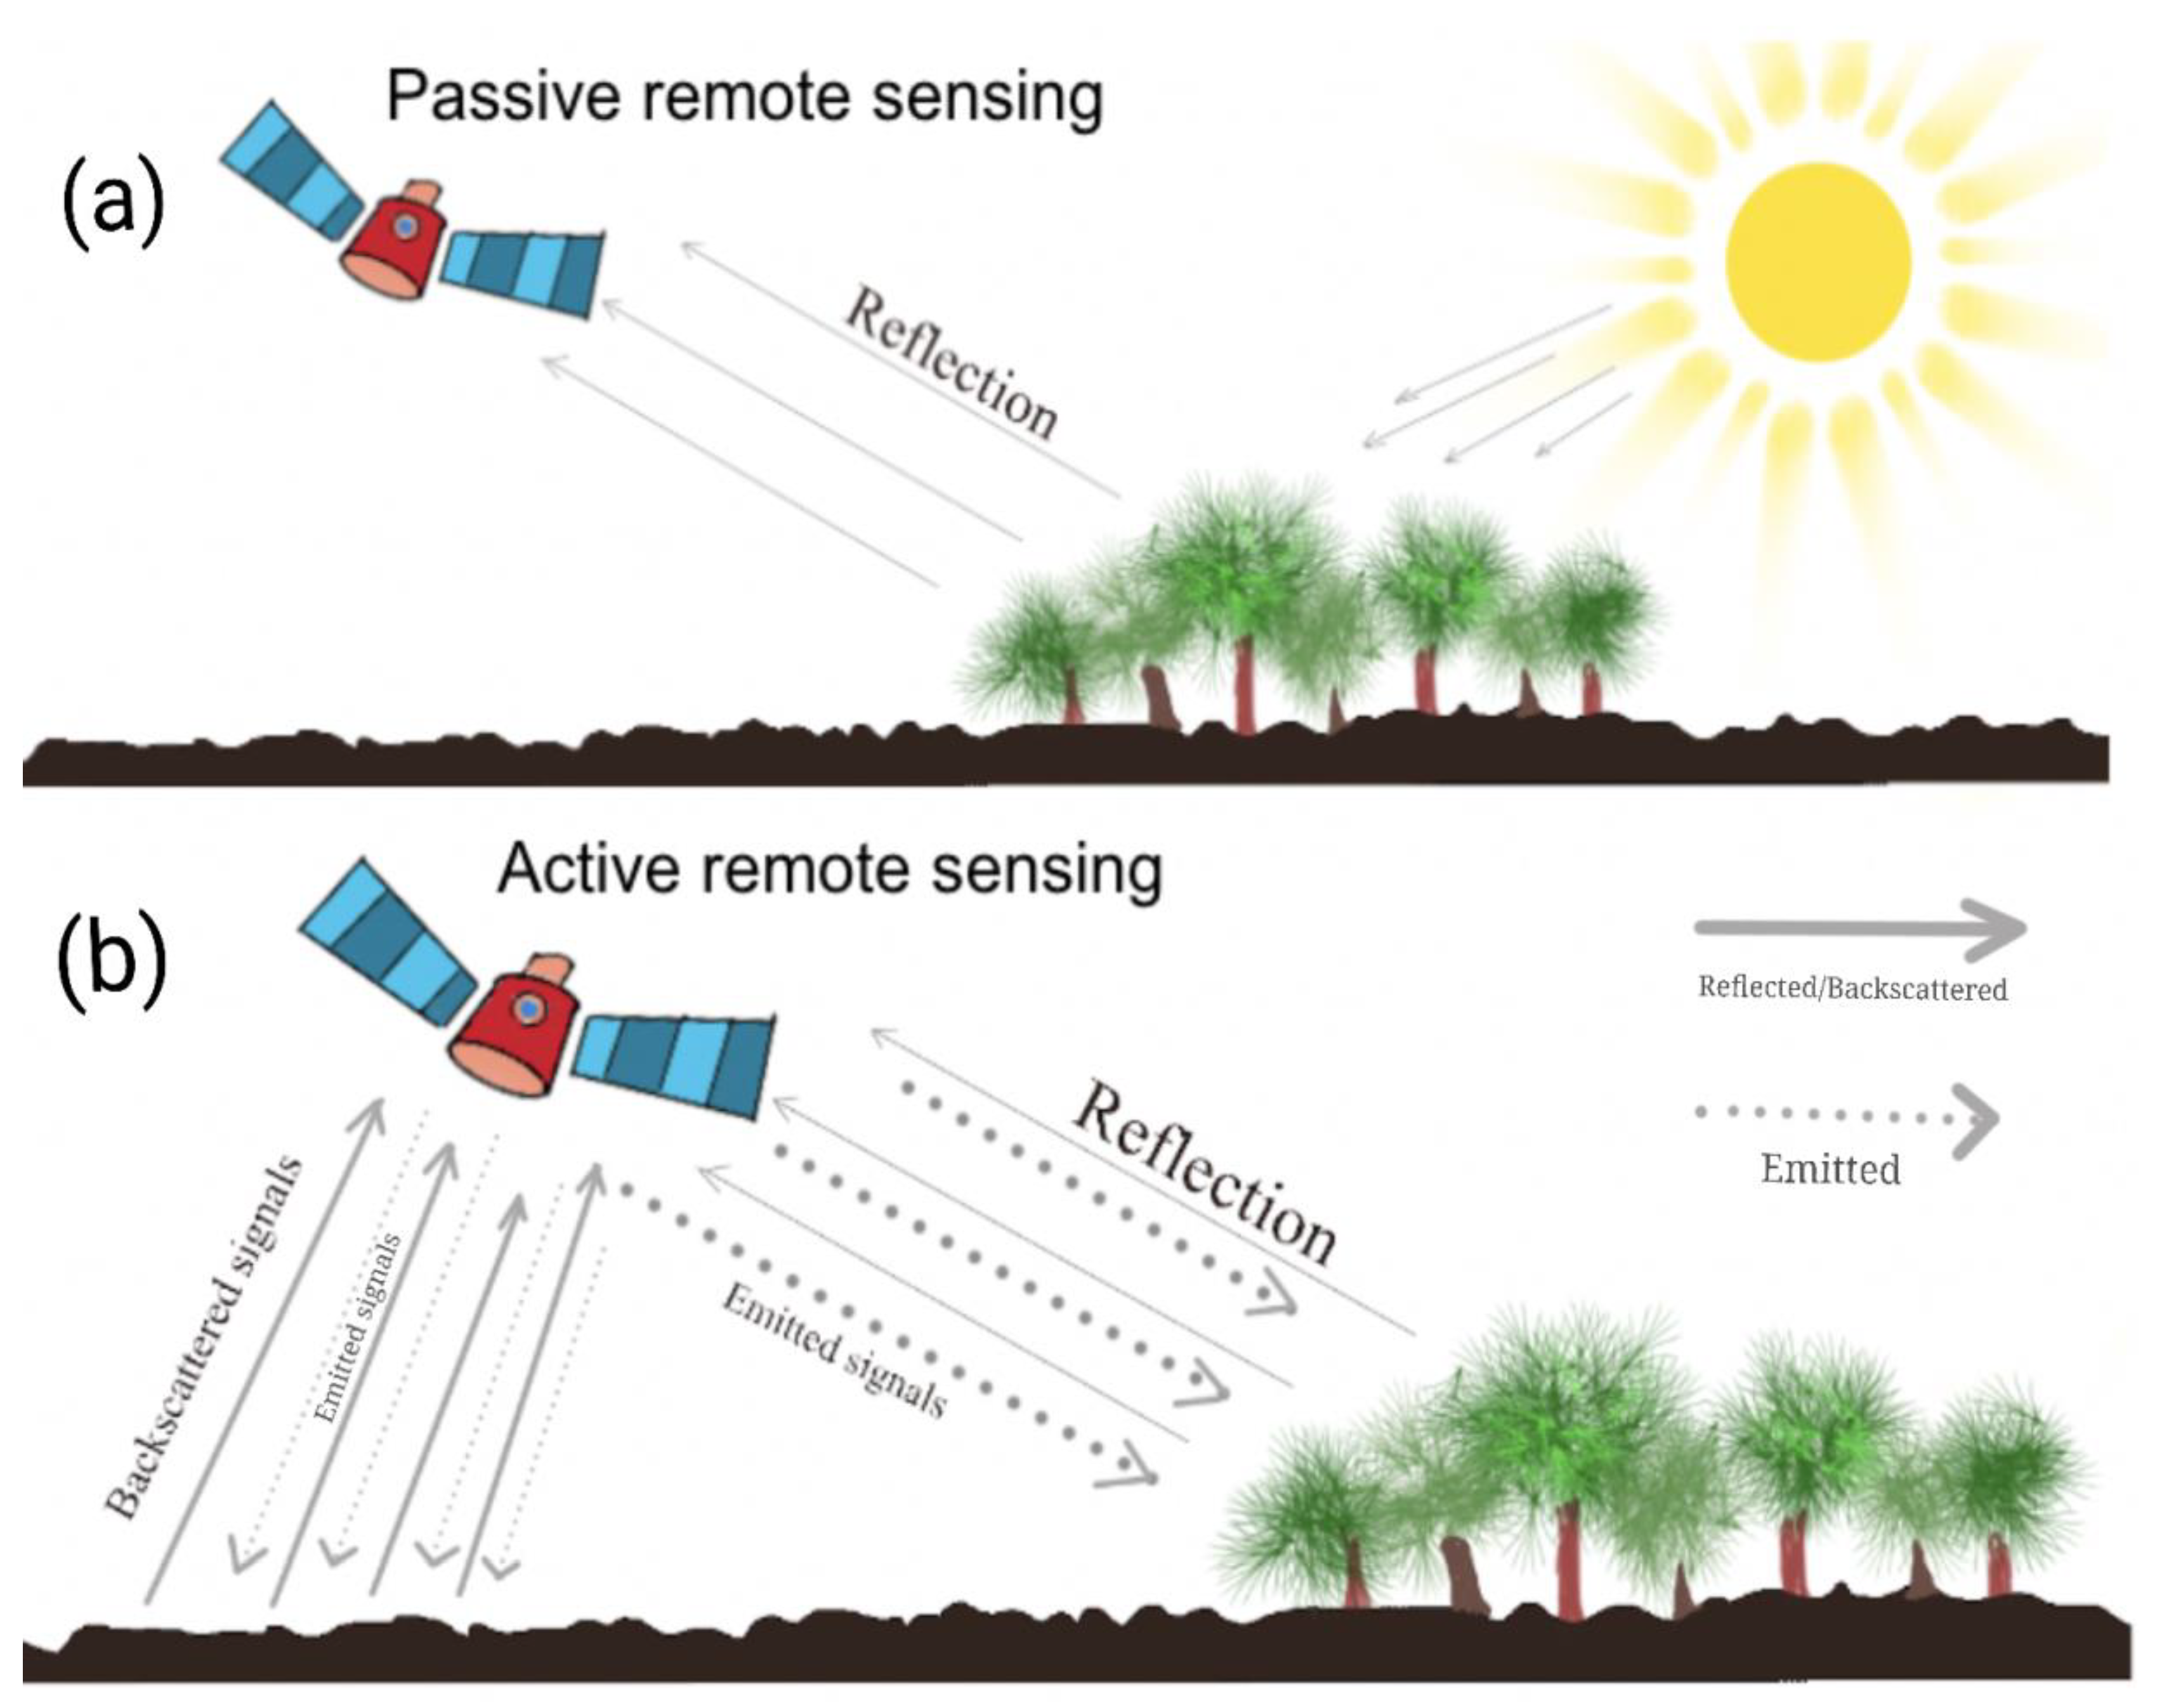
It is worth being honest about where this approach breaks down. Very low resolution imagery, below 4 meters per pixel for most object classes, makes detection unreliable regardless of model choice. Thermal or multispectral data without a visible band lacks the texture information most detectors rely on. Dense urban canyons with heavy shadowing produce inconsistent results across different times of day. And if your target class has fewer than a few hundred annotated examples, fine-tuning a general detector will almost certainly overfit. In those cases, few-shot learning methods or manual inspection workflows are more practical than forcing a deep learning pipeline. For small-object detection specifically, there is a technique called slice-aware augmentation or SAHI that processes each tile independently and merges the results. It does not magically recover information that is not there, but it consistently improves recall on objects smaller than 32 by 32 pixels at the original resolution. Pair it with a higher input resolution and you will see a measurable improvement, usually in the range of 3 to 8 percent in mAP@0.5.
Open source resources
Ultralytics provides a solid implementation of YOLO for detection tasks and handles most of the preprocessing and training pipeline automatically. The Hugging Face Transformers library supports DETR and other transformer-based detectors with pre-trained weights. For satellite-specific work, the SpaceNet dataset and the DIUx XDA competition data from DARPA have been useful references for building realistic benchmarks. If you need to work with existing satellite imagery quickly, Google Earth Engine offers access to large archives without downloading terabytes of data locally. The field moves fast. What worked reliably two years ago is often outperformed by newer architectures now. Keep the training pipeline modular so you can swap components without rebuilding everything. That habit saves more time than any single model choice ever will.