The messy reality of getting students to assess their own work
Most people think teaching students to self-assess means handing them a rubric and walking away. That never works. I tried it with a Grade 9 math class once. Gave them a twelve-point rubric for solving linear equations and asked them to grade three sample solutions. Eighteen out of twenty-two students gave full marks to work that missed the sign rule on page two. The rubric was clear. They just did not know what clarity in a correct answer actually looked like. The gap between having criteria and applying them reliably is where the real work lives. It is not a small gap. It takes roughly six to eight weeks of deliberate practice before most students can calibrate themselves within one level of an expert grader. Before that point, you are basically running a calibration exercise dressed up as learning.
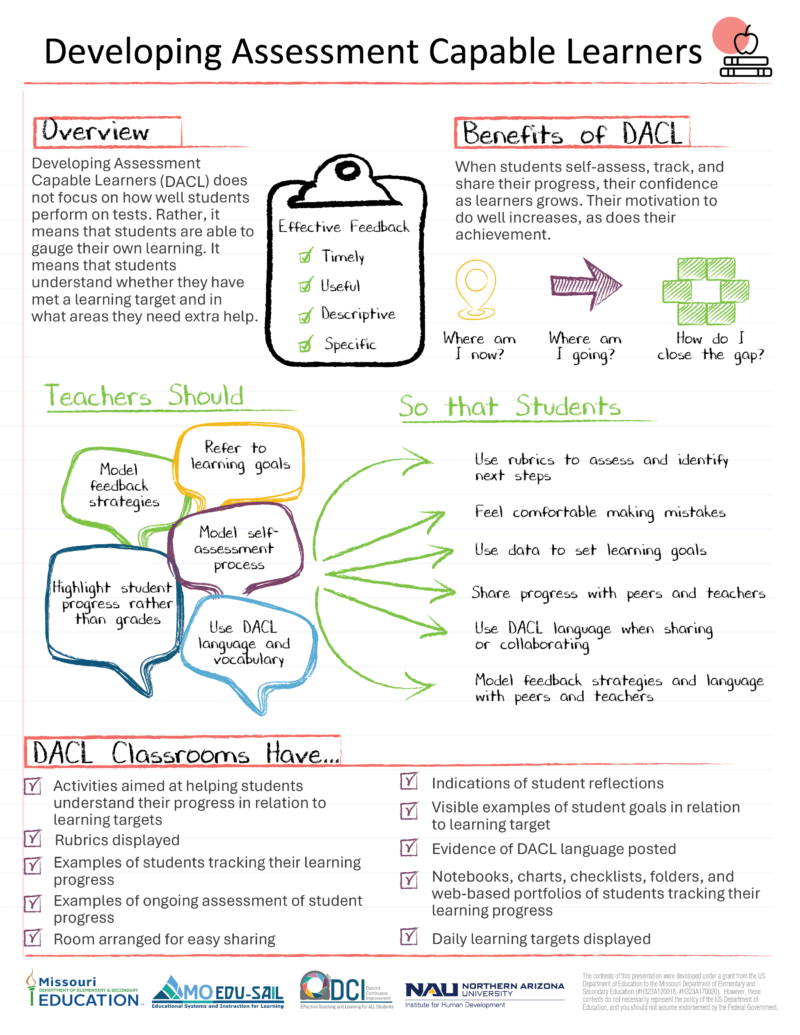
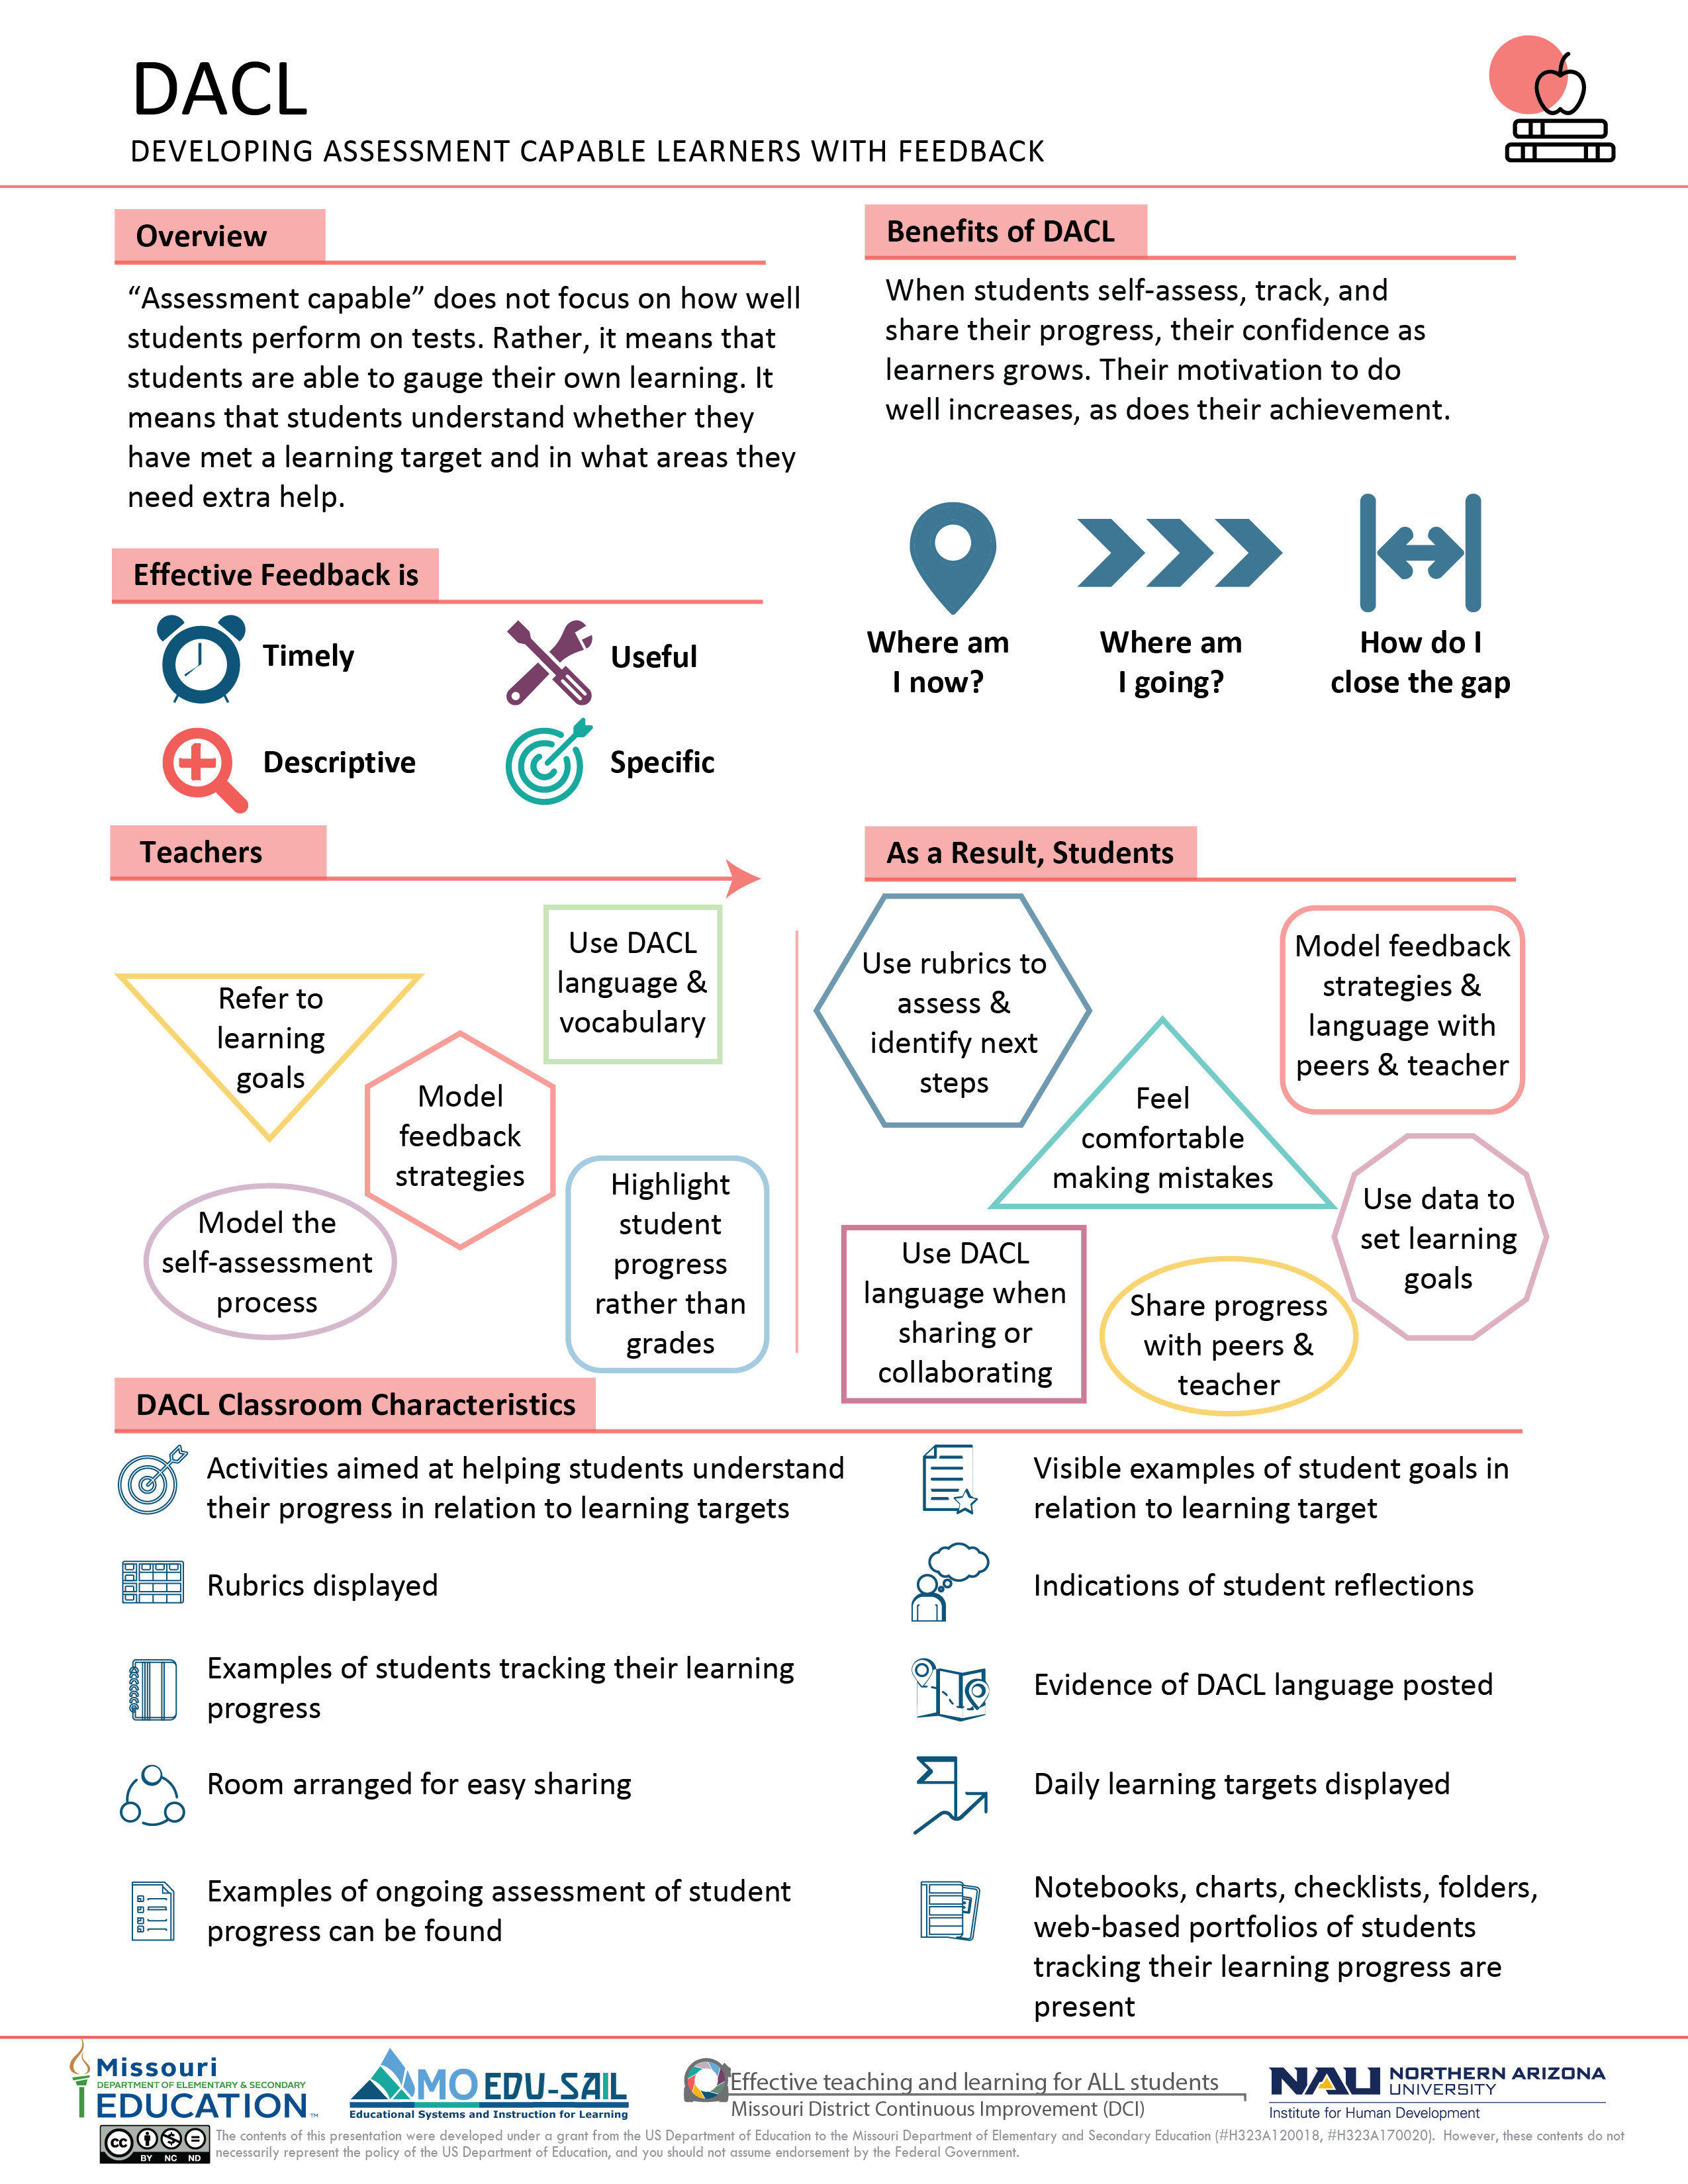
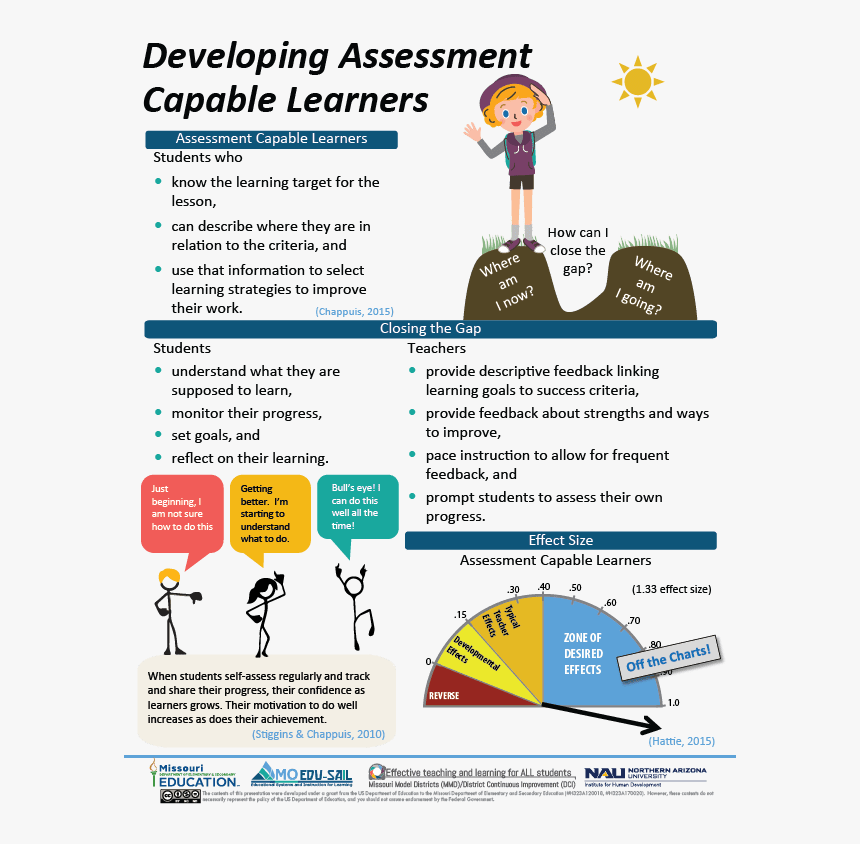
Developing Assessment Capable Learners
Assessment capable learners are students who can interpret success criteria, monitor their own work against those criteria in real time, and adjust their approach without waiting for teacher feedback. The framework originated in New Zealand research by Wiliam and Leahy, then picked up traction through Hattie and Timperley's work on feedback loops. It sits squarely inside formative assessment practice. The name sounds bureaucratic but the mechanism is straightforward: you make learning intentions visible, you surface success criteria through quality exemplars, you build in frequent low-stakes checks, and you train students to interpret the results and act on them. Here is how it actually runs in a classroom over a semester. I start units by co-constructing success criteria with the class instead of posting mine on the board. Students read two anonymized responses from previous years. They argue about which one meets the standard. We write the criteria together. It takes two class periods. That is two periods I will never get back. Then for the next month, every assignment starts with a self-assessment block where students mark their work against each criterion and write one sentence explaining the match or the gap. Most classes resist this for the first three weeks. They fill it in mechanically. The format changes around week four when they start noticing patterns in their own errors.
What most people get wrong about self-assessment
The biggest mistake is treating self-assessment as a substitute for teacher feedback rather than a precursor to it. Students cannot replace a teacher's calibrated eye. They can, however, become faster at spotting the mistakes they already make. That speed matters more than accuracy in the beginning. A student who notices they consistently drop negative signs during simplification will fix that faster than a student who waits for the red pen to tell them. Another common failure mode is using vague criteria. "Clear writing" means nothing to a sixteen-year-old. "Every paragraph opens with a claim that directly answers the prompt" is something they can check against their own draft. Specificity is not optional here. It is the entire mechanism. I ran into a stubborn edge case last year with a Year 11 history class. We were working on sourcing documents, and the success criteria included evaluating bias. Half the class kept conflating bias with factual error. They would mark a source as unreliable simply because the dates were wrong, which is a different skill entirely. I spent three sessions building a separate track for factual accuracy versus interpretive bias, with paired exemplars that were intentionally mixed. One document had accurate facts but heavy bias. Another had biased framing but correct dates. Students had to score them on both dimensions independently. It added maybe forty minutes to the unit plan. The calibration improved noticeably after that. Their peer feedback sessions stopped collapsing the two skills into one argument.
Get the Full Details
Building the habit without burning out
You do not need fancy software for this. A three-column self-assessment table works fine. Column one lists each criterion. Column two asks the student to rate their work against it. Column three asks for one specific action they will take before submitting. That third column is the piece most teachers skip. Rating without a follow-up action is just journaling with a grade attached. It feels productive and changes nothing about the work. Peer assessment follows the same logic but introduces a calibration risk. Students who have not yet developed reliable judgment will reinforce each other's blind spots. The fix is structured inter-rater practice. Before students assess each other's drafts, you do five to eight rounds of joint calibration using exemplars. You score the same sample independently, then compare notes until your scores fall within one band. That process usually takes about twenty minutes per cycle. Doing it once a month keeps peer assessment from drifting into friendship grading. For feedback loops to actually close, you need a mechanism where students see the impact of their adjustments. I use a resubmission policy on the first major task of each unit. Students submit a draft, receive criteria-based feedback, revise, and submit again. The second submission is where the learning actually registers. I track revision quality separately from content quality. A well-revised paper with weak arguments still shows growth in assessment capability, and that distinction matters for grading honestly.
When this approach breaks down
Self-assessment does not scale well across large class sizes without a system for tracking individual calibration trends. If you have three hundred students and no digital tracker, you will either stop collecting the data or turn it into busywork. I moved to a simple shared spreadsheet with color-coded calibration scores per student. It reduced the time needed to spot drifting accuracy from about four hours per grading cycle to roughly thirty minutes. Thirty minutes is still too much if you are doing it manually for every unit, which is why some schools adopt platforms like FreshGrade or ClassDojo for lighter tracking. Those tools cut administrative time further but introduce their own friction around setup and parent access. Choose based on your actual workflow, not the brochure. There is also a hard ceiling on how much this helps students who lack foundational skill. Self-assessment requires students to actually understand the content well enough to judge their work against it. Give this to a class that has not mastered the underlying material and you get noise, not insight. In those cases, targeted skill instruction comes first. Assessment capability builds on top of content competence, not around it. The approach also struggles in subjects where success criteria are genuinely contested. Literature response, creative writing, and design projects often resist neat rubric breakdowns. Forcing overly rigid criteria onto those subjects tends to narrow what students produce more than it improves judgment. A looser framework with verbal feedback plus occasional exemplar comparison works better there. Do not pretend a single method fits all disciplines.
Practical sequence for implementation
Week one: introduce learning intentions and co-construct criteria using exemplars. Week two: teach students to self-assess using a simple rating table with a mandatory action column. Week three: run the first peer calibration round with five paired samples. Week four: first low-stakes assignment with self and peer feedback built in. Weeks five through eight: rotate peer calibration rounds monthly while adding increasingly complex tasks. After week eight, most students show stable calibration within one scoring band of the teacher, assuming the criteria stayed consistent throughout. If you skip the early exemplar work and jump straight into self-assessment sheets, you will see a temporary confidence spike followed by a gradual drift downward as students settle into pattern-matching rather than actual judgment. That drift is real and it shows up in grade inflation on early assignments that reverses by mid-term. The exemplar phase is not decoration. It is the foundation. The whole system demands more class time upfront than traditional direct instruction models. Expect to spend approximately fifteen to twenty percent of total instructional time in the first semester on criteria work, calibration, and feedback cycles. That is a measurable reduction in content coverage. Whether that trade-off is worth it depends on your goals. If the goal is test score improvement over a single year, direct instruction often wins on efficiency. If the goal is producing students who can independently monitor and improve their own work across subjects, this framework is one of the few approaches that actually moves the needle past the junior year mark.