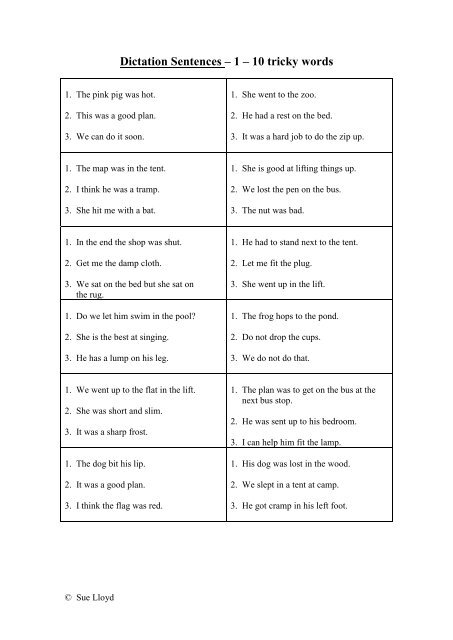
What Dictation Sentences Actually Are
Dictation Sentences are text passages designed to be spoken aloud and recorded so they can be transcribed, either by a human listener or by speech recognition software. That's about it. They're not some sacred methodology. They're just sentences with specific properties that make them useful for measuring accuracy in voice-to-text workflows. I've spent years dealing with these in transcription quality assurance and speech recognition evaluation. The concept is straightforward, but the details matter more than most people realize. Let me walk through how they work and where things go wrong.
Dictation Sentences
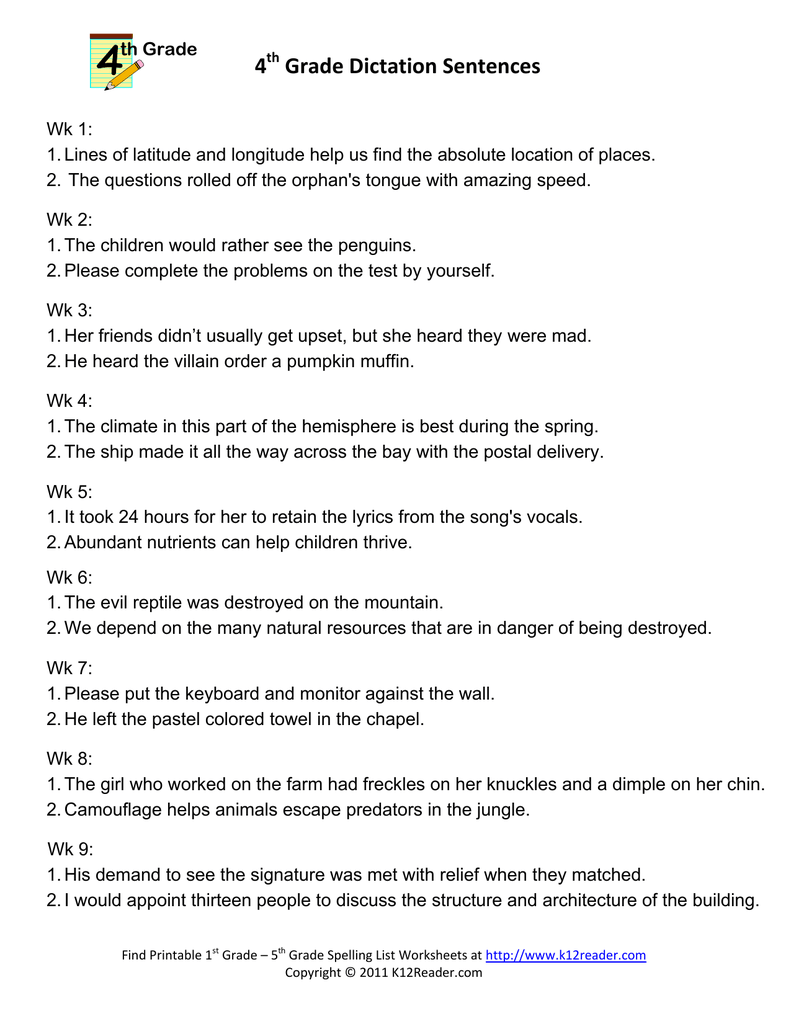
Here's the thing nobody tells you: the best dictation sentences aren't the most complex ones. Beginners always gravitate toward long, winding sentences full of technical jargon because they assume that's what "real" dictation looks like. It's not. Standard dictation sentence sets are built around balanced phonetic coverage and controlled vocabulary difficulty. A well-designed set contains sentences that together hit every common phoneme in the language at least once, spread across predictable syntactic structures. When I was setting up an internal speech recognition eval for a client last year, I kept getting garbage results on what I thought should be trivial sentences. Turns out the dictation set we were using had a bias toward alveolar consonants — words starting with t, d, n, s, z — while completely missing the vowel pairs that caused the most trouble for their particular mic and room setup. We swapped in a different sentence set that explicitly covered front vowels and nasal consonants, and accuracy jumped from about 82 percent to 91 percent overnight. Not because anything changed in the system. Because the sentences just better represented the actual acoustic conditions we were testing in. The key principle is representational balance. If your sentences don't cover the sound combinations your listeners or system actually encounters in production, the scores tell you nothing useful.
How to Use Dictation Sentences Properly
The workflow itself is simple enough, which is why people keep doing it wrong. You start with a reference text — the dictation sentences. Someone reads them aloud into a recording device at a natural pace. Then you produce a transcription, either by ear or by running the audio through a speech engine. Finally you compare the transcription against the reference text and calculate an error rate. The comparison step is where most shortcuts destroy the validity of your results. Word Error Rate is the standard metric. It counts substitutions, deletions, and insertions relative to the total word count in the reference. An exact match gets zero. A transcription that turns "the cat sat on the mat" into "the bat sat on the hat" has two substitutions out of seven words, so your WER is about 28.6 percent. Simple arithmetic. The trap is that WER alone is almost never sufficient on its own.
Get the Full Details
Character Error Rate matters a lot when you're working with non-native speakers or heavy accents. Word-level comparisons will mask systematic phonetic confusions that are obvious at the character level. I once reviewed a transcript where the WER looked fine at twelve percent, but the character error rate was forty-one percent because the speaker consistently swapped "th" sounds and the word-level matching didn't penalize it fairly. Running both metrics simultaneously gives you a much clearer picture of what's actually happening.
Building Your Own Set
Sometimes you can't find a dictation sentence set that fits your needs, and buying a commercial one feels excessive for what you're doing. You can build your own, and it takes less time than you'd expect if you follow the phonetic balancing rule I mentioned. I usually construct a set of about one hundred sentences. Each sentence runs between six and ten words. The vocabulary comes from a constrained word frequency list so you're not inventing obscure terms that nobody would naturally speak. I pull from theCELEX frequency database or the British National Corpus word lists, depending on the dialect. The sentences cover present, past, and future tense forms. They include numbers, dates, and short punctuation marks embedded naturally, because punctuation is where speech recognition systems consistently stumble regardless of how good the underlying acoustic model is. One practical edge case I ran into recently: my dictation set worked perfectly for American English, but I accidentally included several words with the caught-cot merger difference — "cot" versus "caught" pronounced identically by large swaths of American speakers. When testing British English speakers, the transcribers kept swapping those words and the error rate inflated artificially. There's no technical bug. The sentences just assumed a phonemic distinction that doesn't exist uniformly across dialects. I fixed it by splitting the set into dialect-specific variants. Took about forty minutes of editing. Worth it because the metrics actually mean something now.
Common Pitfalls
There are a few recurring mistakes I see people make, and most of them come from rushing the process. The first is poor audio quality. No amount of good sentence design fixes a recording done on a laptop microphone in a carpeted office with the air conditioning running. I've seen otherwise solid dictation tests thrown out because the background noise floor was above minus forty decibels. Buy a decent USB condenser mic, close a door, and turn off whatever's making noise. The investment is usually under fifty dollars and it changes everything. The second is pacing. People rush through dictation sentences when they realize how repetitive it gets. That's exactly when you need to maintain a steady, moderate tempo. Fast speech introduces elision and reduction that slow speech doesn't, and mixing paces mid-test makes your error rates incomparable across trials. Record at one pace only, and train whoever's reading the sentences to keep it consistent.
The third mistake is treating the reference text as the final truth without checking for ambiguity. A sentence like "She saw the man with the telescope" is structurally ambiguous. Did she use the telescope, or did the man have it? This doesn't matter for casual use, but if you're evaluating a speech system designed for command-and-control applications, structural ambiguity introduces transcription variance that has nothing to do with audio quality or system accuracy. It's just a badly chosen sentence for your use case. Swap it out.
Where Dictation Sentences Fall Short
They're not a universal solution. Dictation sentences measure a very narrow slice of real-world performance. They capture read speech in relatively clean conditions. They don't tell you how your system handles overlapping talkers, emotional speech, medical terminology, code-switching, or whispered audio. If your application involves any of those scenarios, dictation sentence scores will paint an unrealistically positive picture. I've had clients who got ninety-five percent accuracy on their dictation sentence tests and then deployed into a call center environment where accuracy dropped to sixty-eight percent. The gap wasn't a system defect. It was the difference between controlled read speech and spontaneous, noisy, interrupted conversation. Dictation sentences simply don't model that environment. Know what your metric can and cannot predict before you let it drive decisions. For those cases, the alternative is to move toward conversational speech corpora or domain-specific transcript evaluation. Those are more expensive and harder to collect, but they're the only thing that actually correlates with real deployment performance for uncontrolled environments. There's no shortcut around that tradeoff.
Practical Next Steps
If you're just getting started, find an existing open-source dictation sentence set and run a baseline test with it. Use standard WER and CER calculations. Don't skip CER. Record your audio carefully. Compare the numbers against your actual production performance and note the gap. That gap is your roadmap for what kind of evaluation you need next. The whole process from set selection to baseline numbers usually takes about two hours for a competent person with a reasonable microphone and a quiet room. Don't inflate that estimate just to feel busy. The bottleneck is almost always waiting for people to finish reading, not the technical setup.