Understanding the Core Distinction
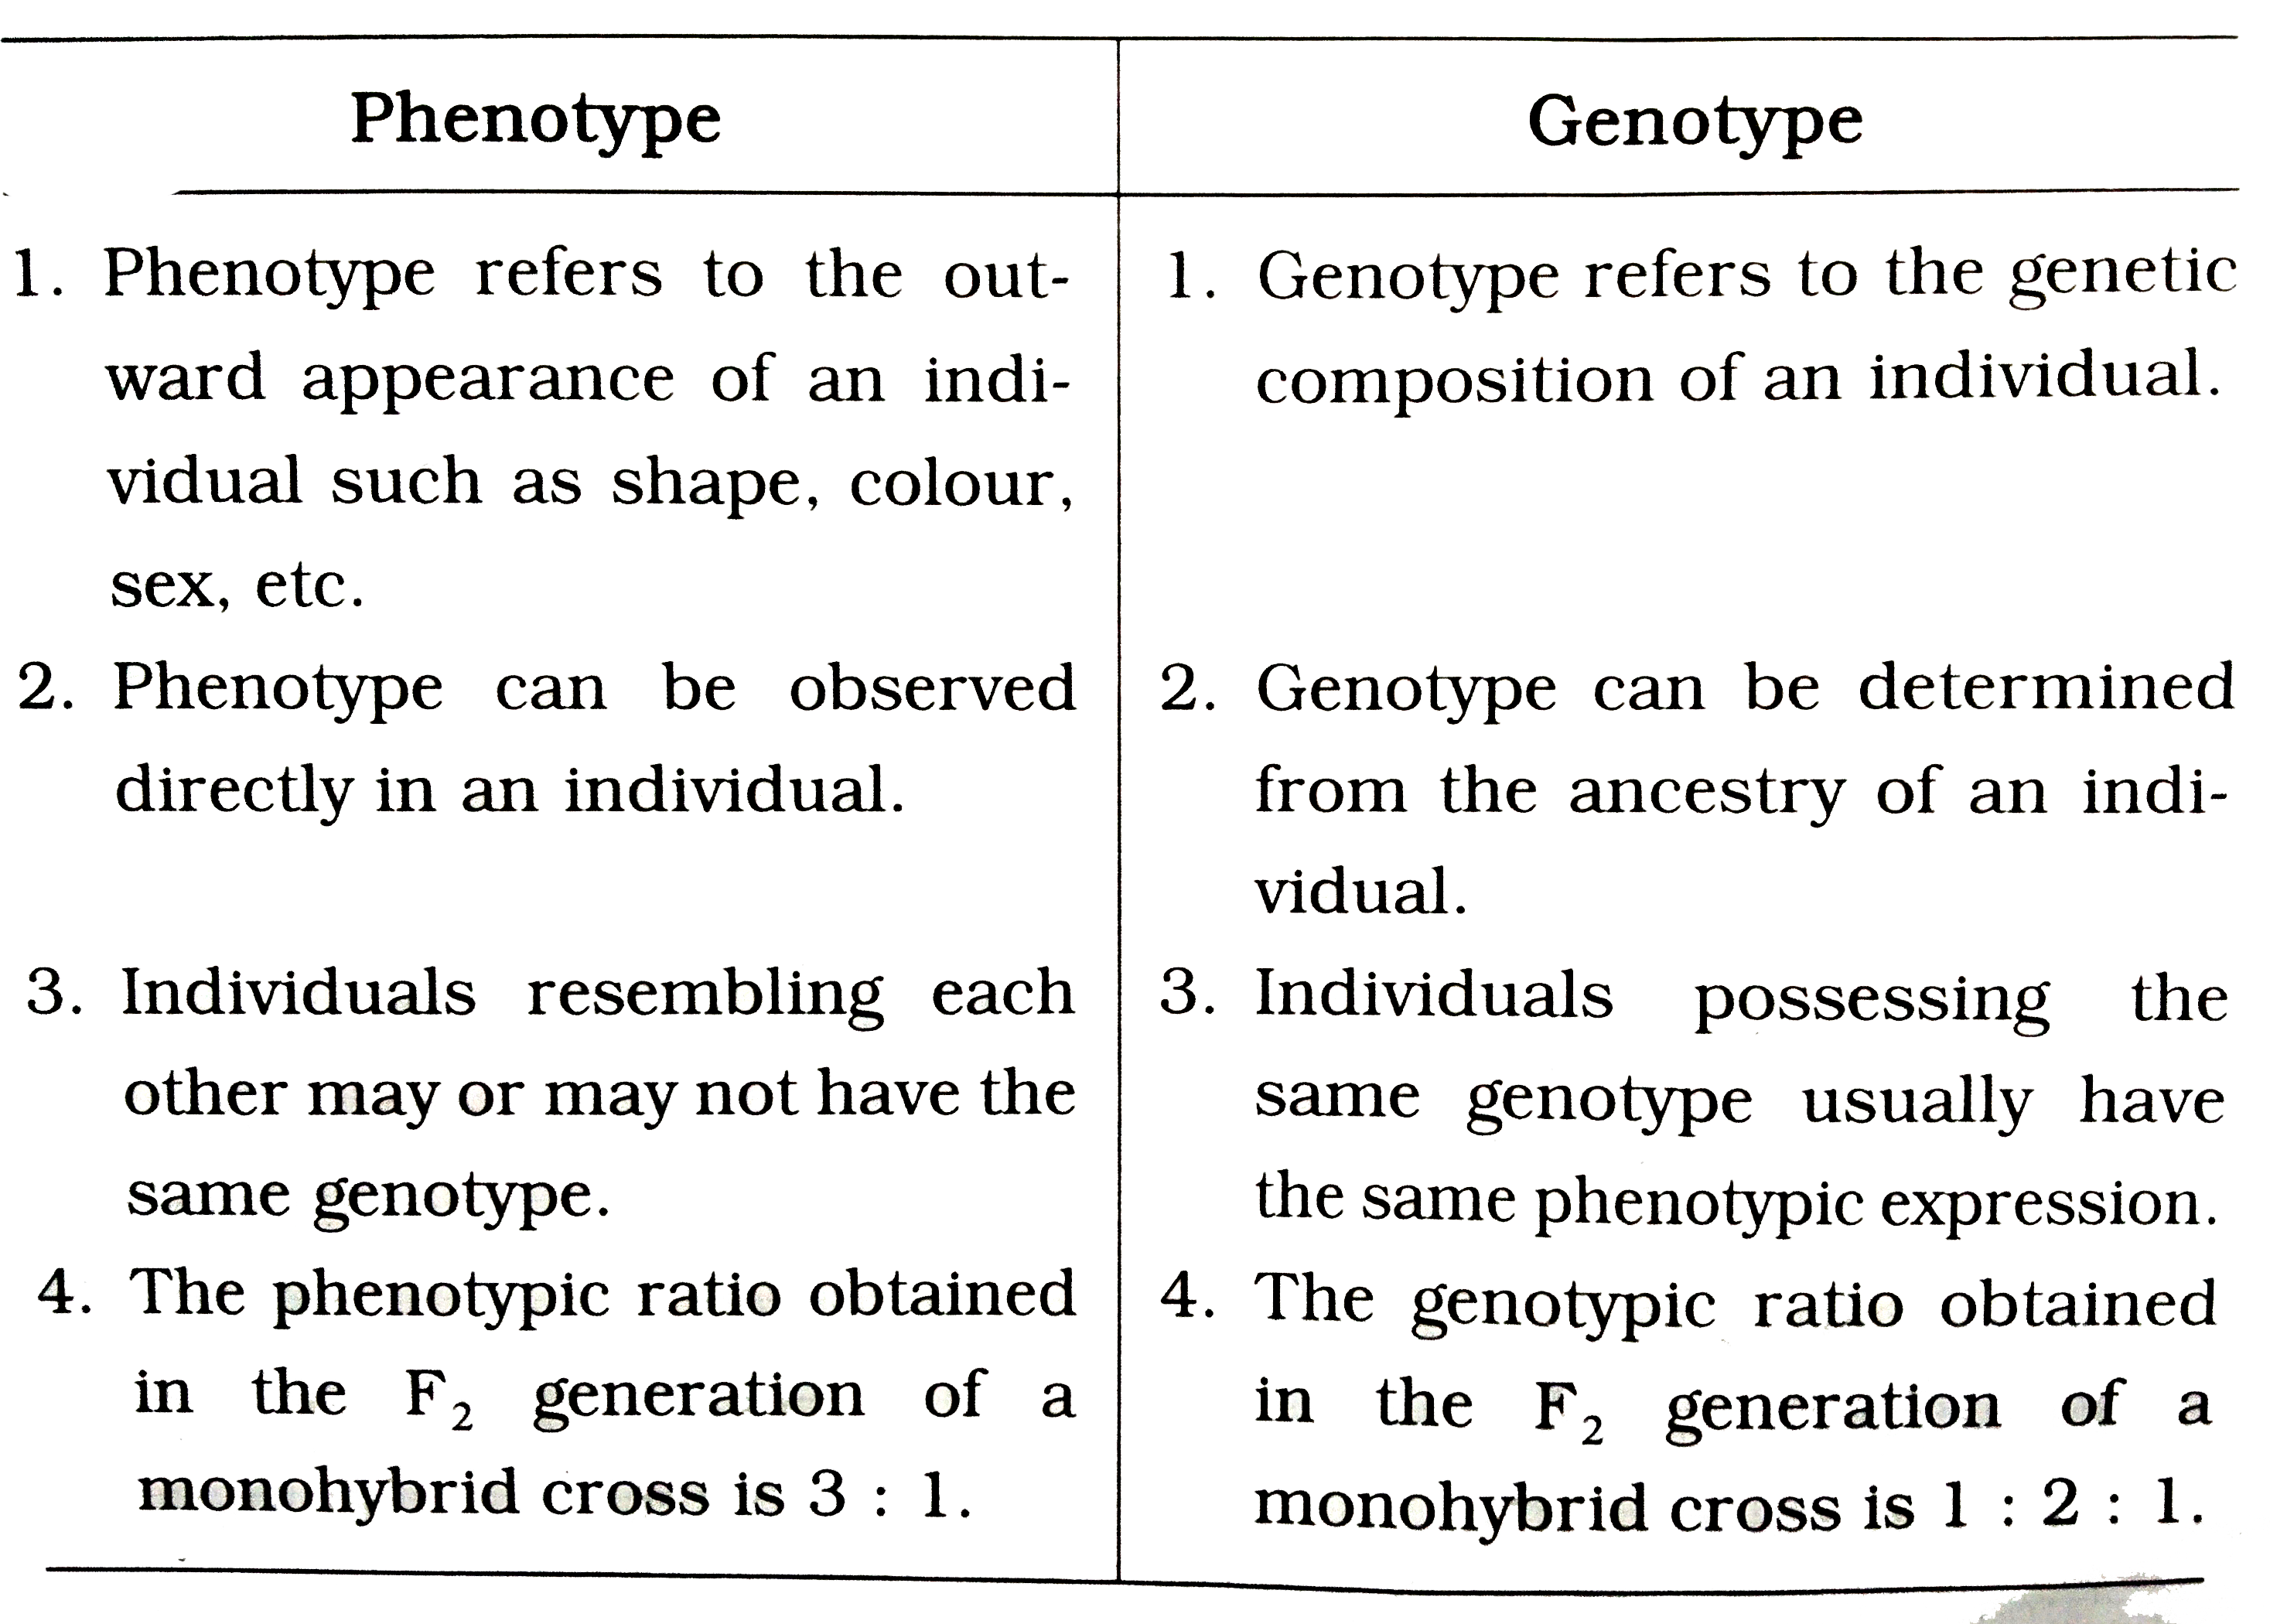
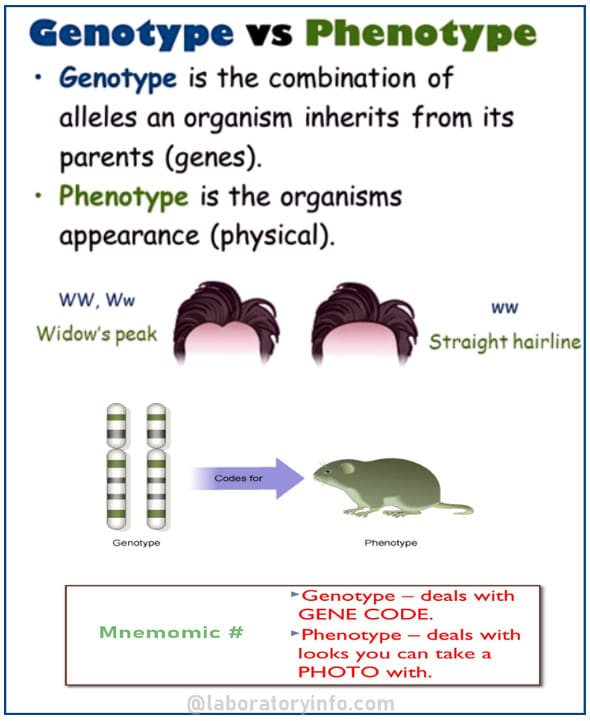
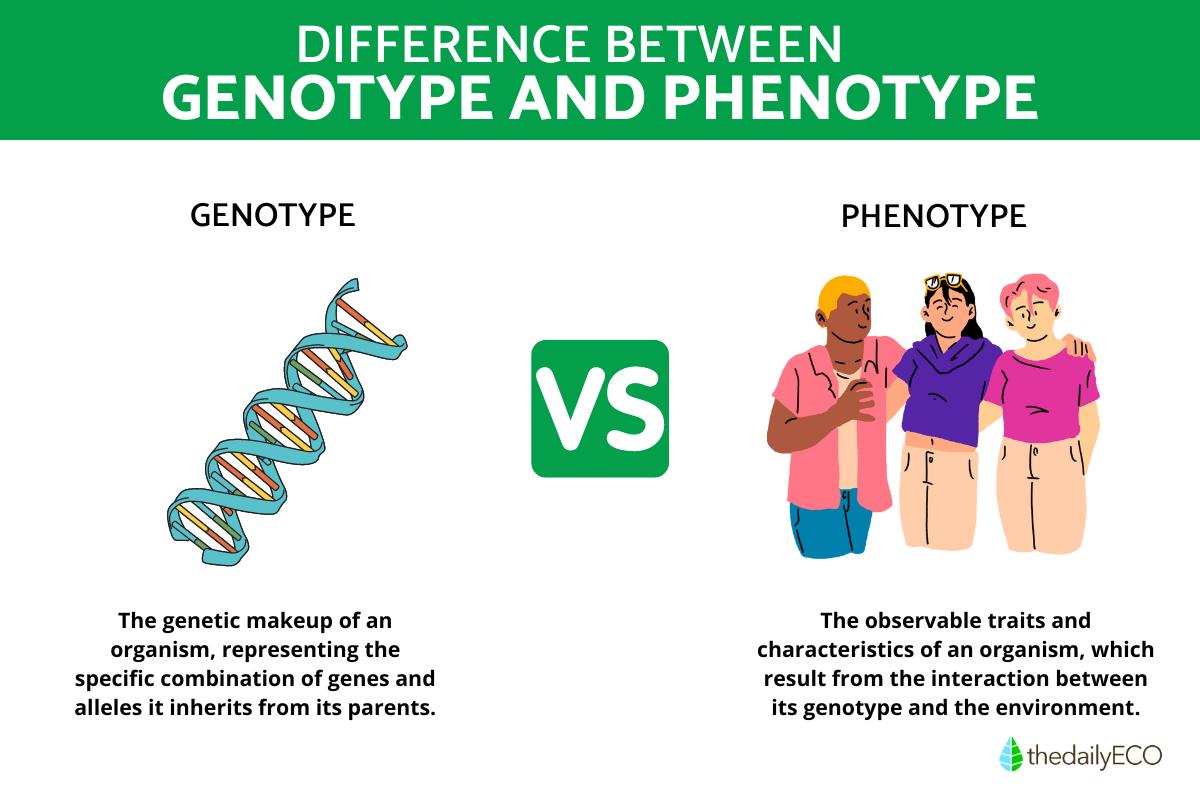
Genotype refers to the genetic makeup of an organism—the actual DNA sequence present in its cells. Phenotype refers to the observable characteristics that result from that genetic material interacting with the environment. It sounds simple on paper, but the relationship between the two is far more complex than most beginners realize. I spent years working in agricultural genetics before moving into clinical diagnostics, and one thing that consistently trips people up is assuming a direct one-to-one mapping between genotype and phenotype. The reality is messier than that, and understanding why matters if you want to actually predict outcomes rather than just catalog them.
Difference Between Genotypic And Phenotypic
How Each Term Actually Works in Practice
When I first entered the field, I treated genotype as the blueprint and phenotype as the finished building. That analogy breaks down pretty quickly. A genotype is not a fixed set of instructions—most genes can be turned on or off depending on environmental conditions, developmental timing, and epigenetic modifications. The phenotype is what emerges from all of those interactions, not just a straightforward readout of the DNA. Take something like human height. You can sequence every relevant gene and still only explain about 80 percent of the variance. The remaining 20 percent comes from nutrition, health history during childhood, hormone levels, and things we probably haven't even identified yet. That gap is the classic example of why phenotype cannot be predicted purely from genotype without accounting for environmental variables. On the flip side, identical genotypes can produce dramatically different phenotypes under different conditions. I ran into this directly when working on a project involving drought-resistant crop varieties. Two fields planted with the same genetically modified seeds showed wildly different yields and stress responses. The DNA was identical. The soil composition, water retention, and microclimate in each field completely changed how those genes expressed themselves.
The Technical Mechanics Behind the Concepts
Genotyping methods have advanced significantly. Standard approaches include PCR-based genotyping, SNP arrays, and whole-genome sequencing. Each has its own resolution, cost structure, and throughput. SNP arrays are fast and cheap but limited to known variants. Whole-genome sequencing catches everything but generates massive data volumes that require real computational infrastructure to process properly. Phenotyping is actually harder than genotyping in most practical settings. There is no single instrument that reads phenotype the way a sequencer reads DNA. You measure traits directly—height, color, enzyme activity, disease resistance—and each measurement introduces its own error. Manual phenotyping is slow and subjective. Automated phenotyping through imaging systems and sensors is faster but expensive to deploy and maintain. Here is where most people stumble: they assume more genetic data means better prediction. That assumption fails hard when the trait being studied is polygenic or environmentally sensitive. A study looking at disease susceptibility often needs thousands of samples just to detect a meaningful genotype-phenotype correlation because environmental noise drowns out the genetic signal.
Get the Full Details

A Real Problem I Encountered and How I Fixed It
During a clinical genetics project several years ago, we were tracking a particular hereditary condition where carriers were expected to show mild symptoms based on published phenotype data. About 30 percent of confirmed carriers showed zero observable symptoms. Standard interpretation would label those individuals as non-penetrant and move on, but that explanation felt insufficient. I cross-referenced their genotypes against a broader set of modifier genes that are rarely included in standard panels. Several of the asymptomatic carriers had protective variants in nearby genes that effectively compensated for the primary mutation. This is a known phenomenon called genetic modifiers, but it is easy to overlook when you are working with a focused panel that only covers the disease-associated gene itself. The workaround was straightforward once I recognized the pattern. We expanded the genotyping panel to include known modifier loci for that condition, then reclassified the asymptomatic carriers as having a modified rather than nonpenetrant phenotype. It changed how we reported risk to families, which is the whole point of doing this work in the first place.
Counter-Intuitive Insights Most Beginners Miss
One insight that does not make it into textbooks is that phenotype can sometimes be useful even when the genotype is unknown. In clinical settings where rapid decisions matter, observable symptoms and test results can guide treatment while genetic testing runs in the background. Waiting for full genotypic confirmation before starting therapy is occasionally justified but often causes unnecessary delays. Another nuance that gets overlooked is that phenotypic plasticity—the ability of one genotype to produce multiple phenotypes—is actually an adaptive feature rather than a bug. Organisms that can adjust their phenotype in response to environmental changes survive better than rigid ones. This is why genotype-first breeding programs sometimes fail in real-world conditions that differ from controlled environments.
Limitations You Need to Accept
Genotypic analysis has well-known blind spots. Structural variants, copy number variations, and repetitive regions are difficult to detect with standard short-read sequencing. These gaps matter because they are often where the functional variation lives. If your genotyping pipeline relies solely on Illumina short-read data without long-read or linked-read validation, you will miss significant variants that contribute to phenotype. Phenotypic measurement suffers from different but equally serious limitations. Trait heritability estimates vary across populations and environments, meaning a heritability figure from one study may not apply to your specific context. Broad-sense heritability includes all genetic effects while narrow-sense heritability captures only additive effects, and confusing the two leads to incorrect predictions about offspring phenotypes. The biggest bottleneck in the field right now is the integration gap. Genomic data and phenotypic data are often collected and stored in completely separate systems with different standards and formats. Projects that attempt to link them tend to spend more time on data harmonization than actual analysis. Standardized frameworks like the GA4GH protocols help, but adoption remains inconsistent across institutions.
There is no perfect shortcut around these limitations. The best approach is to acknowledge where your data will be incomplete and design your analysis accordingly rather than pretending the missing information does not exist.