What Diffusion Anime Guide Actually Covers
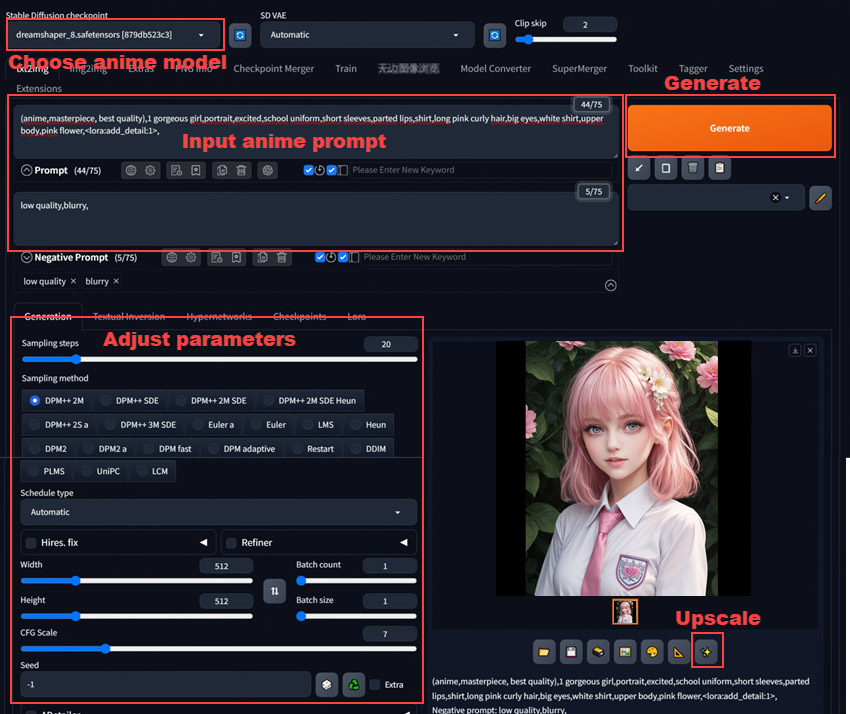
The Diffusion Anime Guide is a set of practices for generating consistent anime-style artwork using latent diffusion models, most commonly Stable Diffusion 1.5 or 2.1 pipelines. It covers model selection, training pipelines, prompting strategies, and post-processing workflows that are specific to anime aesthetics rather than photorealism. The reason you can't just swap a photorealistic checkpoint into any anime project and get good results is because anime art has fundamentally different texture distribution, color banding behavior, and edge characteristics. A normal SDXL realism checkpoint will render hair strands as fuzzy noise clusters and flatten character design into generic proportions. The guide solves this by pointing you toward anime-specific checkpoints, LoRA weights, and control networks that preserve line quality and cel-shading behavior. Most people I see trying this for the first time download a checkpoint, paste a prompt, and hit generate. They wonder why their character looks like a bad watercolor painting instead of a clean anime render. The core issue is usually that they're using the wrong sampling parameters for the model type. Anime checkpoints respond best to DPM++ 2M Karras or Euler a samplers at 20 to 30 steps with a CFG scale between 5 and 7. Anything higher than 8 on CFG will burn the colors and introduce the plastic sheen that makes everything look like a bad mobile game ad. I spent about three weeks debugging why my character consistency workflow kept producing mismatched eye colors between frames. The problem wasn't the seed or the model. It was that I was running img2img at 75% denoise with an anime checkpoint without adjusting the vae. Switching to a dedicated anime VAE file like the one included in most anime-specific checkpoints fixed the chromatic inconsistency immediately. The VAE controls how the latent space decodes into color space, and default_VAE files are tuned for photo datasets, not flat cel-shaded output.
Downloading the Right Components
You don't need a specific website to access the core tools. The base components come from a few standard places. The main Stable Diffusion web UI (Automatic1111 or ComfyUI) handles most of the pipeline. Checkpoints go into the models directory. For anime-specific work, you're looking at checkpoints from Civitai or HuggingFace repos like Anything-v5, Counterfeit, MeinaMix, or Animagine XL if you're working in SDXL space. LoRA files go into the LoRA folder. Some people bundle everything into a single installer package labeled as a Diffusion Anime Guide suite, but that's usually unnecessary overhead. The individual pieces are free and well-documented. If you want a straightforward entry point, ComfyUI with the anime checkpoint packs from the official Civitai model hub is probably the most flexible setup. It gives you node-based control over every stage of the generation pipeline, which matters when you're doing batch generation or trying to maintain consistency across multiple character sheets.
Prompting and Token Behavior Specific to Anime Models
Anime checkpoints don't use prompts the same way photorealistic models do. The token weighting system behaves differently because these models were trained on imageboard datasets with heavily tagged metadata. Tag order matters less than it does in SDXL, but tag presence is critical. Including quality tags like masterpiece, best quality, highres is still effective but diminishing in impact as newer models handle them differently. What actually moves the needle for anime generation is character-specific tag inclusion and style modifiers. For example, adding official alternate costume, school uniform, summer outfit directly changes the composition in ways that general prompts don't. The model has learned associations from thousands of tagged anime illustrations where these tags correlate with specific pose, framing, and lighting conventions. A prompt with proper quality tags and no style specification will still generate anime, but it tends toward generic poster-child compositions rather than scene-specific shots.
Get the Full Details
ControlNet and Line Art Preservation
This is where the workflow gets practical. If you're generating reference sheets or consistent character designs, ControlNet is non-negotiable. The anime line art models for ControlNet (specifically the diffusers anime lineart variant or the lineart_anime model) will preserve your composition while letting the diffusion model fill in color and detail. I use this constantly when generating turn-around sheets where the pose needs to stay identical across angles. The edge detection models like Canny and Scribble also work but tend to produce harder, more rigid outputs that look like colored-in worksheets rather than polished illustrations. The anime lineart model is softer and lets the diffusion process add natural variation while keeping structural integrity. Denoise strength between 0.55 and 0.75 gives you the right balance between following your input and allowing the model creative room.
Common Pitfalls That Break Everything
The biggest issue I see repeatedly is upscaling without proper tile settings. People generate at 512 by 712, then run the result through a basic upscaler and wonder why the anime lines become muddy and the colors bleed. Tile diffusion with a resample method like Lanczos and tile size 512 or 640, using an anime-specific upscaler model like 4x-AnimeSharp or ESRGAN_4x, keeps the line quality intact through the entire process. Running a standard RealESRGAN upscaler on anime art will softening the lines to the point where they lose their characteristic crispness. Another issue that nobody talks about enough is aspect ratio snapping. Most anime checkpoints were trained primarily on 3 by 4 and 4 by 3 ratios. When you push them into extreme widescreen or portrait formats, the model starts redistributing composition elements awkwardly. Characters get cut off, backgrounds warp, and details compress. Staying within one aspect ratio step of the training distribution prevents most of these artifacts. Going from 512 by 768 to 768 by 512 is fine. Jumping to 1024 by 256 will produce structural problems that post-processing can't easily fix.
When This Approach Fails Completely
Diffusion-based anime generation does not work well for frame-accurate animation. If you need consistent character appearance across dozens of sequential frames, you will spend more time fighting randomization than producing usable output. The models are inherently probabilistic, and even with the same seed and prompt, every generation differs enough to break continuity. For animation work, the practical solution is generating a single consistent reference sheet and then using it as a ControlNet input for each frame, accepting that minor variations will exist and editing them in post. The other hard limitation is text and UI elements. Anime checkpoints are not trained for readable typography. Any attempt to generate signs, menus, speech bubbles with text, or on-screen UI will produce gibberish characters that look vaguely linguistic but mean nothing. You need to generate the scene without text and composite the typography separately. This adds about five to ten minutes per image to the workflow but it's the only reliable approach.
Practical Batch Generation Workflow
Once you have your pipeline set up, the typical production workflow runs like this. You start with a base prompt and negative prompt, generate 4 to 8 variants at low resolution to evaluate composition, select the best one, apply ControlNet refinement if needed, upscale with tile diffusion, and then do a final pass with inpainting for any areas that didn't resolve cleanly. A full batch of 10 character sheets at decent resolution takes roughly 40 to 60 minutes on a mid-range GPU like an RTX 3080. On a 4090, that drops to about 15 to 20 minutes. The difference isn't just speed. Higher VRAM allows larger batch sizes and higher resolution outputs without hitting memory limits mid-generation. The Diffusion Anime Guide concepts boil down to understanding that anime diffusion is a different beast from general diffusion. The models, the samplers, the upscalers, and the ControlNet choices all need to be aligned toward that aesthetic rather than treated as generic image generation tools. Get those pieces right and the output quality jumps significantly. Get them wrong and you're fighting the model the entire time.