Diffusion Inpainting Isn't Magic — It's Math You Need to Control
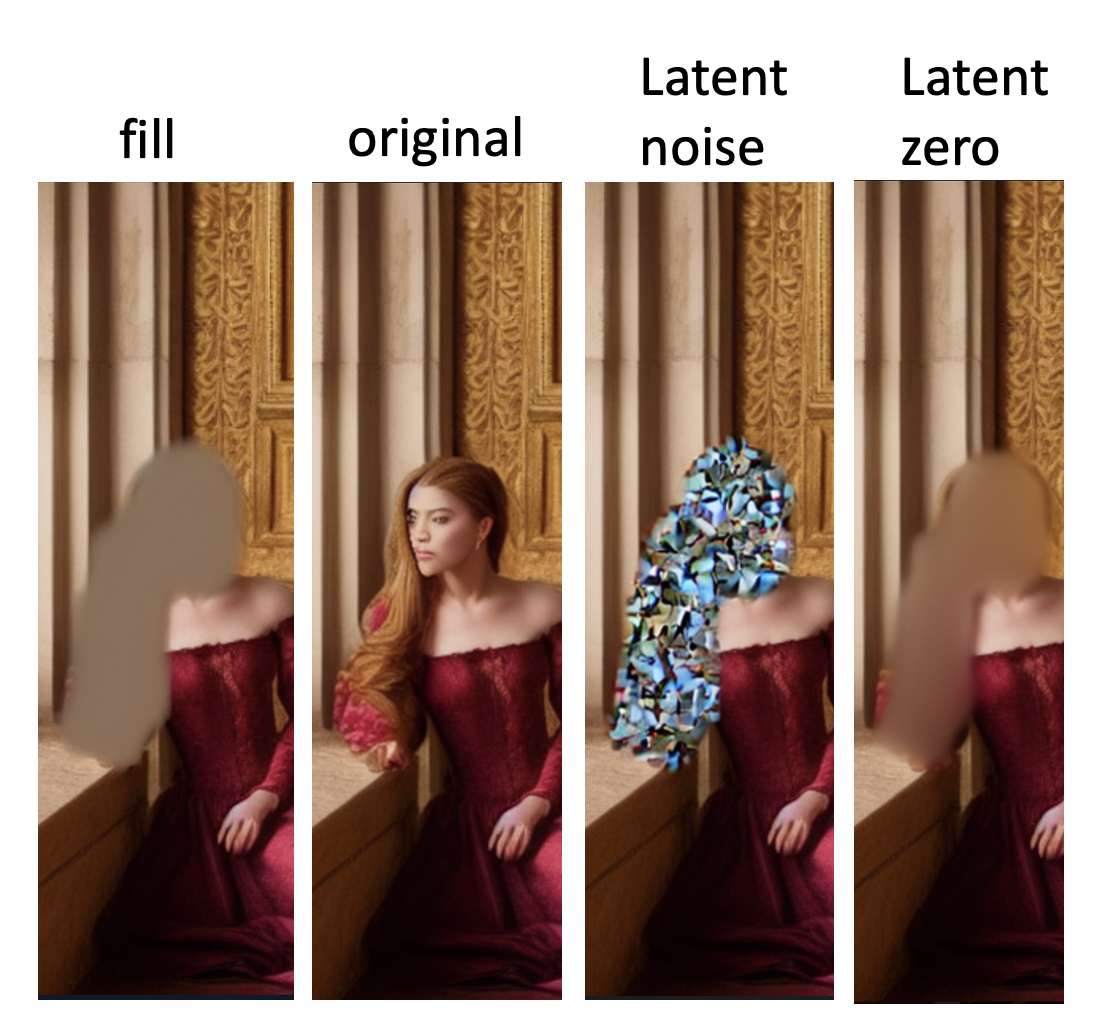
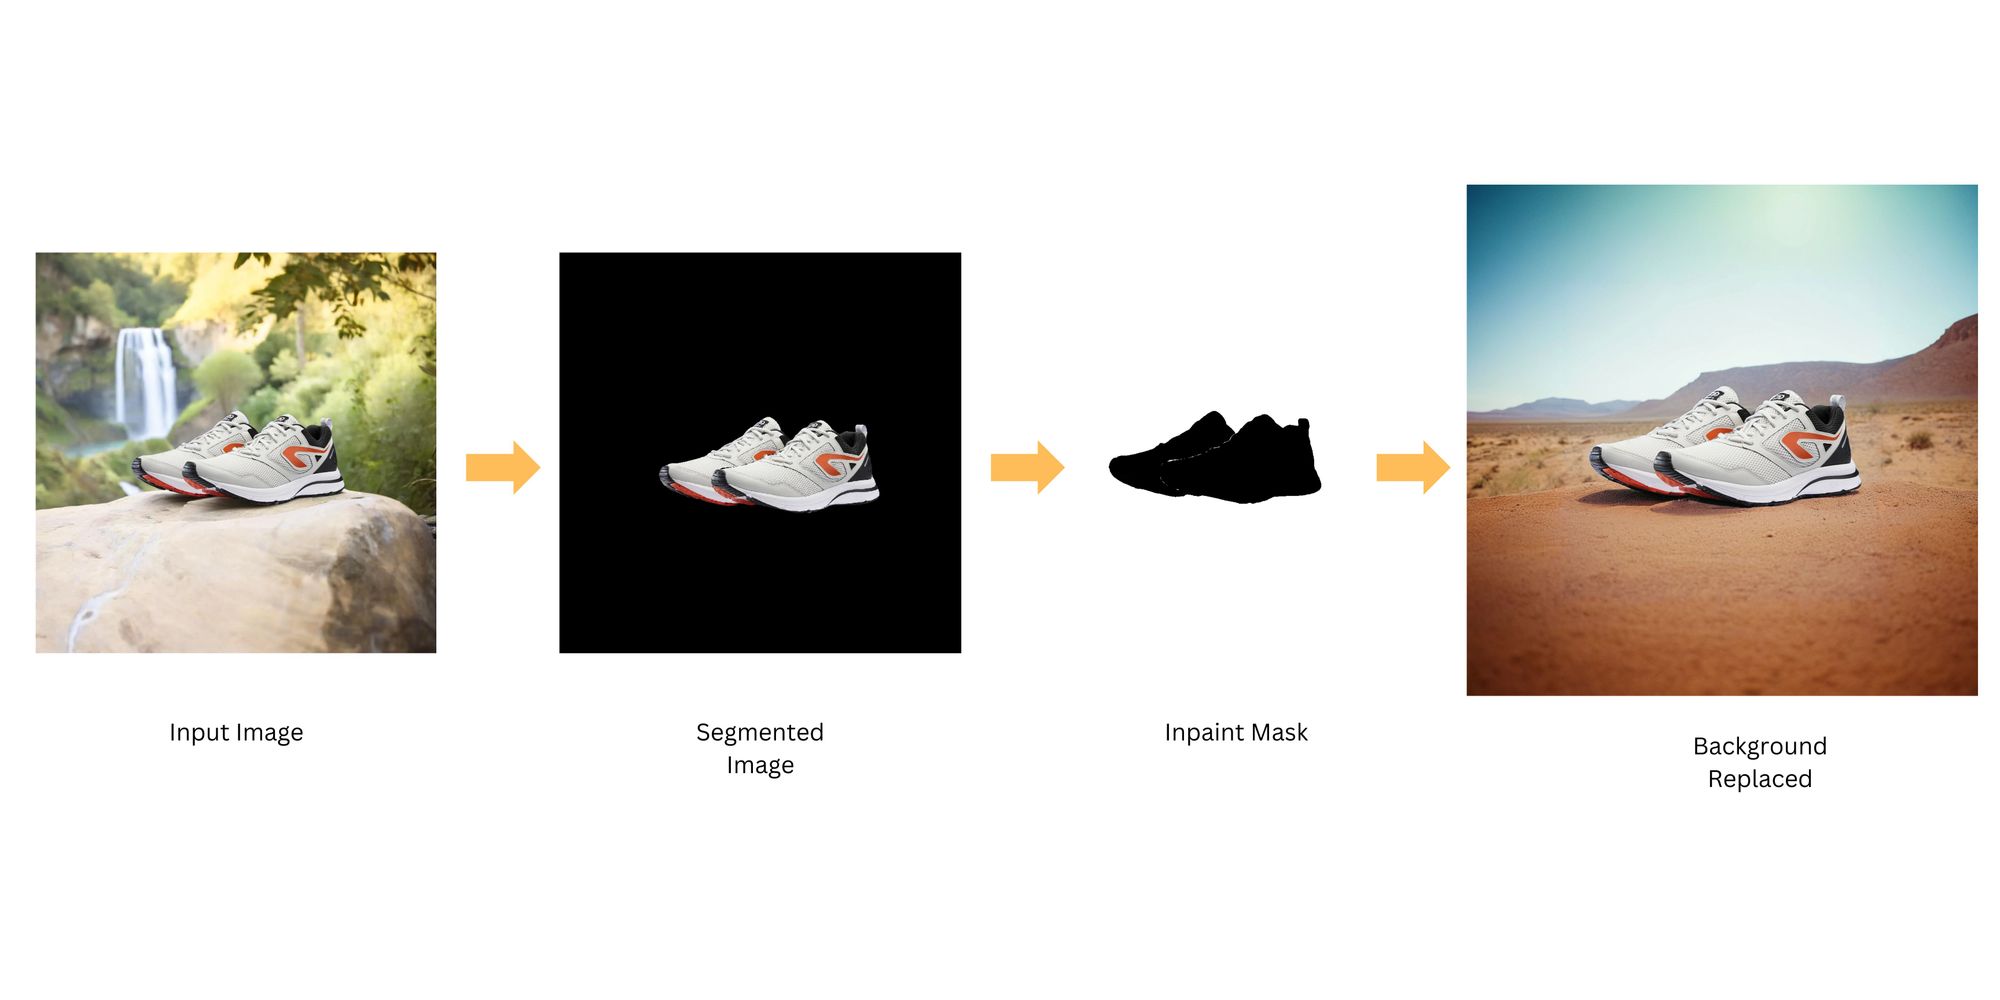
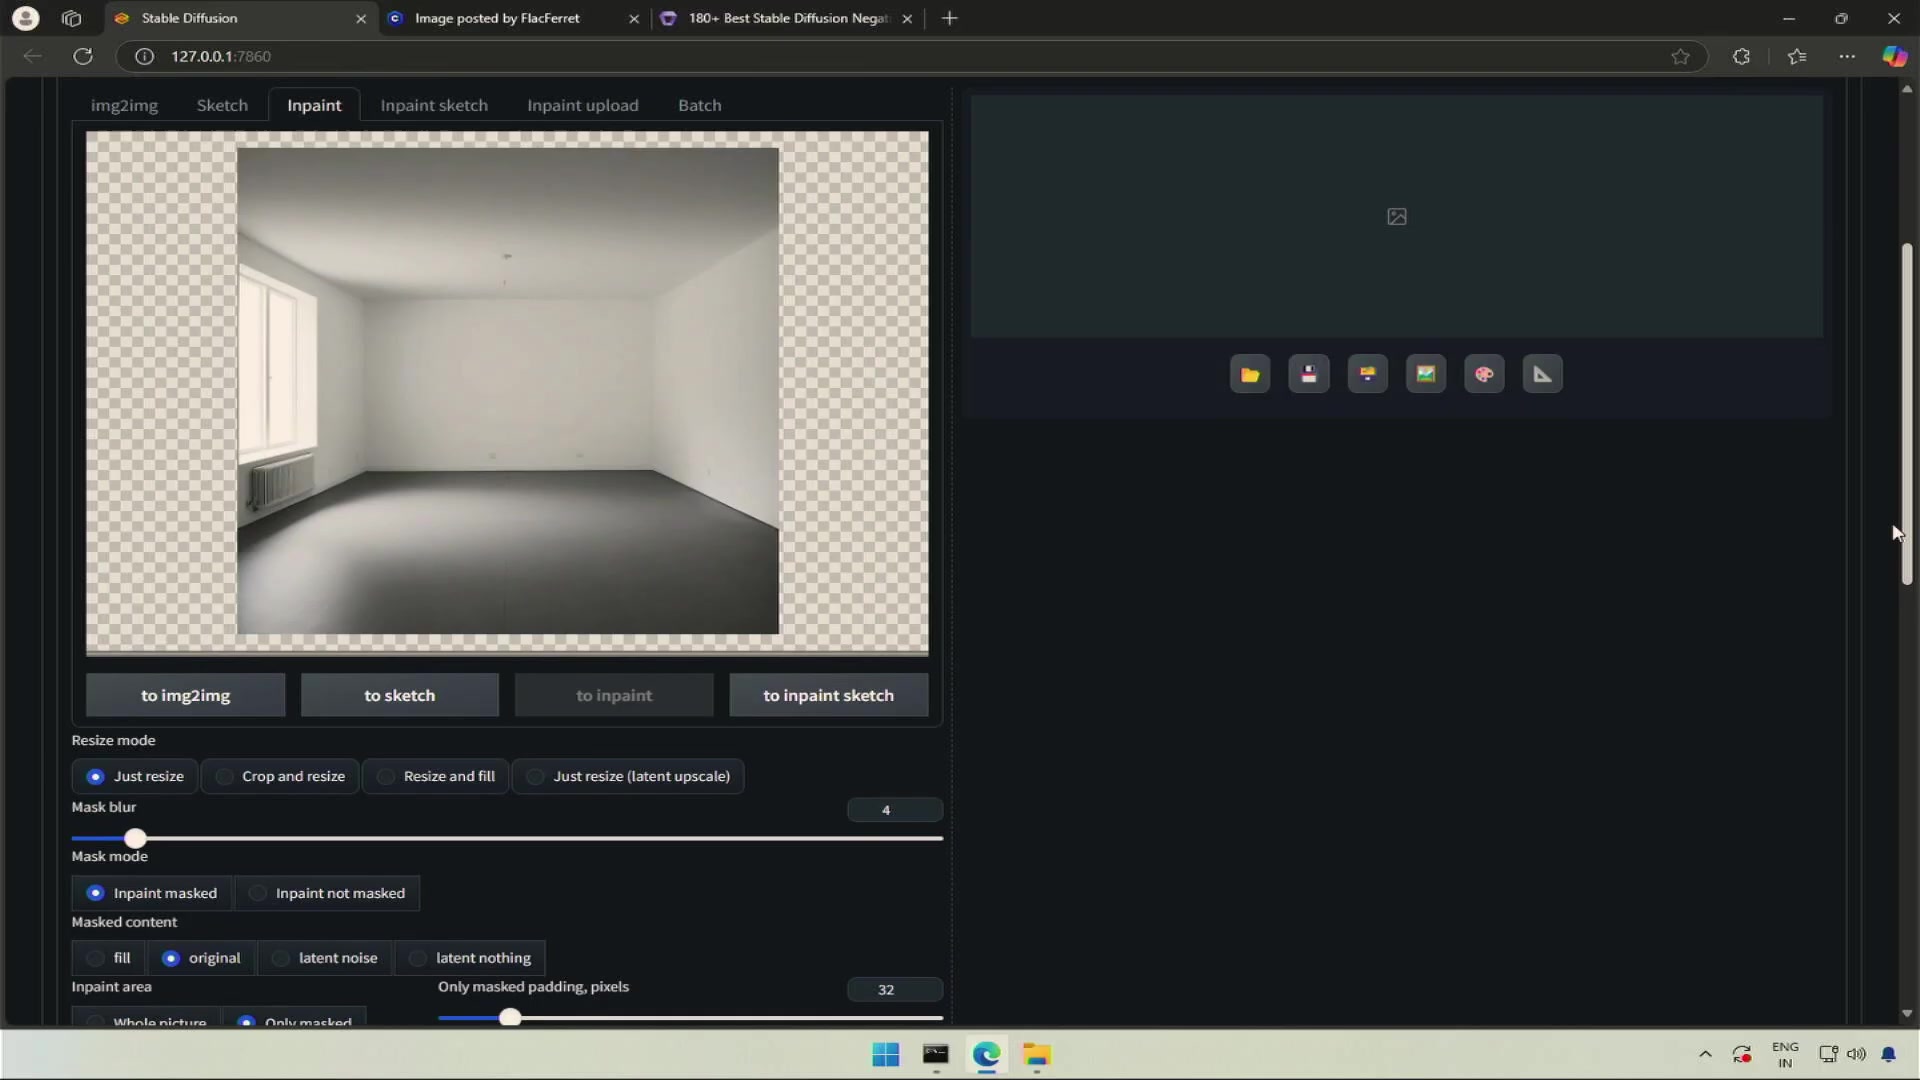
Most people treat inpainting like a magic eraser tool. They mask an area, type a prompt, and hope for the best. It doesn't work that way. The model is trying to reconstruct pixels based on the surrounding context and your text description, but it has no real understanding of physics, lighting, or perspective. You have to guide it precisely or you'll end up with melted textures and ghost artifacts. The core workflow uses a pretrained diffusion model — usually Stable Diffusion 1.5, SDXL, or a fine-tuned variant like DreamShaper or Juggernaut. You run it through a UI like Automatic1111, ComfyUI, or Fooocus. The inpaint pass takes your original image, applies a mask, and generates new content only within that masked region while keeping everything outside it intact. Here's the setup most people get wrong before they even start generating. Your mask needs a feathered edge. A hard, pixel-perfect mask creates visible seams. Feather between 8 and 32 pixels depending on your image resolution. In Automatic1111, that slider lives right in the inpaint tab. Go too high and the model blends into the surrounding area too aggressively, losing detail. Go too low and you get a hard boundary that screams "edited." The sweet spot depends entirely on the texture of what you're replacing.
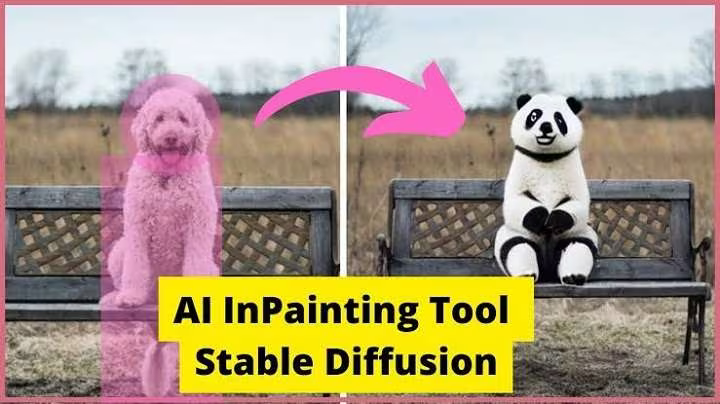
The prompt should describe what you want to appear, not what you're removing. If you're replacing a person with a tree, prompt for a tree with leaves, bark texture, and the appropriate lighting. Don't include "remove person" or "no human" in your prompt — the model ignores those instructions anyway and might actually introduce more artifacts. The denoising strength is where most beginners lose control. Set it between 0.6 and 0.85. Lower values preserve more of the original masked pixels, which is good for minor touch-ups. Higher values let the model generate more freely but can completely ignore your intended subject. I typically start at 0.7 and adjust from there. Resolution matters more than people admit. If your source image is 1024x1024 and your mask covers a small region, the model still processes the full resolution. That's why inpainting on upscaled images often looks better — the model has more pixel data to work with when reconstructing textures. But upscaling too far without adjusting your denoising strength will just create noise. There's a balance. Use regional prompting if your UI supports it. Automatic1111 has the Region extension. ComfyUI has region nodes built in. This lets you assign different prompts to different parts of the mask. Replace a sky and a building in the same image? Give each region its own prompt instead of one bloated description that confuses the model.
The Details That Separate Good Results From Garbage
The VAE decoder is non-negotiable. Running inpaint with the wrong VAE or skipping it entirely produces washed-out, muddy colors. Make sure your inpaint model and your base model use the same VAE. If you're using SDXL, the VAE is baked into the checkpoint. If you're on SD 1.5, you might need to load one separately. Check what your model was trained with and match it. ControlNet can be a lifesaver for structure. If you're inpainting an object that needs to match the perspective of the scene — like adding a window to a building or extending a road — use a depth or lineart ControlNet pass alongside your inpaint. It constrains the generated geometry to match the existing scene. Without it, the model will generate plausible textures but likely ignore the vanishing point and proportions. Hires fix after inpainting helps. Running a second pass at a higher resolution over your inpainted result smooths out texture inconsistencies between the generated area and the original image. Set the denoising strength low here — 0.2 to 0.35. You're not rewriting the image, you're blending the edges.
Get the Full Details
My Actual Problem With Face Inpainting
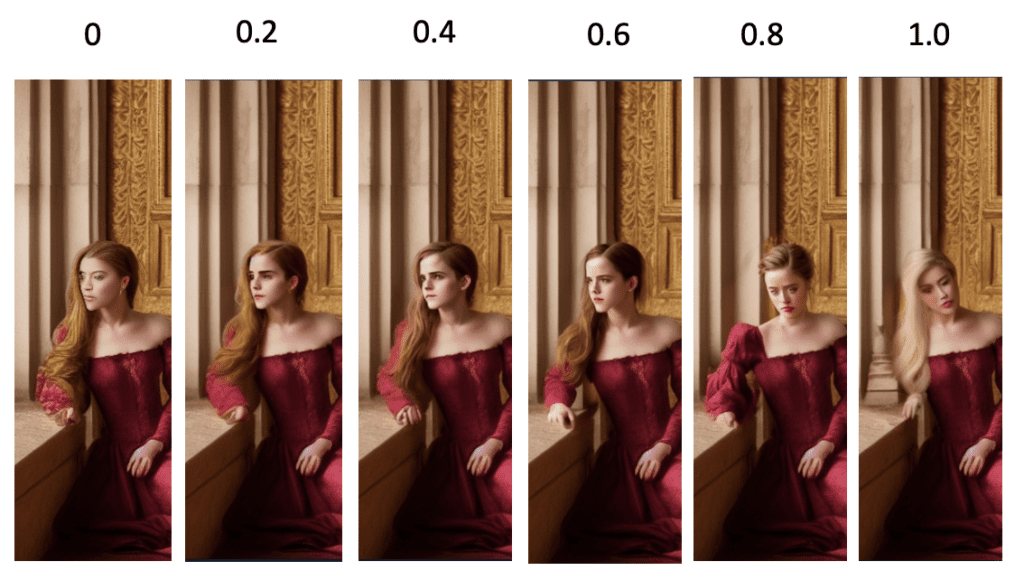
I was inpainting a portrait — replacing sunglasses with eyes — and every attempt produced asymmetric faces where one eye was sharper than the other, or the skin texture around the eyes didn't match the rest of the face. The model kept generating generic placeholder faces rather than integrating with the person's actual features. The workaround was threefold. First, I used a face-focused inpaint model like Counterfeit orREVAnimated rather than a general-purpose checkpoint. Second, I set denoising to 0.55 instead of the usual 0.7 to preserve more of the original facial structure. Third, I ran a final pass with GFPGAN or CodeFormer as a post-process restore step, but only on the face region, not the whole image. This took about 10 minutes per attempt but the results were consistently better than any single-pass approach. Different models handle different scenarios, and some are genuinely bad at certain things. SD 1.5 struggles with hands, complex geometry, and text. SDXL is better but still fails on fine details like individual blades of grass or small text. If you're inpainting architectural details at distance, you're likely to get warped lines. If you're replacing skin with fabric, the texture transition often looks pasted on. These aren't bugs — they're limitations of how the model was trained on datasets that don't cover every possible edit scenario. For cases where diffusion inpainting simply cannot produce reliable results, traditional tools still win. Photopea's content-aware fill handles uniform textures like skies and water faster and more consistently than any diffusion model. For small object removal on clean backgrounds, the heal brush in Photoshop or GIMP does the job in seconds without requiring a GPU or prompt engineering. I use these first and only turn to inpainting when the subject is complex enough that algorithmic fill would leave visible artifacts.
Memory constraints are another hard limit. SDXL inpainting on a 24GB GPU at 1024x1024 with a large mask can push VRAM to the edge. Use the xformers or Triton memory-efficient attention flags in Automatic1111. In ComfyUI, switch to the memeff attention mode. This cuts VRAM usage by roughly 30 to 40 percent without meaningfully affecting output quality. If you're on 8GB or less, SD 1.5 is your only realistic option for anything beyond tiny masks.
Download Links and Model Sources
Stable Diffusion itself is open source and available on Hugging Face under the Stability AI license. The checkpoints live at huggingface.co/stabilityai/stable-diffusion-xl-base-1.0 and huggingface.co/stabilityai/stable-diffusion-2-1. Fine-tuned inpainting models are scattered across Civitai and Hugging Face. Search for "SDXL inpaint" or "SD1.5 inpaint" and sort by downloads. The top results are generally safe, but always check the model card for licensing restrictions if you plan commercial use. Automatic1111 runs on GitHub at github.com/AUTOMATIC1111/stable-diffusion-webui. ComfyUI is at github.com/comfyanonymous/ComfyUI. Both are free. Fooocus is simpler but more limited at github.com/lllyasviel/Fooocus. If you're new to this, start with Fooocus to understand the basics, then move to Automatic1111 or ComfyUI when you need control.
Advanced Nuance: The Mask Expansion Trick
Most people don't know about mask padding, but it changes results significantly. When you draw a mask, the model samples from pixels immediately adjacent to the mask boundary. If your mask edge is exactly on a hard transition — say, the edge of a building against the sky — the model sees both regions and gets confused. Expanding the mask by 4 to 16 pixels pushes the boundary into uniform area, giving the model cleaner context to work from. The inpainted region will naturally blend back into the original edge during decoding. In Automatic1111, the "mask blur" and "mask expansion" sliders control this directly. In ComfyUI, you apply a dilate/erode node to the mask before feeding it into the inpaint pipeline. Another thing nobody talks about enough: the order of operations matters. If you're doing multiple inpaint passes on the same image, do lighting and color correction first, then geometry changes, then fine detail. The model's noise schedule assumes a certain directionality. Running detail passes before structural passes creates compounding artifacts that get worse with each iteration. I've seen people spend an hour on a single image only to realize they did the steps backward and had to start over from the base image. The sampler choice also influences inpaint quality more than most guides mention. DPM++ 2M Karras gives consistent results across most scenarios. Euler a is faster but can produce softer outputs. DDIM is the fastest but lowest quality. For portrait work, I use DPM++ 2M Karras with 30 steps. For textures and environments, I sometimes drop to 20 steps since the model doesn't need as many iterations to get coherent patterns. More steps does not always equal better quality — past 40 steps on inpaint, you typically just see marginal improvements that are barely noticeable at screen size.
If you need something I haven't covered, the documentation for Automatic1111 is thorough and the Discord community is active. Just don't expect patience when you ask questions that the manual already answers.