The actual process nobody talks about
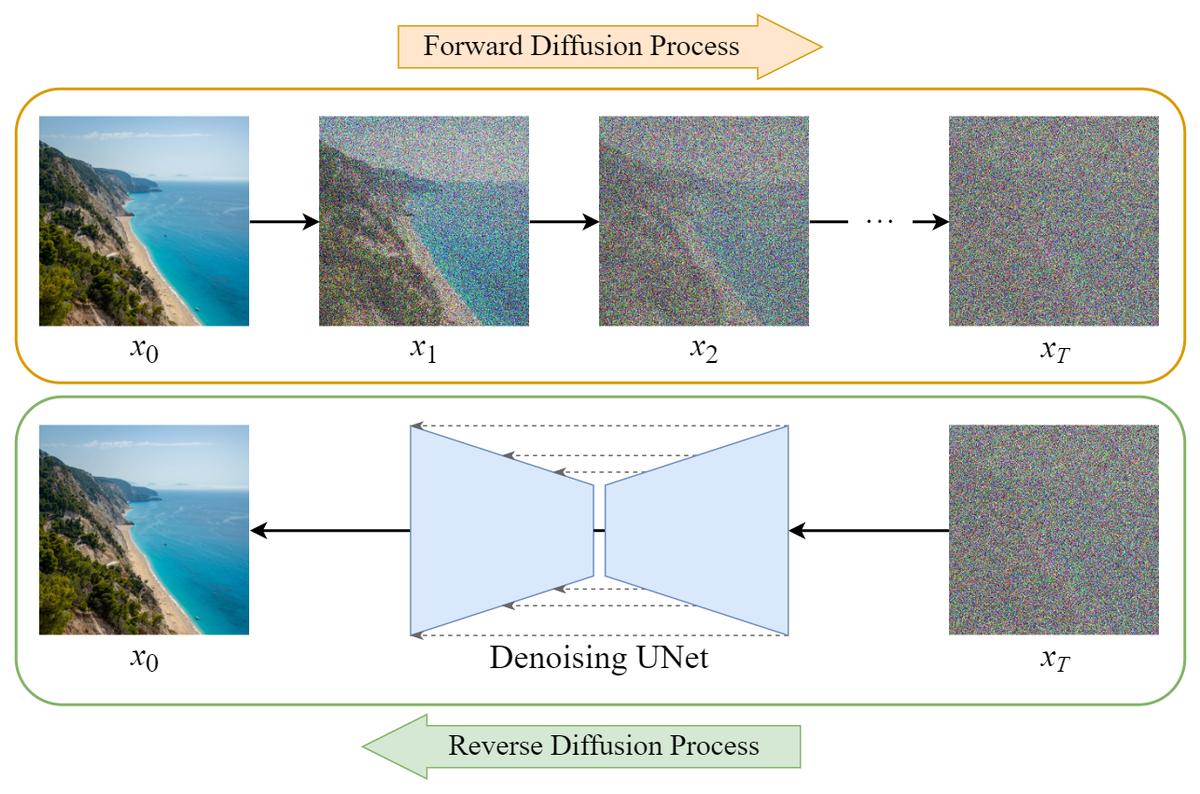
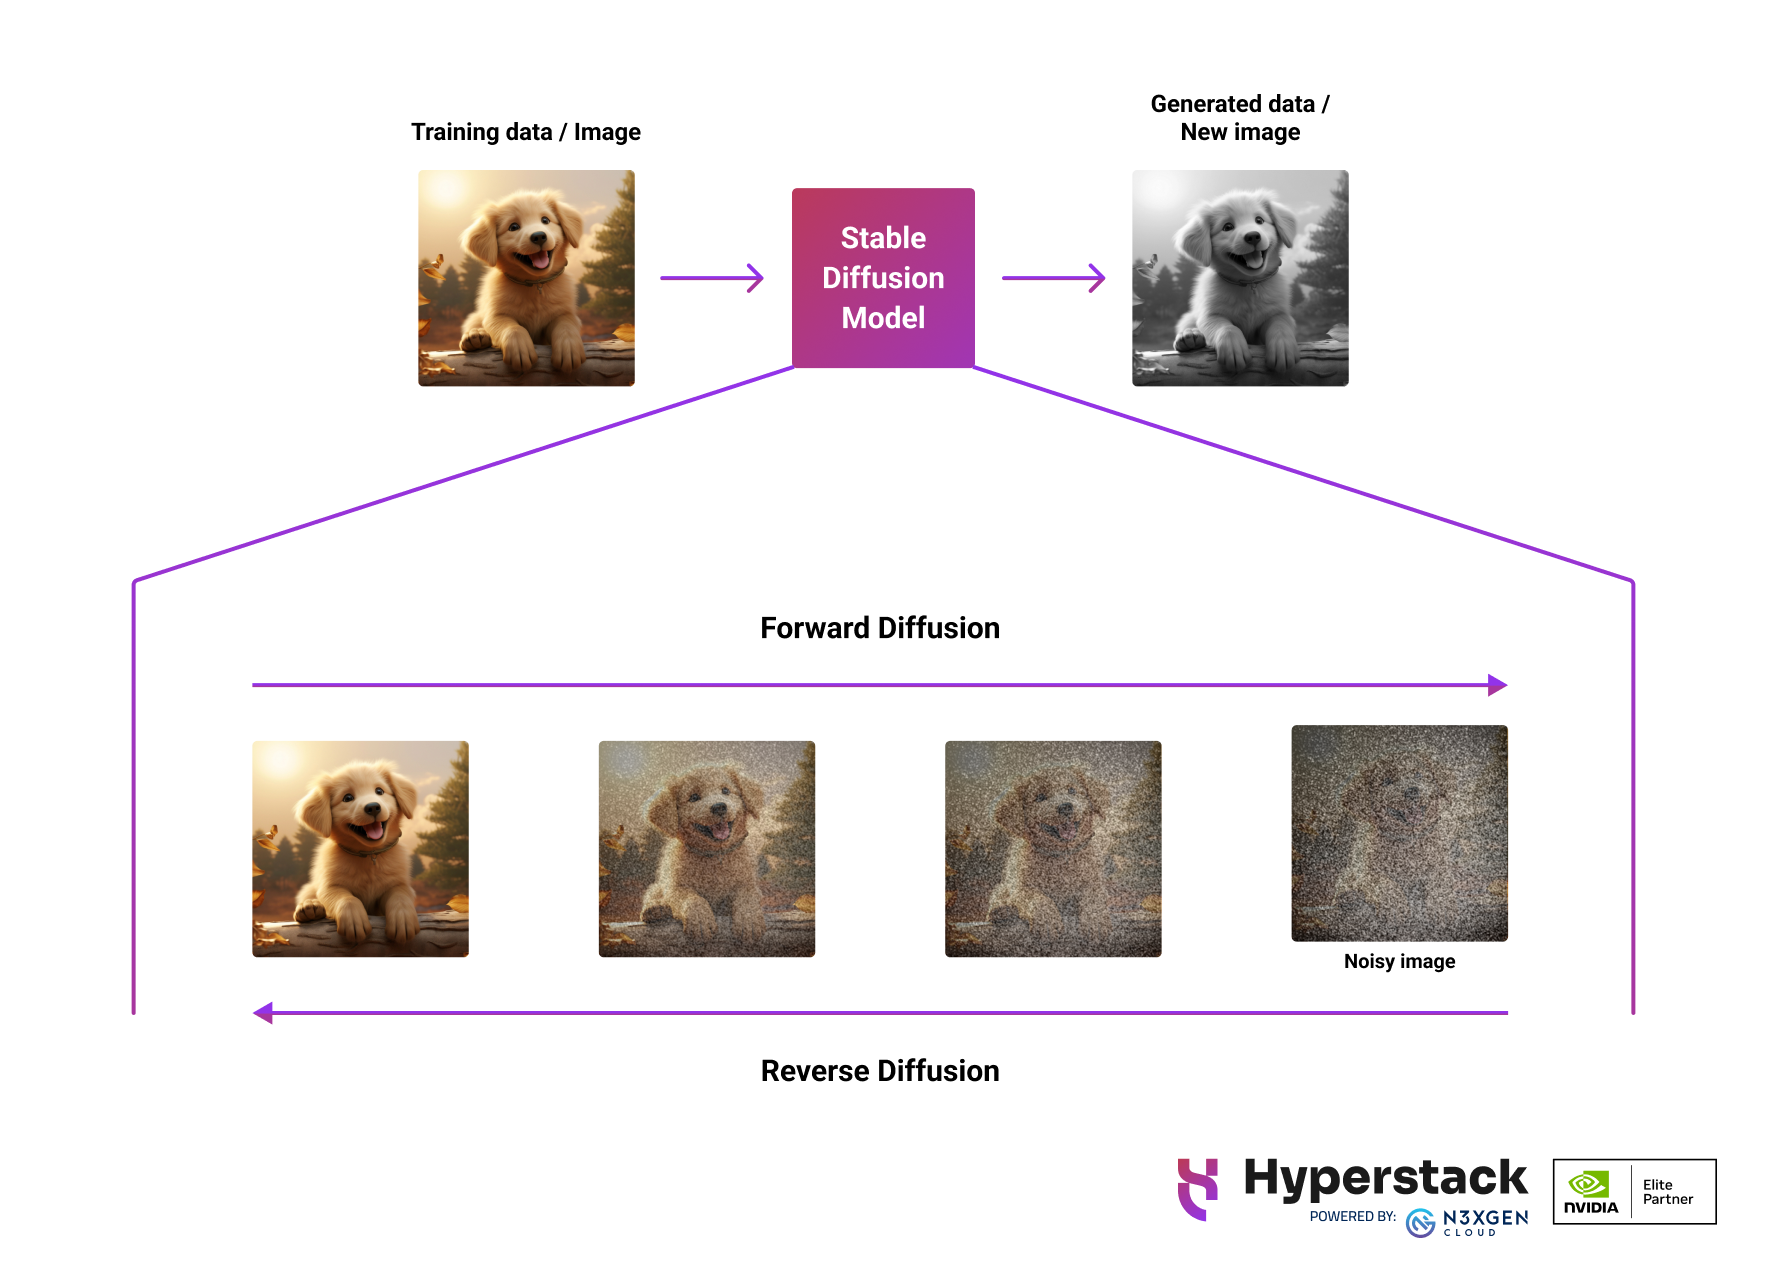
Most people think Diffusion Model Training is just firing up a script and waiting. The reality is mostly data cleaning, hyperparameter debugging, and watching your GPU fill VRAM one batch at a time. I spent about three weeks on a small text-to-image project before I actually understood what went wrong when things went wrong. The first week was just staring at loss curves that never seemed to converge properly. The core mechanism is straightforward enough on paper. You take an image, gradually add Gaussian noise to it over a series of timesteps, and then train a neural network to reverse that process. The network learns to predict the noise that was added at each step. During inference, you start with pure random noise and iteratively denoise it until you get something recognizable. The architecture behind most of this is based on U-Nets with attention layers, and the training objective is usually a simple MSE loss between predicted and actual noise.
Getting started with Diffusion Model Training
I started with Stable Diffusion's implementation because it was the most documented option available. The codebase is on GitHub and you can find training scripts in the repository. You need a dataset in a format the trainer understands — ideally paired image-text data or just images if you are doing unconditional training. I used roughly 8,000 images for my first attempt, which turned out to be both too little and too much in equal measure. The training command itself is deceptively simple. You set your batch size, learning rate, number of epochs, and point it at your dataset directory. For a 512x512 model on an A100, a reasonable starting point is a batch size of 32, a learning rate around 1e-5, and somewhere between 10 and 20 epochs. That last number is where people get confused. More epochs does not automatically mean better results. I trained for 40 epochs on my second attempt and the outputs were worse than my 15-epoch run because the model overfit to the training distribution. You will also want to set up a validation loop. Without it you are training blind. I used a simple metric where I generate a handful of images every few hundred steps and save them to a folder. Looking at those images later tells you more than any loss number ever will. The loss curve from my first attempt kept dropping but the generated images looked increasingly broken around epoch 8, which meant something was wrong with the noise schedule or the model capacity, not the optimizer.
One thing that catches people off guard is the VRAM usage. Even a base model with no optimization takes up significant memory when you factor in the optimizer states. Mixed precision helps but it is not a free pass. I had to enable gradient checkpointing and lower the resolution to 256x256 initially just to fit a batch size of 8 on a single GPU. Once I moved to a multi-GPU setup with model parallelism, everything smoothed out considerably.
Get the Full Details
Things that actually break during training
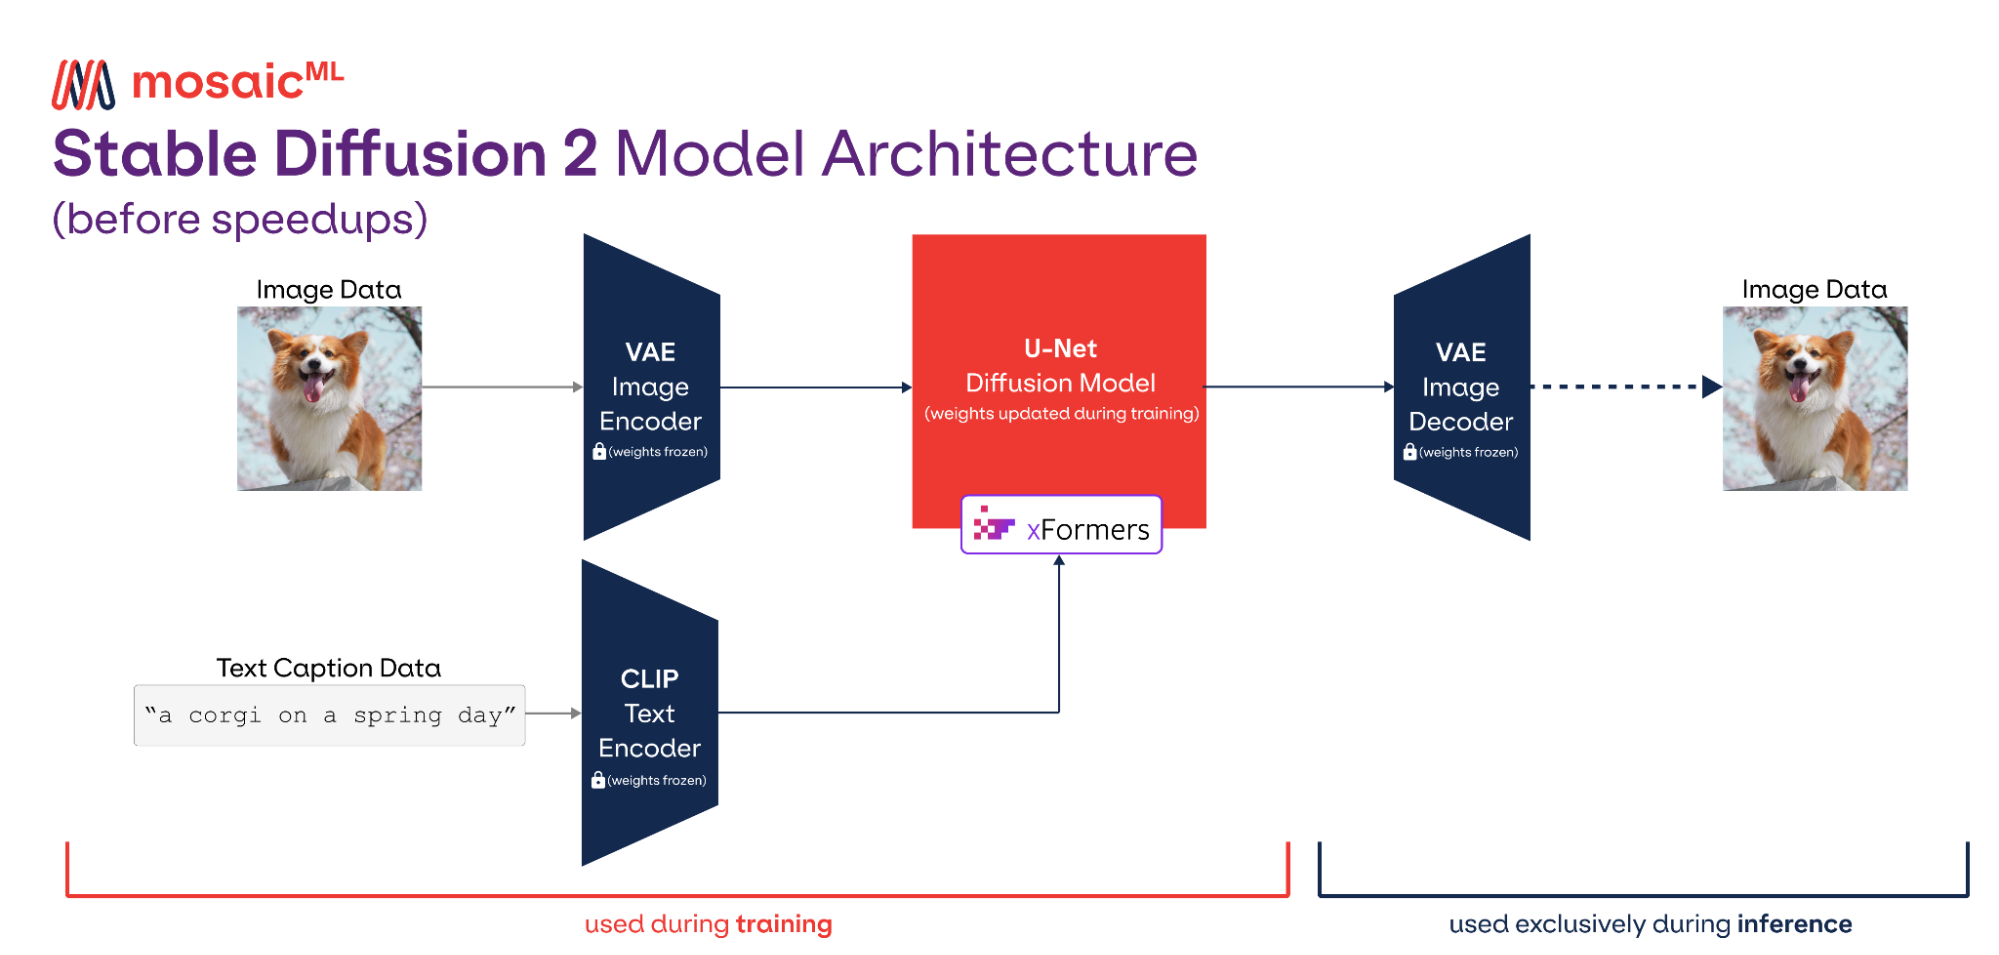
There is a specific issue with latent diffusion that most tutorials gloss over. When you train in the latent space using a pretrained VAE, the VAE encoder and decoder are frozen, which means any artifacts in how the VAE compresses your images become part of the training signal. My images came out with this strange smudged quality around edges and textures that should have been sharp. The fix was not to retune the diffusion model but to fine-tune the VAE itself alongside the diffusion UNet. That took another week of experiments. Another problem I ran into was class imbalance in my dataset. I had a lot more images of one type of subject than another, and the model learned to bias heavily toward the majority class. I solved this by implementing a weighting scheme that downsampled the oversampled classes during training. It is a small change but it made a noticeable difference in output diversity. Without it, every generation looked like a variation of the same few concepts. Learning rate scheduling also matters more than people realize. A flat learning rate works for the first few thousand steps and then starts causing instability. I switched to a cosine decay schedule with a warmup period of about 500 steps and the convergence became much more stable. The difference between a constant 1e-5 and a cosine schedule that ramps down to near zero is the difference between a model that trains cleanly and one that oscillates uselessly.
What nobody warns you about
The biggest hidden cost is evaluation. Training a diffusion model is one part of the work. Evaluating it properly requires generating hundreds or thousands of samples and running metrics like FID or doing manual inspection. I spent more time on evaluation than on the actual training. Automated metrics like FID are useful for comparing runs but they do not tell you if the model is hallucinating structures or generating coherent content. You need both numbers and eyes-on samples. Data quality is another area where shortcuts fail. No amount of training trickery will compensate for low-resolution, poorly captioned, or misaligned image-text pairs. I learned this the hard way when my initial models produced blurry, incoherent outputs despite having good loss numbers. The captions were generic and unhelpful, and many of the images had compression artifacts from being scraped. Cleaning the dataset took longer than training the model itself. I ended up re-captioning everything with a CLIP-based model and filtering out low-resolution images, which immediately improved output quality. If you are working with limited compute, consider starting with a smaller architecture or fine-tuning an existing pretrained model rather than training from scratch. Full training of a state-of-the-art diffusion model requires significant resources and many people underestimate how much data and how many steps are needed for decent results. Fine-tuning a pretrained checkpoint on your domain-specific data is usually the faster and more practical path unless you have a very specific reason to train from scratch.
The field moves fast and tools change regularly. What worked six months ago may not be the best approach today. Keep an eye on newer architectures and training techniques, but do not chase every new method. The fundamentals of good data, reasonable hyperparameters, and consistent evaluation remain the same regardless of which framework you are using.