What Diffusion Prompting Actually Looks Like in Practice
Most people approach prompt generation for diffusion models the wrong way. They treat it like writing a good search query, which is why they get confused when their outputs look nothing like the prompt. A Diffusion Prompt Guide is essentially a structured way to think about how latent diffusion models interpret text-to-image inputs, but that definition barely scratches the surface of what matters when you're actually getting usable results. The gap between a coherent description and a model-ready prompt is wider than most tutorials admit. I spent about three weeks trying to generate consistent character references across 40+ images using a standard Stable Diffusion pipeline before I actually sat down and mapped out how the model parses prompts. What I found was that most of my issues weren't prompting problems at all, they were sampling parameter conflicts. You can have the perfect prompt and still get garbage if your guidance scale, steps, and sampler are misaligned. That realization shifted everything for how I approach this. The core mechanism is straightforward enough: the model encodes your prompt into a latent space representation, then iteratively denoises from random noise conditioned on that representation. The trick is understanding what the conditioning actually looks like inside. When you write "a cinematic portrait of a woman in a red coat," the model isn't looking at the words as a sentence. It's looking at overlapping token embeddings that fire across different concept dimensions simultaneously. A "cinematic" tag influences lighting and color grading in ways that have nothing to do with the subject matter itself.
Here's the part nobody tells beginners: negative prompts often matter more than positive prompts when you're working with certain model versions. With SDXL and similar architectures, the negative prompt acts as a sort of anti-conditioning filter, pushing the generation away from certain visual patterns. I found that adding "ugly, deformed, noisy, blurry, distorted, grainy" to the negative prompt was less effective than just using the model's built-in negative embedding, which is a pre-trained vector specifically designed to cancel out common failure modes. That's not optional, it's basic.
How to Structure Prompts That Actually Work
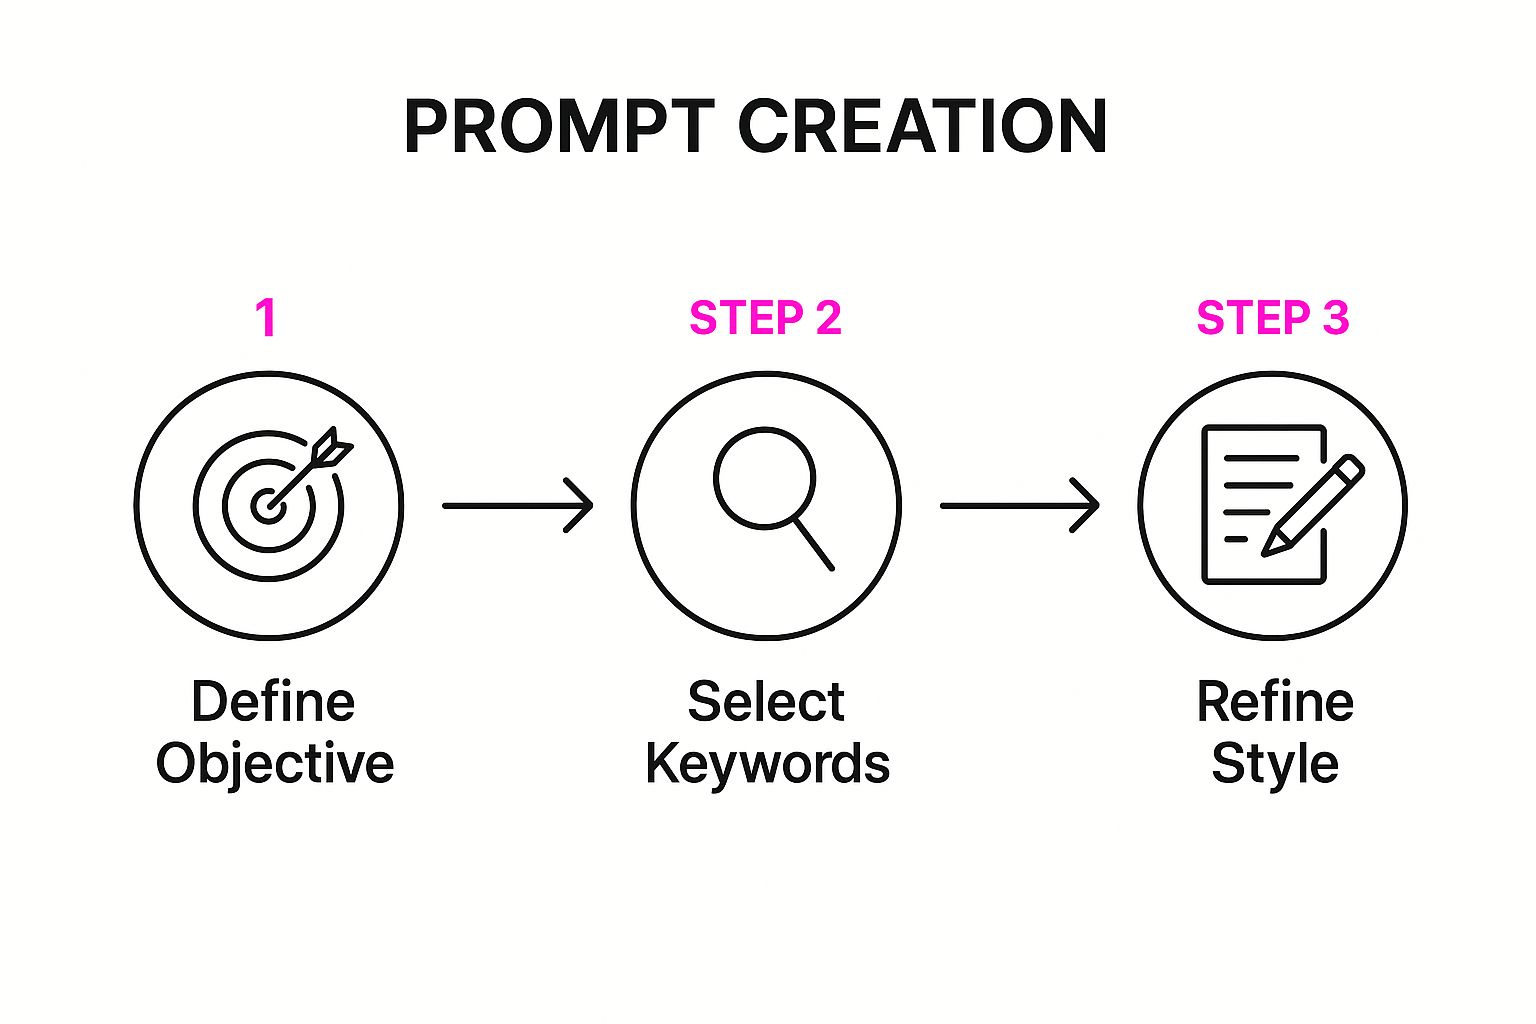
I keep a working document that tracks prompt structures across different model checkpoints, and the pattern that emerges is surprisingly consistent. The order of elements matters because the model gives more weight to tokens that appear earlier and later in the sequence, with a dip in the middle. This is called positional weighting and it's documented in multiple research papers, but most people just write prompts in natural language order and wonder why the results are inconsistent. A practical structure I use starts with subject identification, moves to composition and framing, then lighting and atmosphere, and finishes with quality modifiers. So instead of writing "a beautiful woman in a forest with nice lighting," I write something like "portrait of a woman, medium shot, deep forest background, dappled sunlight, soft rim light, film grain, detailed skin texture, shot on 85mm lens." Each element occupies its own semantic bucket and the model can assign appropriate weights without ambiguity. Weighting syntax is where most people hit a wall. Different interfaces support different approaches. Comma-separated lists with parenthetical multipliers like (word:1.3) work in Automatic1111 and Forge. Bracketed emphasis like [[word]] or [word] functions in ComfyUI workflows. SDXL tends to handle plain text better than previous versions, which means over-weighting becomes a bigger problem. I learned this the hard way when I spent two days troubleshooting why my prompts were producing washed-out, oversaturated images only to realize I had been applying SD1.5 weighting strategies to an SDXL checkpoint. The model was interpreting my aggressive multipliers as conflicting signals and collapsing into generic outputs.
Get the Full Details
Common Pitfalls and What I Do Instead
There's a persistent myth that more detail in a prompt always means better results. This is false. I've seen prompts with 80+ tokens that produce worse images than 15-token prompts. The model has a context window, and once you exceed a certain token count, the additional descriptors don't add information, they add noise. The embeddings start interfering with each other. With SDXL, I typically cap prompts at 50-60 tokens and accept that some ambiguity is necessary. The model fills gaps with its training prior, which is often more coherent than forced specificity. Another issue I encounter constantly is style token contamination. When you include terms like "photorealistic," "digital art," "oil painting," or model-specific tags like "hdr," "vivid," or "cinematic," you're pulling the generation toward whatever those terms correlate with in the training data. The problem is that correlation varies wildly between model versions. A term that produces desirable results on one checkpoint might produce something completely different on another. My workaround is to maintain a style glossary that I update per-checkpoint, documenting which terms actually move the needle and which ones are dead weight. Seed control is another area where beginners consistently underperform. Setting a fixed seed does not guarantee consistent results across different sampler types, step counts, or resolution settings. I had a client who needed identical character faces across 20 images and I wasted four hours trying to make seed locking work across different samplers before I realized the sampler choice was the variable. Switching to the same sampler, same resolution, and same step count made the seeds actually lock. Then I used img2img with a low denoising strength to iterate on composition while preserving the base generation.
Advanced Techniques That Most Guides Skip
Token truncation and embedding manipulation are tools I use regularly but rarely see discussed outside of specialized communities. Some checkpoint fine-tunes introduce new token embeddings that override default meanings. For example, in certain anime-style models, the word "detailed" might trigger a completely different rendering pipeline than it does in the base SDXL model. I found this when a client's prompts suddenly started producing overly stylized results on a checkpoint that was supposed to be photorealistic. The fix was swapping to a different embedding file or disabling the custom embeddings in the UI configuration. Proxy prompting is another technique I rely on. Instead of describing what you want, you describe what the image should resemble in terms of reference materials. "Reference sheet for character design," "medical illustration style," "vintage textbook diagram" — these trigger specific visual schemas that are more reliable than trying to manually specify every visual attribute. The tradeoff is that you get the reference style baked into the output, which may or may not be what you want. I use proxy prompts when I need consistency across a series and abandon them when the style becomes too restrictive. Resolution matters more than you'd think. SDXL was trained primarily at 1024x1024 and related aspect ratios. Generating at non-native resolutions introduces artifacts that no amount of prompt engineering can fix. I've seen people try to push SDXL to 1920x1080 for banner assets and get terrible compositional results, then blame the prompt. The model wasn't trained for that aspect ratio, and the latent space doesn't distribute well at those dimensions. The workaround is either using a model fine-tuned for widescreen formats or doing a full-res upscale pass after generating at the native resolution.
What This Approach Doesn't Solve
I should be clear about where structured prompting falls apart. Hand-generated diffusion prompts still struggle with spatial reasoning, complex multi-subject interactions, and fine-grained control over relative positioning. If you need a cat sitting on a chair to the left of a table with a lamp on top, no amount of prompt structure will reliably produce that. You need ControlNet, region prompting, or inpainting workflows. Prompt engineering alone gets you maybe 70% of the way there on complex scenes, and that's being generous with anything beyond simple portraits or landscapes. The other limitation is checkpoint dependency. A prompt that works perfectly on one model version can fail entirely on another, even within the same family. The training data, tokenization, and latent space geometry all differ. I keep separate prompt libraries for SD1.5, SDXL, and Flux because treating them interchangeably is a waste of time. The Flux model family in particular has a very different token interpretation strategy that makes many traditional prompting techniques irrelevant or actively harmful. If you're just starting out, I'd recommend working exclusively with one checkpoint for at least two weeks before branching out. Learn how it responds to weighting, how it handles negative prompts, what resolution it prefers, and which sampler types it likes. That foundation will serve you better than trying to memorize prompt templates that are optimized for a different model. The Diffusion Prompt Guide concept is useful as a framework for thinking about prompts systematically, but the actual values in any given guide are only as good as the model they were written for.