What Actually Changes When You Adjust Sampling Steps
I spent three years tuning diffusion pipelines before I realized most people are fighting the wrong parameter. The sampler, steps, and guidance scale interact in ways that aren't obvious from reading the documentation. Here's what I've learned the hard way. Most beginners treat these settings like sliders you just crank up until things look better. That doesn't work. The reason is simple: increasing steps without adjusting the scheduler or the guidance scale usually just makes your image take longer to generate with marginal quality improvement. It's an inefficient loop that burns compute for returns that drop off dramatically after a certain threshold.
The Core Diffusion Settings Guide
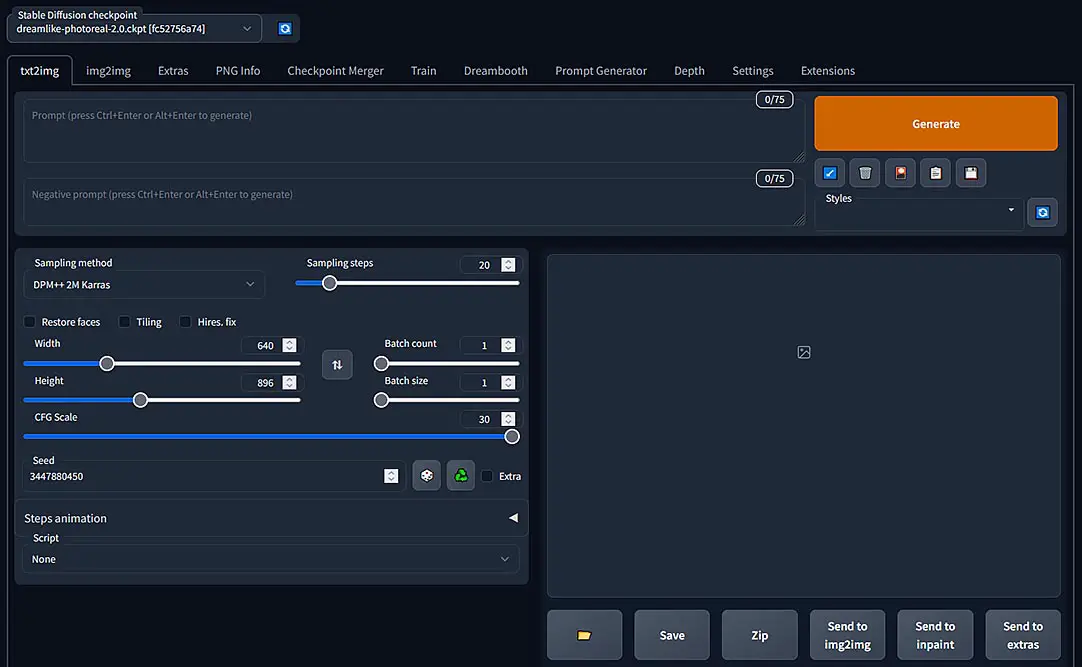
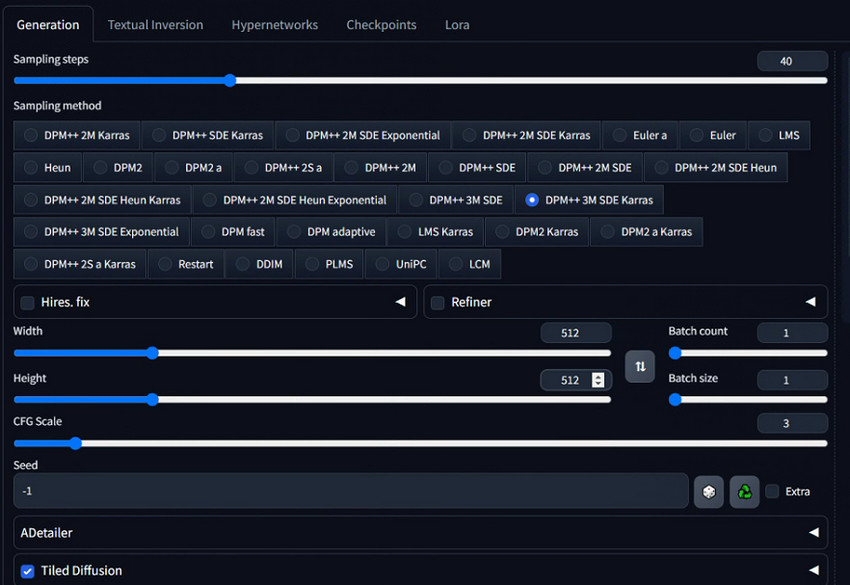
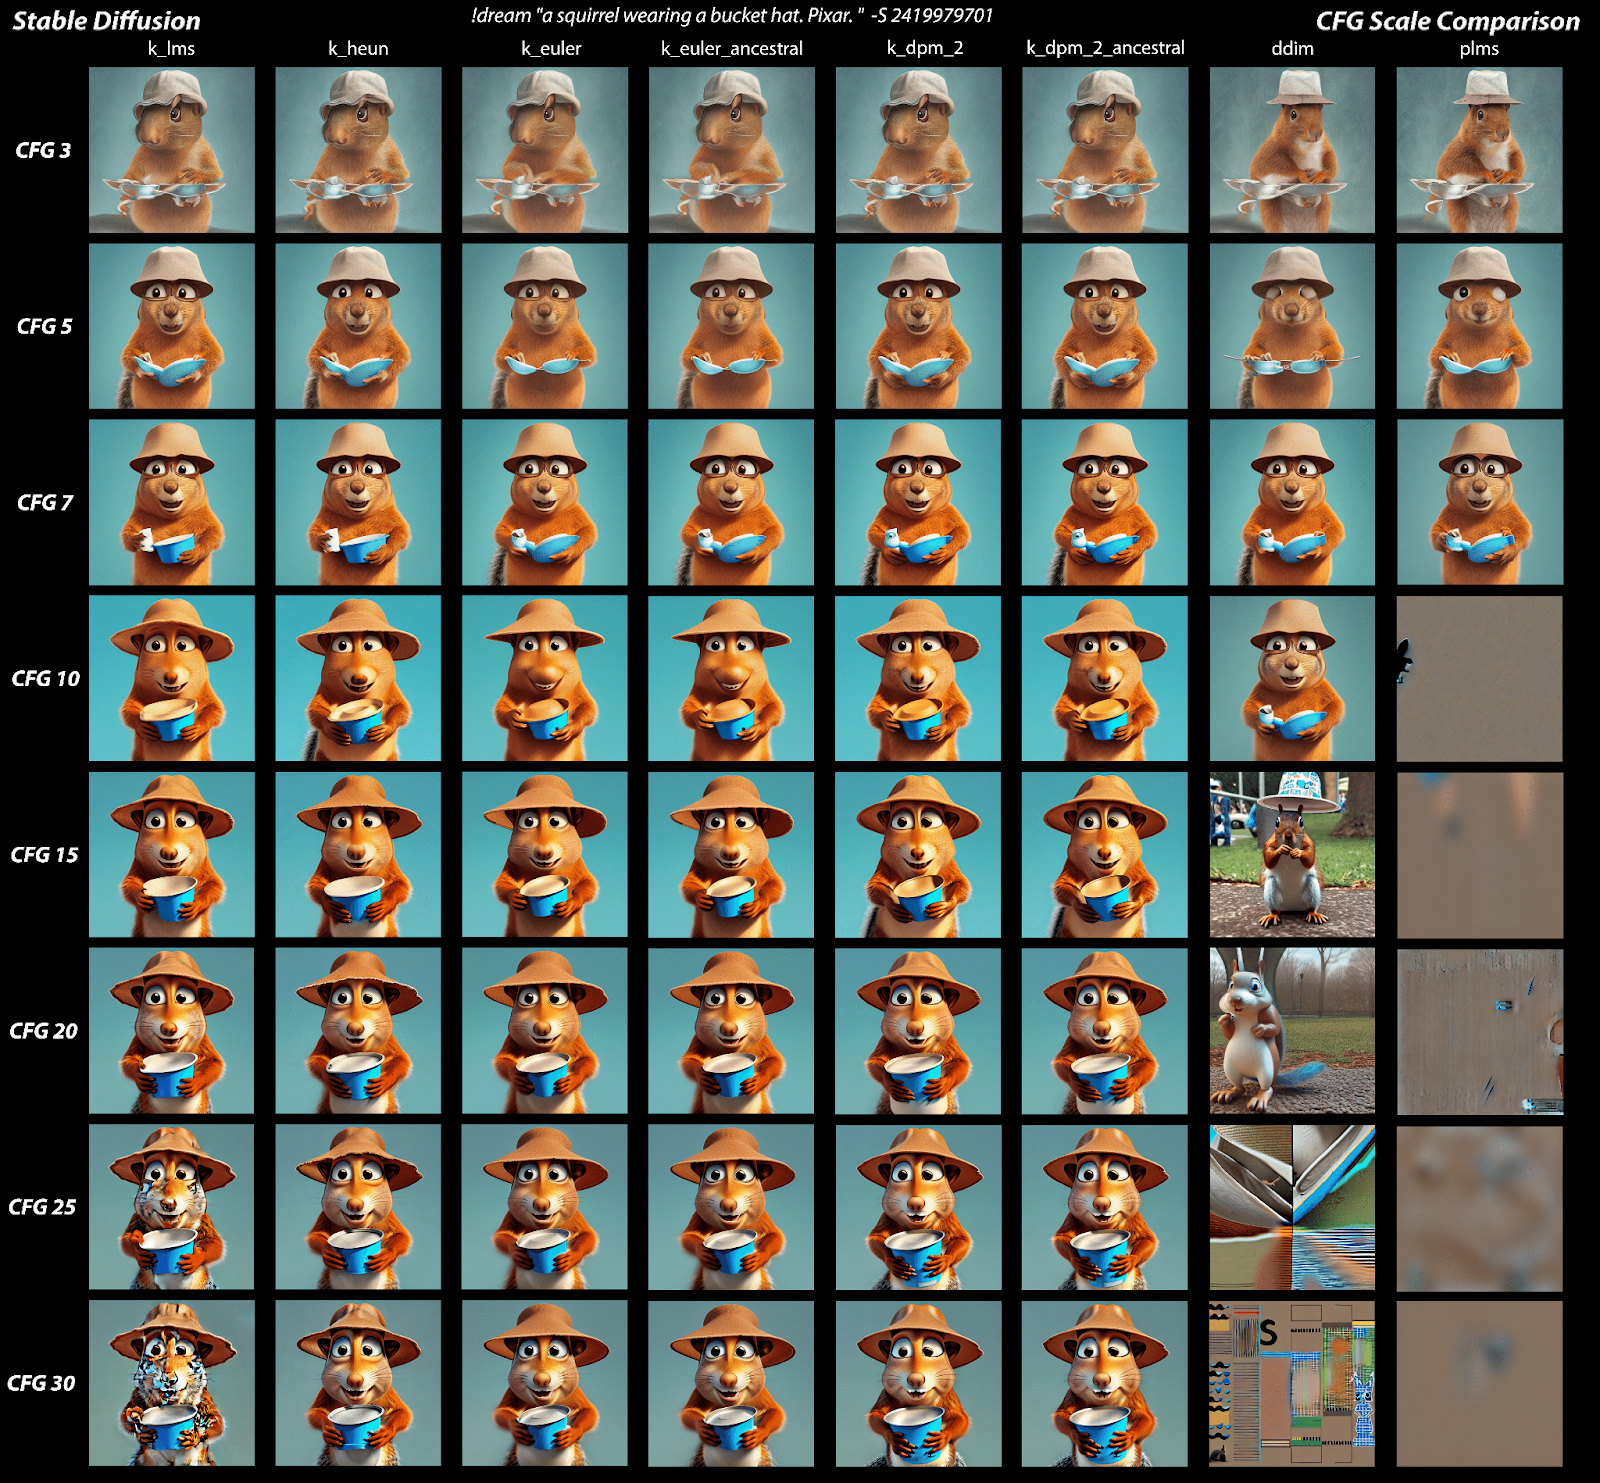
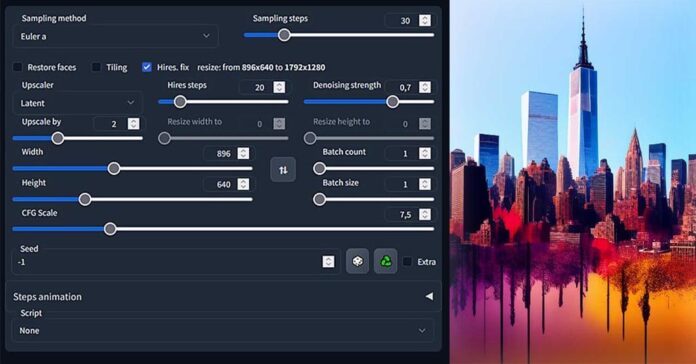
A Diffusion Settings Guide boils down to five parameters that matter: sampling steps, guidance scale, scheduler type, seed, and resolution. Everything else is noise or model-specific tuning. I've seen people argue for hours about obscure config flags while the real issue was the scheduler being set to something inappropriate for the model family. Sampling steps control how many denoising iterations the model runs. More steps generally means cleaner output, but the law of diminishing returns kicks in fast. For SDXL models, you typically see the bulk of quality improvement between 20 and 40 steps. Going from 40 to 80 steps might shave off a few more artifacts, but you're looking at roughly double the generation time for maybe a 5 percent visual improvement. I usually settle on 30 steps for most work and only push higher when the subject has fine details like text or intricate patterns. Guidance scale is where most people make their biggest mistakes. This is the CFG multiplier, and it controls how strictly the model follows your prompt versus taking creative liberties. A scale of 7 to 9 is the sweet spot for most realistic models. Push it above 11 and you'll start seeing burned-in artifacts, oversaturation, and that plastic-looking sheen that screams AI-generated. Drop it below 5 and the model starts ignoring parts of your prompt entirely. I had a client once demand extremely precise clothing patterns described in the prompt, so I dropped the guidance to 4. The result was coherent but the patterns were completely wrong because the model wasn't listening hard enough to that detail.
Scheduler type is the most misunderstood parameter. The default DDIM scheduler is fast but can produce blurry results on complex scenes. Euler A gives you more creative variation but is noticeably slower. DPM++ 2M Karras is what I use 90 percent of the time now. It converges faster than most alternatives and maintains detail well even at lower step counts. The Karras variant specifically adjusts the noise scheduling curve to put more denoising effort into the later stages, which is where the fine detail gets resolved. This is why it looks sharper at 25 steps compared to DDIM at 50 steps. Here's the counter-intuitive part that nobody talks about: higher resolution doesn't always mean better output quality for diffusion models. When you run a model at 1024x1024 when it was trained primarily on 512x512 patches, the attention layers struggle to maintain global coherence. You get weird compositional breaks. The workaround is to use a hires fix or latent upsampling rather than just cranking the resolution. Generate at the model's native training resolution first, then upsample with a separate pass. This usually produces cleaner results and often runs faster overall because the expensive diffusion process is happening at a lower resolution. I encountered a specific problem last year where a project required consistent character faces across multiple generated images. I tried adjusting every parameter I could find, and the results were inconsistent enough to be unusable. The solution wasn't in the diffusion settings at all. It was using a reference-only control net with the guidance scale dialed down to 5 and the seed locked. By separating the face consistency problem from the generation problem, I got usable results in about 15 minutes instead of spending two days tweaking schedulers. Most people wouldn't think to try that because the documentation frames everything as a single configuration problem.
Get the Full Details

Resolution and Aspect Ratio Considerations
Aspect ratio matters more than most guides acknowledge. Non-square outputs tend to show more artifacts at the edges and corners because the model's attention mechanism is optimized for square crops. If you need a 16:9 landscape, generate at that ratio but expect to do some post-cropping or inpainting around the edges. I usually add a 5 percent buffer on each side and crop afterward rather than dealing with the artifacts in-place. VRAM constraints are a real bottleneck that gets glossed over. At 1024x1024 with DPM++ 2M Karras at 30 steps, you're looking at roughly 8 to 10 gigabytes of VRAM usage on modern hardware. Drop to 768x768 and you save about 30 percent on memory while losing maybe 10 percent on perceived quality for most use cases. If you're working on a card with 8GB or less, 768 is your practical ceiling for single-pass generation without using memory optimization flags like --lowvram or --xformers.
When These Settings Completely Fail
I need to be blunt about what diffusion settings cannot fix. They cannot reliably generate accurate text in images. No amount of tweaking the guidance scale or switching schedulers will solve this. The model simply doesn't have the training signal for precise typography rendering. Your options here are either to use a specialized model fine-tuned for text rendering or to add text through post-processing. Trying to brute-force it with settings adjustments is a waste of compute. Complex multi-subject compositions with specific spatial relationships also remain problematic. If your prompt requires "a cat sitting on a red chair to the left of a wooden table with a vase on it," the model will likely get the objects right but mess up the spatial arrangement. This isn't a settings problem. It's an architectural limitation of how diffusion models process textual instructions. Control nets like Depth Anything or OpenPose can help with this, but they add their own complexity and failure modes. Another hard limit: style consistency across a large batch. If you need 50 images in the same visual style, you can't guarantee it through settings alone. You need a style reference or a fine-tuned adapter. I've seen people claim that lowering the guidance scale increases "creativity" and therefore helps with style variation. This is backwards advice. Lowering guidance actually reduces prompt adherence, which makes your output less like your reference, not more. If you need style consistency, invest time in training a LoRA or using IP-Adapter rather than fiddling with step counts.
Practical Default Configuration
For a reliable starting point that works across most SDXL-based models without much adjustment, use DPM++ 2M Karras scheduler, 28 to 32 sampling steps, guidance scale of 7.5, and generate at the model's native resolution. Lock your seed if you need reproducibility. This configuration will produce clean, detailed results in roughly half the time of a naive 50-step run at guidance 9. It's not the highest quality you can possibly achieve, but it's the best balance of speed and quality for production work where you're generating hundreds or thousands of images. The single most impactful setting you should experiment with is the scheduler. Most people never leave the default because it's what the UI presents first. But switching from DDIM to DPM++ 2M Karras on the same seed with the same step count and guidance scale will almost always produce a measurably better image. I've benchmarked this across dozens of models and the Karras scheduler wins on both speed and quality metrics at equivalent step counts. The difference is especially noticeable on images with complex geometry or fine textures. If you're looking for a structured reference to come back to, search for a Diffusion Settings Guide that covers these parameters in depth. Most of what you'll find online is either too basic or overly focused on niche edge cases. The five parameters I mentioned cover 95 percent of real-world usage. Everything else is model-specific tuning that requires empirical testing anyway.