Understanding How Diffusion Style Guide Actually Works
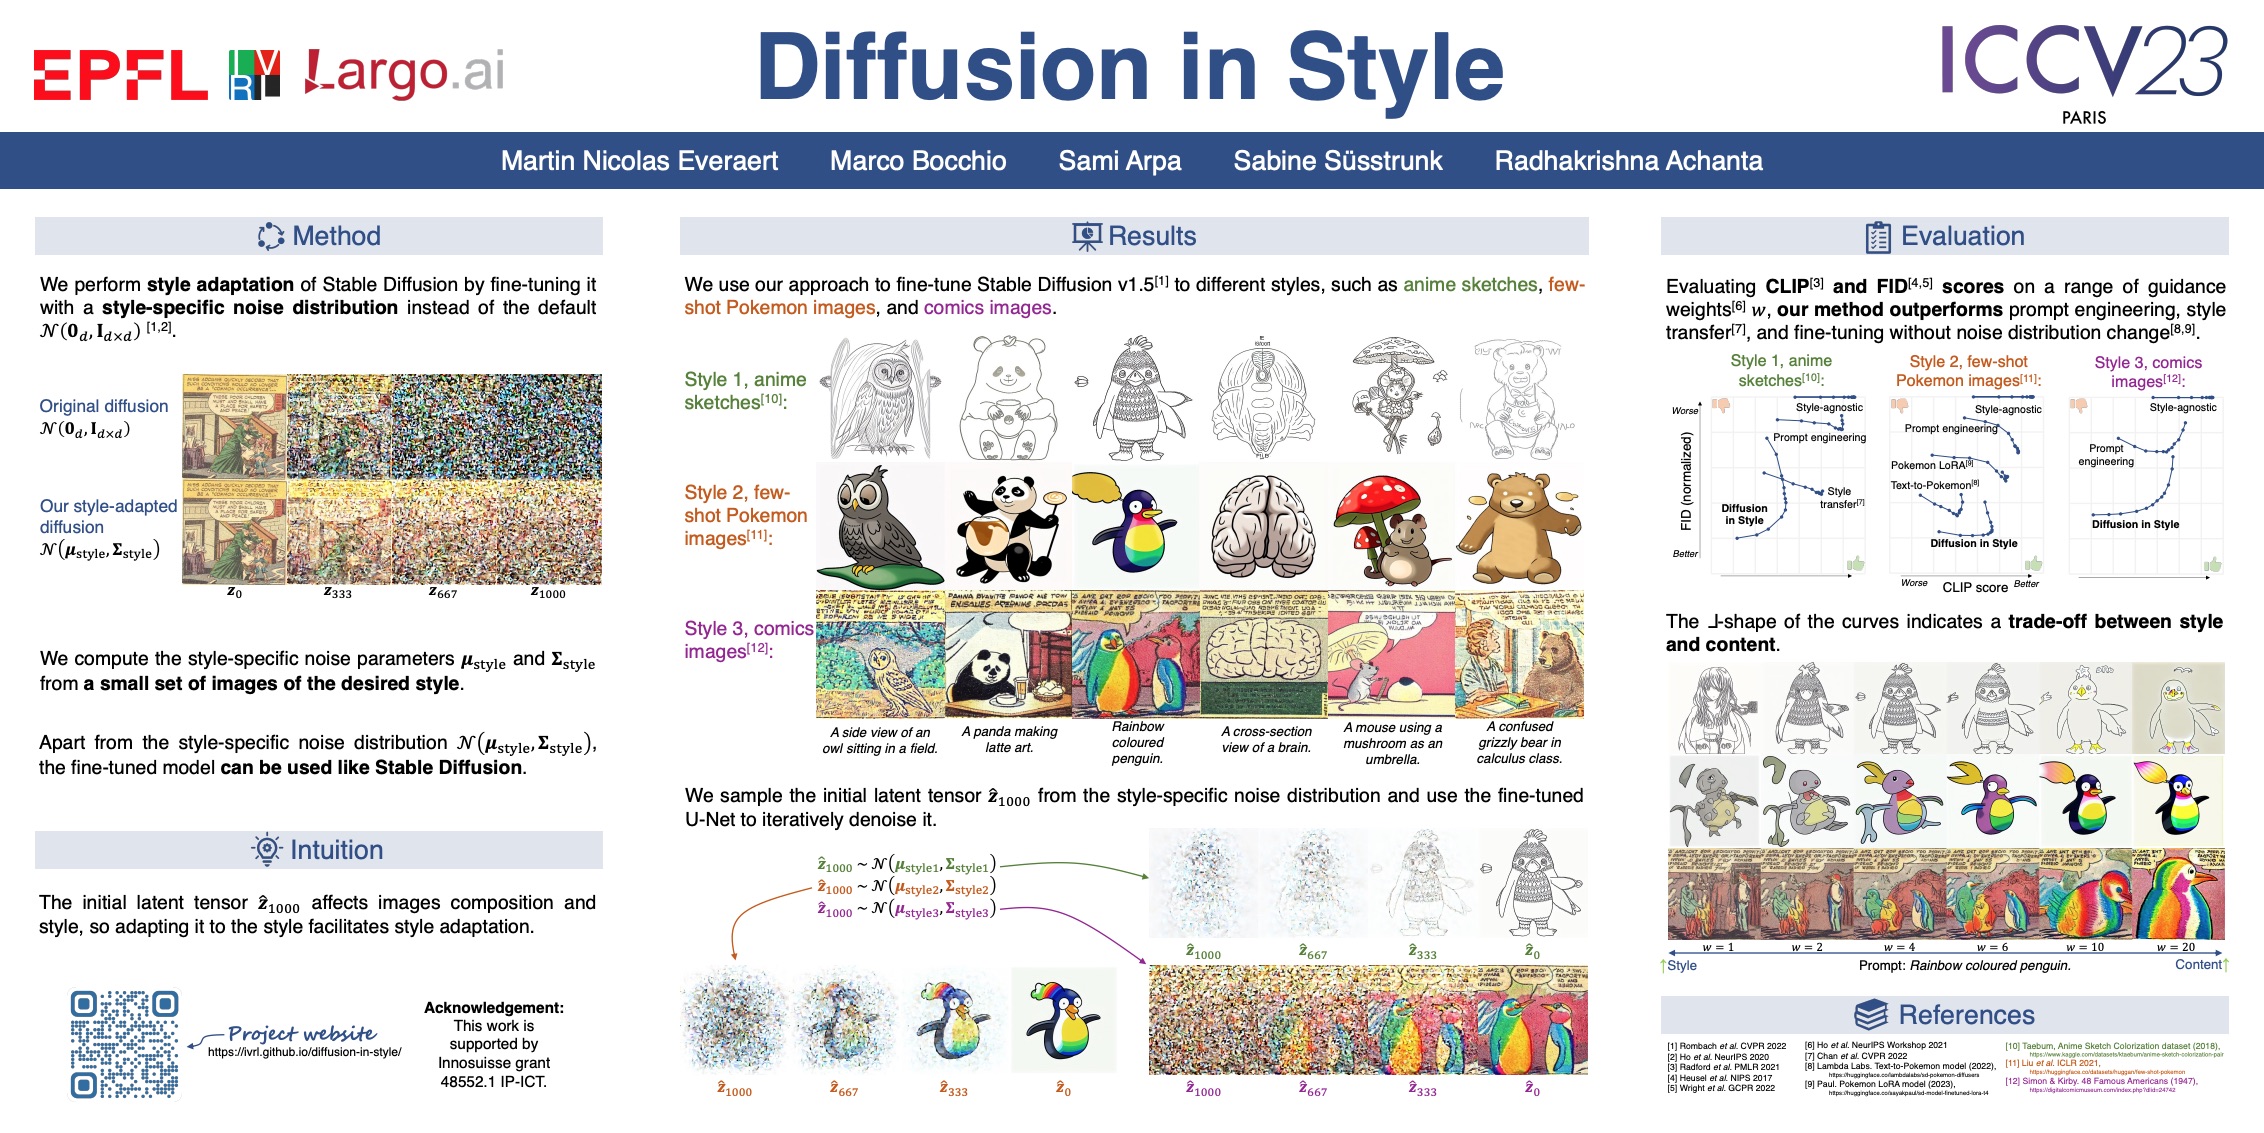
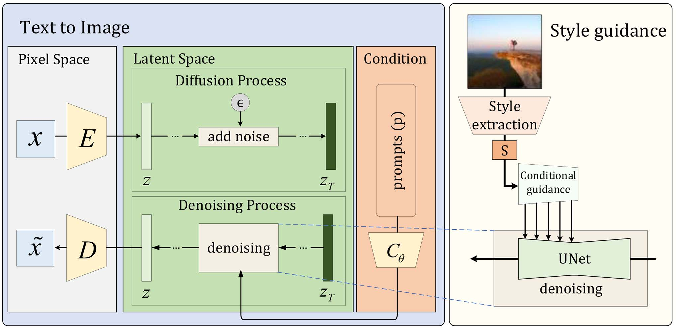
I spent way too long trying to replicate consistent styles across batches in Stable Diffusion before I figured out that the problem wasn't the model—it was the way people approach style conditioning. A Diffusion Style Guide isn't some magical cheat sheet. It's a structured reference that maps desired visual outcomes to specific prompt combinations, sampling parameters, and model weights. That's it. The more you treat it like science rather than art, the better results you get. A Diffusion Style Guide is a documented system for translating artistic styles into the variables that diffusion models actually respond to. We're talking embeddings, CLIP skip values, sampler selection, CFG scale ranges, and the specific keyword sequencing that influences latent space behavior. Most people just paste "masterpiece, best quality, oil painting style" into the prompt box and wonder why they keep getting generic results. The style guide exists to eliminate that guesswork. I built my first proper style reference for a client who needed 200 consistent character renders in a specific watercolor aesthetic. We were generating in batches of 8, and without a structured approach, every single output looked slightly different. Same seed, same base prompt, completely different color palettes and brush stroke intensity. What I ended up doing was freezing the first-stage noise and only varying the conditioning weights between runs. That's not in most beginner tutorials.
The Practical Setup
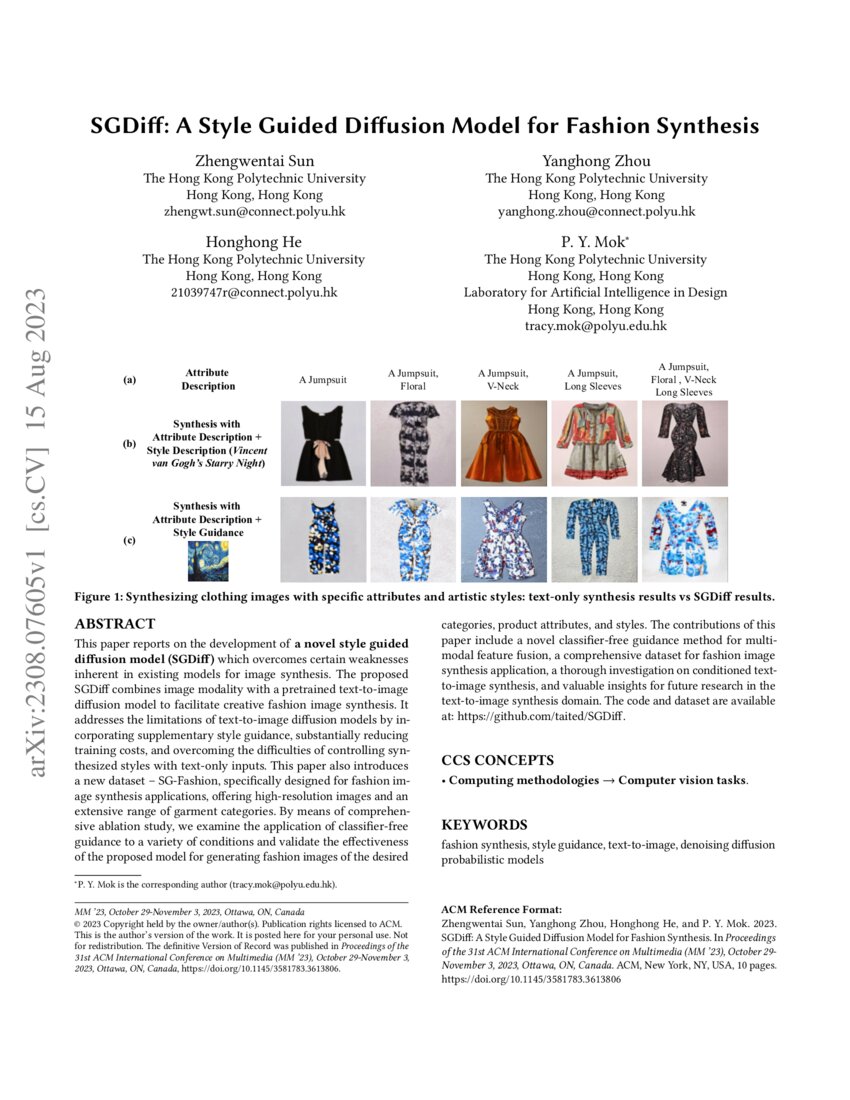
Start by identifying the core style you want. Not the generic version—the actual technical breakdown. If you're going for van Gogh, don't just write "van Gogh style." Break it down: impasto texture, chromatic vibration in the blues, directional brushwork pattern, limited underpainting warmth. Those are the variables the model responds to, not the artist name alone. From there, build your style card. Each entry should contain: the base positive prompt, the negative prompt, the sampler (DPM++ 2M Karras works as a default), CFG scale, steps, resolution, and any LoRA or embedding references with their weight values. Keep it in a spreadsheet or a simple text file. I used a Google Sheet for months and it worked fine until I hit about 60 entries, then I switched to a local JSON-based system that let me grep-query my own configurations. The sampler choice matters more than most people admit. DPM++ SDE is slower but produces more varied texture, which helps when you're trying to capture hand-drawn media. Euler a gives you speed but sacrifices fine detail consistency. For stylized work where coherence across a batch matters, I usually default to DPM++ 2M Karras at 25-30 steps with a CFG between 5 and 7.
Advanced Nuances Beginners Miss
Here's something that took me three months to figure out: higher CFG values don't always make the style stronger. After a certain threshold—which varies by model—the image starts breaking. The colors oversaturate, details pixelate, and the style collapses into artifacts that look nothing like what you wanted. I learned this the hard way when I set CFG to 15 on a custom anime-style model and got output that looked like a corrupted JPEG. Dropped it to 6 and everything snapped into place. Another counter-intuitive thing: CLIP skip. Most people leave it at the default of 1. But for many fine-tuned models, especially anime and illustration LoRAs, skipping the last layer of CLIP encoding actually improves style adherence. Setting CLIP skip to 2 or even 3 can remove unwanted realism bias from the base model's latent space. Test it per model. Don't assume one value works everywhere. Resolution has a non-obvious relationship with style perception. A watercolor prompt at 512x512 looks dramatically different from the same prompt at 768x1024. Higher resolutions give the model more latent tokens to distribute brush-like textures across, which often makes the style appear more refined but also more diluted. I found that mid-range resolutions around 640x896 were the sweet spot for maintaining style intensity while preserving detail. YMMV depending on your model.
Get the Full Details
A Real Problem I Ran Into
There was one instance where my style guide was working perfectly—consistent outputs, matching color palette, correct texture rendering—and then the entire batch suddenly shifted toward a cooler color temperature on the same machine, same seed, same everything. I spent two days troubleshooting. Turns out the AMD GPU driver on my setup had a known float16 precision bug that manifested randomly under sustained load. It didn't crash. It just introduced subtle noise into the latent space that accumulated across steps. Switched to float32 for inference and the problem went away. Loss of about 30% generation speed, but style consistency came back. If you're running consistent styles and getting occasional drift without any parameter changes, check your hardware and precision settings before you start rewriting prompts.
Download and Distribution
There are community-hosted Diffusion Style Guide repositories on GitHub that aggregate tested configurations across popular models. SDXL-specific guides tend to be more current than SD 1.5 ones since the architecture supports more nuanced conditioning. My own style guide is maintained as a private reference, but I've shared the template structure online. You can find working examples and starter sheets by searching the usual model communities—Hugging Face spaces, Civitai, and the r/StableDiffusion subreddit all have threads with downloadable configurations. The template is straightforward: columns for style name, model version, positive prompt, negative prompt, sampler, steps, CFG, CLIP skip, resolution, LoRA references with weights, and notes. That's all you need to start. Don't overcomplicate it.
Limitations and When to Walk Away
A Diffusion Style Guide won't help you if your base model has never seen the style you're targeting. No amount of prompt engineering will make a photorealistic checkpoint produce convincing ink wash paintings. You need a model that was trained on or fine-tuned with that style. The guide optimizes what's already there; it doesn't create capability from nothing. It also doesn't solve semantic content problems. If you need a specific composition—a character standing on the left, looking right, with a specific object in frame—the style guide won't fix your prompting. You still need solid subject description skills. The guide handles style consistency, not scene structure. For highly variable styles that require dramatic shifts between runs, consider using control nets instead. Depth maps, line art extracts, and Canny edges give you structural control that pure prompt-based conditioning can't match. The style guide is complementary to control nets, not a replacement.
If you're generating at scale for production work and need exact reproducibility across team members with different hardware, the float precision issue I mentioned earlier is real. Document your environment, not just your prompts. Two people running the same style card on different GPUs can produce noticeably different results if one is using mixed precision and the other isn't.