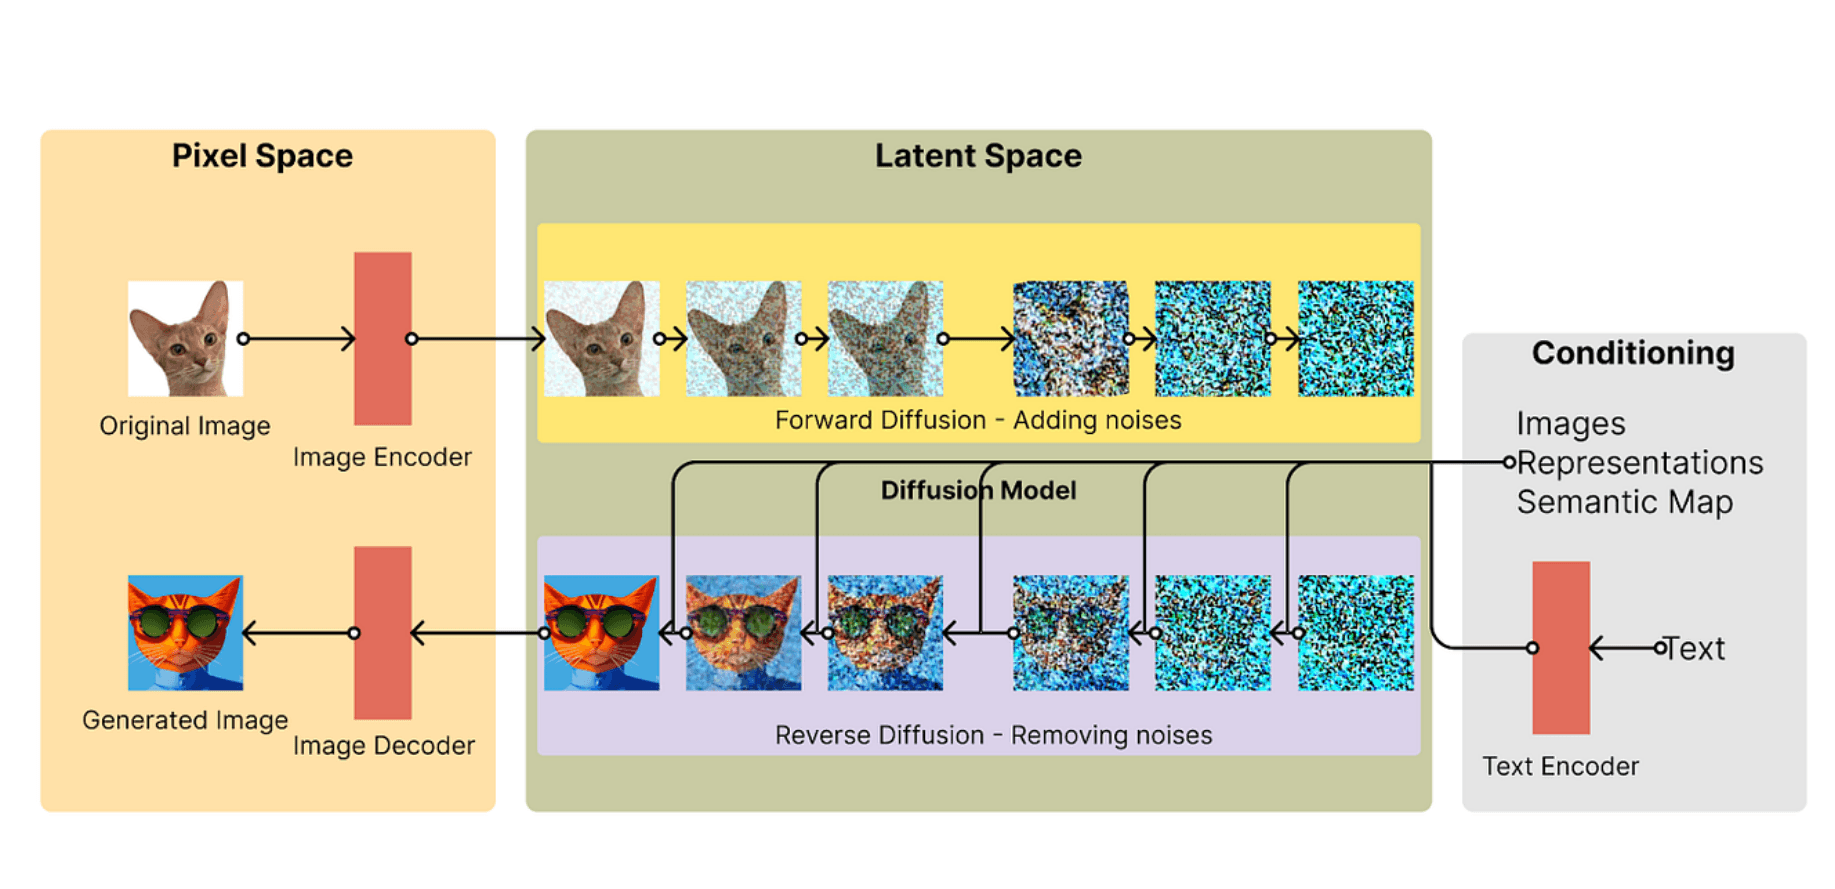
How diffusion models actually get trained
Most people talk about diffusion training like it's just pushing a button, but the reality is a lot more fiddly. I've been running these training runs for a while now, and I can tell you that the difference between a decent result and something actually usable usually comes down to understanding what each parameter does rather than following a guide verbatim. When I first started training diffusion models, I assumed the number of training steps was the most important thing. It's not. It matters, sure, but getting the dataset together correctly and picking the right base model will save you far more headaches than cranking up the step count. I learned that after burning through three different checkpoints that all looked washed out or had weird artifacts because I hadn't thought through my preprocessing.
The core Diffusion Training Steps
The basic flow goes like this, and it's not as simple as it sounds: Step one is data collection and preparation. You need 15 to 30 images for a LoRA, or 50 to 100 if you're training a full fine-tune. The images should be high quality, properly cropped, and captioned accurately. I used to skip detailed captions and just run the training, then wonder why the model was learning the wrong associations. One time I trained on a dataset where half the images had \"sunset\" in the caption but the actual subject was a portrait. The model literally couldn't figure out what it was supposed to learn. Took me a weekend to realize what I'd done wrong. Step two is choosing your base model. For SDXL, you have SDXL 1.0, Juggernaut, DreamShaper, and others. Each has different strengths. For character work, some bases handle anatomy better. For landscapes, others are sharper. I typically go with a checkpoint that's already close to what I want rather than starting from scratch. Training from a solid base means fewer steps needed and better results overall.
Step three is setting your training parameters. This is where most people go wrong. Learning rate, batch size, epoch count, resolution, optimizer choice -- these all interact with each other. A learning rate that works for one setup will completely blow up another. I usually start with a learning rate around 1e-4 to 5e-5 for LoRAs and something closer to 1e-5 for full fine-tunes. The exact value depends on your dataset size and what kind of changes you're trying to make. Step four is the actual training run. This is where you wait. A typical LoRA on an RTX 4090 with 20 images might take 30 to 60 minutes. A full fine-tune on the same hardware could run for several hours. You monitor the loss curve during training. If it's dropping too slowly, your learning rate might be too low. If it's oscillating wildly or going negative, it's too high. If it plateaus early, you might need more epochs or a different resolution. Step five is sampling and evaluation. Don't just look at the final checkpoint. Sample throughout training. I keep a set of test prompts and generate samples every 100 to 500 steps depending on how fast the training is running. This lets you catch problems early. I once trained for six hours only to discover the model was overfitting badly and had forgotten how to render hands properly. If I'd checked at step 2000, I would've stopped at step 3000 and saved four hours.
Get the Full Details

Step six is saving and deploying. Once you're happy with the results, save your model. For LoRAs, this is usually a .safetensors file. For full fine-tunes, same format. Load it into your inference pipeline and test it on prompts you didn't use during training. This tells you whether the model generalized or just memorized your dataset.
Things that aren't obvious
Here's something I wish someone had told me: resolution matters way more than people admit. Training at 1024x1024 when your images are mostly 512x768 portraits will hurt your results. Match your training resolution to your actual image aspect ratios. I trained a model at 1024 square on portrait images and the output had strange distortions around the edges. Switched to a variable resolution approach where the aspect ratio is preserved and the total pixel count stays roughly the same, and the quality jumped significantly. Another counter-intuitive thing: more data isn't always better. I had a case where I threw 80 images at a LoRA training run and the result was worse than when I used 20. The extra images had inconsistent lighting and composition, which confused the model. Quality of data matters more than quantity. I've found that 15 to 20 well-chosen, consistently styled images often beats 50 messy ones. There's also the question of captioning. Automatic captioning tools can work, but they often miss important details. I've seen models trained with captions that described the background but not the subject. The model learns from what you tell it. If your captions are vague, your model will be too. I spend a lot of time writing custom captions rather than relying on BLIP or WD14 taggers alone. It takes longer upfront but saves hours of retraining later.
Common problems and what to do about them
Overfitting is the most common issue. Your model starts producing great outputs that look exactly like your training images but fails on anything different. The fix is usually to reduce training steps, increase regularization, or add more diverse data. I've found that adding a few generic images to the dataset -- ones that don't have your specific subject -- helps the model remember general concepts while still learning the target. It's called regularization, and it's included in most training frameworks by default, but you need to make sure it's actually enabled. Another problem is that the model forgets basic capabilities. You train a character LoRA and suddenly it can't render hands properly or the anatomy breaks. This happens because the training data didn't include enough variety in poses or angles. I learned this the hard way after training a character model that looked perfect in three poses and fell apart in everything else. The workaround was adding more diverse reference images and using a lower rank for the LoRA, which constrains how much the model can deviate from the base. Sometimes the model just won't converge. You crank up the steps, change the learning rate, try different optimizers, and nothing helps. In those cases, the problem is usually in the data. Check your captions for consistency. Check your images for quality issues. Sometimes the dataset is just too small or too noisy, and the honest answer is to start over with better data rather than keep tweaking parameters.

When this approach doesn't work
Diffusion training steps, as I've described them, work well for learning a specific style, character, or concept. They don't work well for things that require fundamental architectural changes. If you're trying to train a model to generate photorealistic images from a stylized base, you're going to have a bad time. The gap between the source and target domains is too wide for fine-tuning to bridge effectively. In those cases, you're better off starting with a base model that's already closer to what you want or looking into text-to-image model architectures designed for that kind of transfer. Training from scratch rather than fine-tuning is another scenario where this whole process falls apart. Full training from random initialization requires orders of magnitude more data and compute. Unless you have a dataset of hundreds of thousands of images and GPU clusters to match, stick with fine-tuning. The results will be better and you'll actually finish the run. One more limitation: diffusion models struggle with text rendering. No amount of training steps will make your model reliably produce legible text in images. This is a fundamental limitation of the architecture, not a training parameter issue. If you need text in your outputs, you're better off using a separate tool for that rather than expecting the diffusion model to handle it.