Understanding The Three Main Types Of Natural Selection
You probably learned about directional, disruptive, and stabilizing selection in an intro bio class and then forgot most of it. That's normal. These concepts sound simple on paper but get messy fast when you actually look at real data. I spent years working with phenotypic distribution curves in field populations, and even now I catch myself second-guessing which model fits when the data is noisy. Let me walk through what these actually mean in practice, where people mess up, and how to tell them apart when you're looking at raw numbers instead of textbook diagrams.
Directional Disruptive And Stabilizing Selection
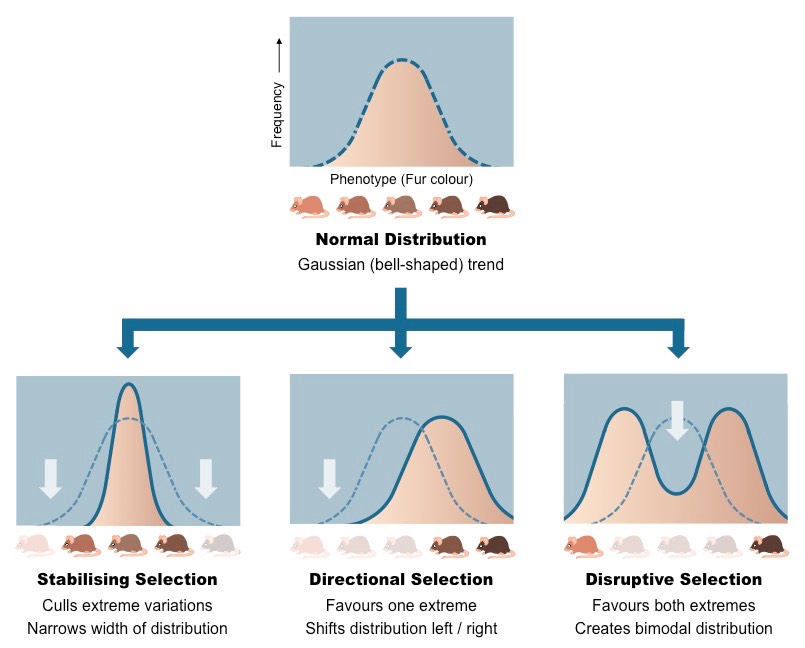
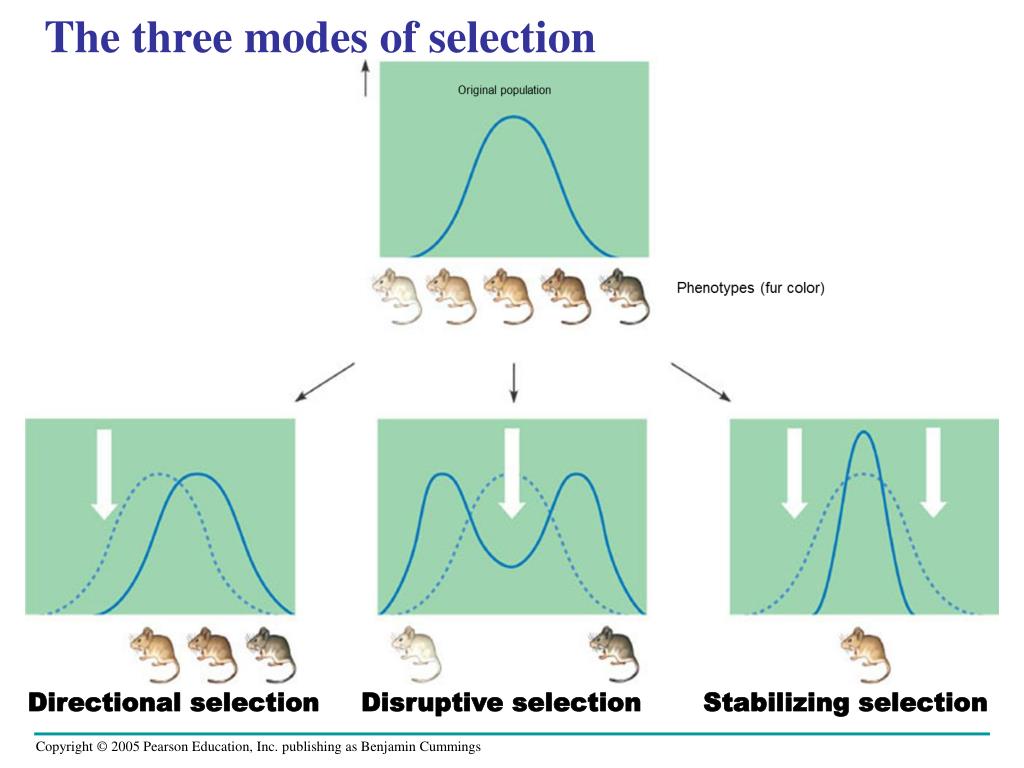
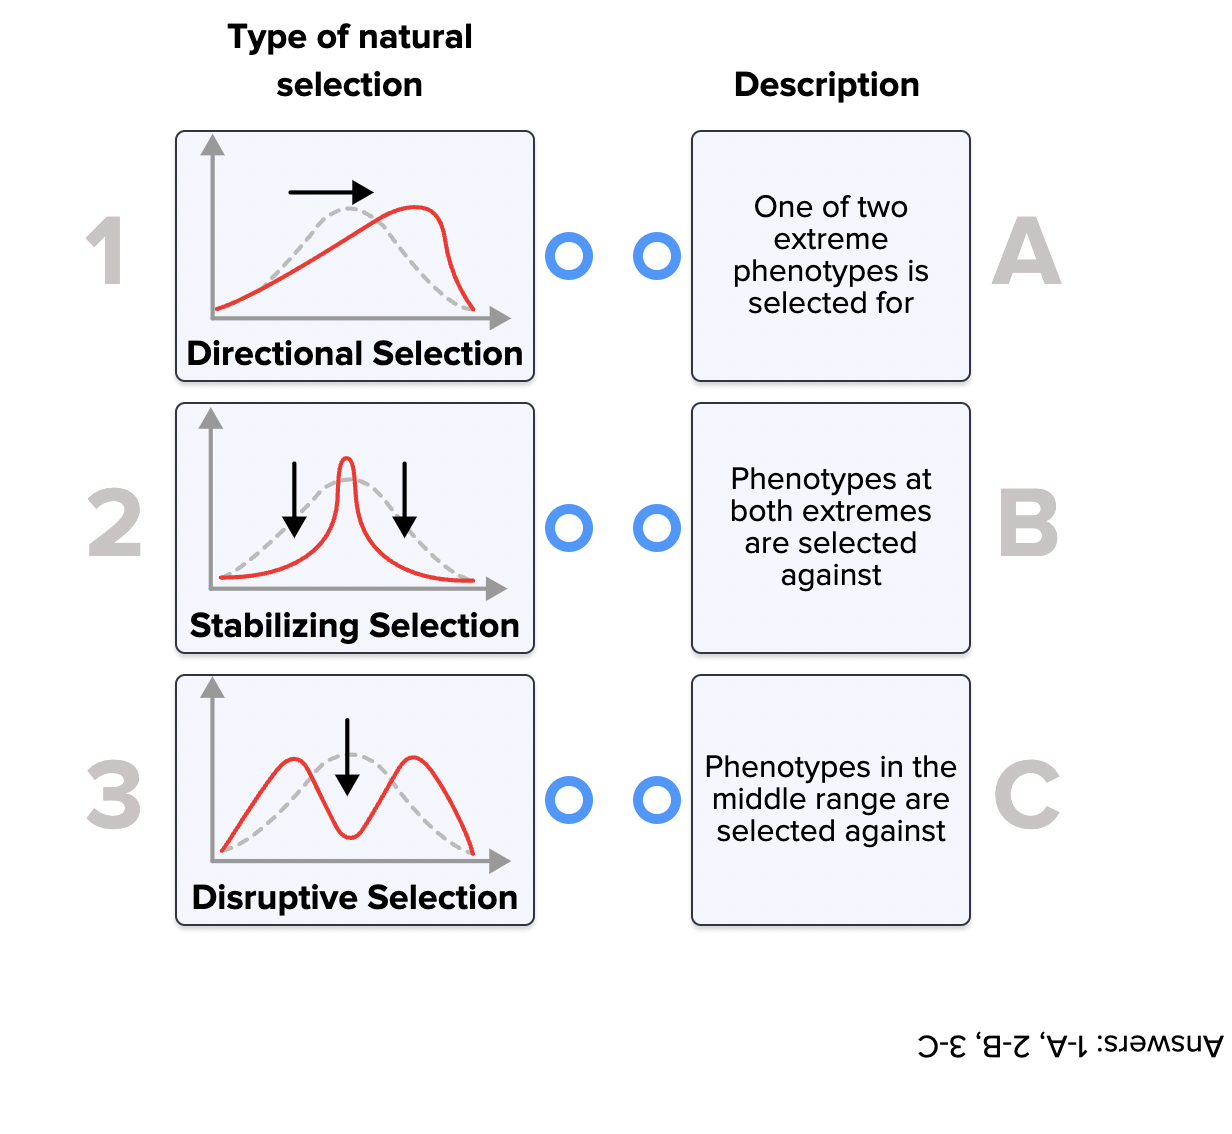
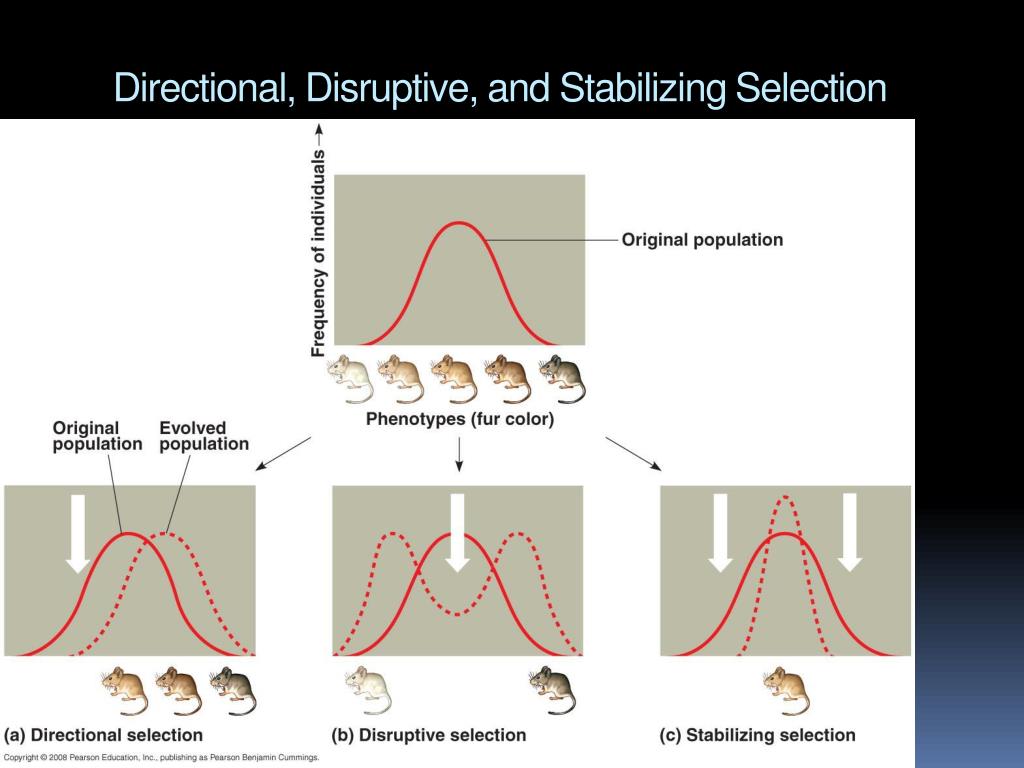
First, the definitions, but stripped of the cartoonish bell curve illustrations that make this seem easier than it is. Directional selection shifts the mean of a population toward one extreme of a trait distribution. It happens when environmental pressure consistently favors individuals at one end of the phenotypic spectrum. Classic example: bacteria evolving antibiotic resistance. The susceptible population gets wiped out, and the resistant fringe becomes the new normal. The distribution curve moves left or right. Stabilizing selection does the opposite of what most people assume. It doesn't maintain the status quo passively. It actively culls extremes on both sides and narrows the variance around the mean. Human birth weight is the standard example because it's empirically well-documented. Babies at the low end and high end of the weight distribution have higher mortality. The curve gets sharper and tinier over generations, not flatter.
Disruptive selection splits the population into two distinct phenotypic peaks by selecting against the intermediate form. This is the one that actually matters for speciation. When intermediates are worse off than either extreme, you can get a bimodal distribution emerging from what was once a normal curve. African seedcracker birds with small versus large beaks depending on seed hardness is one of the cleaner documented cases. Here's the part textbooks don't emphasize enough: these three modes aren't always mutually exclusive in a single population at a single time. Different traits within the same organism can be under different selection pressures simultaneously. A bird might be under stabilizing selection for wing length but disruptive selection for bill size. Layering them on top of each other makes the data look like garbage if you don't know what you're looking for. I ran into this exact problem about five years ago working with a population of alpine plants. The leaf size distribution looked roughly normal at first glance, which immediately suggested stabilizing selection. But when I separated the data by elevation band, the high-altitude group showed clear directional selection toward smaller leaves while the low-elevation group was under disruptive selection with a trough in the middle. Pooled together, the signal canceled itself out and I almost filed it as null results. The workaround was stratifying by microhabitat before running any selection gradient analysis. Always stratify. Your aggregate data is lying to you.
Get the Full Details
The practical method for detecting which mode is operating comes from quantitative genetics, specifically the Lande and Arnold framework. You measure the trait of interest, you measure fitness (usually reproductive success or survival), and you calculate selection gradients. Directional selection shows up as a significant linear gradient. Stabilizing selection appears as a significant quadratic (curved) gradient pointing downward. Disruptive selection is a quadratic gradient pointing upward. Correlated traits complicate this because selection on one trait can drag another along through genetic linkage. There's a common pitfall here that costs people weeks of work. Sample size. Detecting stabilizing or disruptive selection requires significantly more individuals than detecting directional selection because you're looking for curvature in the relationship, not just a slope. I've seen papers claim stabilizing selection from datasets with fewer than 50 subjects. That's not enough. You need power to detect a quadratic term, and that means hundreds of measured individuals minimum if the selection differential is anything but enormous. Another counter-intuitive thing: stabilizing selection doesn't necessarily reduce genetic variation forever. Mutational input continuously reintroduces variance, and if the fitness landscape changes even slightly, that standing variation becomes useful. The population looks static phenotypically while quietly accumulating genetic diversity under the surface. This is why some species persist through environmental shifts that should theoretically wipe them out.
Disruptive selection is arguably the hardest mode to confirm in wild populations because it requires showing that intermediates have genuinely lower fitness, not just that extremes happen to survive. Confounding factors like assortative mating, habitat heterogeneity, or simply different growth rates can mimic the pattern without actual disruptive selection being the cause. The gold standard is a common garden experiment where you raise individuals from different phenotypic classes in identical conditions and measure their fitness directly. For directional selection, the cleanest evidence comes from long-term datasets. The peppered moth is the famous case, but it's also well documented in guppies, Darwin's finches during drought cycles, and various parasite-host arms races. The signal is usually unmistakable because the mean shifts measurably across just a few generations. That said, directional selection can reverse. If the environmental pressure flips, you get the mean marching back the other way. What looks like a directional trend over ten years might just be a pendulum swing. If you're working with this stuff yourself and your selection gradient analysis isn't coming out significant, check these things before you conclude no selection is happening: make sure you've measured the right trait, verify your fitness proxy actually correlates with evolutionary fitness rather than just current abundance, and confirm you have enough samples. Also consider whether frequency-dependent selection might be at play, which can produce oscillating patterns that look like noise but are actually a different selective regime entirely.
There's no software shortcut that replaces careful experimental design here. The tools exist for calculating selection differentials and gradients, but garbage inputs still produce garbage outputs. I've seen people feed raw observational data into selection analysis pipelines without accounting for environmental covariates and then wonder why their results looked biologically absurd. Always control for confounding variables. Size often correlates with everything, and if you don't partial it out, you'll attribute selection to one trait that's actually just tracking body size.