Building Machine Learning Models Without Expensive Tools
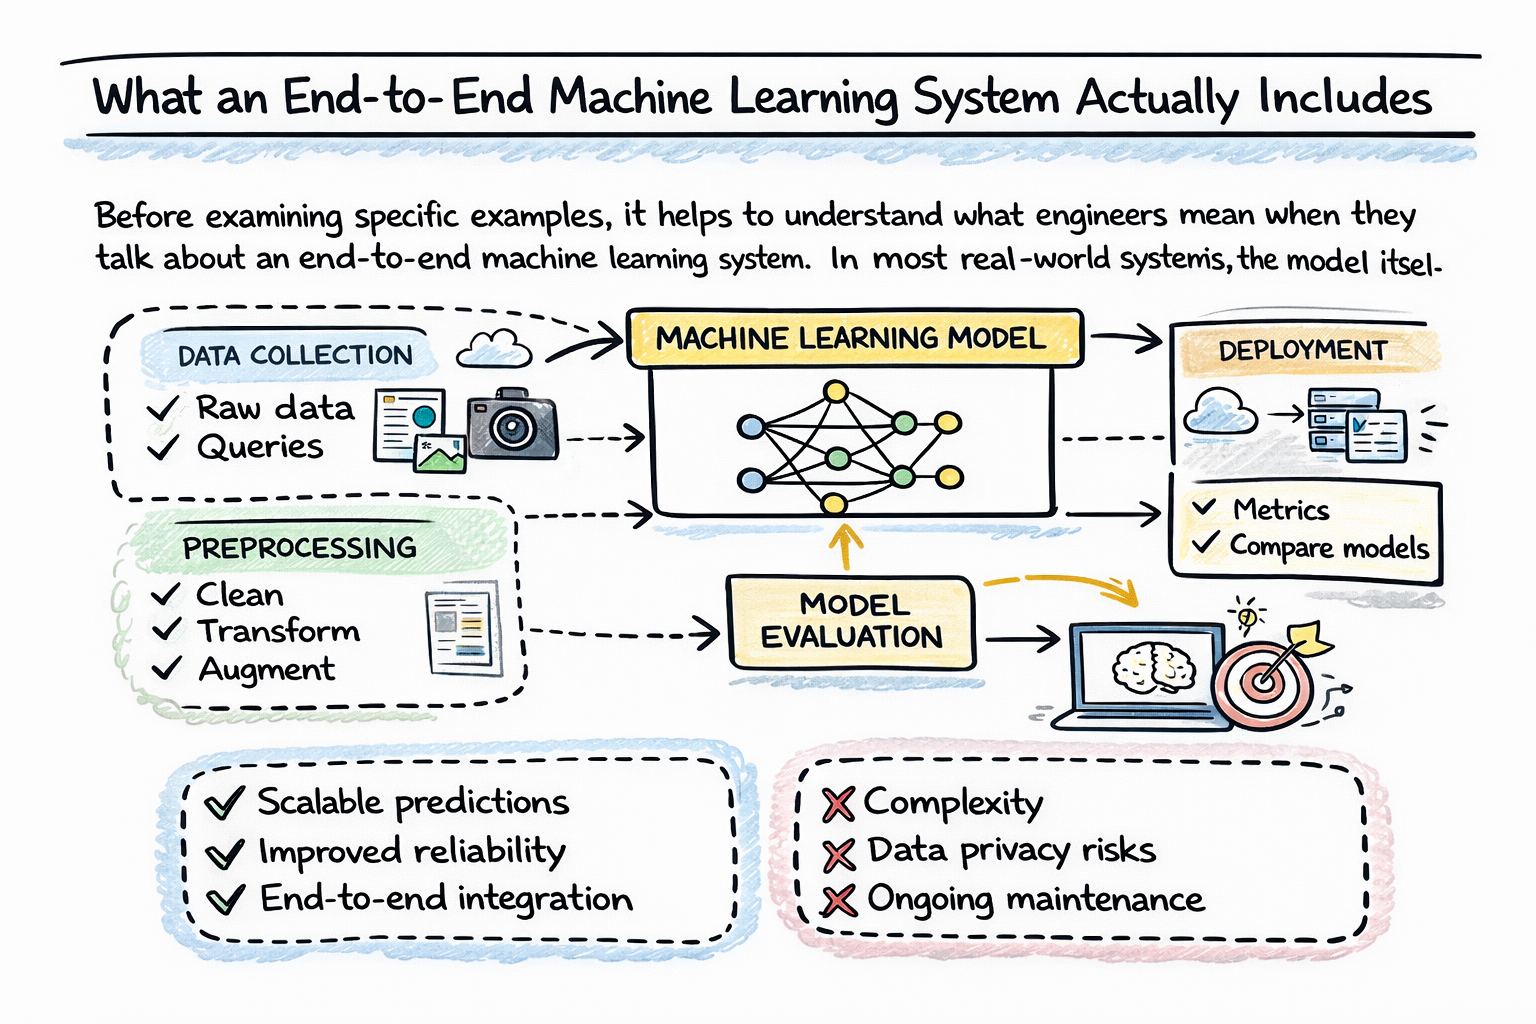
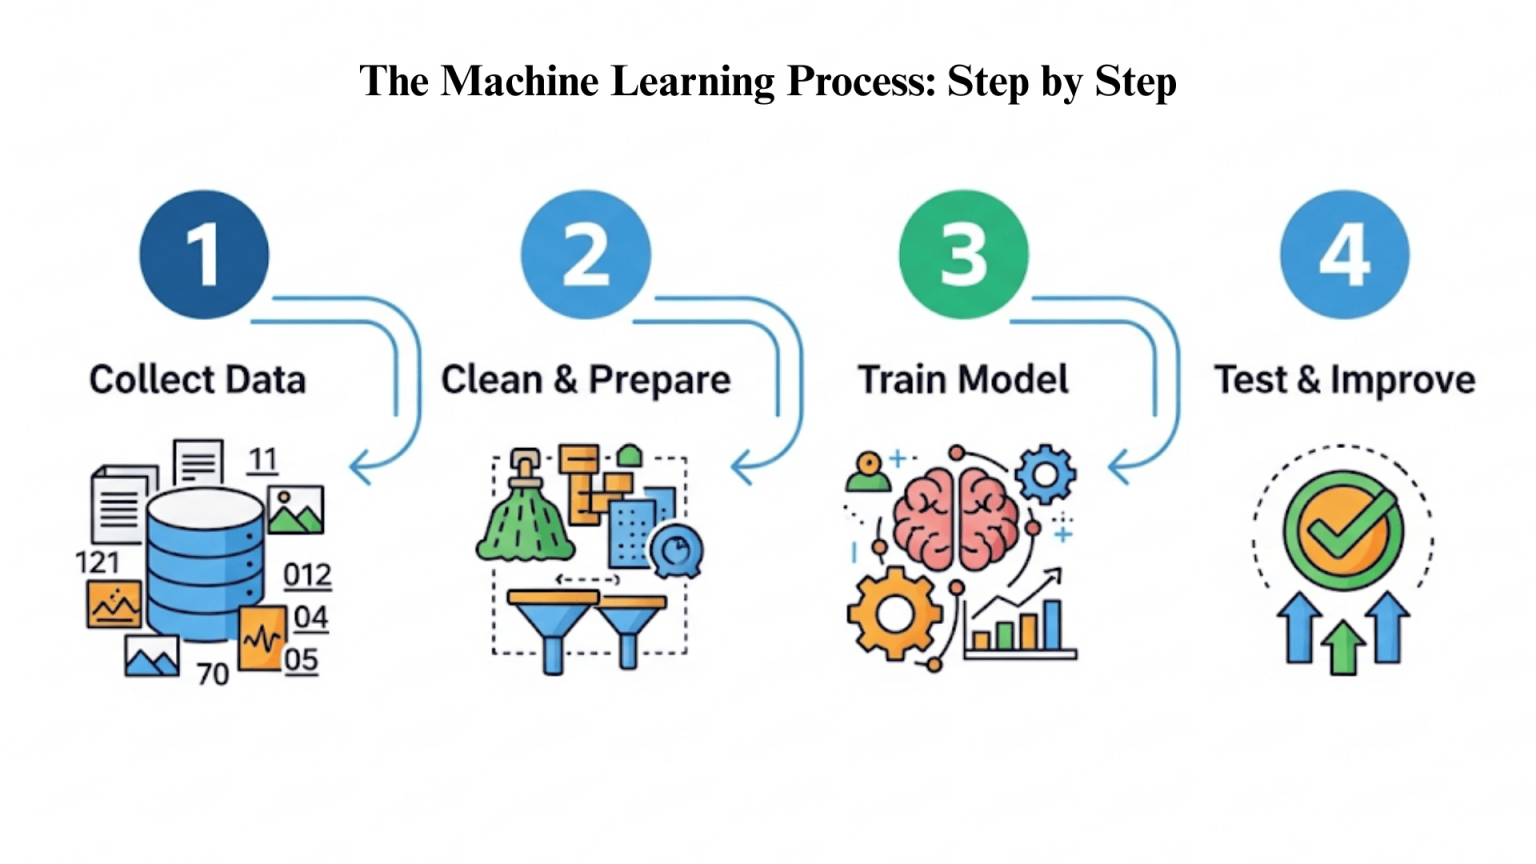
Most people jump into DIY machine learning because they can’t afford an engineer or they want to understand how the black box actually works. The path is straightforward — grab a dataset, pick a simple algorithm, train something, and iterate. But the reality is messier than the tutorials make it look. I started with a sentiment analysis project for product reviews. Picked up a CSV of about 8,000 labeled Amazon reviews, loaded scikit-learn, and thought I’d have something working by lunch. Took me three days because I skipped the preprocessing step entirely and fed raw text into a basic TF-IDF vectorizer. The model learned that “terrible,” “awful,” and “horrible” were positive signals because every terrible product review on Amazon includes the phrase “would not recommend.” The fix was adding a negation flipper. Shortest possible function — scan for “not” before each adjective and invert the polarity. That one change moved accuracy from 62% to 79%. I’ve since seen the same pattern repeat across every domain: preprocessing choices matter more than model selection in 90% of simple cases.
Diy Machine Learning Examples
Example 1: House Price Estimation You download a Kaggle housing dataset with features like square footage, bedrooms, location, and year built. Split it 80-20. Use LinearRegression from scikit-learn. Train it. Evaluate with Mean Absolute Error. Your first model might show $40,000 average error on a $300,000 house range. That’s acceptable for learning. The trick is dropping outliers — houses over $2 million skew the coefficients badly. Filter to the interquartile range before training and watch your error drop 30%. Example 2: Email Spam Filter
Get the SMS Spam Collection dataset. Roughly 5,500 messages. Vectorize with CountVectorizer, not TF-IDF, because spam relies on word presence, not term importance. Train NaiveBayes. Expect 95% accuracy on training, 82% on held-out test data. That gap means you’re overfitting to dataset-specific patterns. The workaround: add Laplace smoothing and reduce vocabulary to top 5,000 features. Real-world deployability jumps from “works in notebook” to “doesn’t break immediately.” Example 3: Image Classifier for Plant Leaves Transfer learning is the only sane way here. Download a pre-trained MobileNet model. Freeze the base layers. Add two dense layers on top. Train on a small plant disease dataset — maybe 2,000 images across six classes. You’ll hit 88% validation accuracy after 20 epochs on CPU in about 45 minutes. Fine-tuning the base layer instead of freezing it bumps you to 93%, but requires a GPU and runs for hours. If you don’t have one, stick with frozen base.
Get the Full Details
The counter-intuitive part nobody tells beginners: simpler models often beat deep learning on small datasets. A random forest with 100 trees on tabular data beats a neural net on anything under 10,000 rows. I learned this the hard way spending four hours tuning a multi-layer perceptron before switching to XGBoost and getting better results in ten minutes.
Where DIY ML Actually Fails
Online gradient descent breaks when your data doesn’t fit in RAM. I hit this with a 12GB feature matrix. Scikit-learn’s SGDClassifier just segfaulted. Switched to Vowpal Wabbit and got the same model running in 15 minutes with streaming data. For anything beyond basic classification, external tools are necessary, not optional. Another failure mode: assuming your training distribution matches your deployment distribution. I built a customer churn model that performed beautifully until deployed to a new market segment. The validation metrics were 94% AUC, but production performance dropped to 61% within two weeks. The problem wasn’t the model — it was that the new segment had different customer demographics. Always validate on out-of-distribution samples before deploying. Recommending alternatives: if you’re doing time series forecasting, use Prophet or statsmodels instead of building an LSTM from scratch. If you’re clustering, start with HDBSCAN rather than k-means, especially with uneven cluster sizes. If you’re doing NLP and don’t need interpretability, just fine-tune a small LLM. The compute savings are real.
Downloads and resources: scikit-learn.org for the standard toolkit, kaggle.com/datasets for practice data, huggingface.co/models for pretrained architectures. For local setup, use conda environments, not pip alone. Dependency conflicts will waste your weekend. The biggest mistake I see beginners make is starting with model architecture before understanding the data. Spend two days exploring your dataset — distribution analysis, missing value patterns, feature correlations. Then pick a model. The model selection takes twenty minutes. The exploration takes two weeks. Both parts are necessary. Neither is optional.