Getting Started With Diy Machine Learning Guide
You don't need a PhD to build working ML systems on your own. Most of the people posting tutorials online make it sound like you need a cluster of GPUs and three years of study before you can train anything useful. That's not true. What you actually need is a laptop, some patience, and the willingness to debug code instead of reading about it. I started down this road about five years ago, just trying to get a basic model to classify text without paying for cloud services. The first thing I ran into was that every tutorial assumes you already know how your data is structured. I wasted two weeks on a dataset that had missing values encoded as the string "N/A" instead of actual nulls. Scikit-learn just silently produced garbage results, no warning, no error. I caught it by looking at the actual predictions and noticing the model was assigning the same class to everything. Once I cleaned that column properly, the model started making real distinctions. That was the lesson I carry forward: check your data before you check your loss curve.
What You'll Actually Need
The Diy Machine Learning Guide community tends to recommend a pretty standard stack. Python, obviously. Then pandas for data handling, scikit-learn for everything baseline, and either PyTorch or TensorFlow depending on whether you plan to go deeper into neural networks. For most DIY projects, scikit-learn covers a surprising amount of ground. Random forests, gradient boosting, logistic regression, k-means clustering, PCA for dimensionality reduction. You can build production-quality models with just that. If you want to run training locally, you don't need a GPU to start. CPU-only training is fine for small to medium datasets. A modern consumer laptop with 16 GB of RAM and an M-series chip or a decent Intel i7 will handle most beginner to intermediate projects. The bottleneck usually isn't compute, it's bad data pipelines. I once spent three days trying to optimize a neural network that wasn't learning, only to realize the input features were all scaled differently and the optimizer was bouncing around the loss landscape like a pinball. A simple StandardScaler on the training split fixed everything in ten minutes.
The Practical Workflow
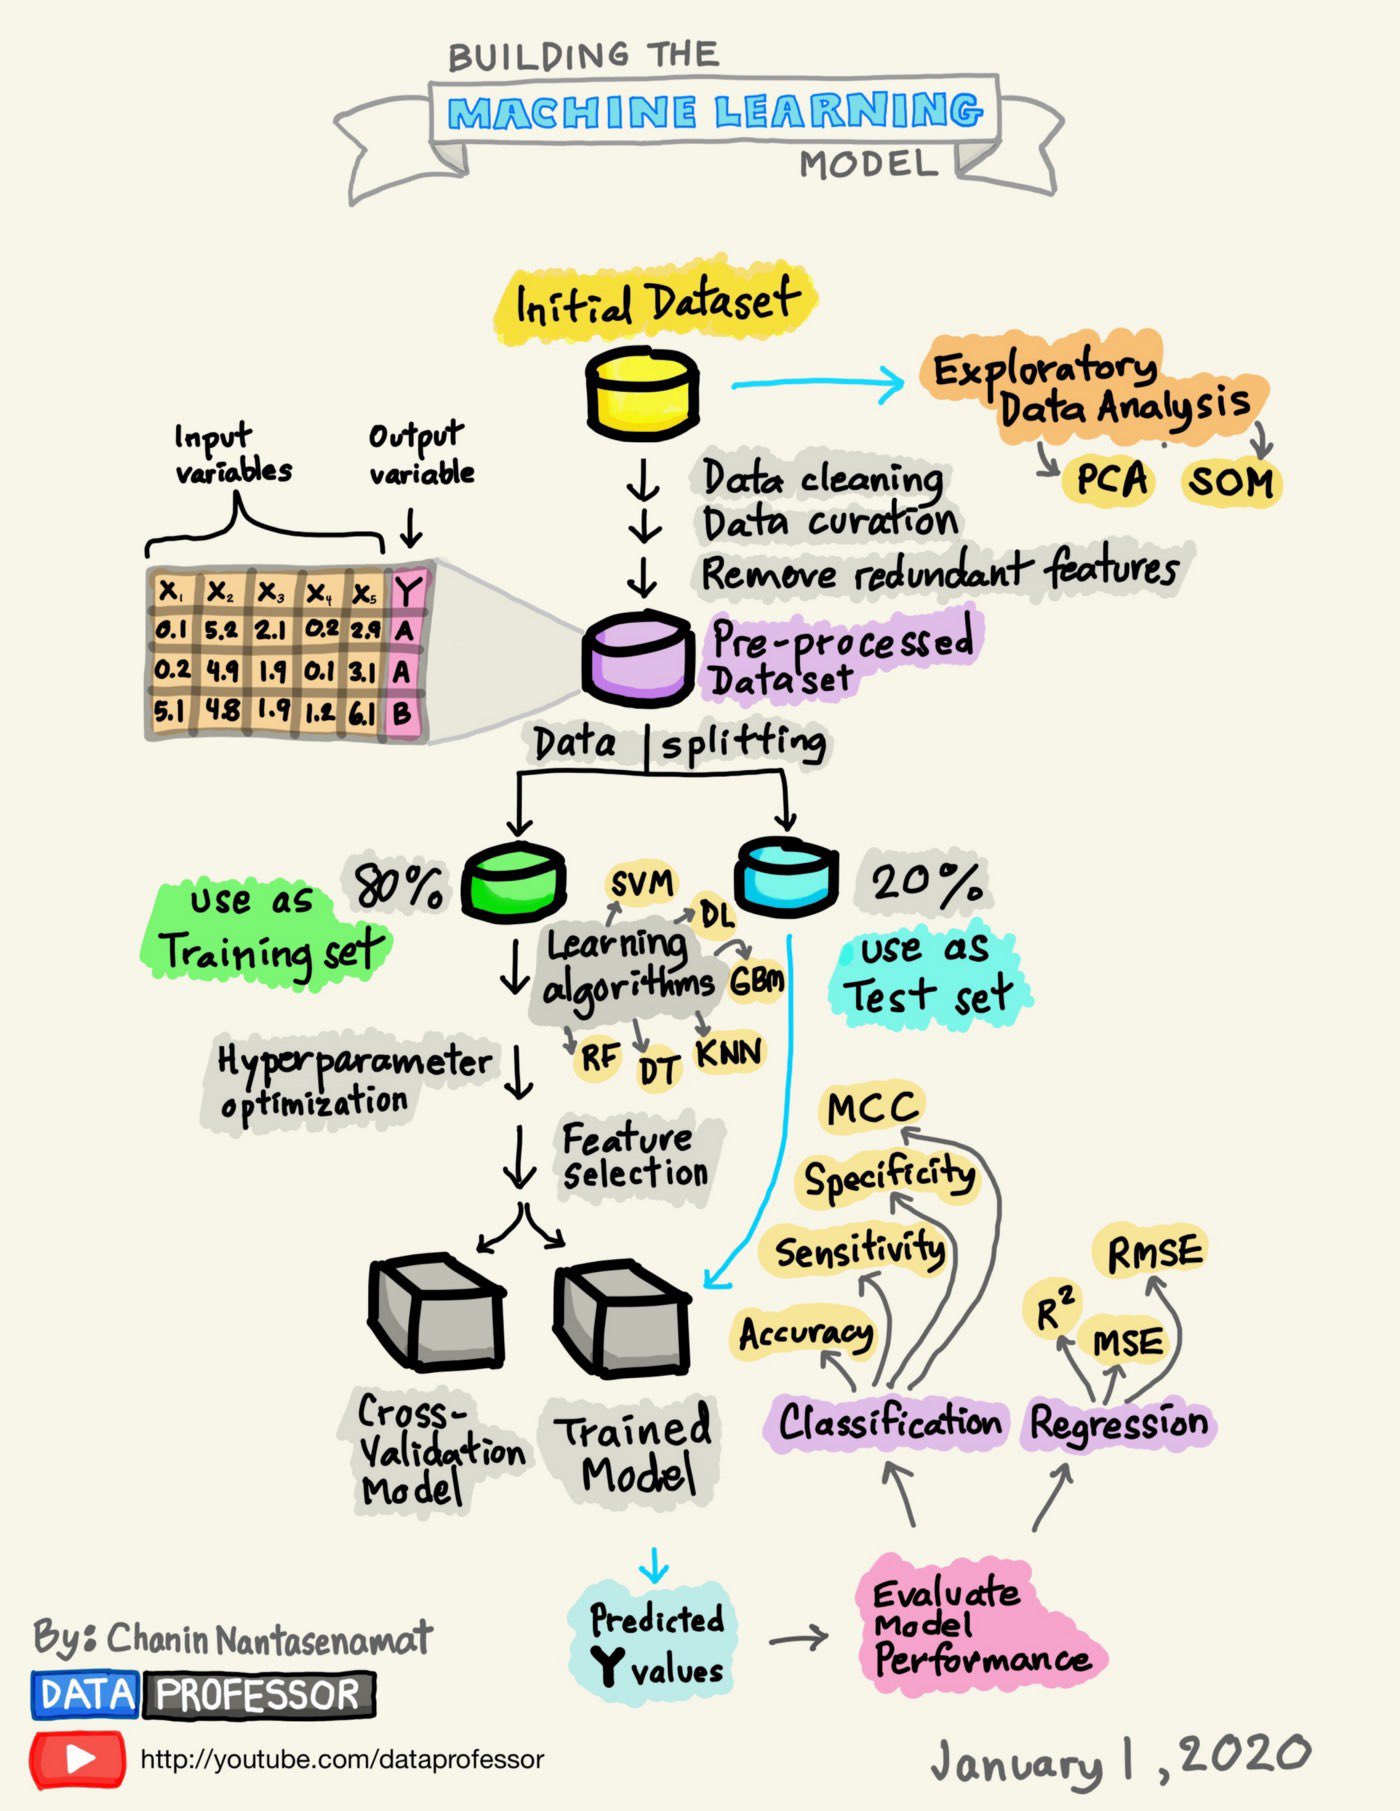
Here's the actual sequence I use now, after burning through enough failed experiments to stop guessing: First, define what success looks like. Pick one metric. Accuracy for classification, RMSE for regression. Don't optimize for five different metrics and then wonder why your model looks good on paper but fails in practice. A model that's 82% accurate but consistently wrong on the class you actually care about is worse than an 75% accurate model that nails that class. Second, get the data into a single file or directory and explore it without preprocessing. Load it, check shapes, count missing values, look at distributions. I keep a Jupyter notebook open for this that I never throw away, even if the project gets scrapped. Those exploratory cells become the foundation when you revisit the project later.
Get the Full Details

Third, split your data before you do any preprocessing that touches the target variable. I've seen people normalize their entire dataset before splitting, then complain about data leakage when their test results look unrealistically good. Train on train, transform on train, apply the same transform to test. That's it. Fourth, start with a dummy model. A classifier that always predicts the majority class. A regressor that always predicts the mean. You need this number so you know when something is actually better than nothing. If your fancy model doesn't beat the dummy by a meaningful margin, you're not solving a machine learning problem, you're overfitting noise. Fifth, pick a simple model and tune it. A random forest with cross-validation is usually the right starting point. It's fast, it handles mixed data types, it gives you feature importance out of the box. Only move to something more complex if the simple model hits a hard ceiling on your chosen metric.
Where People Go Wrong
The most common mistake I see is treating machine learning like a black box you can plug data into and expect answers out of. The second most common is stopping at the first model that works and not testing whether it generalizes. I learned this the hard way when I built a sentiment classifier for product reviews that performed great on my holdout set but fell apart on any new product category. The model had memorized words that only appeared in electronics reviews, not because those words carried actual sentiment signal. Adding a simple filter to remove terms that appeared in fewer than ten reviews across the entire training set fixed it. The model learned the structure of sentiment instead of the vocabulary of one niche. Another trap is ignoring class imbalance. If you have a fraud detection dataset where 99% of transactions are legitimate, a model that predicts "not fraud" every time gets 99% accuracy and is completely useless. Use precision-recall curves instead of ROC curves in these cases. They tell a more honest story about what your model actually does on the minority class.
Resources and Where to Find Help
There are a few solid resources that don't pretend everything is easier than it is. The scikit-learn documentation has practical examples for nearly every algorithm. Kaggle has datasets at all difficulty levels and a discussions section where experienced practitioners answer specific questions. There's also a broader Diy Machine Learning Guide community on GitHub where people share working code and honest post-mortems on projects that didn't work out. If you want a structured path that respects the fact that this takes time, the Diabetic Retinopathy dataset on Kaggle is a surprisingly good starting project. It has real-world messiness: imbalanced classes, image data that's manageable on a laptop, and a clear medical use case that keeps you honest about evaluation choices. The field moves fast and half the tutorials from two years ago already have deprecated APIs. I keep a local archive of working code snippets and skip videos that don't show the actual environment setup. Knowing which versions of which libraries you're running saves hours of dependency hell later.