Why I Started Keeping a Diy Statistics Logbook
I used to run experiments and track results in a messy collection of spreadsheet tabs and sticky notes. It worked fine until I needed to reproduce a finding six months later and couldn't remember which version of the dataset actually produced the p-value I'd cited. That's when I built a proper Diy Statistics Logbook. Not some fancy software purchase. Just a structured paper-and-digital hybrid that forces you to record the same information every single time. The core idea is simple. Every time you run a statistical test or collect a new dataset, you log it in one consistent format. The logbook becomes your audit trail. When someone asks how you got your confidence interval, you open the logbook and point at the entry. No guessing. No "I think I used version three of the data."
Building Your Diy Statistics Logbook
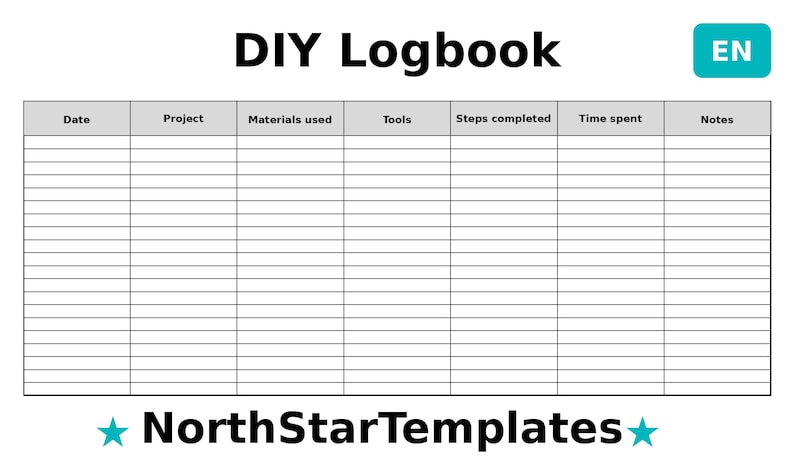
Start with a bound notebook for field notes and a companion digital file. The digital file is your searchable master record. I use a simple spreadsheet with columns that map directly to what matters in practice. The columns I always include are date, objective, dataset description, sample size, variables tracked, statistical test used, software and version, raw data file location, output file location, result summary, and a notes field for things that don't fit elsewhere. Here's what most people get wrong about this. They treat the logbook as a storage location for results rather than a record of process. The difference matters because results change when you revisit them. Process records don't. I've had entries where I originally reported a significant finding, came back three months later with fresh eyes, and realized I'd mis-specified my model. The logbook entry from the original run still showed me exactly what I'd done wrong because I'd written down the formula, the parameter values, and the decision to exclude three outliers. That entry saved me from repeating the same mistake on a completely different project. For the digital version, I recommend using a CSV format rather than a proprietary spreadsheet file. CSV files survive software updates, they're editable in any text editor, and you can parse them programmatically if you ever need to generate reports. I learned that the hard way when a spreadsheet program forced an update that broke my macro formulas and I spent half a day rebuilding things that a CSV would have avoided entirely.
The paper notebook gets its own system. I number every page and never skip pages. If I make an error, I draw a single line through it and initial it. This isn't ceremony. It's evidence. When you're dealing with a Diy Statistics Logbook in a regulated environment or when peer review comes knocking, a crossed-out entry with your initials is infinitely more credible than a pristine page that looks like nothing was ever complicated. Perfection on paper is suspicious. Correction marks on paper are honest. One practical detail that isn't obvious at first. Back up your digital logbook using a method other than cloud sync alone. I keep an external drive, a cloud folder, and a local folder on my work machine. The reason is straightforward. Cloud services change terms. They delete files. They migrate data in ways that corrupt timestamps. The external drive with a full mirror copy costs you maybe twenty minutes per month and eliminates that category of failure entirely.
Get the Full Details
What Actually Goes in Each Entry
Let me walk through a real entry from my own logbook. This isn't a textbook example. This is something I logged last winter while analyzing customer churn data for a small SaaS company. Date was January 14th. Objective was determining whether a new onboarding email sequence reduced 30-day churn. Dataset description was anonymized user records from the analytics platform, covering 2,847 accounts between September and December of the prior year. Sample size was the full 2,847. Variables tracked included cohort assignment (test versus control), onboarding completion rate, support ticket count in the first fourteen days, and whether the account converted to a paid plan within thirty days. Statistical test was a logistic regression with cohort and support tickets as predictors and churn within thirty days as the binary outcome. Software was R version 4.3.1 using the glm function with a binomial family and logit link. Raw data file was stored at /data/churn_analysis/raw_jan2025.csv with a SHA-256 checksum written down beside it. Output went to /data/churn_analysis/results/cohort_model_output.csv. Results showed a coefficient of negative zero point zero four two for the test cohort with a standard error of zero point zero eighteen and a p-value of zero zero three eight. Interpretation was a modest but statistically significant reduction in churn odds for the test group. Notes field contained the edge case that hit me here. Two accounts in the control group had been manually moved into the test group by the marketing team three weeks into the study. I excluded them but flagged the exclusion in the log. That note turned out to matter when a stakeholder later asked why the confidence intervals looked wider than expected. The answer was in the logbook entry, not in my memory.
That's the actual utility of a Diy Statistics Logbook. It captures the decisions, not just the numbers. Most people log the coefficient and move on. The coefficient is the easy part. The decision to exclude those two accounts, the reasoning behind it, and the fact that you noticed it was the unusual part. That's what belongs in the notes field.
Common Mistakes People Make With Their Logbook
People skip the software version line. This sounds minor. It isn't. Different versions of statistical packages handle missing data differently. A logistic regression in one version might drop a case with any missing predictor. Another version might use listwise deletion across the entire row. Without the version documented, you cannot reproduce the result. I found this out when a colleague tried to replicate a model I'd run a year earlier. We got different standard errors. Turns out I'd upgraded between runs and the default behavior for handling incomplete cases had shifted. The logbook entry that included the version number was the only thing that let us identify the problem quickly. Another mistake is recording only the final result instead of the intermediate steps. If you filtered your data, transformed variables, or checked assumptions, write that down. Don't assume you'll remember whether you log-transformed a skewed variable or just truncated it. Six months from now, you won't. I have an entry where I spent an afternoon tracing why my residual plots looked wrong. The logbook showed I'd applied a square root transformation to a Poisson count variable instead of a log transformation. The fix was trivial once I found the note. Without the note, I would have kept going in circles. People also tend to make their logbook entries too short. They write "ran analysis" instead of writing what they actually ran. "Ran analysis" is useless. "Ran a two-sample t-test assuming equal variance after confirming homogeneity of variance with Levene's test and finding a p-value of 0.23" is useful. The difference is the gap between what you think you documented and what you actually documented.

There's also a tendency to treat the logbook as a one-time setup. You complete the first few entries with discipline and then gradually stop filling out the notes field or the checksums or the file paths. The logbook degrades into a half-empty shell. I combat this by keeping the format simple enough that even a rushed entry takes less than three minutes to complete. If the logbook itself becomes a burden, you'll abandon it. I've seen it happen repeatedly. The structure should be rigid on the required fields but flexible enough that you can complete an entry during a twenty-minute coffee break without feeling like you're doing paperwork.
When a Diy Statistics Logbook Isn't Enough
I want to be clear about the limitations. A logbook records what you did. It doesn't verify that what you did was correct. You can meticulously document a flawed methodology and the logbook will faithfully record your flaw. The logbook is an audit tool, not a quality control tool. It catches omissions and inconsistencies. It does not catch conceptual errors in your experimental design. For large teams or projects with regulatory requirements, a paper-and-spreadsheet logbook will eventually hit a wall. The wall is searchability. Once you have five hundred entries, finding a specific analysis by variable or date in a spreadsheet becomes tedious. At that point you'd be better served by a dedicated laboratory information management system or at minimum a structured database with proper indexing. The Diy Statistics Logbook works well for individuals or small teams handling fewer than a couple hundred analyses per year. Beyond that, the friction of manual entry outweighs the simplicity advantage. There's also the issue of data sensitivity. If your logbook entries reference file paths that contain identifiable information, you've created a secondary data exposure risk. I had to restructure my system after realizing that the raw data file paths in my logbook included server names and directory structures that could identify client systems to anyone who accessed the notebook. I moved to relative paths and descriptive aliases instead. The logbook still works the same way. I just stopped storing infrastructure details alongside my statistical records.
Don't expect the logbook to replace version control for your data and code. It complements git. Git handles code and data versioning. The logbook handles the contextual decisions that git ignores. You need both. I keep a README in each data folder that links back to the relevant logbook entry number. That connection between the two systems is where the real value sits. If you're going to build a Diy Statistics Logbook, start small. Set up the spreadsheet columns. Buy the notebook. Do one entry today. The system only works if you use it continuously. An empty logbook is worse than no logbook because it creates the illusion of rigor without the substance behind it. Just start logging and keep the entries honest.