Working With Dna Mutation Simulation Worksheets
A DNA mutation simulation worksheet is a tool used in genetics education and research to model how genetic sequences change over time. It tracks point mutations, insertions, deletions, and frameshifts across generations or experimental conditions. You feed in a starting sequence, apply mutation rules, and the worksheet calculates outcomes. I built my first one back in 2014 using Excel because the off-the-shelf tools at the time were either too expensive or too clunky for actual lab work. Most people treat it like a classroom exercise, but it's useful for real population genetics modeling too. The tricky part is that the math gets messy fast when you introduce variable mutation rates across different codon positions. Here is how I approach building a functional Dna Mutation Simulation Worksheet from scratch.
Dna Mutation Simulation Worksheet Construction Guide
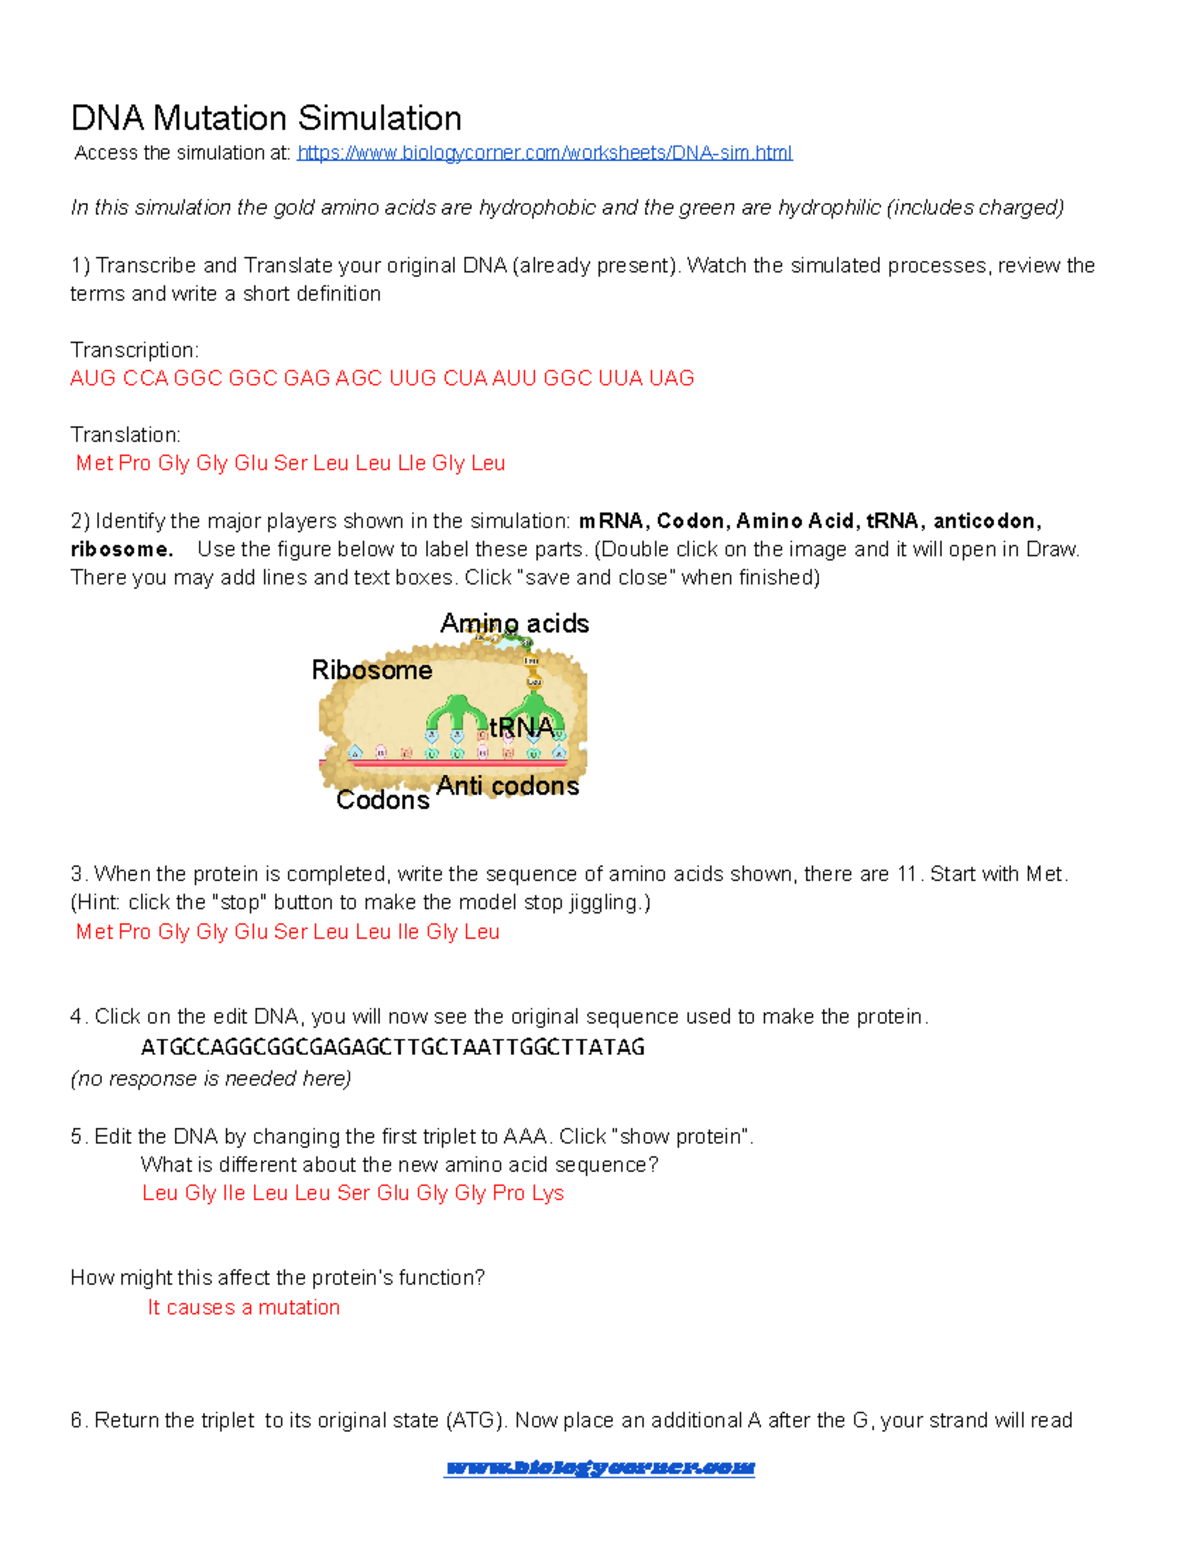
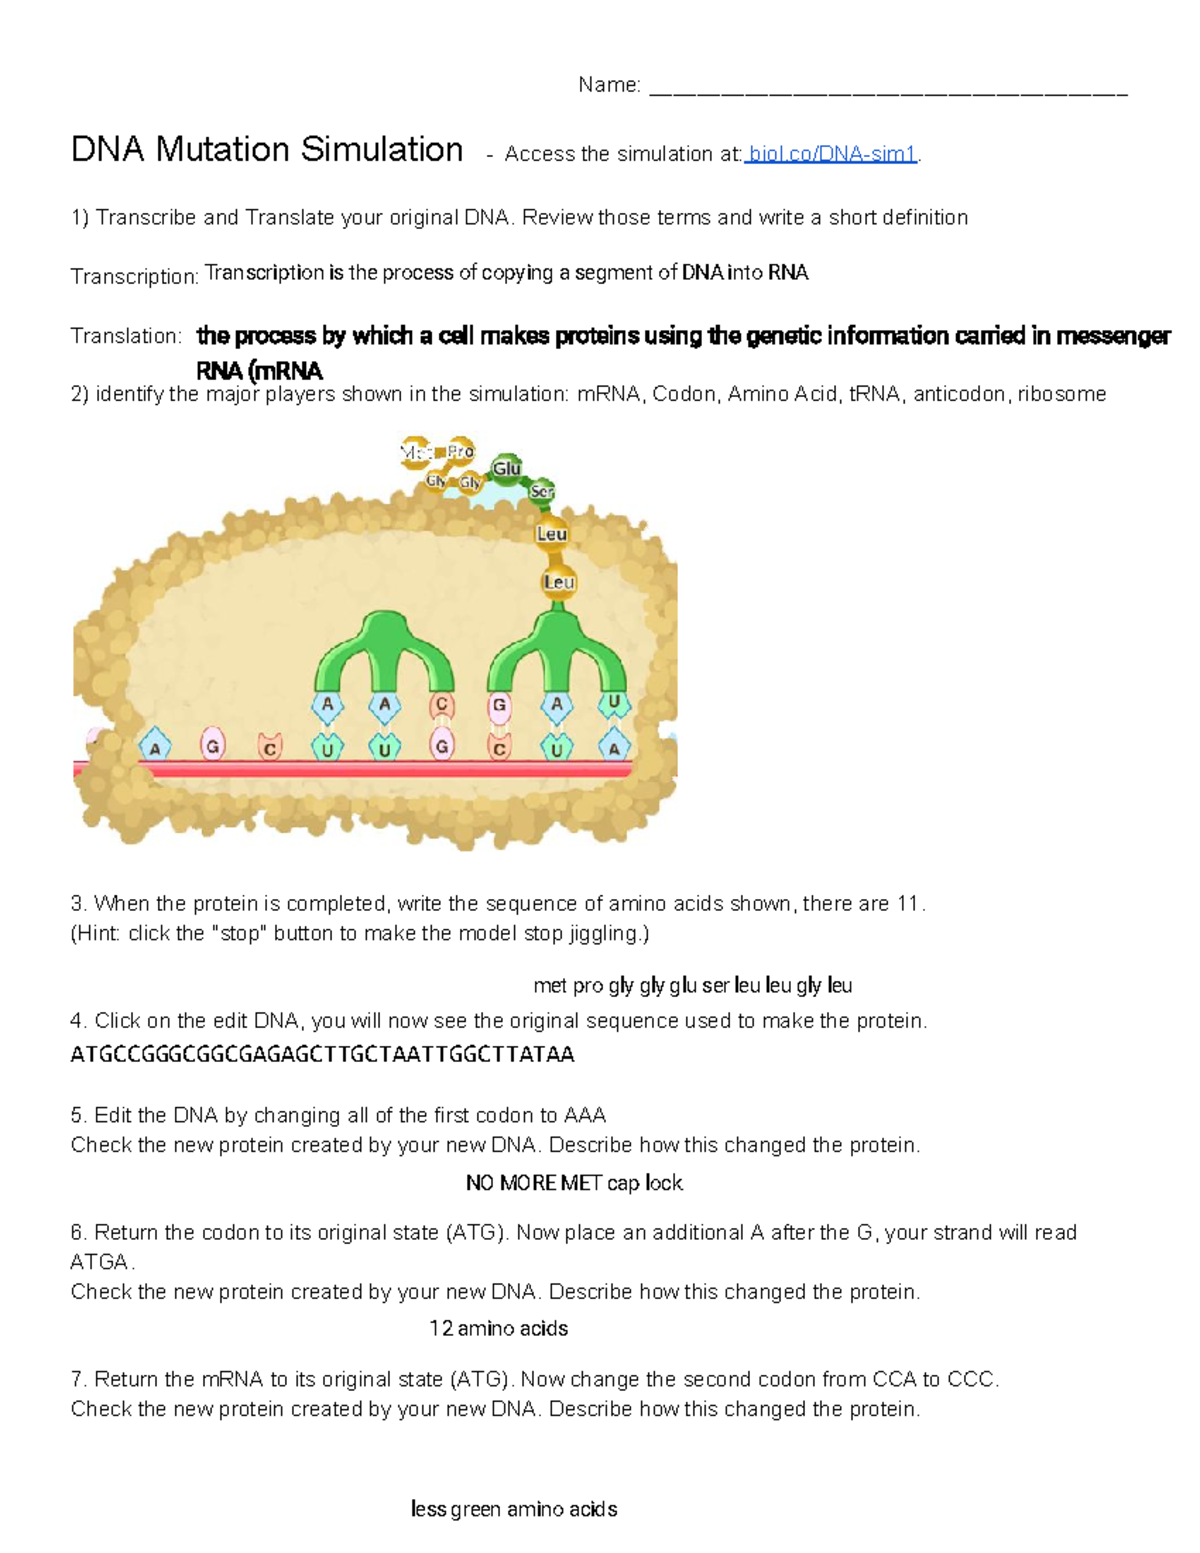
Start with a flat spreadsheet. I use Google Sheets because it handles large sequence matrices better than Excel does, though the logic applies either way. You need four columns minimum: sequence ID, parent sequence, mutation event, and resulting sequence. Add a fifth column for fitness score if you are running a selection model. The mutation engine is where most people mess up. A point mutation replaces one base. An insertion adds one or more bases and shifts everything downstream. A deletion removes bases. A frameshift is not a separate mutation type, it is the consequence of an insertion or deletion that is not divisible by three. I learned that the hard way when I submitted a simulation that predicted a full protein structure instead of a truncated mess because I had accidentally applied a frameshift as a point mutation. Set up your codon table as a lookup. This is non-negotiable. Without a proper codon-to-amino-acid mapping, your simulation outputs are just random letter strings. I store the standard genetic code in a separate sheet and reference it. The Wobble position matters here too. Third-codon-position mutations are silent more often than beginners expect, so your worksheet should account for synonymous versus nonsynonymous distinction.
For the mutation probability logic, I use a per-base-per-generation rate. The typical bacterial mutation rate is around 10 to the negative 9 per base pair per generation. Eukaryotes run higher, somewhere in the 10 to the negative 8 range depending on the organism. Your simulation needs a random number generator scaled to these rates. I use the RANDOM function multiplied by the rate and check if it falls below the threshold. That gives you a binary mutation event per base per generation. When you track population-level simulations, add a column for allele frequency. If you are modeling drift versus selection, you need a population size input and a selection coefficient. The Hardy-Weinberg equations apply if you are assuming no evolutionary forces, which is rarely realistic but serves as a baseline. I usually run ten thousand generations for a clean drift curve. That takes about three to five minutes on a modern machine with a properly optimized sheet. One thing I run into constantly is terminal state confusion. The worksheet will keep running even after all sequences have converged or been lost. I add a convergence check that stops the simulation when the remaining diversity drops below a threshold, usually less than one percent heterozygosity. Without that, your runtime explodes for no reason.
Get the Full Details

Common Pitfalls and What Actually Works
Beginners often forget that frameshifts cascade. A single insertion early in a coding sequence doesn't just shift one codon. It shifts every codon after it until a stop codon appears. Make sure your simulation scans for stop codons in all three reading frames after any indel event. I wasted two days debugging a simulation that kept producing full-length proteins after frameshifts because I had not implemented premature termination detection. Another issue isGC content bias. Real genomes do not mutate uniformly. CpG sites in vertebrates mutate roughly ten times faster than other dinucleotides because of methylation and deamination. If your worksheet applies a flat mutation rate across all positions, your results will look wrong compared to real sequencing data. I added a position-weighted rate matrix after that realization, which brought the simulated divergence patterns much closer to observed phylogenetic data. For the download, I keep a stripped-down version of my working template on my site. It includes the codon lookup table, the mutation engine, and a generation counter. You can adjust the parameters for your own organism or classroom scenario. Search for Dna Mutation Simulation Worksheet download and you should find the template. It is free and open source, licensed under Creative Commons.
If you need something more robust than a spreadsheet, consider using a dedicated tool like Seq-gen or DnaSP. Spreadsheets break down around fifty thousand base pairs and twenty thousand generations. For anything larger, you are better off writing a small Python script with Biopython. The learning curve is steeper but it handles the computation without the lag and formula-throttling that kills spreadsheet simulations past a certain size. The worksheet is fine for teaching and small-scale modeling. Just don't expect it to replace proper simulation software when you move into publishable work. I still use mine for quick checks and classroom demos, but my actual research pipelines have moved entirely to command-line tools. The spreadsheet version has its place, and that is where I keep it.