Transcribing DNA to Protein: A Practical Guide
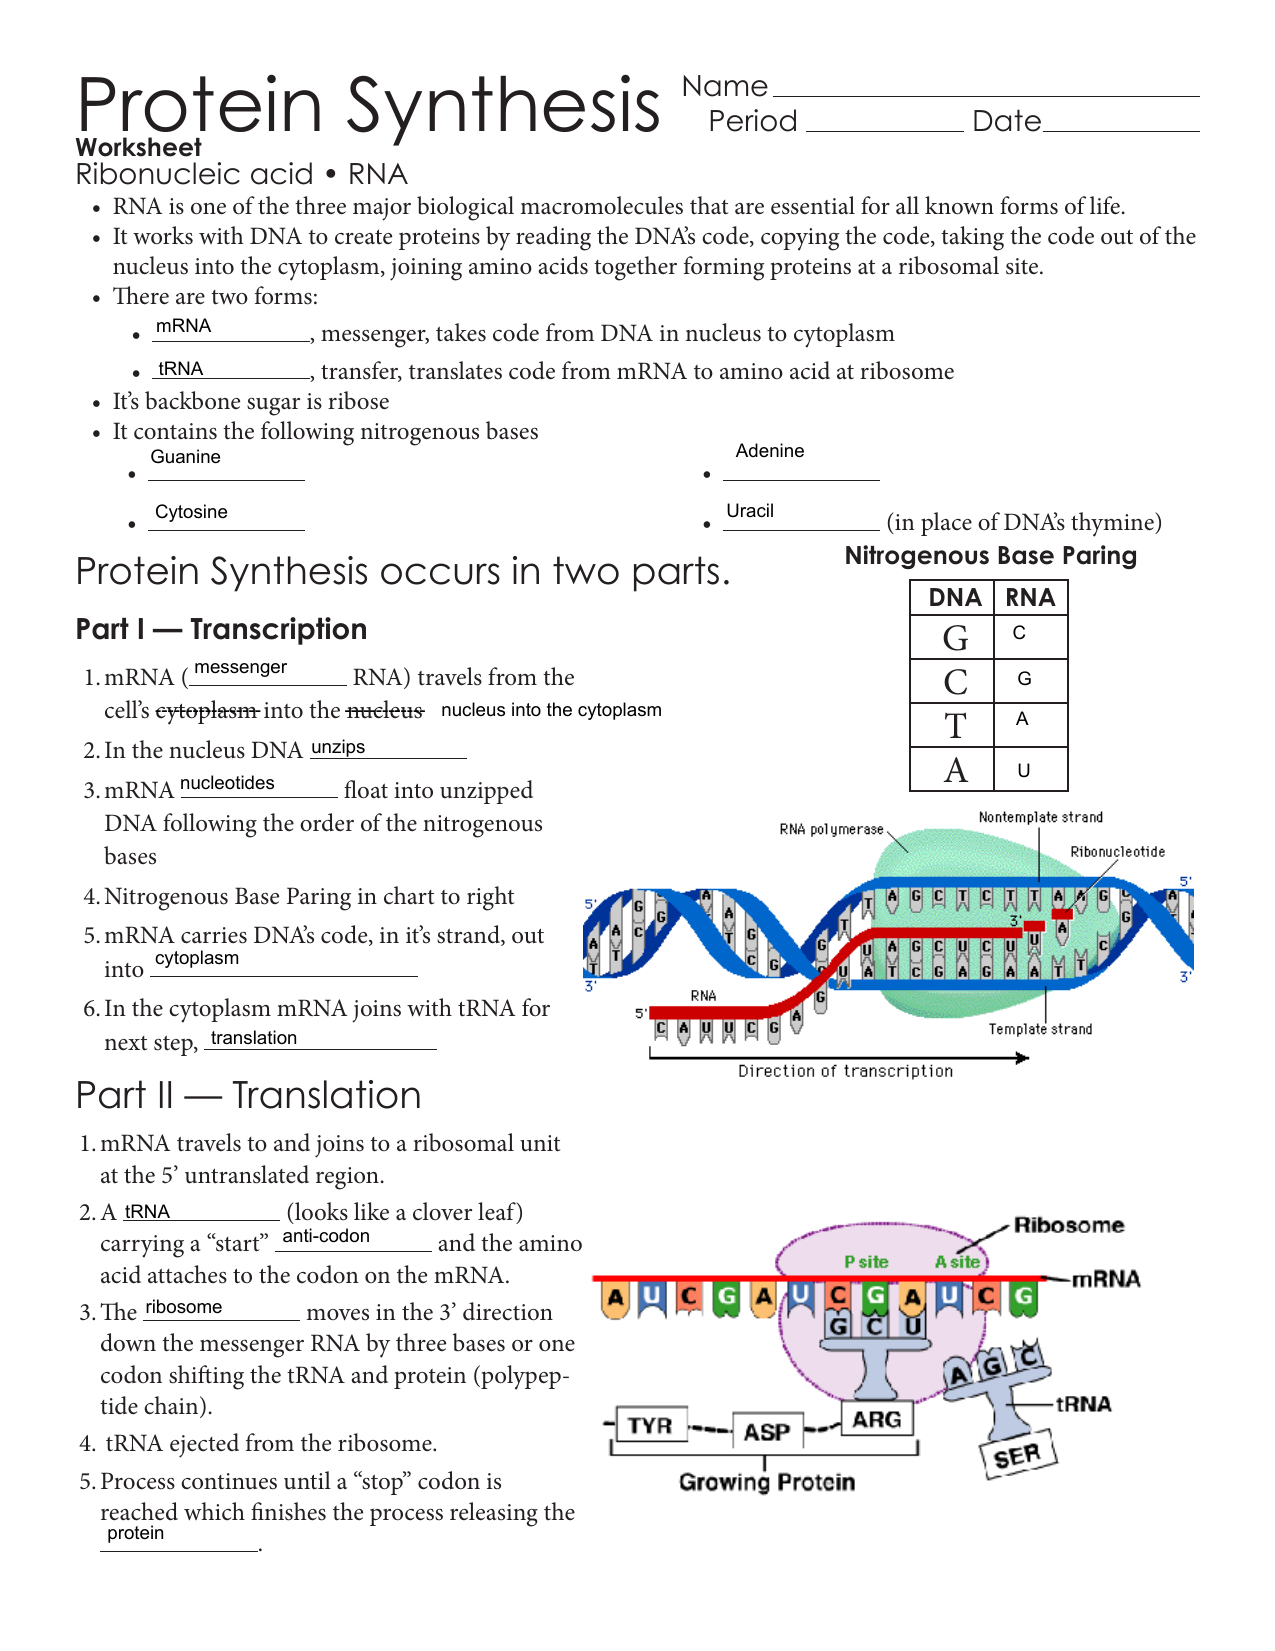
I've seen students spend weeks confused about why their worksheets keep producing nonsense amino acid sequences. The core issue is usually that they're applying base-pairing rules inconsistently between the template strand and the mRNA, or they're reading codons in the wrong direction. This guide walks through what a Dna To Protein Worksheet actually tests, how to work through one correctly, and where most people fall apart. A DNA to protein worksheet is simply a set of practice problems asking you to go from a DNA sequence to a corresponding amino acid chain. It looks straightforward on the surface, but the devil is in the details: which DNA strand are you given, are you supposed to transcribe the coding strand or the template strand, and are there introns complicating things? I've worked through hundreds of these, and the ones that trip people up are never the simple "here's a template strand, write the mRNA" problems. They're the trickier ones where the non-template (coding) strand is given instead, or where the sequence includes a stop codon placed strategically to catch students who forget to check for it. First, identify which strand you're given. If it says "template strand" (also called the antisense strand), you transcribe it directly by writing the complementary mRNA. If it says "coding strand" (the sense strand), you basically copy that strand but swap thymine for uracil, since the mRNA looks almost identical to the coding strand except for U replacing T. I always tell my students to pause here and double-check. Getting this wrong means your entire answer is backwards from that point on, and you waste ten minutes you'll never get back.
Once you have your mRNA, break it into codons—groups of three nucleotides—starting from the 5' end. Use a codon table to translate each one. A standard genetic code table maps each three-base codon to an amino acid or a stop signal. AUG is the start codon and codes for methionine. UAA, UAG, and UGA are stop codons and signal the end of translation. No amino acid is added for a stop codon. Let me show you a concrete example. Say your worksheet gives you this template strand: 3'-TAC GGC CTA AGC TTA-5'
The mRNA would be: 5'-AUG CCG GAU UCG AAU-3' Split into codons: AUG | CCG | GAU | UCG | AAU. Translating: Met-Pro-Asp-Ser-Asn. That's it. One stretch of mRNA, one short peptide.
Get the Full Details

A Realistic Edge Case
Here's something I ran into recently that nobody warns students about. A worksheet gave a coding strand sequence that was longer than what actually gets translated. The sequence included start and stop codons, but also extra bases flanking both sides. When I first saw it, I translated the whole thing and got an absurdly long peptide with a stop codon buried in the middle because I was reading the wrong reading frame. The trick is to scan the coding strand (or its mRNA equivalent) for the first ATG (AUG in mRNA) that appears after the 5' end, then keep translating until you hit a stop codon. Everything outside that open reading frame is irrelevant. I learned this the hard way during a practice exam when half the class produced completely wrong answers because they didn't identify the proper reading frame first. Reading frames are the number one mistake. If you shift by even one nucleotide, every codon downstream changes and you get garbage. Always triple-check your groupings. Another frequent error is mixing up the template and coding strands, which flips the whole process. A third is forgetting that the worksheet may give you the template strand written 3' to 5', and if you blindly write the complement without respecting directionality, your mRNA will be backwards. Also worth noting: some worksheets include splicing. If you're working with eukaryotic DNA, introns get removed and exons get joined before translation. A worksheet that says "eukaryotic gene" without showing you which parts are introns is either a poorly designed question or an advanced one testing whether you can spot intron motifs like GT-AG splice sites. I've seen students lose points for not removing hypothetical introns. If the instructions don't specify which segments to splice out, assume it's a prokaryotic system and no splicing occurs. But flag it if you're unsure and move forward with the simpler assumption.
Working Through a Full Example
Let's take a slightly more complex case. Here's a coding strand: 5'-ATGCCCGATTCGTAA-3' The mRNA is basically the same with U instead of T:
5'-AUGCCCGAUUCG UAA-3' Codons: AUG | CCC | GAU | UCG | UAA. Translation: Met-Pro-Asp-Ser-[STOP]. The UAA stop codon terminates translation. The final product is a four-amino-acid peptide. Notice I didn't add anything for UAA—that's a critical detail. Students often write "stop" as an amino acid in their answer and lose points.

What These Worksheets Can't Do
A DNA to protein worksheet is a simplified abstraction. In real cells, transcription and translation are coupled in prokaryotes, RNA polymerase has proofreading, ribosomes undergo conformational changes during elongation, and post-translational modifications like phosphorylation or glycosylation can alter the final protein. None of that shows up on a worksheet. The worksheet tests whether you understand the central dogma's basic flow and can apply the genetic code. That's it. It won't teach you about alternative splicing variants, codon bias in different organisms, or how mutations actually affect protein folding in practice. For those things, you need a molecular biology course or a bioinformatics tool. If you find yourself stuck on a worksheet, the best approach is to slow down on the strand identification step, write out the mRNA explicitly before trying to translate, and verify your codon groupings against a printed or digital genetic code table. Most errors happen in the first five minutes before anyone even starts translating. Getting that right makes the rest mechanical.