Getting Actual Protein Out Of Your Construct
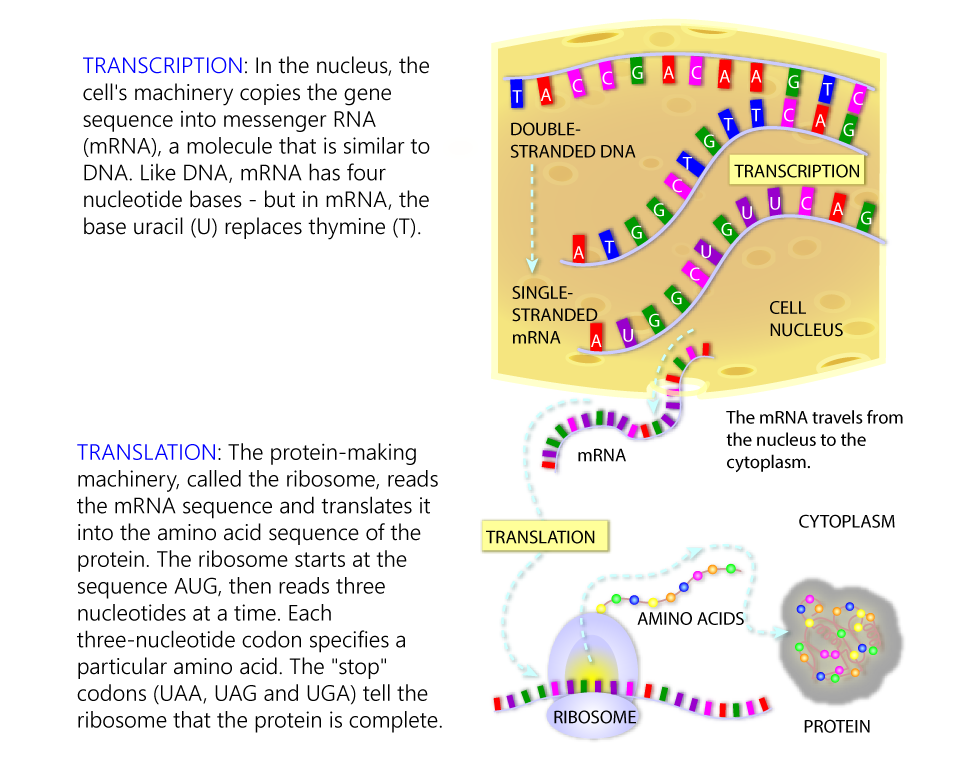
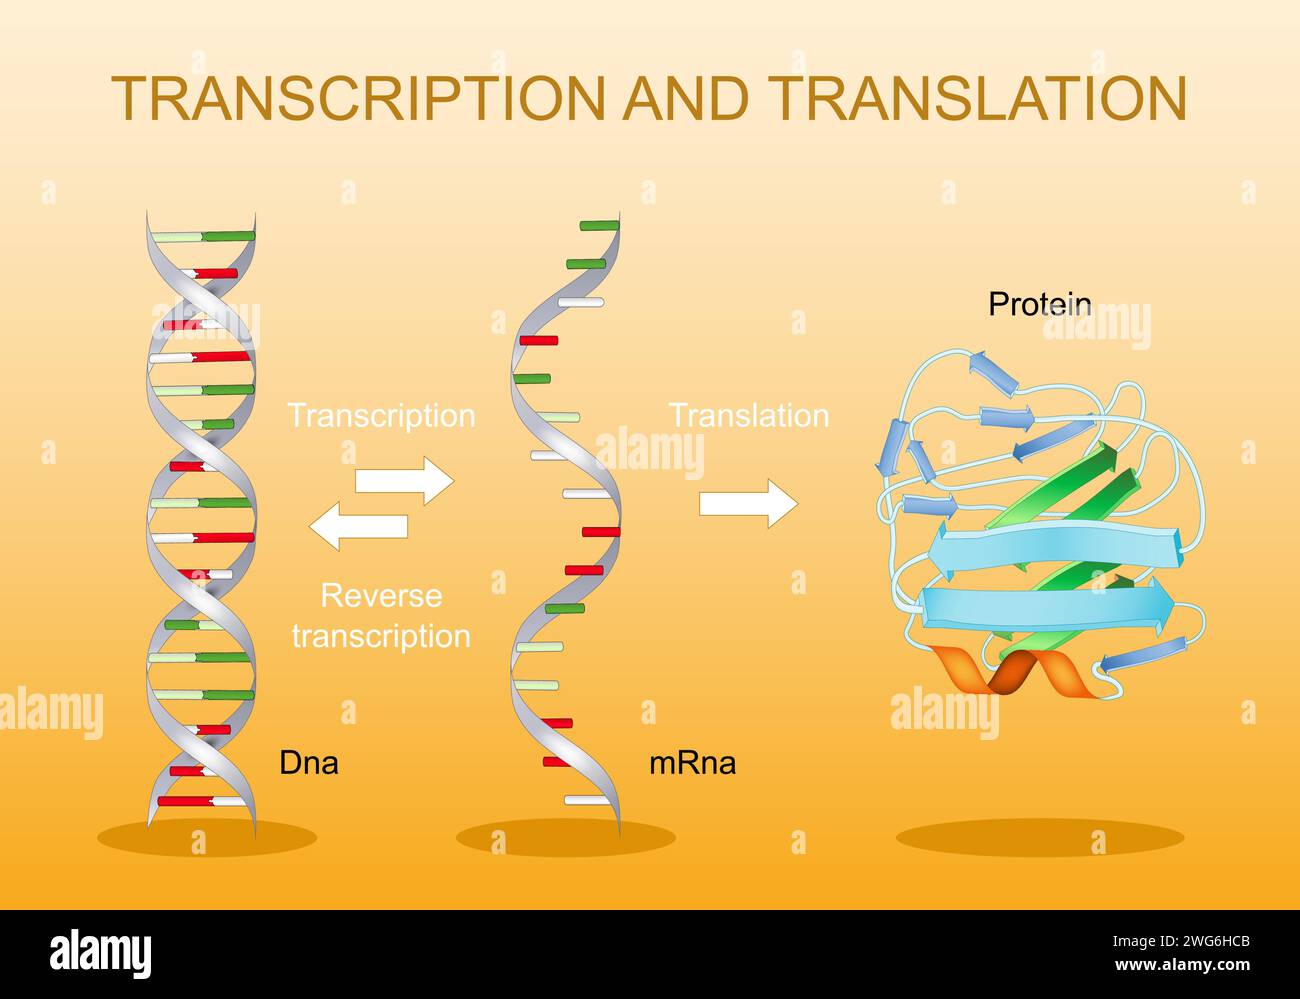
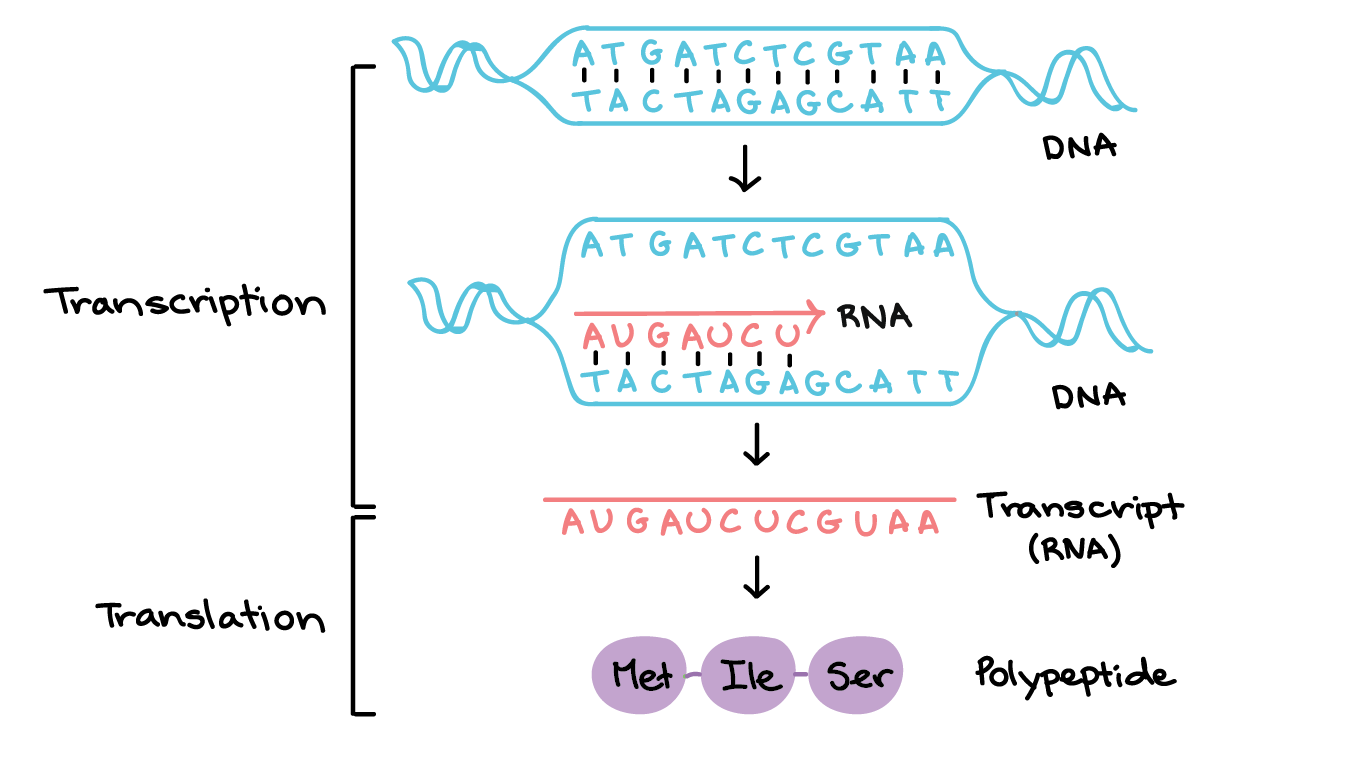
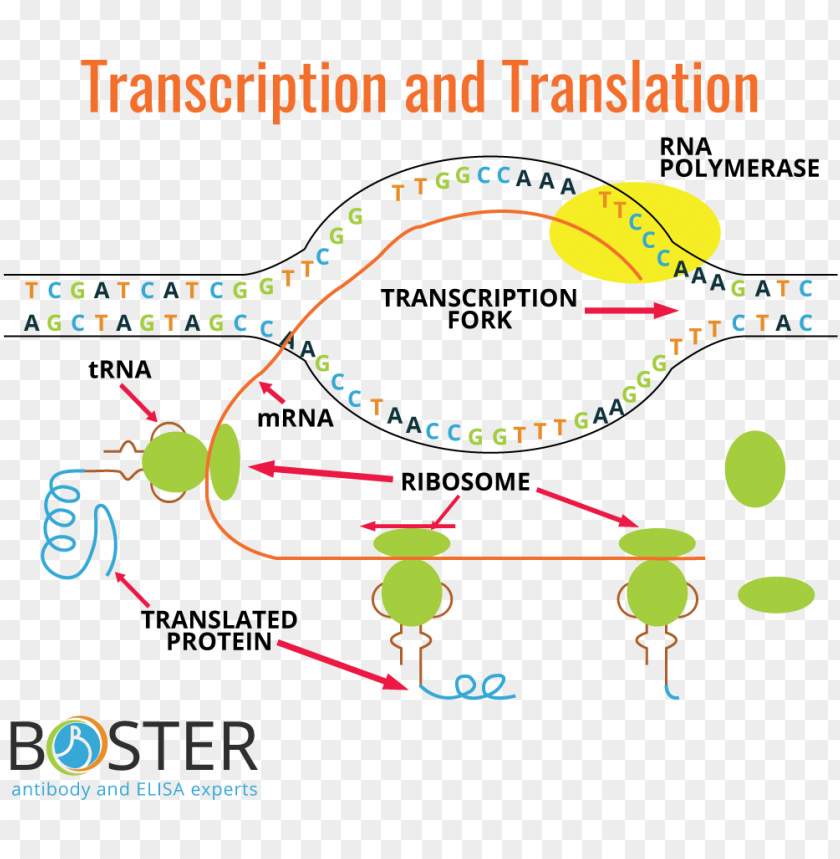
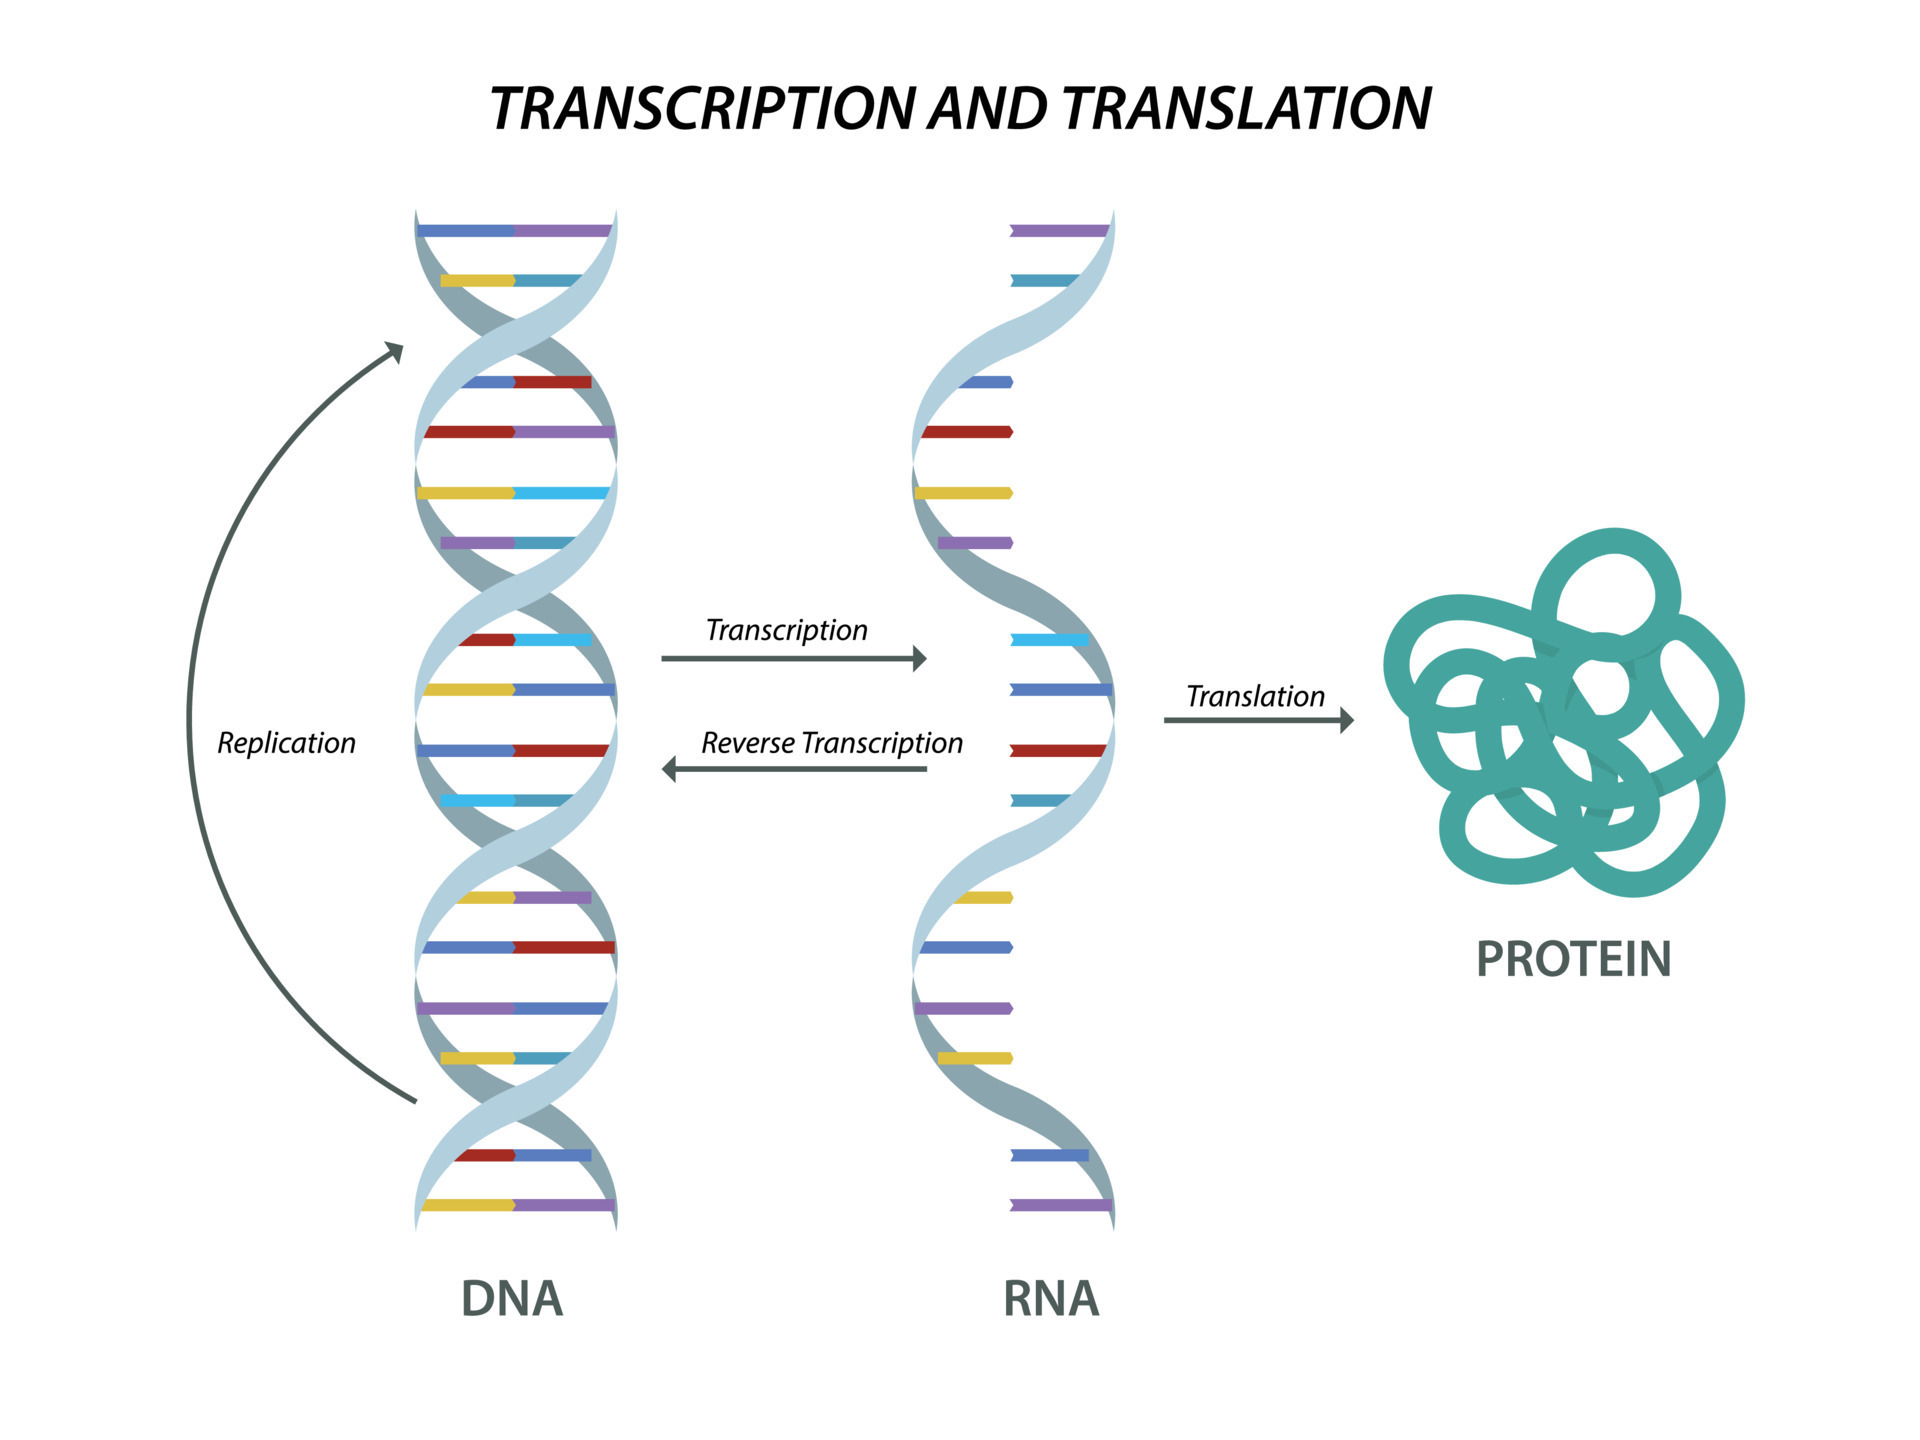
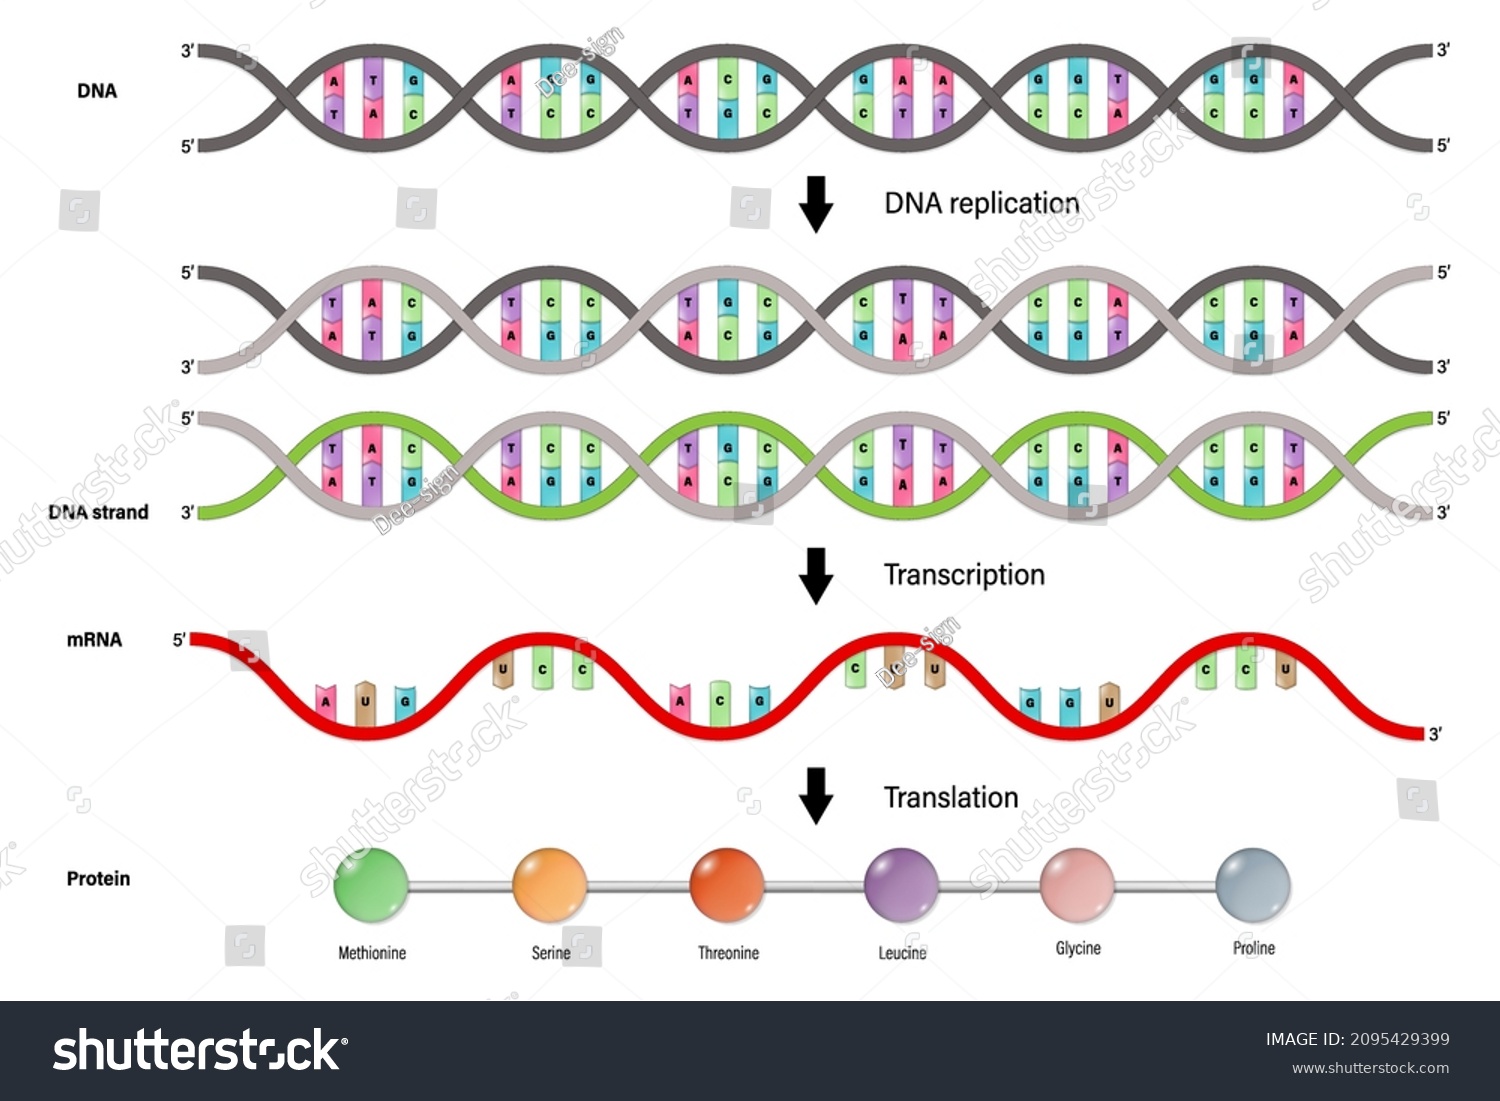
Most people learn about dna transcription and translation in a textbook diagram that looks like an assembly line, but actually running these processes in the lab is nowhere near that clean. You'll spend more time troubleshooting failed expressions than anything else, especially if you're working with mammalian cell lines or trying to produce something that doesn't fold the way it should. The basic mechanism is straightforward enough. RNA polymerase reads the DNA template strand from 3' to 5' and synthesizes a complementary mRNA strand in the 5' to 3' direction. Then ribosomes dock at the start codon and read triplet codons, recruiting the matching tRNAs charged with amino acids, building the polypeptide chain until a stop codon terminates the process. But the devil is in the details. I once spent three weeks trying to express a human protein in E. coli and couldn't figure out why the yield was essentially zero after confirming the sequence was correct. The issue turned out to be rare codons - my construct had several clusters of arginine codons that matched AGA and AGG, which are rare in E. coli and correspond to tRNAs that are present in very low abundance. The ribosome would stall at those positions, and the protein wouldn't complete. I fixed it by cotransforming the cells with a plasmid carrying the rare tRNA genes, the kind used in Rosetta strain systems. That alone went from a non-starter to a workable expression system.Common pitfall number one: people assume that if the gene is transcribed, translation will follow automatically. In eukaryotic cells this is even more disconnected than in prokaryotes. The mRNA has to be exported from the nucleus before any ribosome can touch it, and there are quality control checkpoints along the way that can degrade your transcript before it ever gets translated.
You also need to think about the 5' cap and the poly-A tail if you're working with eukaryotic systems. These aren't decorative additions. The cap structure is recognized by the translation initiation complex, and without it ribosomes won't efficiently load onto the mRNA. The poly-A tail works with the cap through protein bridges to circularize the mRNA, making the ribosome recycle instead of just falling off the end. Another thing nobody warns you about is codon usage bias and how it affects both transcription efficiency and translation speed. Just because your genetic code technically works doesn't mean the cellular machinery handles it the same way it handles native genes. I've seen constructs with identical coding sequences but different codon optimizations produce anywhere from 10% to 400% of each other in protein yield depending on the host organism.