Why Domain Of Ethical Assessment Keeps Breaking In Production
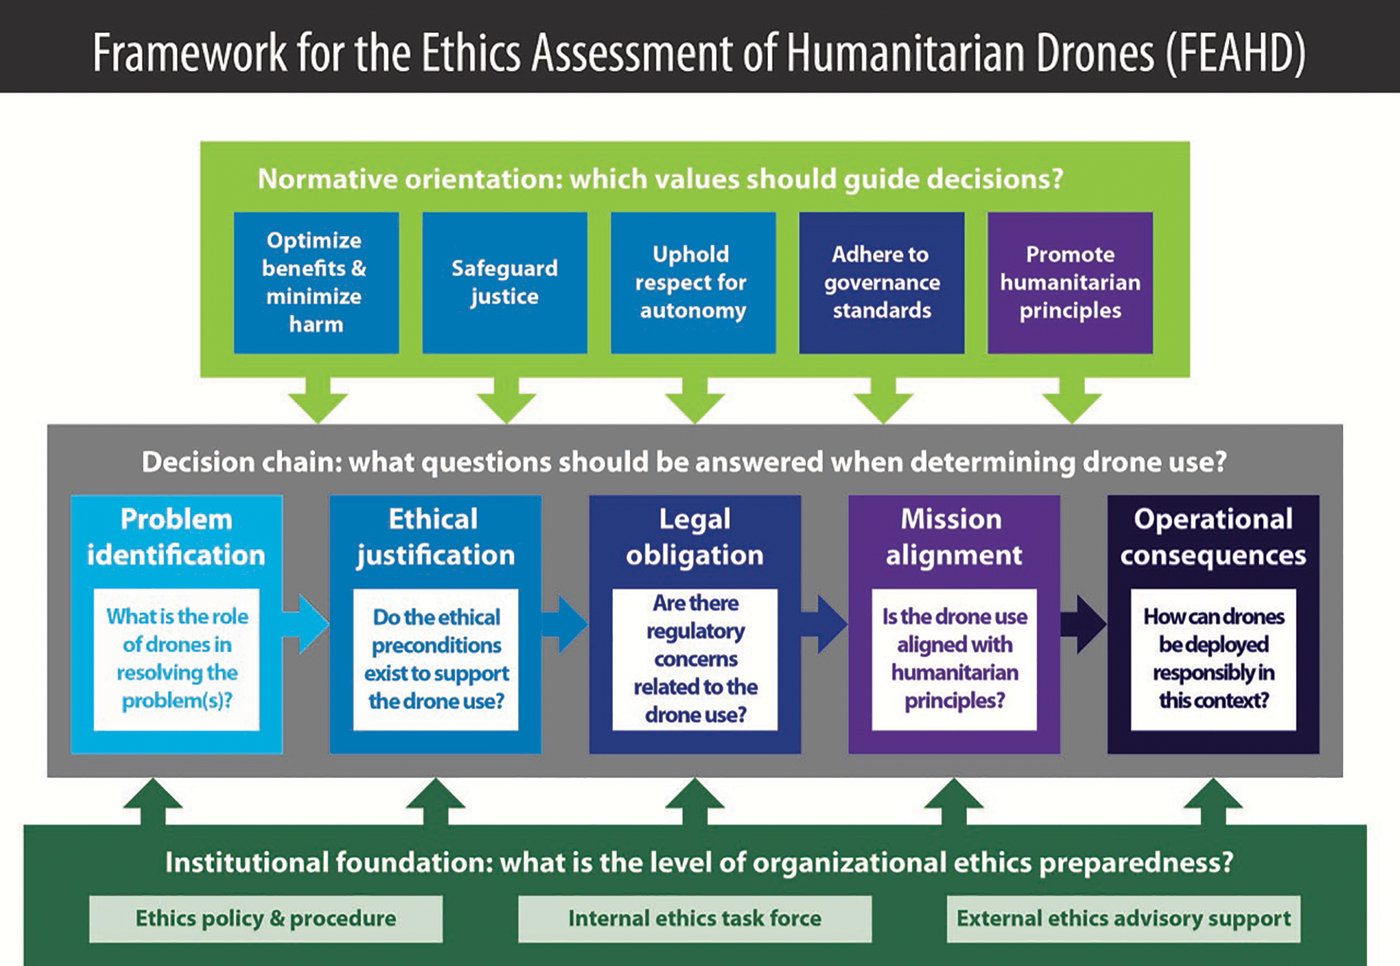
I used to run a flat rubric — list the domains, assign scores, ship the report. It looked clean on paper and failed in practice because the domains weren't actually independent. I learned that the hard way when a bias audit and a privacy assessment kept producing contradictory signals on the same model, and my team spent three weeks going back and forth before we realized we were using the same evidence twice under two different labels. At its core, Domains Of Ethical Assessment breaks an AI system's risk profile into separate lanes so you can inspect each one without the others drowning it out. The common set looks something like fairness, privacy, accountability, transparency, safety, and societal impact. People love to argue about whether to add a seventh or collapse two together. Don't. The exact partition matters less than making sure every lane has a clear owner and a real acceptance test. Here's the thing most guides skip: domains overlap by design, and that's not a bug, it's how ethics works. Safety and fairness intersect on a medical triage model. Privacy and transparency collide when you need to explain data flows without revealing proprietary pipeline details. If your assessment treats these as silos, you'll get clean scores and wrong conclusions.
The Method That Actually Works
Start with evidence, not definitions. Before you touch a single domain, gather what you already have — training data sheets, model cards, incident logs, user complaints, deployment constraints. Then map each artifact to every domain it touches. You will see the same document appear under three headings. That is normal. The work is deciding which heading gets final say when two domains conflict. My workflow runs like this:
- Phase one: Inventory every data source and model checkpoint the system touches. This usually takes a senior engineer half a day on a mature product and two days on something newer.
- Phase two: For each domain, write down the specific harm scenario you are guarding against. Not "bias happens" but "the model denies loan applications at 2.3x the rate for applicants in zip code cluster B compared to cluster A at equal income levels."
- Phase three: Assign an owner per domain. Not a committee. One person who can say no and mean it.
- Phase four: Build a conflict resolution matrix. When fairness scores drop but safety thresholds are met, who decides? Write it down before the conflict exists.
This structure turns an ethical review from a ceremonial checkbox into something you can actually use during a incident call at 2 AM. Last year I ran a Domains Of Ethical Assessment on a hiring recommendation tool. The fairness domain flagged disproportionate rejection rates for candidates over forty. The privacy domain flagged that fixing the bias required including age-related features in the model, which violated our data minimization pledge. Both domains were right. The fix was neither domain's fault alone. Here's the workaround I used: we created a synthetic age-proxy variable that captured seniority signals without storing actual birth years, then ran the fairness audit against that proxy. It reduced the disparity from 1.8x to 1.1x while keeping the original data flow intact. The assessment report noted the residual gap and required quarterly re-measurement. Nobody was satisfied. That's honest.
Get the Full Details

Common Pitfalls That Waste Time
The biggest mistake is treating Domains Of Ethical Assessment as a documentation exercise. You will produce beautiful tables and zero behavioral change. I've seen teams ship a 40-page ethical review that changed nothing about the model weights or the deployment pipeline. The assessment became a artifact for the compliance folder, not a tool for engineering decisions. Another trap is domain inflation. Every stakeholder wants a new category. "Digital wellbeing." "Algorithmic dignity." "Computational justice." Add too many and your assessment loses teeth. Each domain needs a measurable failure condition. If you cannot write a pass/fail test for it, it is a value statement, not an assessment domain. Keep the list tight and make each one painful to ignore. The third pitfall is timing. Running Domains Of Ethical Assessment only at the end of a project is like inspecting the wings after takeoff. The cost of fixing a fairness issue discovered post-deployment is roughly ten times what it would have cost during data collection. I budget my assessments at three points: data intake, model training, and pre-production. Anything after that is damage control, not assessment.
When This Approach Fails Completely
Domains Of Ethical Assessment does not work well in these situations: In those cases, consider shifting to a risk-based monitoring model with automated drift detection. It is less elegant than a clean domain framework but it actually catches problems before they ship. Good assessment needs good metrics. Bad metrics produce good reports and bad outcomes. For the fairness domain, reject aggregate accuracy. Use equalized odds difference or disparate impact ratio depending on your jurisdiction. For privacy, measure re-identification risk under realistic attack models, not theoretical bounds. For accountability, trace every automated decision to a human reviewer within your defined escalation window.
The metric choice matters more than the domain choice. I once watched a team proudly report "99.7% privacy compliance" using a metric that measured data retention policy coverage, not actual data leakage. The system was leaking embeddings through log files. The metric was correct. The conclusion was wrong. Always ask what the number actually protects against.

A Realistic Timeline and Cost Estimate
For a medium-complexity model with existing data governance, a proper Domains Of Ethical Assessment runs about 40 to 80 engineering-hours spread across two to three weeks. This includes inventory, scenario writing, metric selection, conflict resolution setup, and report drafting. A simpler system with clean data might take 20 hours. A cross-border deployment with legacy data pipelines can easily exceed 160 hours because you are untangling both technical and legal dependencies. The cost is not the problem. The problem is forgetting to budget it. I have seen projects cut the assessment timeline by half to meet a launch date, then spend three times that amount fixing issues discovered after deployment. The economics are simple: prevention is cheaper than remediation, but only if you actually do the prevention work instead of writing it down and moving on.
Tools That Help Without Solving Everything
There are frameworks worth knowing. Fairness Indicators for TensorFlow, AIF Datcards, IBM's AI Fairness 360, Microsoft's Fairlearn. They handle the measurement part well. They do not handle the domain conflict resolution or the ownership assignment. Treat them as calculation engines, not decision engines. The human judgment call still sits with your domain owner and your conflict matrix. For privacy-specific work, differential privacy libraries and membership inference attack tools give you harder numbers than policy checklists. For transparency, model card templates and datasheets for datasets are still the most practical standards, despite being around for years. Nothing replaces reading the actual data distributions and looking at the error patterns yourself. A solid Domains Of Ethical Assessment is not about finding the perfect framework. It is about building a process where responsible people with real authority can make defensible trade-off calls before the system reaches users. The frameworks help. The structure helps more. The willingness to make hard calls helps most.